Machine-Learning-Framework-for-option-mispricing: The XGBoost Pipeline That Keeps Repricing the Market
A practical trading framework for NSE BANKNIFTY options that combines defensive data cleaning, cross-sectional z-scores, and walk-forward retraining to surface mispricing signals.
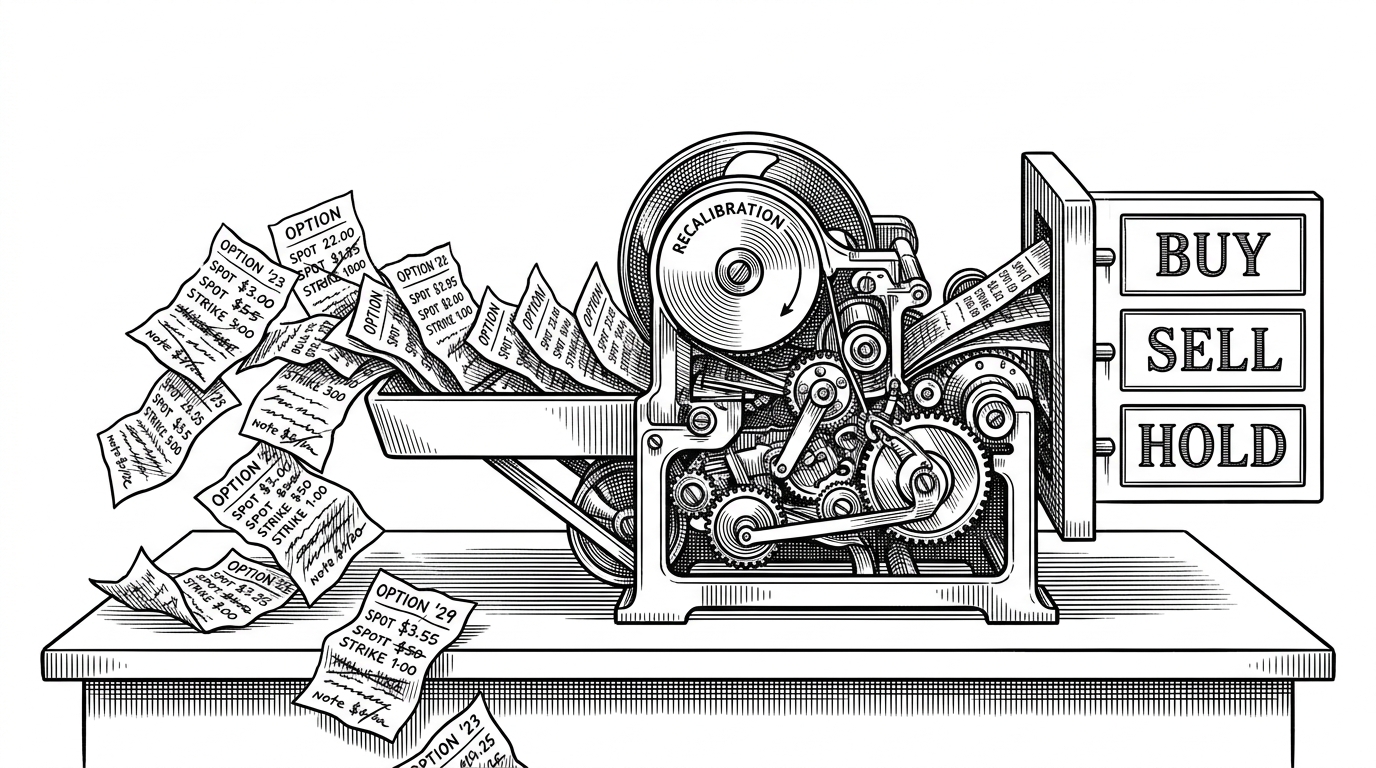
- This repo treats option mispricing as a moving target, so the real product is the feedback loop, not the regressor.
- The moat is defensive data engineering, because the model only works if dirty exchange data becomes stable features first.
- Walk-forward retraining and rolling recalibration matter more here than model complexity, because market drift is the failure mode.
- Cross-sectional z-scores turn raw prediction error into a ranking problem, which is closer to how a trading desk actually acts.
The most interesting thing here is not that XGBoost can estimate an option price. It is that the repo refuses to trust any single fit for long. It normalizes messy NSE data, predicts on a chronological split, then recalibrates residuals and retrains on a walk-forward schedule so the signals can survive regime change.
The market doesn’t sit still, so neither does this model
That is the whole thesis in one sentence. A static pricing belief breaks as soon as volatility shifts, skew changes, or the exchange feed gets weird. This framework answers with a loop: clean the input, score the chain, correct the bias, and retrain on newer data before the old pattern goes stale.
Built for NSE BANKNIFTY, not a clean textbook dataset
The repository is aimed at BANKNIFTY options, which means the code has to live with real market clutter: inconsistent date formats, daily files, volatility spikes, and contracts that do not behave like neat textbook examples. That setting shapes the architecture. The repo is not trying to be a generic finance library. It is trying to produce usable signals from a specific, noisy market.
Building models. Shipping pipelines. Solving engineering problems and xyz other things... But at some point, I realized I wasn't just interested in building systems, I wanted to understand them, question them, and contribute something new. Research became that outlet for me.
Why preprocessing is the real moat
The repo’s strongest code lives before the model. In preprocess.py and daily_features.py, it normalizes dates across multiple formats, computes implied volatility, and builds features like IV_relative, IV_HV_Spread, and term-structure slope. That matters because a trading model is only as honest as the rows it sees.
The model is simple. The training discipline is not.
XGBoost is a pragmatic choice for tabular options data. The repo uses it with a chronological split rather than random sampling, which matters more than the algorithm name. In finance, leakage is a fake victory. A time-aware split and a log-price target are what make the evaluation believable.
| Approach | Strengths | Weaknesses | Best use case | Why this repo chooses another path |
|---|---|---|---|---|
| Black-Scholes and other parametric models | Fast, interpretable, and easy to reason about | Assumes a cleaner world than live options often provide | Baseline pricing and sanity checks | This repo wants learned mispricing signals, not just a formula benchmark |
| Rule-based anomaly detection | Simple to deploy and easy to inspect | Hard to adapt when regimes shift or features interact | Quick screening rules | The repo needs ranking power across many contracts, not a brittle threshold |
| Sequence-heavy deep learning | Can model temporal structure and nonlinear effects | More complex to train, tune, and explain | Large data settings with strong sequence signal | This repo is optimized for tabular derivatives data and operational stability |
| XGBoost with walk-forward retraining | Strong on tabular data and easier to recalibrate | Still depends on feature quality and market structure | Daily mispricing detection in a drifting market | It balances performance, interpretability, and retraining discipline |
The clever part is the recalibration loop
This is the mid-article payoff. The repo’s recalibrate_zscores step removes rolling five-day bias before signals are ranked, and walk_forward_retrain rebuilds the model on an expanding monthly window. That is not cosmetic. It is a direct defense against model drift, which is the quiet failure mode that ruins most financial ML systems.
Signals become useful only after you compare contracts to each other
The repo does not stop at prediction error. It turns errors into cross-sectional z-scores within the same day, which changes the question from “how wrong was the model?” to “which contract is most mispriced relative to the rest of today’s chain?” That is the market-neutral move. It is also why the output can become a practical BUY or SELL list instead of a pile of residuals.
| Signal lens | What it measures | Why it matters |
|---|---|---|
| Absolute error | Difference between predicted and actual price | Useful for model debugging, but not enough to rank opportunities |
| Cross-sectional z-score | Residual standardized against other contracts that day | Turns raw error into a relative mispricing ranking |
| Walk-forward signal | Rank after recalibration and retraining | Keeps the list relevant as regime and volatility change |
Daily Run turns research code into a workflow
The production entry point is daily_run.py. It auto-picks the latest file, applies clipping bounds from clip_bounds.json, and sends the result toward the dashboard. That is the difference between a notebook and a workflow. One is a demo. The other is something you can return to every trading day.
What this repo beats is not a single rival. It beats stasis. It is more operationally useful than a pure formula stack when the data is messy, more resilient than heuristic flags when the market shifts, and more practical than heavier sequence models when tabular features carry the signal. That said, it still lives or dies on feature quality and on whether the market remains learnable enough for the loop to matter.