syncstorage-rs: The Rust Service That Makes Firefox Sync Feel Simple
A deep dive into the storage layer behind Firefox Sync, where metadata, blobs, auth, and legacy protocol compatibility are split apart on purpose.
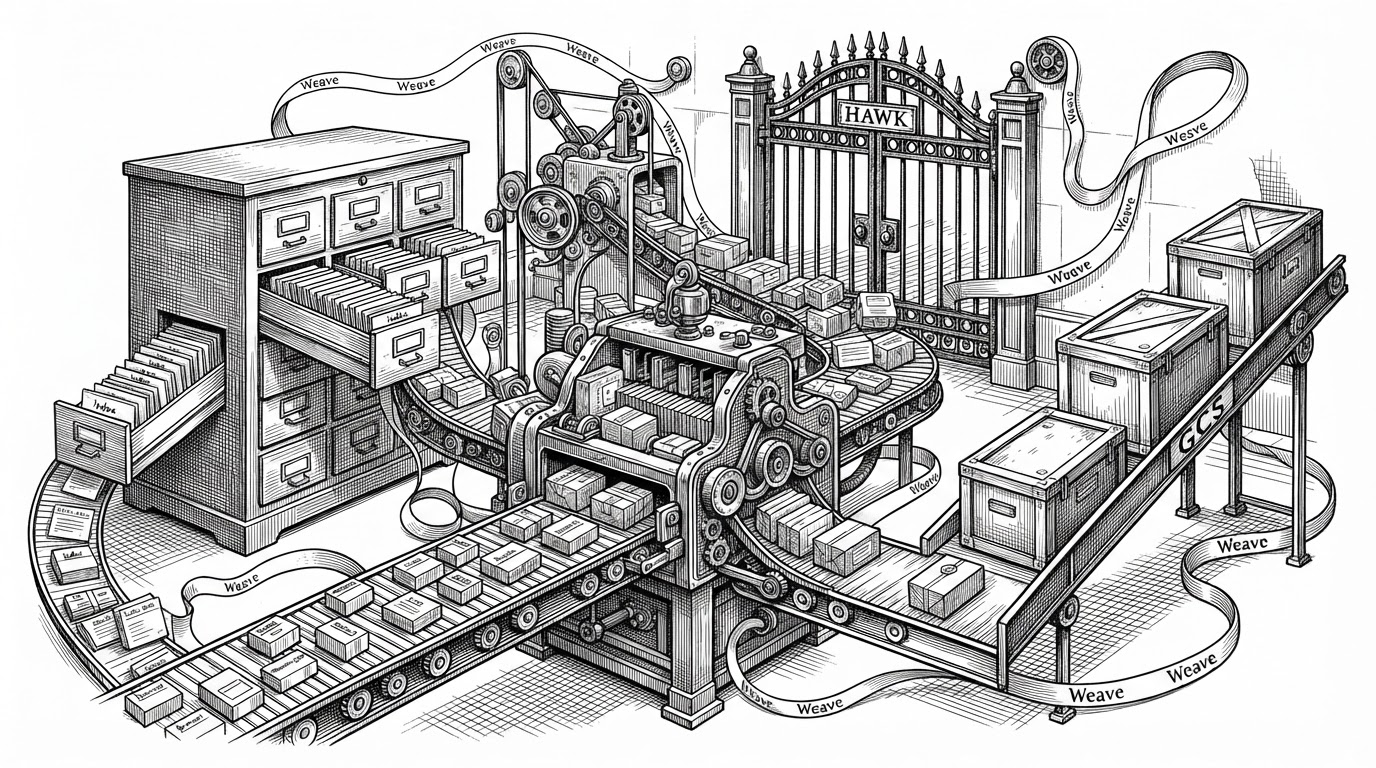
- syncstorage-rs is really a split storage pipeline, not a single database, and that split is the point.
- Mozilla pushes payloads away from metadata so Firefox Sync can scale without turning the database into a blob dump.
- The request path is built around transaction boundaries, observability, and automatic response stamping rather than ad hoc HTTP handlers.
- Rust matters here because it makes a hard multi-backend architecture safer to run, not because the architecture itself is simple.
The browser thinks it is one service. It is actually four
Firefox Sync feels like a single checkbox in the browser. In reality, `syncstorage-rs` sits in the middle of a layered system: tokenserver handles identity and node allocation, syncstorage handles the data plane, the database stores metadata, and object storage takes the heavy blobs. The browser never sees that split. It only sees a sync service that works.
That separation is the story. Mozilla did not build a giant bucket for browser data and stop there. It carved the service into parts that can fail, scale, and change independently.
Why Mozilla split payloads away from metadata
The most interesting design choice in the repo is the payload split. Metadata stays in the database. Large BSO payloads can move into Google Cloud Storage. That means the database keeps the indexes, timestamps, and pointers it needs for consistency, while object storage absorbs the expensive part of the workload.
This is not elegance for its own sake. It is a scale move. If you store every payload in the database, the hot path gets wider, backups get heavier, and the cost curve gets ugly fast. By separating payloads from metadata, Mozilla keeps the transactional core small and pushes bulk storage where it belongs.
The request path is a transaction machine
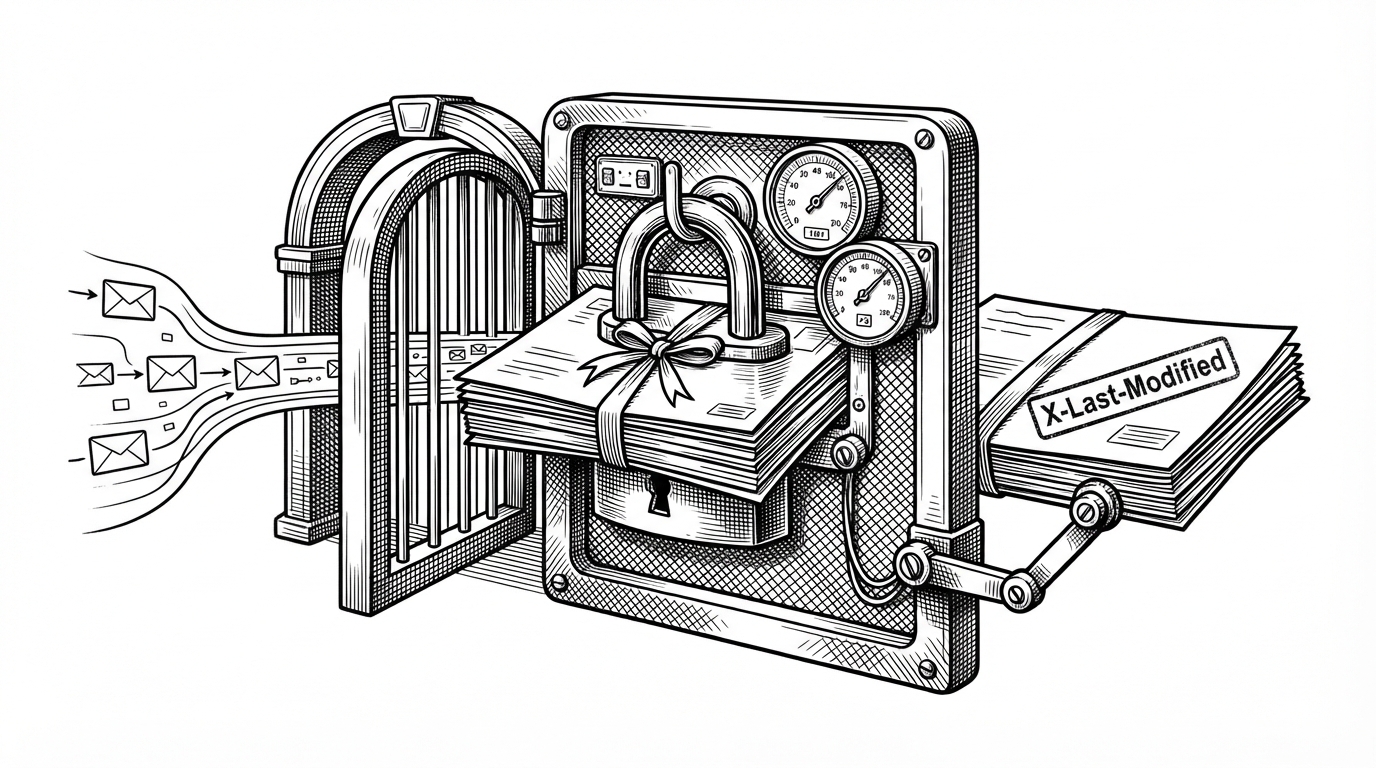
Inside `syncserver`, the request lifecycle is engineered to preserve invariants. The transaction wrapper acquires a connection, starts the transaction, captures connection details for telemetry, and then injects the final `X-Last-Modified` header before the response leaves the server. That is a lot of control for a seemingly ordinary API call.
The point is not ceremony. It is consistency. If this service is the authority for sync state, then every request needs to leave behind a reliable timestamp trail and a predictable database state.
// Simplified shape of the request wrapper
async fn transaction_http<F, R>(&self, f: F) -> Result<HttpResponse>
where
    F: FnOnce(&mut Transaction) -> Future<Output = Result<R>>,
{
    let mut conn = self.pool.acquire().await?;
    let mut tx = conn.begin().await?;

    let result = f(&mut tx).await?;
    let modified = tx.sync_timestamp();

    let mut response = HttpResponse::Ok().finish();
    response.headers_mut().insert("X-Last-Modified", modified.into());
    Ok(response)
}
Auth is intentionally not the storage layer’s problem
The storage server does not get raw passwords. That boundary matters. HAWK auth, token expansion, and HKDF keep credentials and storage separate, so the sync layer works with derived tokens instead of user secrets. In other words, the storage backend is not also your identity system.
Running sync server on a raspberry pi for yourself, you'd be unaware of a lot of those problems. Running sync servers for hundreds of millions of users on a limited budget, and you become deeply aware of those issues. A bunch of those are the driving reasons for why we're rebuilding in Rust and using a cloud based database.
Rust is the constraint engine, not the headline
Rust is the mechanism that makes the architecture survivable. Actix-web gives the service async throughput. Diesel and backend-specific crates let the same codebase talk to MySQL, PostgreSQL, and Spanner. `utoipa` keeps API docs close to the handlers, so the contract does not drift as fast as the codebase evolves.
That is the real Rust story here. It lowers the risk of a system that already has a lot of moving parts. It does not turn a complex backend into a simple one.
| Project or approach | Storage model | Auth model | Protocol coverage | Self-hosting difficulty | Best for |
|---|---|---|---|---|---|
| syncstorage-rs | Split metadata plus payload offload | HAWK and tokenserver | Full Firefox Sync 1.5 | High | Mozilla-scale Sync and strict compatibility |
| Legacy Python syncserver | Mostly monolithic storage | HAWK and tokenserver | Full Firefox Sync 1.5 | Medium | Older self-host setups and simpler ops |
| Floccus | Extension plus external storage | Depends on backend | Bookmarks only | Low to medium | People who want bookmark sync over a personal backend |
| xBrowserSync | Custom service and client-side encryption | Custom account flow | Bookmarks and tabs | Medium | Browser-agnostic lightweight sync |
The compatibility trap: modern infrastructure, old Sync protocol
The repo still speaks in the language of Weave, legacy headers, and protocol continuity. That matters because compatibility is not just about keeping an old client alive. It is about preserving a contract that already exists in millions of browsers.
This is where the project earns its complexity. Mozilla is not free to redesign the sync protocol around what is easiest today. It has to keep the promise Firefox users already depend on.
How it compares to self-hostable alternatives
Compared with tools like Floccus and xBrowserSync, `syncstorage-rs` is much less about convenience and much more about protocol fidelity. Those alternatives are attractive because they are easier to set up and narrower in scope. `syncstorage-rs` is attractive because it behaves like Firefox Sync, not like a separate sync product pretending to fit in.
That tradeoff cuts both ways. The Mozilla stack is the most complete implementation here, but it is also the least casual. If you want the full browser-native protocol, you pay for it in operational complexity.
| Project or approach | Storage model | Auth model | Protocol coverage | Self-hosting difficulty | Best for |
|---|---|---|---|---|---|
| syncstorage-rs | Split metadata plus payload offload | HAWK and tokenserver | Full Firefox Sync 1.5 | High | Mozilla-scale Sync and strict compatibility |
| Legacy Python syncserver | Mostly monolithic storage | HAWK and tokenserver | Full Firefox Sync 1.5 | Medium | Older self-host setups and simpler ops |
| Floccus | Extension plus external storage | Depends on backend | Bookmarks only | Low to medium | People who want bookmark sync over a personal backend |
| xBrowserSync | Custom service and client-side encryption | Custom account flow | Bookmarks and tabs | Medium | Browser-agnostic lightweight sync |
What this repo reveals about Mozilla’s infrastructure philosophy
`syncstorage-rs` reads like product plumbing, but its real lesson is organizational. Mozilla prefers clear boundaries, protocol stability, and backend flexibility over a single all-purpose service. It is willing to keep old contracts intact if that is what production demands.
That is why the code feels disciplined. The browser sees simplicity. The infrastructure sees a set of carefully managed constraints, each one placed there on purpose.