homebrew-forgemax: Stop Feeding LLMs JSON Schemas: Inside postrv/forgemax
How a Rust-based gateway uses a V8 isolate to collapse the Model Context Protocol, saving 98% of token costs by forcing agents to write code instead of reading schemas.
Forgemax's Code Mode approach draws inspiration from Cloudflare's sandbox tool-calling pattern — their implementation of sandboxed code execution for MCP tool orchestration is excellent and well worth studying. We encourage supporting their work.
- Forgemax solves the Model Context Protocol scaling problem by reducing N tools down to just two commands.
- Instead of planning and executing sequential tool calls, the LLM writes a single JavaScript function that orchestrates internal tools locally.
- A Rust-embedded V8 isolate ensures that LLM-generated code runs securely without leaking host credentials or state.
- The project utilizes a Functional Source License to prevent cloud providers from immediately strip-mining the infrastructure.
The Context Window Tax
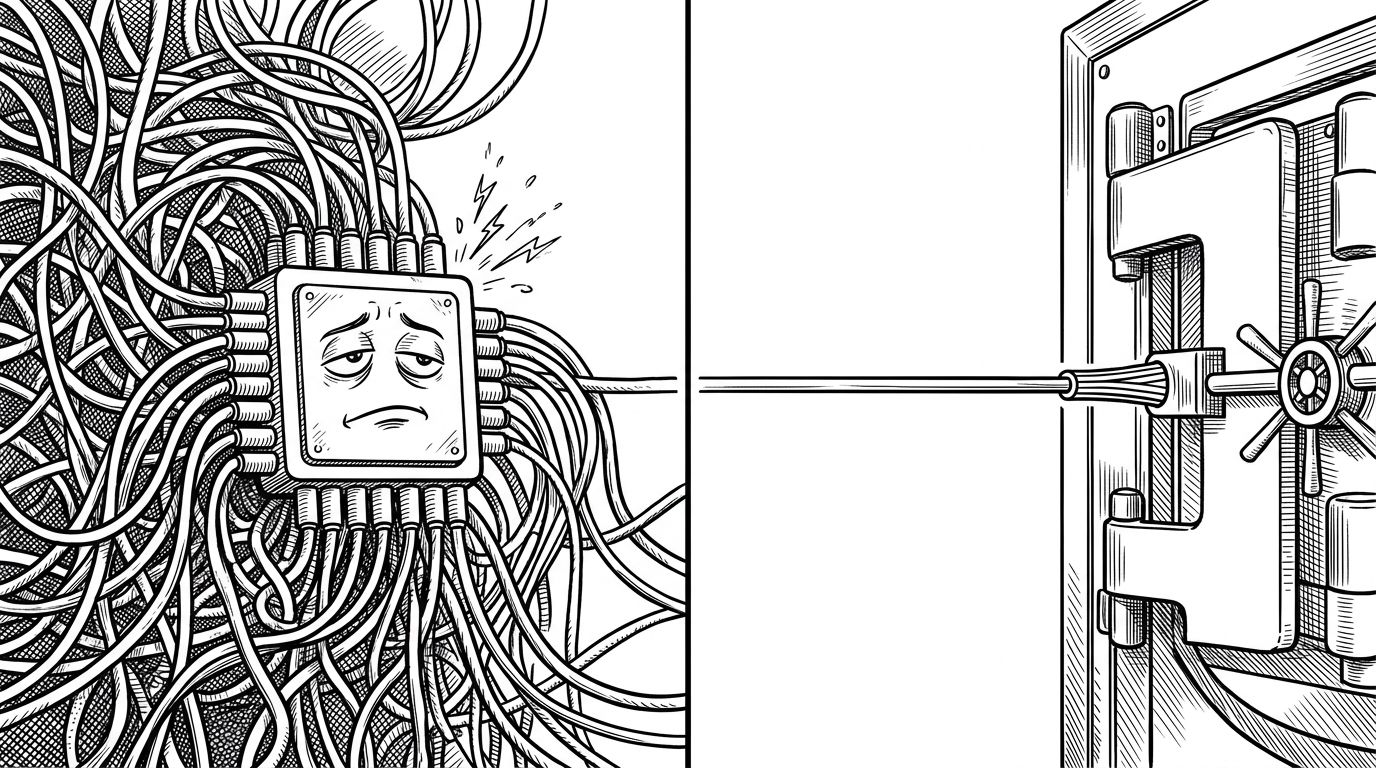
The Model Context Protocol (MCP) has a scaling problem. Every time you connect a new database, GitHub repository, or internal API to an AI agent, the LLM must ingest the entire JSON schema for every available function. For an agent equipped with dozens of tools, this means burning tens of thousands of tokens on boilerplate before the model even begins to process the prompt.
It is an O(N) context tax that degrades both performance and reasoning capabilities. When you are paying per input token, shoving 70 tool definitions into every single API call destroys your unit economics. The latency of sequential round-trips only compounds the issue when an agent needs to use multiple tools in a row.
| Feature | Traditional MCP | Forgemax |
|---|---|---|
| Tool Exposure | Full JSON schema for every tool | Strictly 2 tools (search and execute) |
| Token Cost | Variable and scaling up to 30k+ tokens | Constant O(1) at ~1,100 tokens |
| Multi-Step Orchestration | Multiple LLM round-trips | Single V8 script execution |
| Execution Model | Agent plans, host executes | Agent codes, V8 sandbox executes |
The Two-Tool Collapse
Forgemax flips the paradigm. Instead of treating the large language model like a user picking from a massive menu of tools, it treats the LLM like a software engineer. The gateway actively hides the underlying tool library from the model.
Instead of dumping every tool schema into the LLM's context window, Forgemax exposes exactly two MCP tools: `search` — query a capability manifest to discover tools (read-only, sandboxed) `execute` — run JavaScript against the tool API in a sandboxed V8 isolate
By collapsing the interface, the LLM writes a single JavaScript snippet that chains these tools together locally. Writing a quick JS function to map over a database query and push to GitHub feels way more natural for an LLM than emitting five separate JSON tool-call objects.
Sandboxing the Agent
Allowing an autonomous agent to write and execute arbitrary JavaScript on a local machine is a massive security risk. Forgemax mitigates this by embedding a V8 isolate within its Rust architecture. This sandbox ensures that the agent cannot access the host directly.
The script executes within the isolate, performing rapid sequential queries against the internal tools without ever making a network call back to the LLM. Using a V8 isolate here is brilliant. It spins up in milliseconds compared to the heavy overhead of a Docker container, making it perfect for ephemeral agent tasks.
Blue-Collar AI Infrastructure
Beyond its architecture, Forgemax is packaged for immediate real-world use. It is distributed via a Homebrew tap, hiding its complex Rust build pipeline behind simple pre-compiled binaries. You configure it with a developer-friendly TOML file.
The project also employs the Functional Source License (FSL). This strategic choice protects the creator from commercial strip-mining by cloud vendors, ensuring the infrastructure can mature sustainably before transitioning to Apache 2.0.