Twitter_Sleuth: The OSINT Tool That Hunts Twitter Through Google
A small Python framework turns dorking, cross-platform pivots, and structured reporting into a reconnaissance workflow for the age of locked-down social APIs.
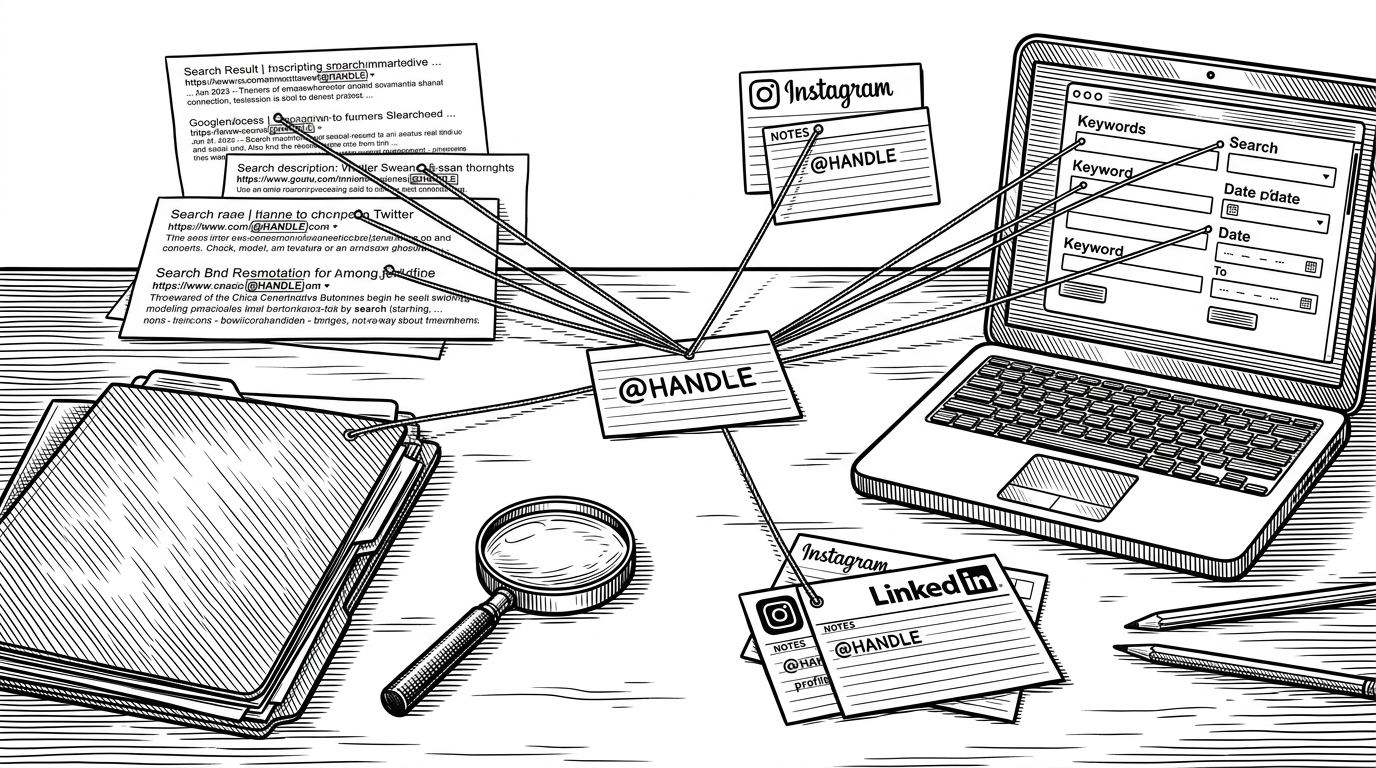 Google’s index as the front door to social investigation." data-prompt="Create an editorial illustration rendered entirely in black ink on a pure white background. The image depicts a detective-style desk scene in which a single Twitter handle written on a card sits at the center of the composition. From that card, thin threadlike lines lead to printed Google search results, a laptop screen showing query templates, and small index cards labeled Instagram and LinkedIn. The scene should feel like a map of indirect tracing and cross-platform correlation, not a literal software screenshot. The artist uses tightly packed crosshatching lines layered at different angles to build up shadow and form, with clean open areas of white for highlights. The line work has the quality of a classic metal engraving, precise and deliberate, with varied line weights where bold contour lines define shapes and finer interior lines create tonal depth. The overall style evokes vintage newspaper editorial illustrations from The Economist or Wall Street Journal. No color, no gradients, no grey fills. Only black lines on white. The background MUST be pure white #FFFFFF. No paper texture, no cream, no off-white, no noise, no grain. Perfectly clean flat white background." loading="lazy">
- Twitter_Sleuth treats Google’s index as the real search surface, then uses Twitter as a pivot instead of a destination.
- The tool’s strength is not brute-force collection but query fan-out, cross-platform correlation, and structured reporting.
- Its most unusual trait is architectural as much as technical: the main repo reads like a distribution shell around a method.
- The project reflects a broader OSINT shift in which indirect traces become more reliable than direct platform access.
The real interface is Google
Twitter_Sleuth is not trying to win a head-on fight with X. It assumes the platform is harder to search, harder to scrape, and less stable than the public web around it. So it starts with the one surface that still remembers a lot: Google’s index.
That matters because OSINT is often a game of residue, not completeness. A handle, a bio fragment, a location string, or a reused profile line can survive in search results long after platform search gets noisy or locked down. In this repo, Google is not a helper. It is the primary interface.
target = "@example_handle"
queries = [
    f'site:twitter.com "{target}"',
    f'site:twitter.com "{target}" "location"',
    f'site:twitter.com "{target}" "instagram"',
    f'site:twitter.com "{target}" "linkedin"',
]
Why dorking beats brute-force scraping
The central move is query generation. Instead of pulling one record at a time from a brittle endpoint, Twitter_Sleuth expands a target into a bundle of dorks. That fan-out makes the workflow feel resilient because it is built around search patterns, not a single access path.
This is also why the tool reads as method-heavy. It does not just ask, “What does this account say?” It asks, “Where else does this name, place, or profile fragment appear in public?” That shift turns a handle into a trail of leads.
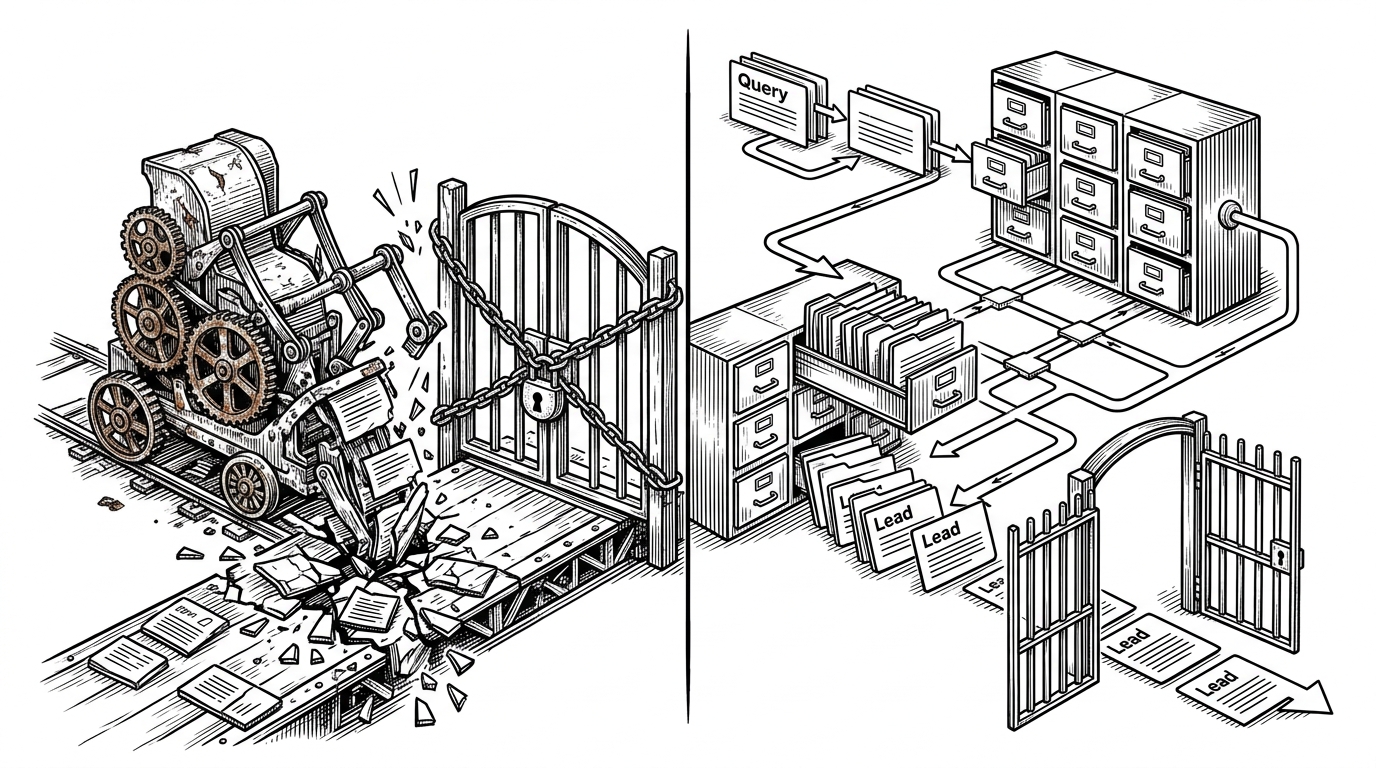
A workflow built for pivots, not just lookups
The repo’s multi-phase workflow is where the idea becomes operational. It starts with automated recon, then moves into direct analysis, and finally wraps the findings into structured outputs like HTML, JSON, or text. The important part is not the file format. It is the pivot logic.
Twitter is treated as one node in a larger identity map. The point is to use one public trace to locate others, including Instagram, LinkedIn, media references, replies, and other web artifacts. That is classic OSINT thinking, but the repo makes the sequence explicit enough to automate.
What config.py is really doing
The configuration file tells you what the author cared about. Delay, retries, SSL verification, and output preferences are not glamorous settings. They are the controls that make a reconnaissance script survivable in the real world.
That suggests the project is built around quiet persistence. It assumes network friction, rate limits, and imperfect environments. The design goal is not raw speed. It is keeping the workflow reliable enough to keep moving when the first pass fails.
REQUEST_DELAY = 2
MAX_RETRIES = 3
VERIFY_SSL = True
OUTPUT_FORMAT = "html"  # or "json", "txt"
TWITTER_BEARER_TOKEN = ""
GOOGLE_CSE_API_KEY = ""
GOOGLE_CSE_ID = ""
The weirdest part: the repo is partly a shell
One of the strangest details is that the main repository behaves more like a documentation and distribution surface than a home for the core logic. The interesting code lives elsewhere, via a Gist. That makes the repo feel less like a conventional project and more like a method packet with a public wrapper.
That choice changes how you read the project. It is not just a codebase. It is a social artifact. The repo advertises the method, keeps the explanation close, and lets the implementation live in a more movable place.
How it compares to the usual Twitter OSINT stack
| Tooling approach | Primary access surface | Dependency on official API | Resistance to platform changes | Typical failure mode | Best use case | Operational burden |
|---|---|---|---|---|---|---|
| Twitter_Sleuth | Google index first, Twitter second | Optional | Higher when search traces remain public | Search results dry up or lose coverage | Cross-platform pivoting from a handle | Moderate |
| Twint-style scraping | Twitter pages and public endpoints | No | Low to medium | Selectors and access paths break | Bulk collection when scraping still works | High |
| SNScrape-style collection | Public social endpoints | No | Medium | Endpoint changes and throttling | General social media harvesting | Medium |
| Tweepy / official API | Official Twitter API | Yes | High at the transport layer, low at the policy layer | Rate limits, access costs, permission gaps | Clean API-based integrations | Medium to high |
The comparison is not about which tool is universally best. It is about where the search begins. Twitter_Sleuth is more adaptive for investigations that start with a name and need a wider web trail, while scrapers and API clients are better when the goal is direct data collection from the platform itself.
What this tool says about modern OSINT
Twitter_Sleuth is a snapshot of how OSINT adapts when direct access gets expensive or unstable. Search engines remain porous. Public traces remain linkable. And the shortest path to useful context is often indirect.
That is the real lesson here. The project is small, a little strange, and more method than software. But it captures a larger shift in reconnaissance work: when the platform closes, investigators do not stop. They reroute.