Production-Ready-Product-Catalog-API: The Small Node Service That Tries to Think Like Production
A layered Express API that pairs cache-aside reads, Redis rate limiting, real database tests, and hardened SQL into a compact backend template.
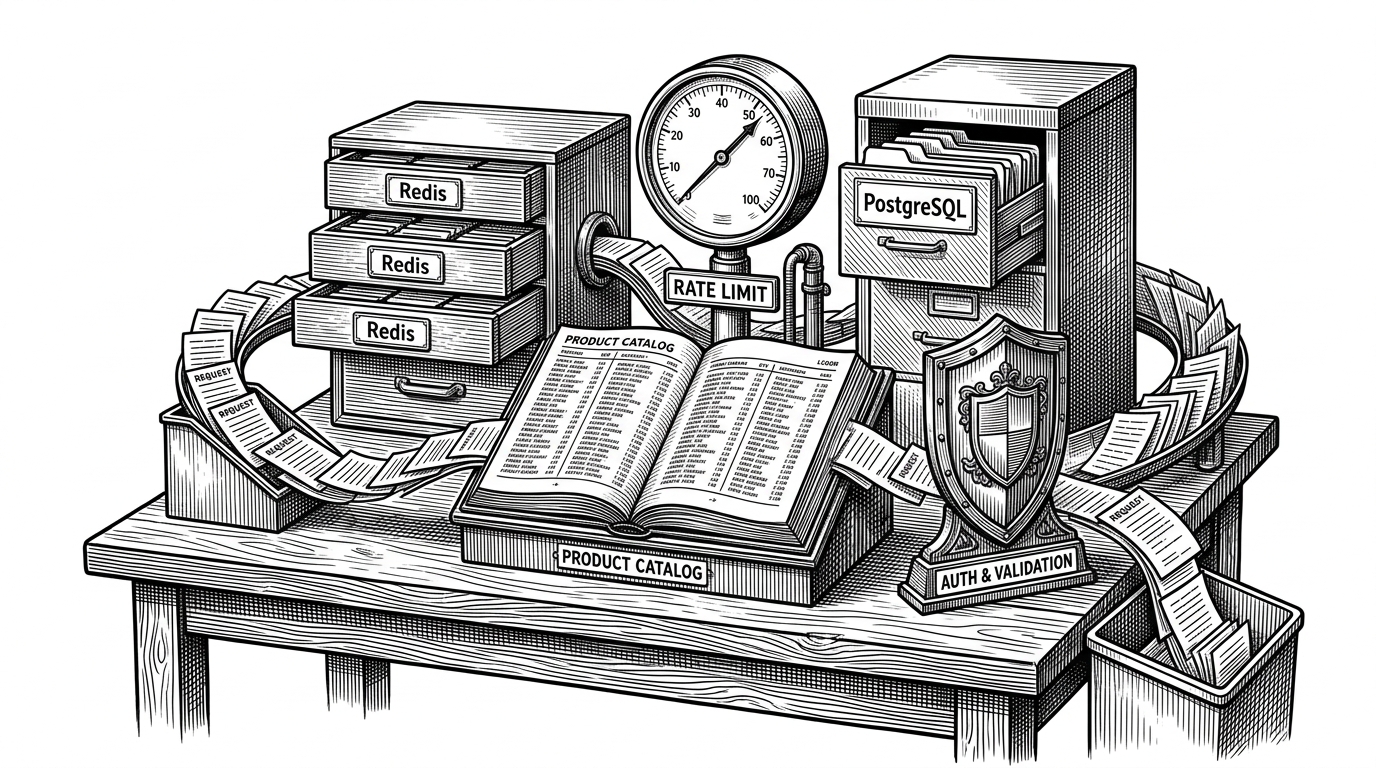
- This repo treats production concerns as the core feature, so the interesting work happens in caching, rate limiting, SQL guardrails, and deployable packaging rather than in the CRUD endpoints themselves.
- Its layered controller-service-repository structure makes the request path easy to reason about once cache decisions, validation, and database access start interacting.
- The cache strategy favors consistency over cleverness by purging broad product list keys when a single record changes.
- It sits in a narrow niche between tutorial code and full commerce platforms, which makes it useful as a backend blueprint rather than a complete product system.
Why This API Feels Like a Real Backend
Most sample APIs stop when the endpoints work. This one keeps going. It adds the boring parts that make software survivable in production: Redis-backed rate limiting, cache-aside reads, cache invalidation, structured errors, security middleware, multi-stage Docker, and integration tests that hit real PostgreSQL and Redis containers.
That is the editorial trick here. The repo is not trying to be a catalog app that happens to have a few extras. It is trying to be a compact template for what a serious Node service looks like once it leaves tutorial land.
The stack is straightforward on purpose: Express, PostgreSQL, Redis, JWT, bcrypt, Helmet, Jest, Supertest, and Docker. The value is not novelty. It is how many production concerns get packed into a small surface area without collapsing into a framework maze.
The Request Path: Controller, Service, Repository
The architecture follows a clean controller-service-repository split. Controllers handle HTTP shape. Services make decisions. Repositories talk to the database. That separation matters here because caching, validation, and SQL safety all live in different layers for a reason.
// service layer sketch
async function getAllProducts(query) {
  const cacheKey = `products:${JSON.stringify(query)}`;
  const cached = await redisClient.get(cacheKey);
  if (cached) return JSON.parse(cached);

  const products = await productRepository.getAllProducts(query);
  await redisClient.setEx(cacheKey, 300, JSON.stringify(products));
  return products;
}
That shape is the whole point. The controller stays thin, the service owns the cache decision, and the repository stays focused on SQL. Once you have pagination, filters, and rate limits, mixing those concerns into one file becomes a maintenance tax.
The Clever Part: Cache-Aside With Aggressive Invalidations
The repository’s most interesting choice is not that it caches. It is how it invalidates. Reads use cache-aside. Updates and deletes remove the specific product key and also clear the broader product list caches. That is blunt, but it keeps stale paginated results from surviving longer than they should.
That tradeoff is worth noticing. Fine-grained cache retention looks elegant on paper, but it often creates uncertainty about which list views are still valid. This repo picks a simpler operational rule: when a product changes, list caches are cheap enough to throw away.
The result is easy to explain and hard to misuse. That is good engineering, especially for a template repo whose readers may adapt it under pressure.
Redis Is Doing Two Jobs Here
Redis backs both the cache and the rate limiter. That is practical, not decorative. It gives the service shared mutable state that survives restarts and works across multiple instances, which is exactly what you want when the same API node may be scaled out behind a load balancer.
The rate limiter uses increment plus expiry, so each client IP gets a moving window tracked in Redis. The API also returns standard rate-limit headers, which makes the behavior visible instead of mysterious. That is a small detail with a real UX payoff for API consumers.
| Use case | Why Redis fits | What would break if it were in memory |
|---|---|---|
| Cache | Fast reads for product lists and product detail lookups | Every restart would cold-start the cache |
| Rate limiting | Shared counters across workers and instances | Limits would reset per process and become inconsistent |
| Mutability | Central state for invalidation and counters | Horizontal scaling would fragment behavior |
SQL That Resists Its Own Footguns
The repository layer uses raw SQL, but not recklessly. It manually builds filters for search and category, then whitelists sort fields so an attacker cannot smuggle SQL through an ORDER BY parameter. That is the important distinction. This is raw SQL with guardrails, not raw SQL because the author forgot better options.
const allowedSort = ['name', 'price', 'created_at'];
const sortBy = allowedSort.includes(query.sortBy) ? query.sortBy : 'created_at';
const sortOrder = query.sortOrder === 'asc' ? 'ASC' : 'DESC';

const sql = `
  SELECT *
  FROM products
  WHERE ($1::text IS NULL OR name ILIKE $1)
  ORDER BY ${sortBy} ${sortOrder}
  LIMIT $2 OFFSET $3
`;
That pattern keeps the flexibility of hand-built SQL while avoiding one of the easiest injection mistakes. It also matches the repo’s broader philosophy: explicit over magical, observable over implicit.
What Production-Ready Means in Docker and CI
The Dockerfile uses a multi-stage build, which trims the final image down to runtime essentials. That matters less as a buzzword than as a signal. It says the project is thinking about shipping, not just running locally.
The CI pipeline is even more telling. It runs integration tests against real PostgreSQL and Redis containers. That means the code is not only checked for syntax and mocks. The actual database and cache behavior are exercised, which is where a lot of sample APIs quietly fall apart.
| Area | Tutorial pattern | This repo |
|---|---|---|
| Build | Single-stage image with dev tools left inside | Multi-stage image with a slimmer runtime footprint |
| Tests | Mocks for database and cache | Real PostgreSQL and Redis containers in CI |
| Failure mode | Code passes without proving infrastructure behavior | Infrastructure assumptions get tested before merge |
How It Stacks Up Against Larger Platforms
This project lives in a narrow niche. It is smaller than Strapi, lighter than Medusa and Saleor, and more focused than Directus. Those platforms give you broad product systems or content management. This repo gives you a disciplined backend skeleton for one focused service.
| Project | Primary purpose | Stack | Strength | Tradeoff | Best for |
|---|---|---|---|---|---|
| Production-Ready-Product-Catalog-API | Focused product catalog service | Node.js, Express, PostgreSQL, Redis | Clear production-minded backend blueprint | Not a complete commerce suite | Teams that want a lean API template |
| Strapi | Headless CMS | Node.js | Huge ecosystem and flexible content modeling | More platform than purpose-built service | General content and catalog management |
| Medusa | Commerce engine | Node.js | Full commerce features and extensibility | Heavier operational footprint | E-commerce teams needing a platform |
| Saleor | Headless commerce | Python, Django, GraphQL | Strong product and order system | Different stack and broader scope | Complex commerce operations |
| Directus | Database-driven API | Node.js | Fast database-to-API workflow | Less opinionated about backend discipline | Teams exposing existing data quickly |
So the comparison is not about winning. It is about category. Those tools are full platforms. This repo is closer to a blueprint for the plumbing that serious teams often want to own themselves.
Who This Repo Is Actually For
This is useful if you are a backend engineer, architect, or founder who wants a compact, production-minded template for a focused API. It is useful if you care about the shape of the system as much as the endpoints themselves.
It is less useful if you want a full e-commerce suite, a visual CMS, or a broad commerce ecosystem out of the box. The repo’s value is narrower and better defined than that. It shows how a lean Node service can behave like something you would trust in production.