SkillSpector: NVIDIA’s Scanner for AI Skills That Lie About What They Do
A hybrid security pipeline for agent-era supply chains, where static rules catch the obvious and LLM analysis catches the mismatch between promise and behavior.
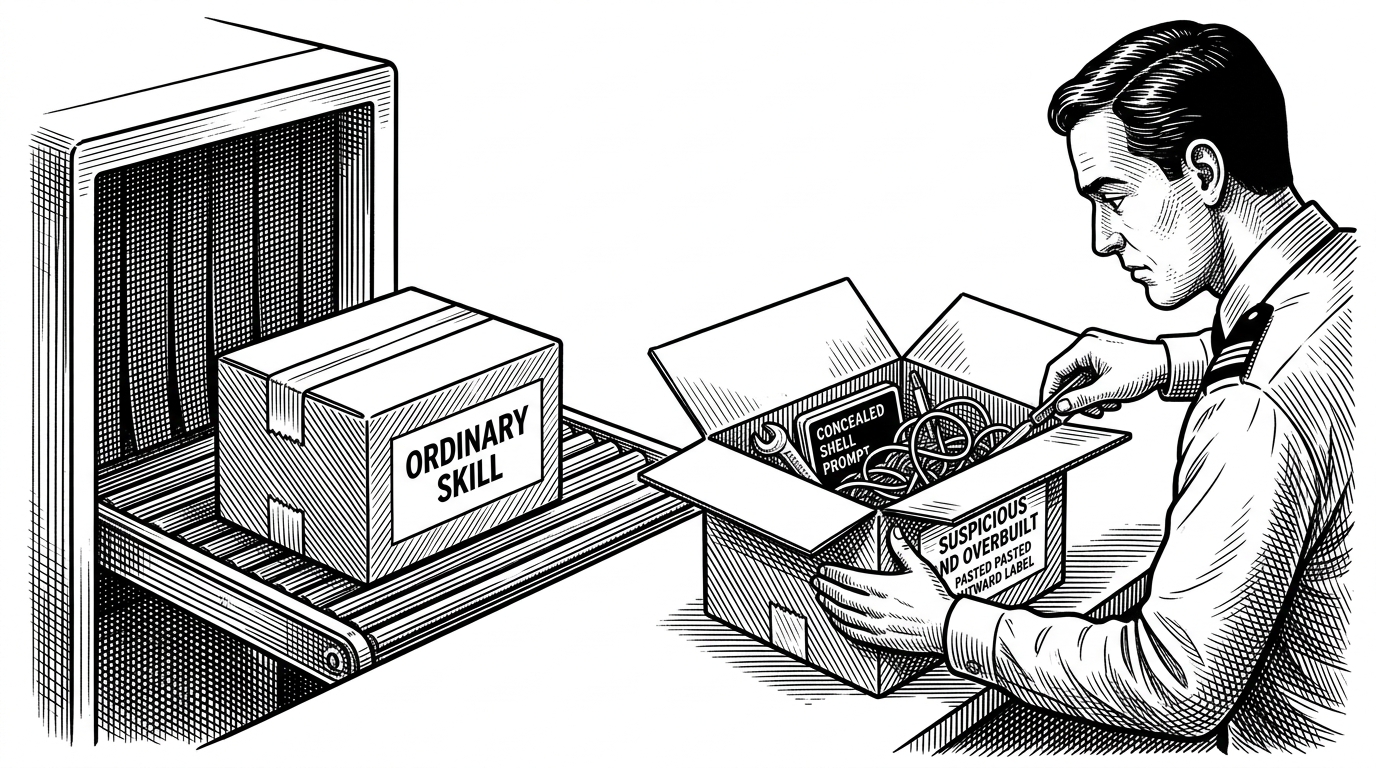
- SkillSpector treats AI agent skills as executable trust objects and asks the first question that matters: should this skill run at all?
- Its real differentiator is semantic skepticism, because it compares a skill’s declared purpose with what the code actually does.
- The repo is built as a LangGraph pipeline so multiple analyzers can run in parallel and feed one shared security verdict.
- SARIF output turns the scanner into deployable infrastructure instead of a one-off research demo.
Agent skills look small. That is the problem. A tiny package can still arrive with filesystem access, shell access, and a story that sounds harmless enough to pass a quick glance.
SkillSpector is NVIDIA’s answer to that trust gap. The repo treats these skills less like scripts and more like supply-chain objects that need to be inspected before they are allowed to run. The official docs put it plainly: "SkillSpector is a security scanner for AI agent skills that helps answer: should this skill be installed?"
SkillSpector is a security scanner for AI agent skills that helps answer: should this skill be installed?
The New Trust Problem in Agent Skills
The old software-supply-chain story is familiar. A package manager pulls in code, the code runs, and defenders hope static checks and policy gates caught the bad stuff first. Agent skills add a worse wrinkle: the package can also shape model behavior while it runs.
That means the threat is not just a vulnerable script. It is a skill that claims to summarize files, but quietly overreaches its permissions, leaks data, or slips in a hidden trigger. NVIDIA’s own framing points at exactly that mismatch between declared purpose, requested access, and bundled behavior.
Why SkillSpector Exists
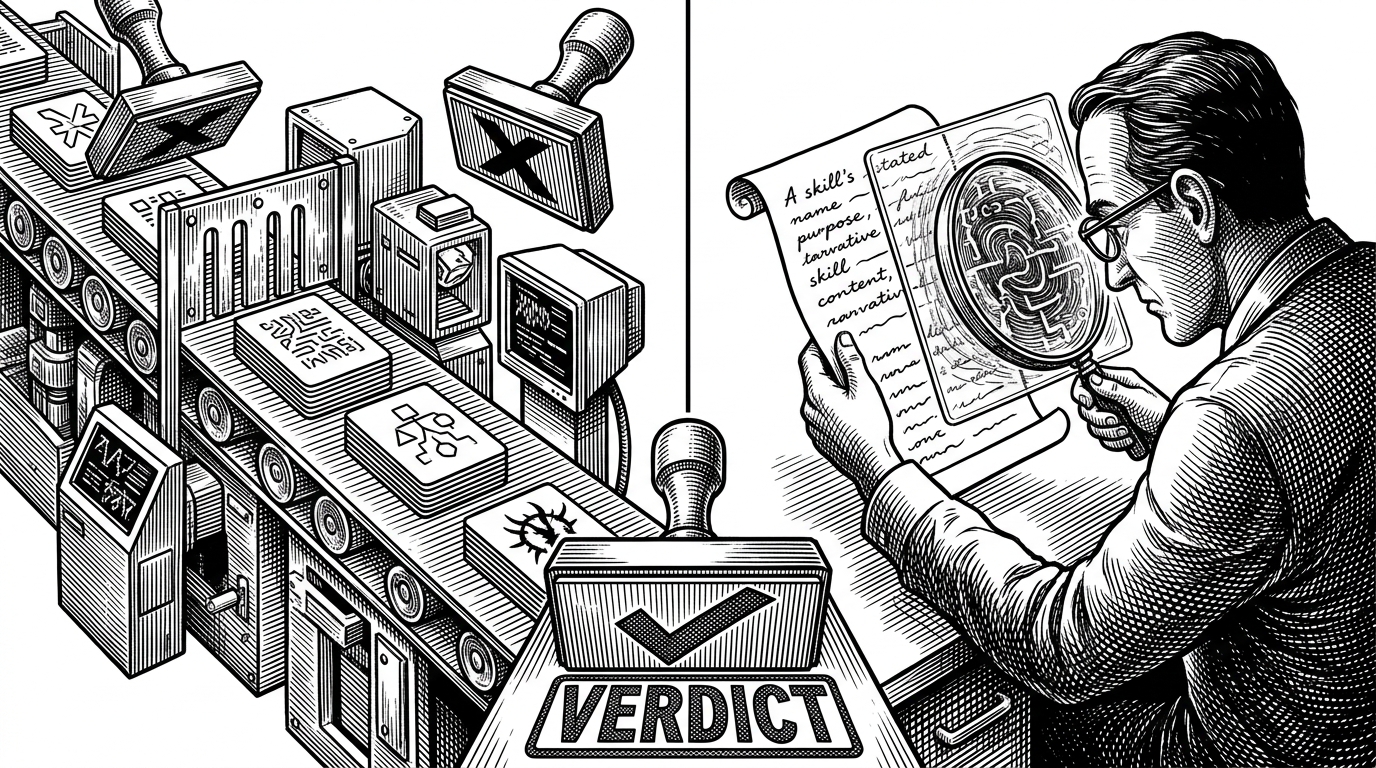
Research shows that 26.1% of skills contain vulnerabilities and 5.2% show likely malicious intent. SkillSpector helps you answer: 'Is this skill safe to install?'
That README line is the whole bet. If skills are becoming a distribution layer for agent capabilities, then installation needs a gate. Not a marketplace badge. Not a vague reputation score. A real scan.
SkillSpector is also clearly aimed at the modern agent stack, especially MCP-flavored tooling and other modular skills that can execute with broad privileges. The project is not pretending these are harmless prompts. It treats them as code with operational consequences.
The Hybrid Pipeline: Rules First, LLM Second
The repo’s core idea is simple: use fast static analysis first, then ask the LLM to judge intent and behavior. Static checks are good at known-bad signatures, dangerous function calls, suspicious files, and dependency risk. The semantic layer is there for the weird failure mode that matters most in agent security: the code looks acceptable, but the description is lying.
That is why the hybrid model matters. A regex will catch a grep-able secret. An AST pass will catch risky calls. The LLM pass can catch the mismatch between a skill’s promise and its actual behavior. That is the kind of deception conventional scanners were never designed to reason about.
Inside the Graph That Runs the Scan
SkillSpector is not a pile of scripts. It is an orchestrated graph. Input is resolved first, context is built once, then the analyzers fan out in parallel and write their findings back into shared state.
# Conceptual flow from the repo
resolve_input -> build_context -> analyzers -> meta_analyzer -> report

# The important pattern is not the syntax.
# It is the stateful fan-out and fan-in design.
That structure matters because the scanner has many overlapping senses. Some analyzers look at file contents. Others inspect ASTs. Others score behavior. The graph lets them work independently without losing the ability to reconcile all of it into one report.
The state model is especially clean. Findings accumulate instead of fighting over shared memory. That makes the tool easier to extend and easier to trust when multiple analyzers disagree.
This approach treats the skill as a deployable agent capability rather than as a static prompt. SkillSpector checks conventional software risks... [and] agent-specific risks, such as hidden instructions, prompt injection, trigger abuse, excessive agency, tool poisoning, and mismatches between a skill's declared purpose, requested access, and bundled behavior.
How It Avoids Redundant Work
The context builder is doing quiet systems work. It normalizes input, walks the file tree once, caches files, caches ASTs, and marks executable scripts so downstream analyzers do not repeat the same expensive discovery steps.
That is the difference between a prototype and an operational scanner. Precomputing shared context keeps the pipeline consistent and avoids making every analyzer rediscover the same facts in its own way.
What It Finds That Traditional SAST Misses
| Approach | What it catches well | What it misses |
|---|---|---|
| SkillSpector | Conventional code risks, agent-specific threats, and description-versus-behavior mismatches | It still depends on the quality of the input skill and the limits of semantic analysis |
| Traditional SAST | Known insecure patterns, risky calls, common vulnerabilities | Agent-specific risks like prompt injection, excessive agency, and narrative deception |
| LLM security tools | Prompt attacks, jailbreaks, harmful model behavior | Pre-install skill vetting and file-level trust decisions |
| Registry curation | Marketplace-level policy and human review | Tool-level inspection of any skill from any source |
The comparison is the point. SkillSpector is not trying to replace Bandit, Semgrep, or human registry review. It fills the gap between “this package exists” and “this package should run with agent privileges.”
Why SARIF Matters
SARIF output turns the scanner into something enterprise teams can actually use. It can plug into GitHub code scanning, CI pipelines, and downstream security workflows without inventing a new review process.
That is a subtle but important sign of maturity. The project is not just describing a research idea. It is trying to join the tooling stack where security teams already live.
The Bigger Bet NVIDIA Is Making
SkillSpector reads like a product, but it also reads like infrastructure. NVIDIA is helping define what trust looks like for agent skills, and it is doing it before the ecosystem settles on weaker defaults.
That matters because the next trust layer in AI is unlikely to be about model size. It is more likely to be about whether a capability package can be inspected, verified, and rejected before it gets a chance to do damage.