hillfate
GitHub
Explained projects
Local LLM Inference
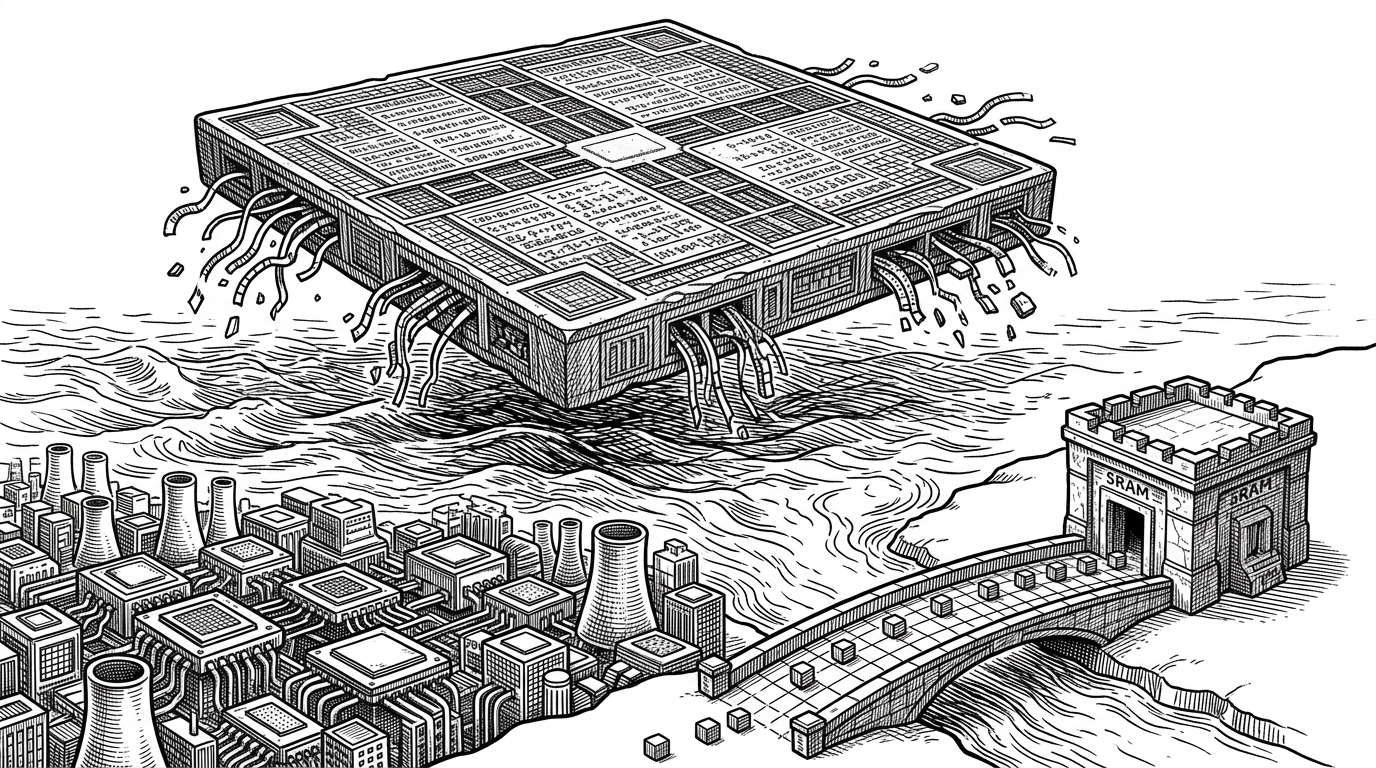
FlashAttention: The Algorithm That Beat the Memory Wall
How a tiled, IO-aware CUDA kernel turned exact attention into something GPUs can actually afford to run at scale.
14 min read · Jun 5, 2026
Yet to be explained