Local LLM InferenceAirLLM: The LLM Engine That Lives on Disk, Not in VRAM
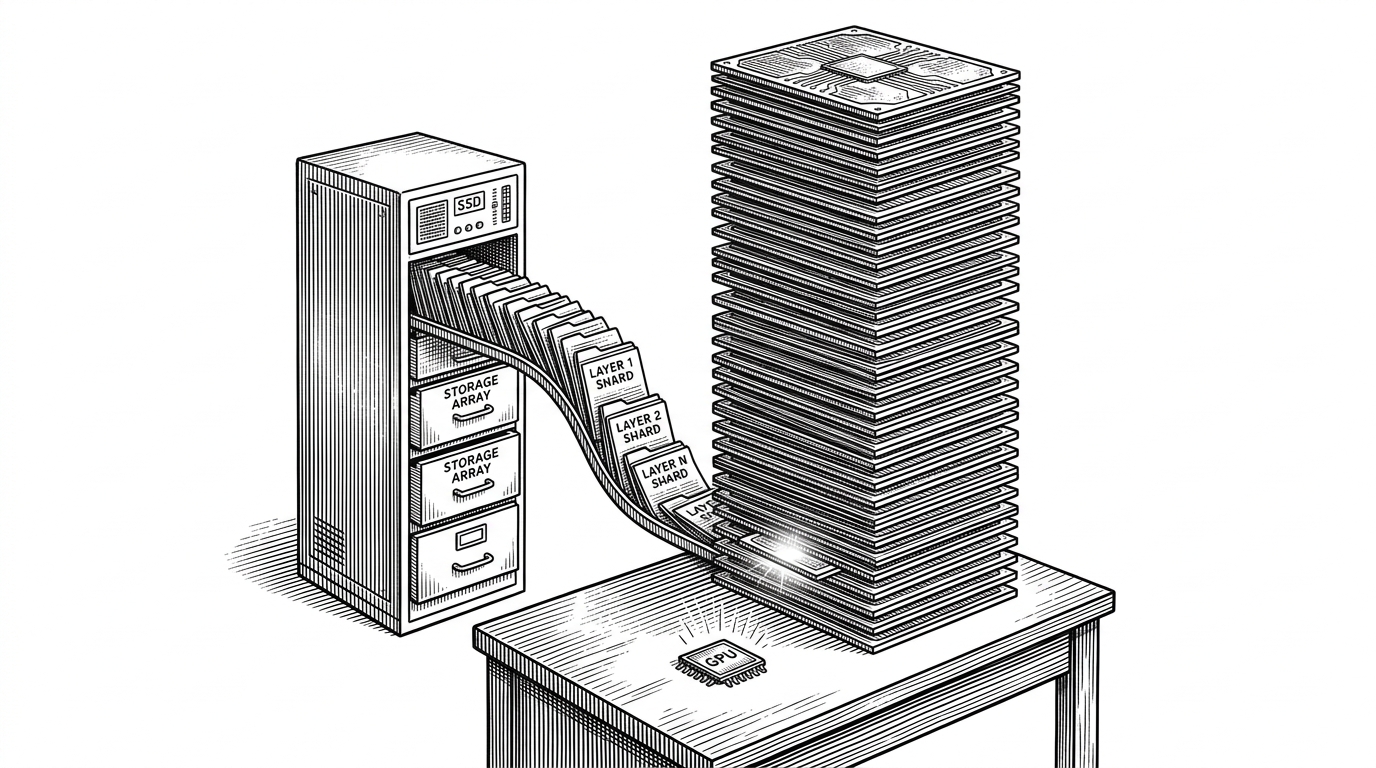
A layer-streaming inference library that makes 70B to 405B models run on consumer hardware by treating GPU memory as a transient workspace, not a home.
10 min read · Apr 12, 2026