FINSIGHT-LLM-Powered-News-Research-Assistant-for-Equity-Analysts: FinSight: A Tiny RAG Engine for Financial News That Answers With Receipts
A Streamlit and LangChain prototype that turns article URLs into a source-linked research layer for equity analysis, with a surprisingly clean split between one-time ingestion and repeat querying.
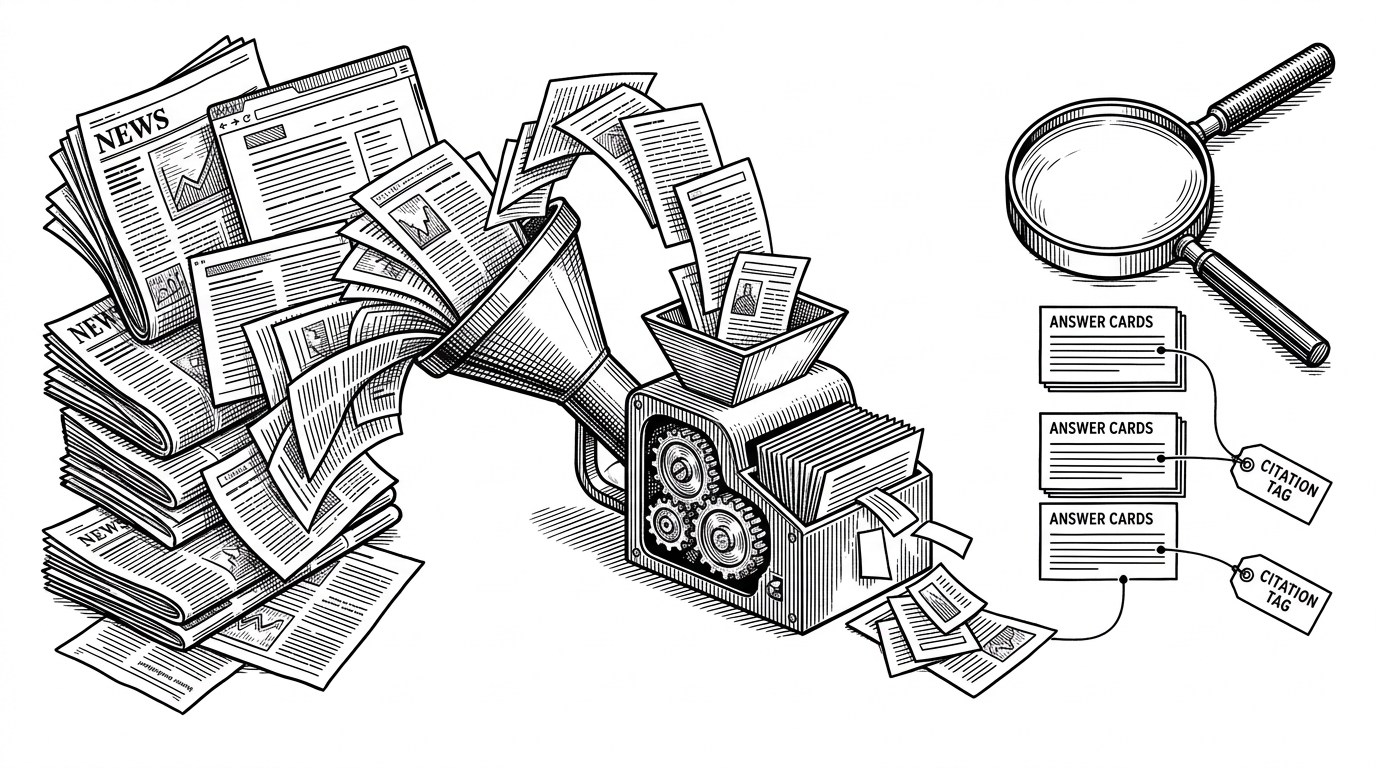
- FinSight’s real product is not finance trivia, it is a workflow that converts messy URLs into a durable evidence base for follow-up questions.
- Its strongest design choice is source attribution, because the app treats an answer without citations as unfinished.
- The repo is a practical RAG prototype, not production infrastructure, and its local FAISS store is what makes the loop fast and portable.
- In finance, the useful AI assistant is the one that can show its work, not just sound confident.
FinSight starts with a simple but sharp bet: analysts do not need another chatbot that vaguely knows markets. They need a way to turn a pile of news URLs into a private research layer they can query repeatedly, with sources still attached.
That shift matters because finance is a proof business. Speed helps, but speed without traceability is just a faster way to be wrong. FinSight aims at the middle ground: quick enough to reduce friction, grounded enough to survive scrutiny.
What FinSight Actually Changes
The repo compresses a familiar analyst loop. Read articles, extract what matters, revisit the same material with new questions, then check the original source when something feels off. FinSight turns that loop into software by making ingestion a one-time job and questioning a repeatable one.
FINSIGHT is a user-friendly news research tool designed to make your life easier. Input news article URLs, and FINSIGHT will deliver instant, data-driven insights. It's like having a dedicated research assistant at your fingertips, ready to answer your questions and provide valuable information from the articles you're interested in.
That README line is doing real editorial work. It describes the app as a research assistant, but the repo’s more interesting move is narrower: it builds a source-linked evidence pile from URLs and then lets the model answer against that pile, instead of against vague model memory.
Why Source Attribution Is the Real Product
| Pattern | What it optimizes for | Where it wins | Where it falls short |
|---|---|---|---|
| FinSight | Fast local research with citations | A single analyst or small team that needs source-linked Q&A on selected URLs | Limited scale, no enterprise data plumbing, no compliance layer |
| Bloomberg-style tools | Breadth, compliance, proprietary data | Deep market coverage and institutional workflows | Expensive, closed, and not something a solo developer can rebuild |
| FinGPT | Model depth and finance-specific training | Fine-tuned finance tasks and research on open models | Heavier lift than a quick app, and not centered on URL ingestion |
| Generic LangChain RAG | Building blocks for anything | Maximum flexibility for document Q&A | No finance-specific opinion, and no workflow by default |
The table above is the point: FinSight is not trying to beat Bloomberg at breadth or FinGPT at model specialization. It sits in the gap between them, where a compact app can still feel genuinely useful.
The design choice that makes this possible is RetrievalQAWithSourcesChain. That is not just a LangChain convenience. It is the mechanism that keeps the answer tied to the documents that produced it, which is exactly what an equity analyst needs when the next question is always, "Where did that come from?"
How the Pipeline Works
The implementation is plain, and that is part of the appeal. In main.py, FinSight loads URLs, cleans them, splits text into chunks, embeds those chunks, stores them in FAISS, and then queries the index through a source-aware QA chain.
urls = st.sidebar.text_input("Enter URLs").splitlines()
loader = UnstructuredURLLoader(urls=urls)
data = loader.load()

text_splitter = RecursiveCharacterTextSplitter(
    separators=["\n\n", "\n", ".", ","],
    chunk_size=1000,
)
chunks = text_splitter.split_documents(data)

vectorstore = FAISS.from_documents(chunks, embeddings)
with open("faiss_store_openai.pkl", "wb") as f:
    pickle.dump(vectorstore, f)

chain = RetrievalQAWithSourcesChain.from_llm(
    llm=llm,
    retriever=vectorstore.as_retriever()
)
result = chain({"question": query}, return_only_outputs=True)
Each step exists for a reason. URL loading turns messy pages into text. Chunking avoids forcing the retriever to swallow whole articles at once. Embeddings make semantic search possible. FAISS gives the prototype a local vector store. The final QA chain converts retrieval into an answer with source metadata.
That sequence also reveals the tradeoff. FinSight deliberately avoids infrastructure-heavy components. There is no hosted database, no multi-tenant service, no orchestration layer. The app works because it is small enough to keep the whole loop understandable.
The Clever Shortcut: Process Once, Query Many
| Choice | Benefit | Cost |
|---|---|---|
| Local pickle-backed FAISS | Portable, cheap, simple to run | Scale ceiling is low and memory use can become awkward |
| Managed vector database | Easier to scale and operate | More setup, more cost, less simplicity |
| Recompute embeddings every time | No persistence logic to maintain | Slow, repetitive, and wasteful |
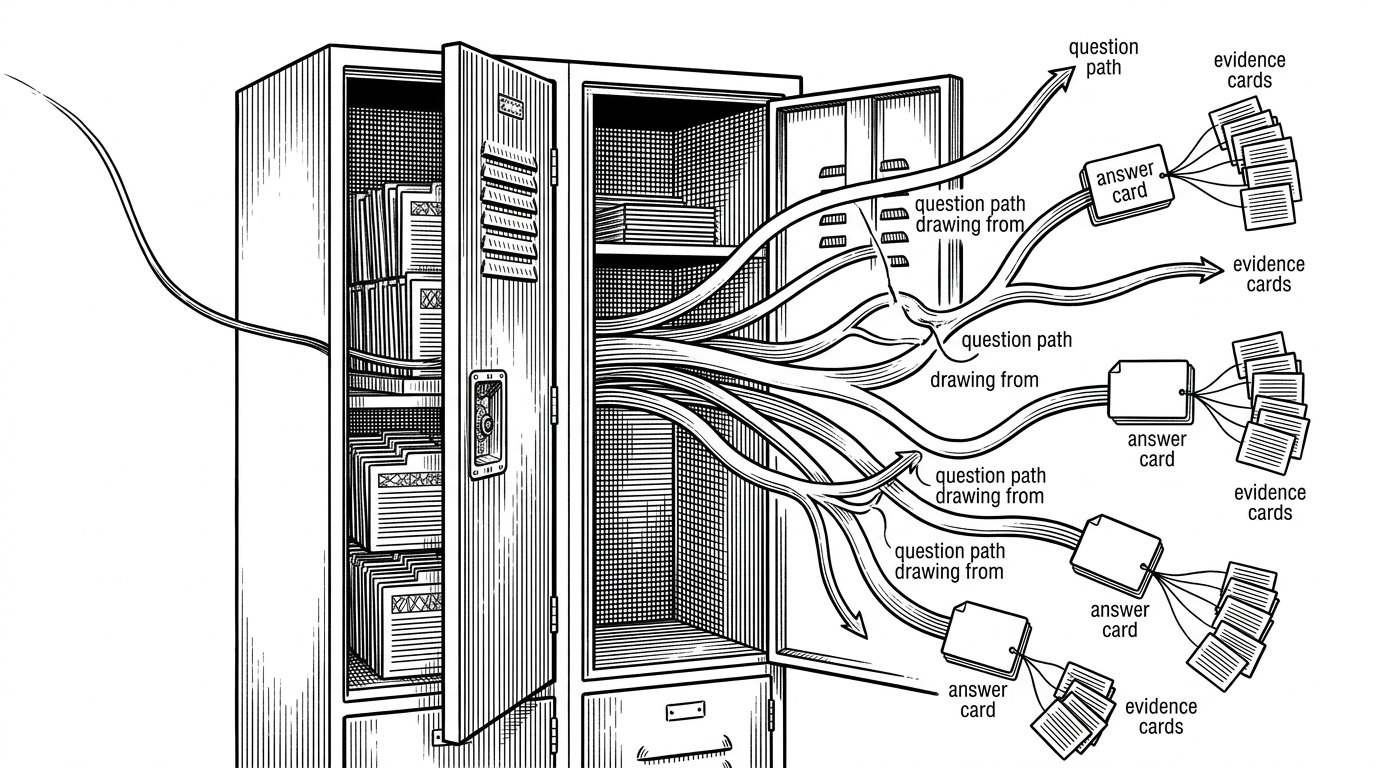
This is where the repo earns its prototype status. The pickle-backed FAISS store is not glamorous, but it is elegant in a narrow sense: it preserves the expensive part of the workflow so the analyst can keep asking questions without paying the ingestion tax again.
That shortcut also defines the ceiling. A local store is perfect for a lightweight demo and for small, repeated research sessions. It is not the shape you want if you need shared access, durability guarantees, or scale across many users.
Where It Sits in the Market
| Tool class | Best at | FinSight’s relationship to it |
|---|---|---|
| Bloomberg-like proprietary platforms | Deep, compliant, premium market coverage | FinSight borrows the analyst workflow but not the data moat |
| FinGPT-style projects | Financial model specialization | FinSight uses models as a component, not the headline |
| Generic LangChain or LlamaIndex apps | Reusable RAG scaffolding | FinSight is the concrete application layer sitting on top |
This is why the project is easy to underestimate. It does not try to be a platform. It does not try to train a better model. It tries to make one narrow research flow feel natural: add URLs, build evidence, ask questions, keep citations.
That lane is smaller than Bloomberg’s and less ambitious than FinGPT’s, but it is also more immediately usable for a solo analyst or a tiny team. In practice, that can be the sharper product choice.
What This Repo Suggests About LLMs in Finance
The bigger lesson is not that LLMs can summarize finance. Everyone already knew that. The more useful claim is that they can help verify finance, if the workflow forces them to stay close to source material.
FinSight is strongest when treated as a research substrate, not an oracle. It reduces the cost of revisiting context, which is often the real bottleneck in fast-moving markets. The model becomes more useful because it is fenced in by retrieval.
That is a sensible boundary for a repo at this stage. The code is clean, the loop is clear, and the limitations are visible. For a finance research assistant, that honesty is a feature, not a flaw.