`darnir/nsga2-Windows`: The C Code That Teaches Machines How to Compare the Incomparable
A compact NSGA-II implementation shows how Pareto ranking, constraint handling, and crowding distance turn multi-objective optimization into a survival game.
- NSGA-II matters because it ranks solutions without pretending all objectives can collapse into one score.
- This repo is valuable because it exposes the algorithm as a small set of readable C files instead of a polished framework.
- Constraint domination is the quiet center of the implementation, because feasibility decides before elegance does.
- Modern libraries hide the machinery, but this code shows how Pareto selection and crowding distance actually survive.
The hard part in multi-objective optimization is not generating candidates. It is deciding what survives when every candidate is better in one dimension and worse in another. `darnir/nsga2-Windows` is interesting because it turns that abstract problem into a concrete C implementation with a very specific rule: compare, rank, preserve spread, repeat.
That makes the repo less like a library and more like a small machine for thinking. It is a lean NSGA-II codebase built around the classic components of the algorithm: Pareto dominance, non-dominated sorting, crowding distance, crossover, mutation, and a problem-definition file that acts like a sandbox for test cases.
What this repo actually is
The structure is refreshingly direct. Core logic sits in files like dominance.c, rank.c, and crowddist.c. Genetic operators live in crossover.c, mutation.c, and tourselect.c. Infrastructure is pushed into allocate.c, list.c, and rand.c.
That flat layout is part of the appeal. There is no framework layer obscuring the logic. You can trace how a candidate moves from mutation into evaluation, then into dominance checks, then into a front, then into the final survivor set.
The algorithm’s real trick: rank first, then protect diversity
NSGA-II is built on a simple refusal: do not force conflicting objectives into one score. Instead, use non-dominated sorting to form fronts. Front 1 contains candidates not dominated by any others. Front 2 contains candidates only dominated by Front 1. The process continues until every candidate is assigned a rank.
That alone is not enough. If selection stopped there, the algorithm could converge to a narrow patch of the Pareto frontier and lose useful variety. So NSGA-II adds crowding distance, which favors candidates in sparse regions and protects the boundary points at the edges of the frontier.
| Step | What it does | Why it matters |
|---|---|---|
| Non-dominated sorting | Groups candidates into ranked fronts | Keeps trade-offs intact instead of collapsing them into one metric |
| Crowding distance | Measures how isolated a candidate is in objective space | Preserves spread across the frontier |
| Boundary protection | Gives edge solutions priority in a front | Prevents the search from shrinking inward |
| Elitist survivor selection | Keeps the best ranked candidates from the merged pool | Lets good solutions survive across generations |
How dominance.c turns constraints into a decision rule
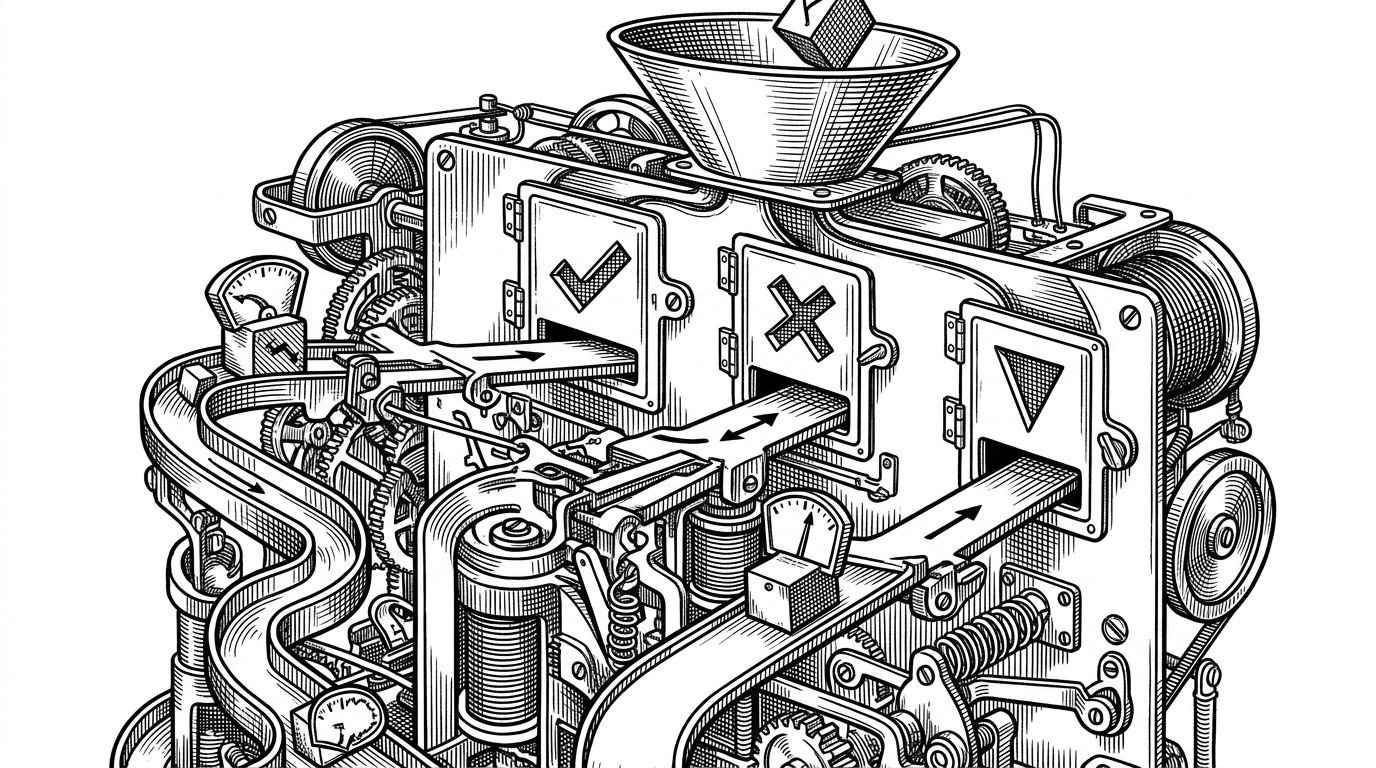
This is the most important function in the repo because it turns theory into a yes-or-no machine. In plain terms, feasible beats infeasible. If both candidates are infeasible, the one with lower constraint violation wins. If both are feasible, Pareto dominance decides the result.
/* Conceptual view of check_dominance */
if (a.feasible && !b.feasible) return 1;
if (!a.feasible && b.feasible) return -1;
if (!a.feasible && !b.feasible) {
    if (a.constraint_violation < b.constraint_violation) return 1;
    if (a.constraint_violation > b.constraint_violation) return -1;
    return 0;
}
/* both feasible: compare objectives for Pareto dominance */
That rule is deceptively small. It matters because optimization problems in the real world are full of infeasible candidates, and the algorithm needs a principled way to decide who gets another chance. Constraint-domination keeps the search from wasting effort on elegant but impossible solutions.
Why the code feels like 2005
The code reads like academic C from the era that valued transparency over abstraction. There are manual allocations, global state, a custom doubly linked list, and a problem-definition file that acts like a switchboard for benchmark problems. It is not modern in style, but it is easy to inspect.
| Trait | What this repo does | What modern libraries usually do |
|---|---|---|
| State management | Relies on globals and shared structs | Wraps state inside objects or classes |
| Memory handling | Manual allocation and cleanup | More automated lifecycle management |
| Front storage | Uses custom linked lists | Often uses arrays, vectors, or higher-level containers |
| Problem setup | Changes benchmark cases in a dedicated file | Uses configuration objects or problem classes |
That style has a cost. It is less convenient, less safe, and less friendly than modern wrappers. But it also strips the algorithm down to its moving parts. For a reader who wants to understand NSGA-II instead of just using it, that is a real advantage.
What modern libraries abstract away
The cleanest way to understand the repo’s place in the ecosystem is to compare it with toolkits like pymoo, DEAP, jMetal, and Platypus. Those projects are platforms. This repo is a mechanism.
| Project | Language | Scope | Setup complexity | How much of NSGA-II is exposed | Best for | Trade-off |
|---|---|---|---|---|---|---|
| darnir/nsga2-Windows | C | Single algorithm implementation | Low to moderate | High | Learning the mechanics, compact deployments | Less ergonomic than modern frameworks |
| pymoo | Python | Broad optimization framework | Low | Medium | Fast experimentation and visualization | Hides more of the core machinery |
| DEAP | Python | General evolutionary computation | Low | Medium | Custom evolutionary workflows | More framework overhead |
| jMetal | Java | Multi-objective optimization suite | Moderate | Medium | Structured academic and enterprise use | Heavier stack and more abstraction |
| Platypus | Python | Multi-objective optimization | Low | Medium | Practical NSGA-II workflows | Less bare-metal visibility |
The difference is not just language. It is visibility. In a toolkit, you get convenience, documentation, and integration. In this repo, you see the selection logic almost naked. That makes it a better teaching artifact than a production comfort blanket.
Why this repo still earns attention
The value here is not novelty. NSGA-II is a foundational algorithm, and the code in this repository is a compact way to see why it works. If you care about optimization, the interesting question is not whether the frontier exists. It is how the machine keeps trade-offs alive long enough to matter.
That is why this repo still deserves a look. It shows the guts of Pareto ranking, constraint-domination, and diversity preservation without burying them under a high-level API. You do not just get the answer. You get the mechanism.