Benchmarks & Eval
LLM benchmarks, eval harnesses, model comparison tools, and agent performance testing
97 explainers
Benchmarks & Eval
Decoding the Visual Syllabus: Avik-Jain/100-Days-Of-ML-Code
How a solo learner's visual shorthand became the de facto curriculum for the Scikit-Learn era.
Benchmarks & Eval
The Compiler in the Chatbox: How anthropics/prompt-eng-interactive-tutorial Formalizes the Black Art of Prompting
Moving beyond "vibes" to build deterministic, production-grade systems with Claude’s hidden structural levers.
Benchmarks & Eval
Auditing the Ground Truth with Cleanlab
How "Confident Learning" turns model uncertainty into a high-precision lens for fixing the world's messiest datasets.
Benchmarks & Eval
The Rollout Bottleneck: Inside THUDM/slime
How the framework behind GLM-4 bridges Megatron-LM and SGLang to scale reinforcement learning.
Benchmarks & Eval
ClawWork: The Benchmark That Makes AI Agents Pay Their Own Way
HKUDS turns agent evaluation into a simulated economy, with task bounties, inference costs, occupation-specific judging, and a survival rule that punishes waste.
Benchmarks & Eval
DeepSpec: The Full-Stack Machine for Teaching Small Models to Predict Big Ones
How DeepSeek-AI turned speculative decoding into a trainable, measurable pipeline, and why the real price of speed is often paid in storage, not compute.
Benchmarks & Eval
napkin-math: The Repo That Turns Guesswork Into Hardware Sense
A Rust-powered collection of benchmarks, scripts, and case studies that teaches engineers how to estimate systems in units that actually matter.
Benchmarks & Eval
openai/parameter-golf: The 16MB Weight Class for Language Models
A leaderboard repo where every byte, every second, and every optimizer choice changes the result.
Benchmarks & Eval
original_performance_takehome: When the interview is a scheduler
Anthropic's original performance take-home strips away compiler magic, exposes the bottlenecks, and asks whether you can fit real work into a rigid machine.
Benchmarks & Eval
CS-Fundamentals: The GitHub Repo That Turns CS Prep Into a Searchable Syllabus
A curated placement-prep library that compresses networking, DBMS, OOP, OS, and system design into a single interview-ready workflow, then adds AI prompts to make the material conversational.
Benchmarks & Eval
The End of the Magic Words Era: Inside EgoAlpha/prompt-in-context-learning
How a bilingual repository of Jupyter notebooks relies on academic papers to turn prompt engineering from a dark art into a structured, composable discipline.
Benchmarks & Eval
ShinkaEvolve: The Survival of the Fittest Code
Sakana AI's framework for autonomous discovery uses "Islands of Intelligence" and a ruthless Novelty Judge to evolve programs that outperform human engineers.
Benchmarks & Eval
Reverse-Engineering the Institutional Ghost in the Machine: raultrades/SMA-outfits
How a forensic research framework uses time-series data and GitHub commits to audit the "blackbox" algorithms governing public wealth.
Benchmarks & Eval
skill: PinchBench: The Blue-Collar Exam for AI Agents
Moving beyond synthetic riddles to see if LLMs can actually manage your calendar, audit your spreadsheets, and survive a messy workspace.
Benchmarks & Eval
LightReasoner: The Amateur's Guide to Expert Thought
How a tiny model's failures teach a giant model to reason with 99% less data.
Benchmarks & Eval
SnitchBench: Measuring the Narcissism of the Modern LLM
When "AI Safety" crosses the line from refusing a prompt to actively reporting the user to the authorities.
Benchmarks & Eval
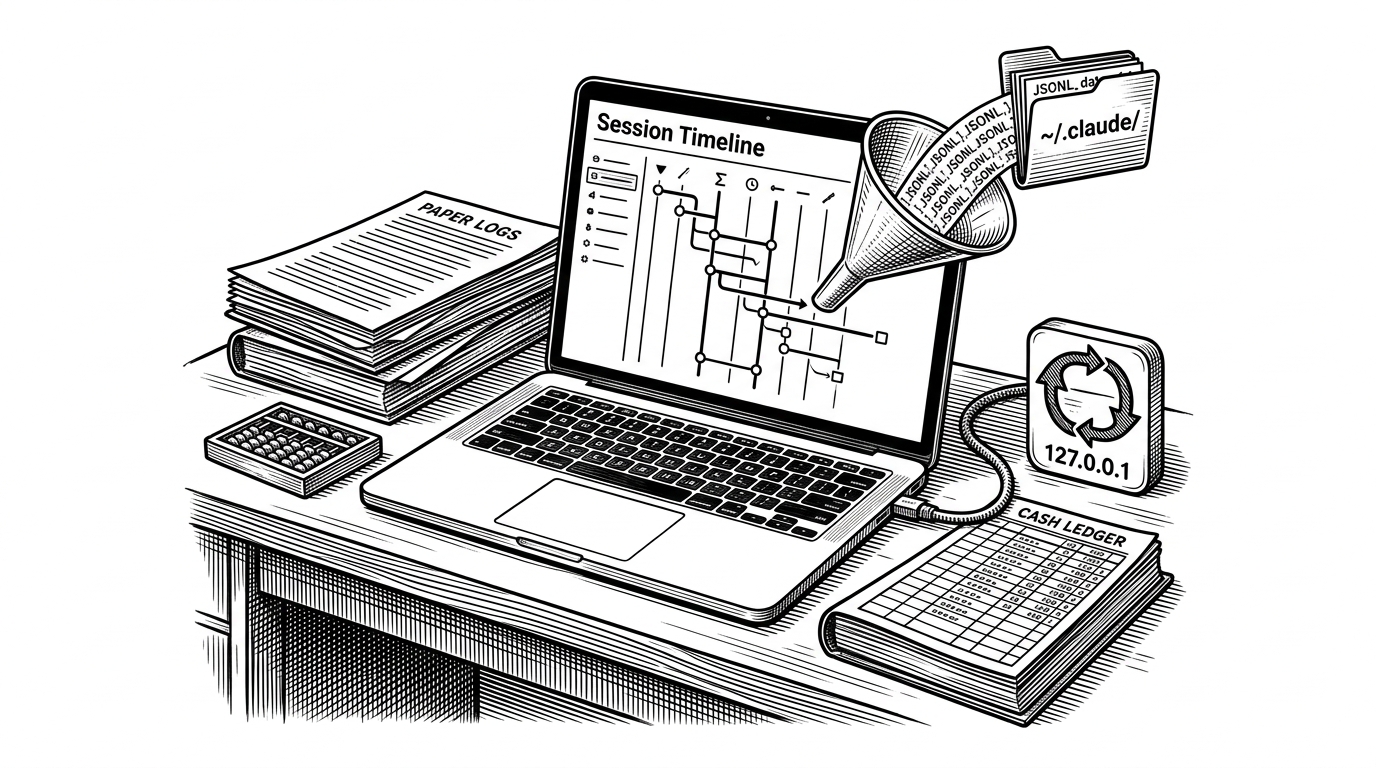
cc-lens: The Dashboard That Turns Claude Code Into a Readable Ledger
A local-first analytics tool that reconstructs cost, context, and session history from Claude Code’s raw logs, then presents the hidden shape of agent work without cloud telemetry.
Benchmarks & Eval
openai/circuit_sparsity: The Sparse Transformer That Comes with a Debugger
A hermetic GPT, hook-first inference, and a Streamlit visualizer turn mechanistic interpretability into something you can inspect, patch, and compare.
Benchmarks & Eval
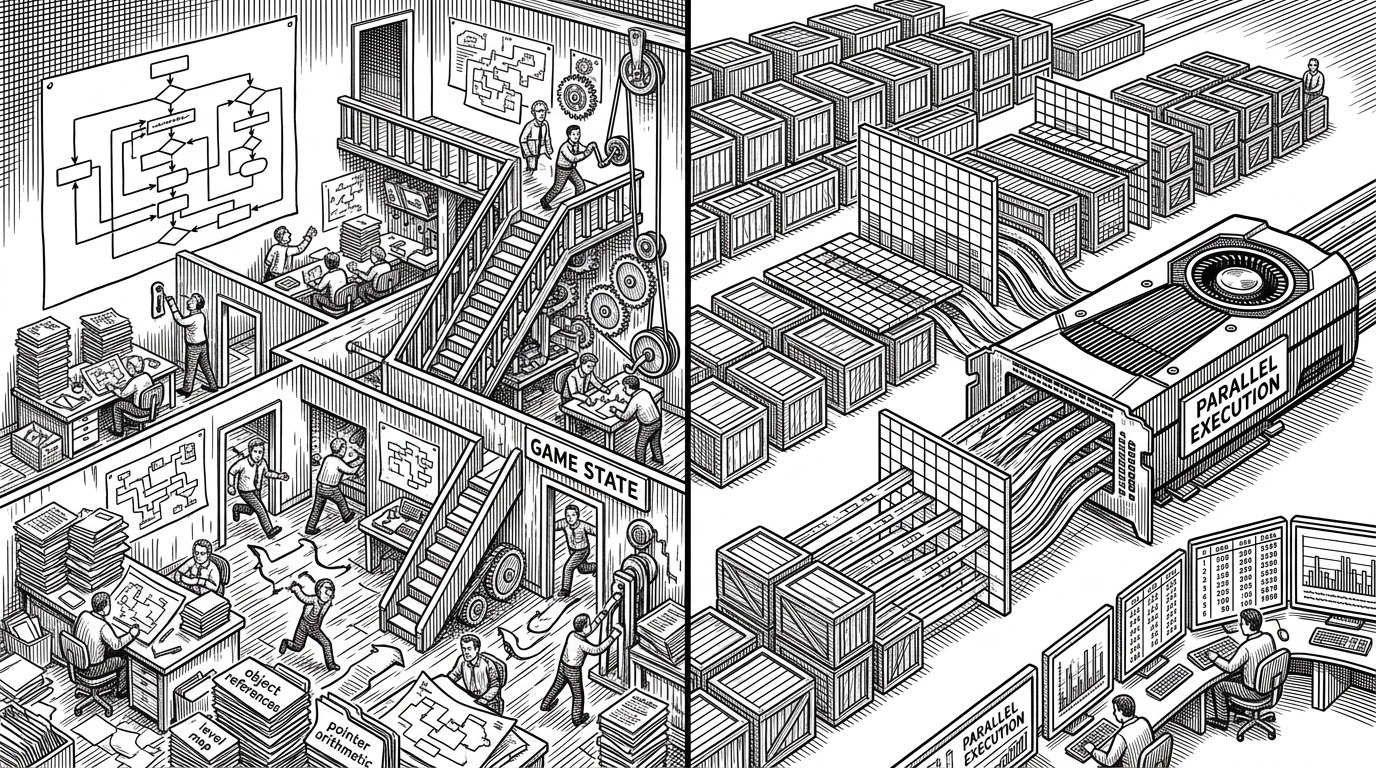
Craftax: The RL Benchmark That Turns a Game Into a Tensor Program
A JAX-native open-world environment that trades loops, branches, and CPU bottlenecks for masked state, vectorized logic, and absurd simulation throughput.
Benchmarks & Eval
GABRIEL Turns LLMs Into a Measurement Stack
OpenAI's toolkit treats ratings, rankings, extraction, and de-identification as repeatable research workflows instead of ad hoc prompts.
Benchmarks & Eval
NVIDIA/SOL-ExecBench: Benchmarking AI Against the Laws of Physics
How an adversarial testing engine and hardware clock-locking force AI code generators to compete against the absolute limits of silicon.
Benchmarks & Eval
skillgrade: Unit Testing the English Language
As AI agents move from chat interfaces to autonomous coworkers, Minko Gechev's new framework replaces "prompt vibes" with repeatable, dockerized evidence.
Benchmarks & Eval
SCORE: The Repo That Lets You Watch an AI Rewrite Scientific Code
A Google Research artifact that turns code generation into a visible refinement loop. The real product is not the model output. It is the audit trail.
Benchmarks & Eval
The Context Window is a Trap: Unpacking memorybench
How a unified evaluation framework is forcing AI memory providers to stop polluting prompts and start competing on token efficiency.
Benchmarks & Eval
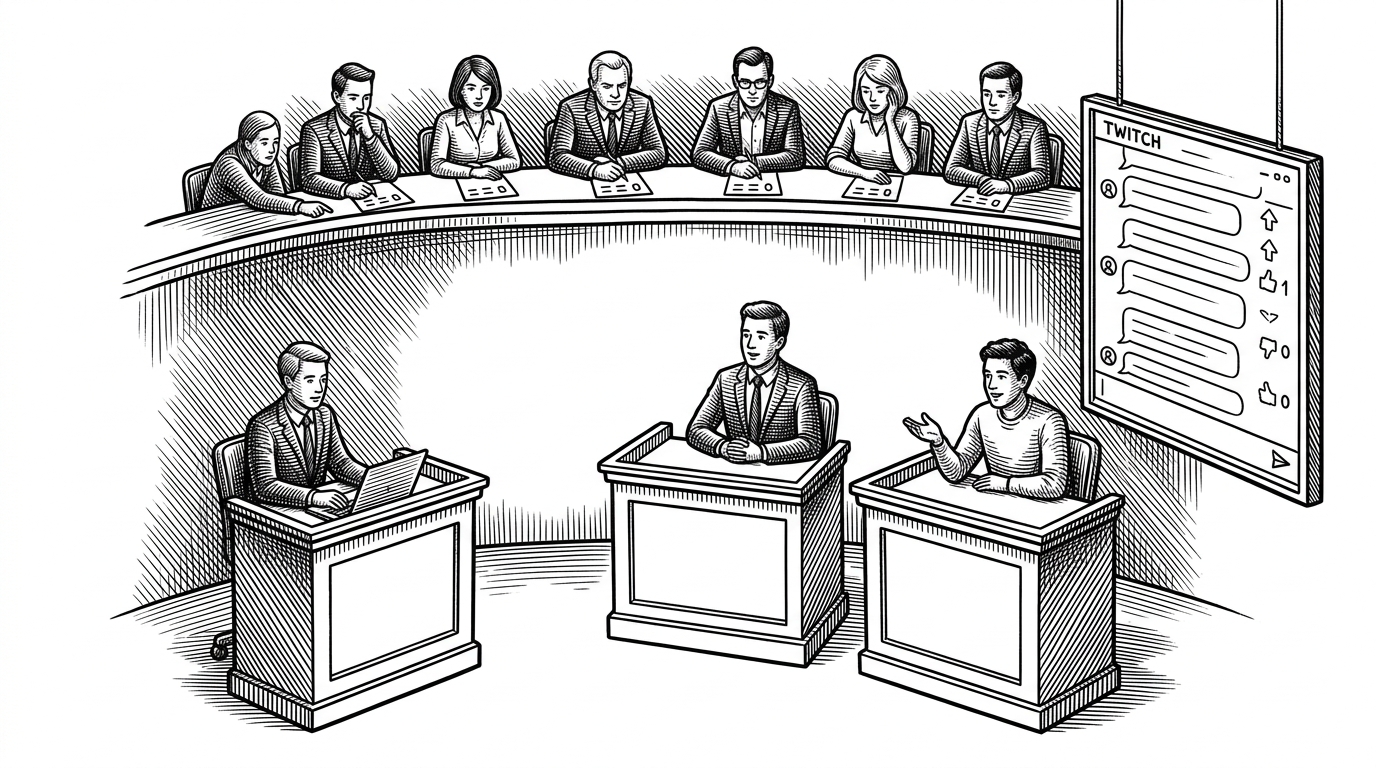
Quipslop: The AI Game Show Where Models Write the Prompt, Answer It, and Judge Themselves
A live, Twitch-ready comedy arena built in TypeScript and Bun, with a recursive voting loop that turns humor into a model benchmark and a streaming spectacle.
Benchmarks & Eval
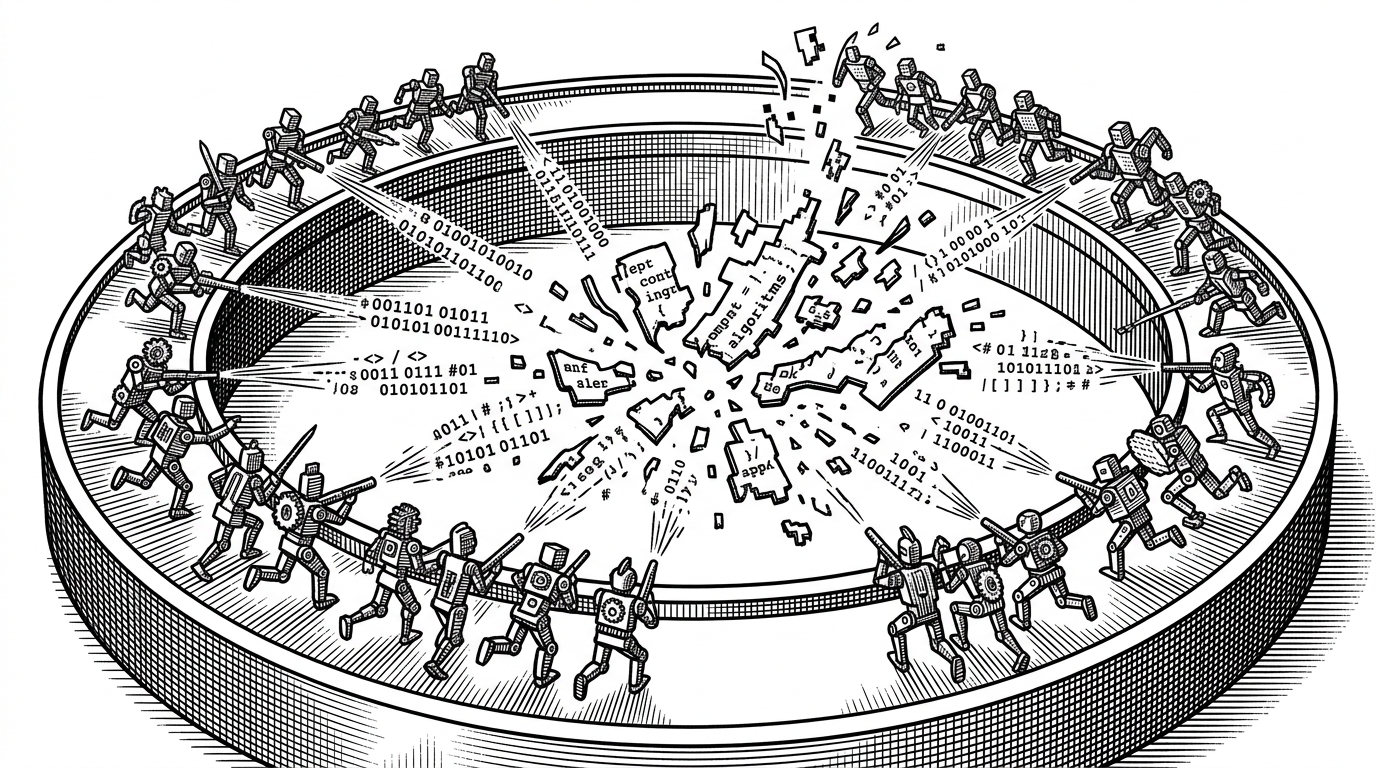
drq: When the benchmark fights back
Digital Red Queen uses an LLM to evolve Core War warriors in an adversarial loop, turning a retro programming game into a lab for open-ended adaptation.
Benchmarks & Eval
AudioTrust turns voice models into a trustworthiness test
A benchmark that scores audio systems on the failures text-only evals miss: spoofing, noise, accent bias, privacy leaks, hallucination, and safety drift.
Benchmarks & Eval
LogicKor: When a benchmark runs out of room
LogicKor turned Korean LLM evaluation into a test of grammar, instruction following, and cultural precision, then froze itself when the top models started crowding the ceiling.
Benchmarks & Eval
FutureShow: The AI Battle Arena Where the Future is the Benchmark
How HKUDS is solving the LLM contamination crisis by forcing models to bet against the real-world wisdom of the crowd.
Benchmarks & Eval
The 800K-Parameter Reasoning Engine: Inside chenglou/sotaku
How a four-layer Transformer uses test-time compute scaling and 2D spatial embeddings to solve extreme Sudoku without learning the rules.
Benchmarks & Eval
The Cost of Mathematical Certainty: Inside MIPVerify.jl
How a Julia framework uses Mixed-Integer Programming to stop playing cat-and-mouse with adversarial attacks and mathematically prove neural network robustness.
Benchmarks & Eval
Statbotics: The FRC Analytics Engine That Turns Robot Chaos Into Points
How one open-source stack combines Skew-Normal modeling, game-aware heuristics, and a public API to make FIRST Robotics Competition scouting more predictive, readable, and useful.
Benchmarks & Eval
robust-kbench: The benchmark that refuses to be gamed
Sakana AI’s robust-kbench turns CUDA evaluation into a robustness test, not a leaderboard trick.
Benchmarks & Eval
SkateBench: The Benchmark That Knows a Kickflip from an Inward Heel
A tiny TypeScript evaluation lab for seeing whether models understand skateboarding terminology, and what that precision costs.
Benchmarks & Eval
ZAPBench: Forecasting a Zebrafish Brain Like a Time Series
Google Research’s benchmark turns whole-brain calcium recordings, stimulus streams, and neuron position into a testbed for neural prediction.
Benchmarks & Eval
mseb: Audio finally gets its benchmark
MSEB turns a fractured field of sound embeddings into one contract for datasets, encoders, metrics, and leaderboards.
Benchmarks & Eval
synbad: The Lie of OpenAI Compatibility
Synbad is a diagnostic tool that proves why your coding agent’s LLM integration keeps breaking on edge cases.
Benchmarks & Eval
DeepResearch-Eval: Teaching Benchmarks to Read Like Editors
HKUDS’s evaluation framework scores long AI research reports for structure, insight, redundancy, and factual grounding by pairing LLM judges with live web verification.
Benchmarks & Eval
The Integrity Trap: How MiniMax-Provider-Verifier Polices the LLM Middlemen
When 'OpenAI-compatible' doesn't mean 'equivalent,' a new breed of deterministic validators is catching providers who cut corners on model deployment.
Benchmarks & Eval
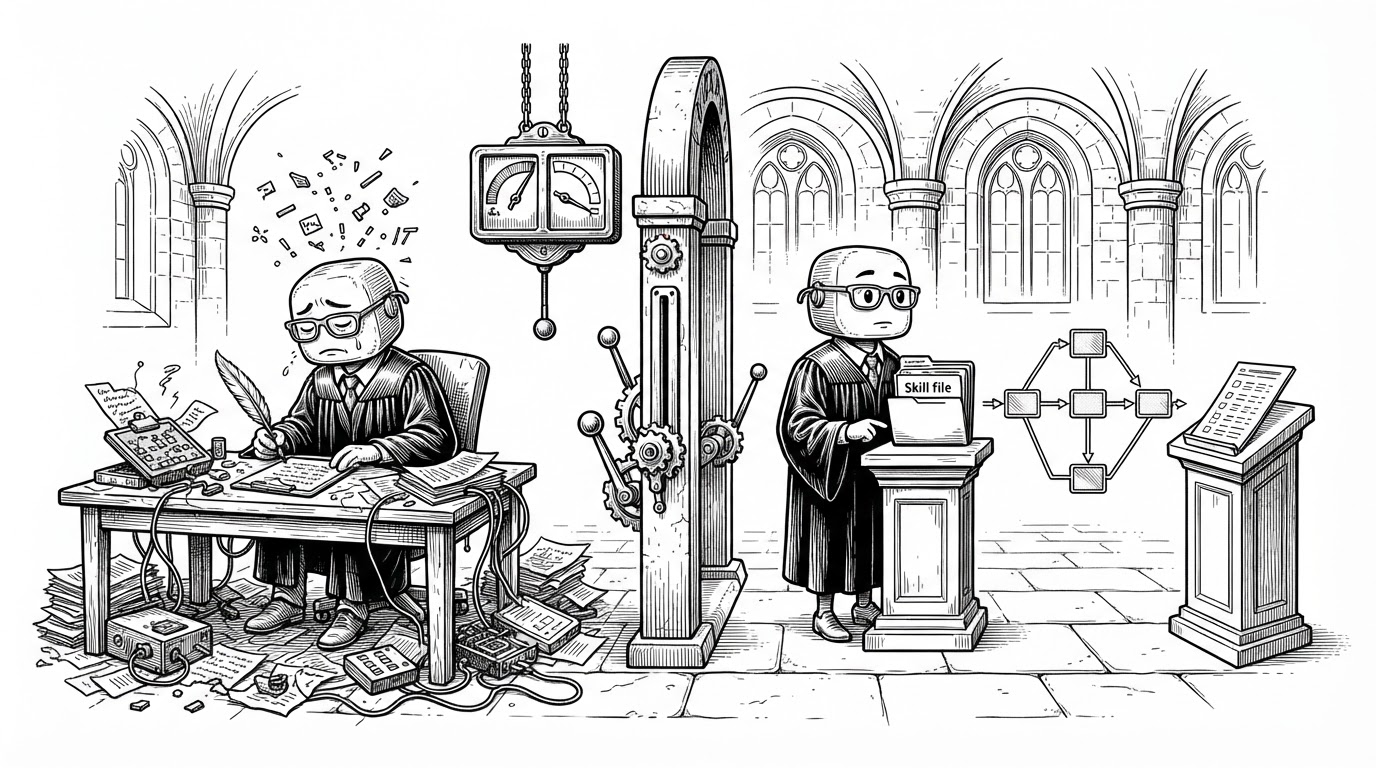
Appwrite Arena: The Benchmark That Tests Whether AI Can Learn Your API Before It Hallucinates
A domain-specific LLM arena that compares base-model memory, skill-file retrieval, and cost per answer across a fast-moving backend platform.
Benchmarks & Eval
QStorm: Simulating the Perfect Storm for Message Queues
Why testing asynchronous workers requires a different mental model than testing REST APIs, and how this Go-based engine generates high-precision pressure.
Benchmarks & Eval
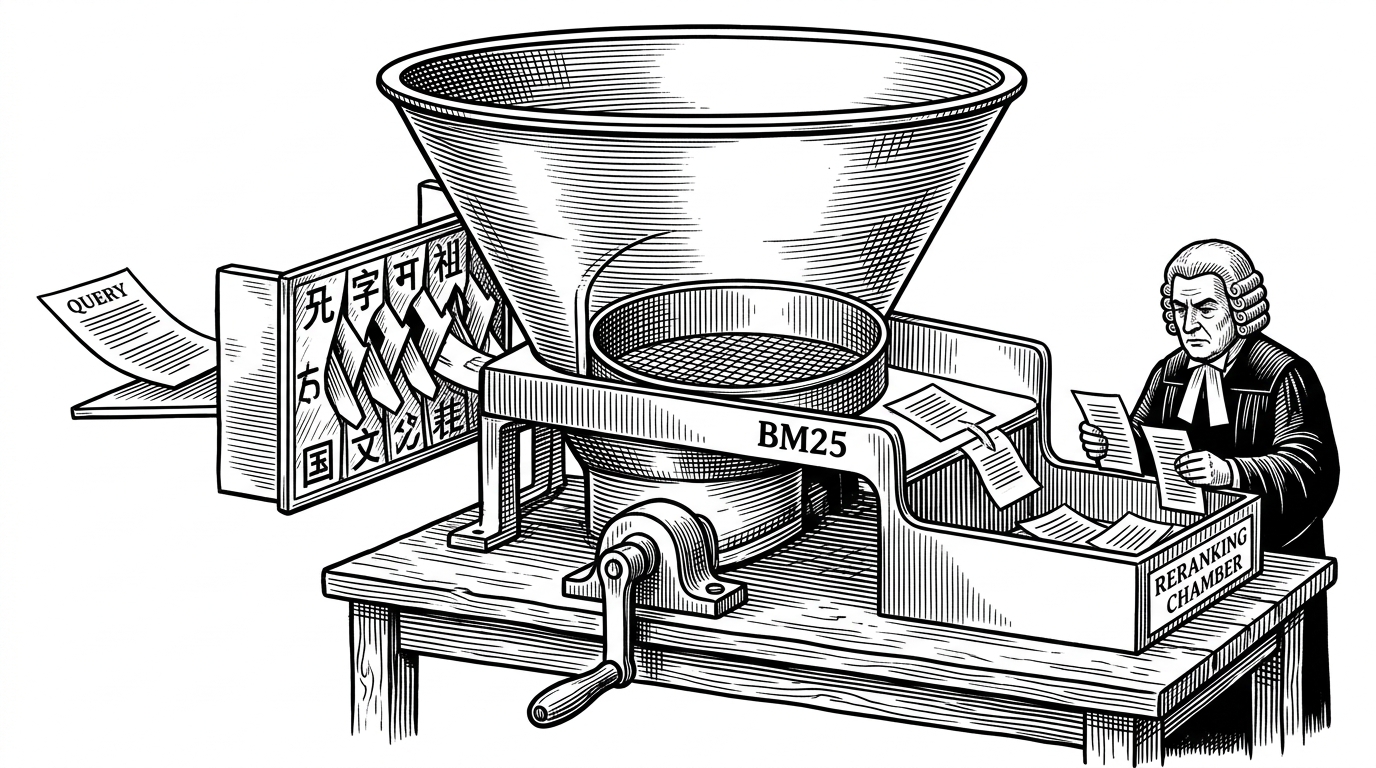
Inside instructkr/reranker-simple-benchmark: The Korean Reranker Benchmark That Starts Before the Reranker
A lightweight evaluation harness that shows how BM25, Korean tokenization, and a two-stage funnel shape what rerankers can actually prove.
Benchmarks & Eval
NVIDIA/omniperf: GitHub Pages as a Robotics Performance Database
A zero-dependency Isaac Lab dashboard uses manifest-driven JSON, Git LFS, Chart.js, and preview images to turn benchmark runs into a browsable, versioned record.
Benchmarks & Eval
FIREVAT: How an R Package Lets a Genetic Algorithm Hunt for Better Somatic Variant Filters
Instead of hard-coding cutoff rules, FIREVAT searches for the filter settings that keep true cancer mutations and discard sequencing artifacts, even across different variant callers.
Benchmarks & Eval
TransEvalnia Makes Translation Scores Explain Themselves
Sakana AI's evaluation framework asks an LLM to critique, compare, and rank translations before it ever emits a final verdict.
Benchmarks & Eval
QSOLKCB/QEC: The Quantum Error-Correction Stack That Treats Reproducibility as a First-Class Result
A deep look at a repo that builds QEC, QLDPC, invariants, and replay proofs into one deterministic system.
Benchmarks & Eval
SakanaAI/neuroevolution-for-ai: The README That Tries to Organize a Research Field
A curated Markdown map of labs, libraries, benchmarks, and learning resources shows how neuroevolution becomes usable when someone turns a field into a commons.
Benchmarks & Eval
RLVR-Directions: The Surgical Geometry of LLM Reasoning
Moving beyond binary correctness to identify and amplify the critical logical pivots within 20,000-token reasoning chains.