The Context Window is a Trap: Unpacking memorybench
How a unified evaluation framework is forcing AI memory providers to stop polluting prompts and start competing on token efficiency.
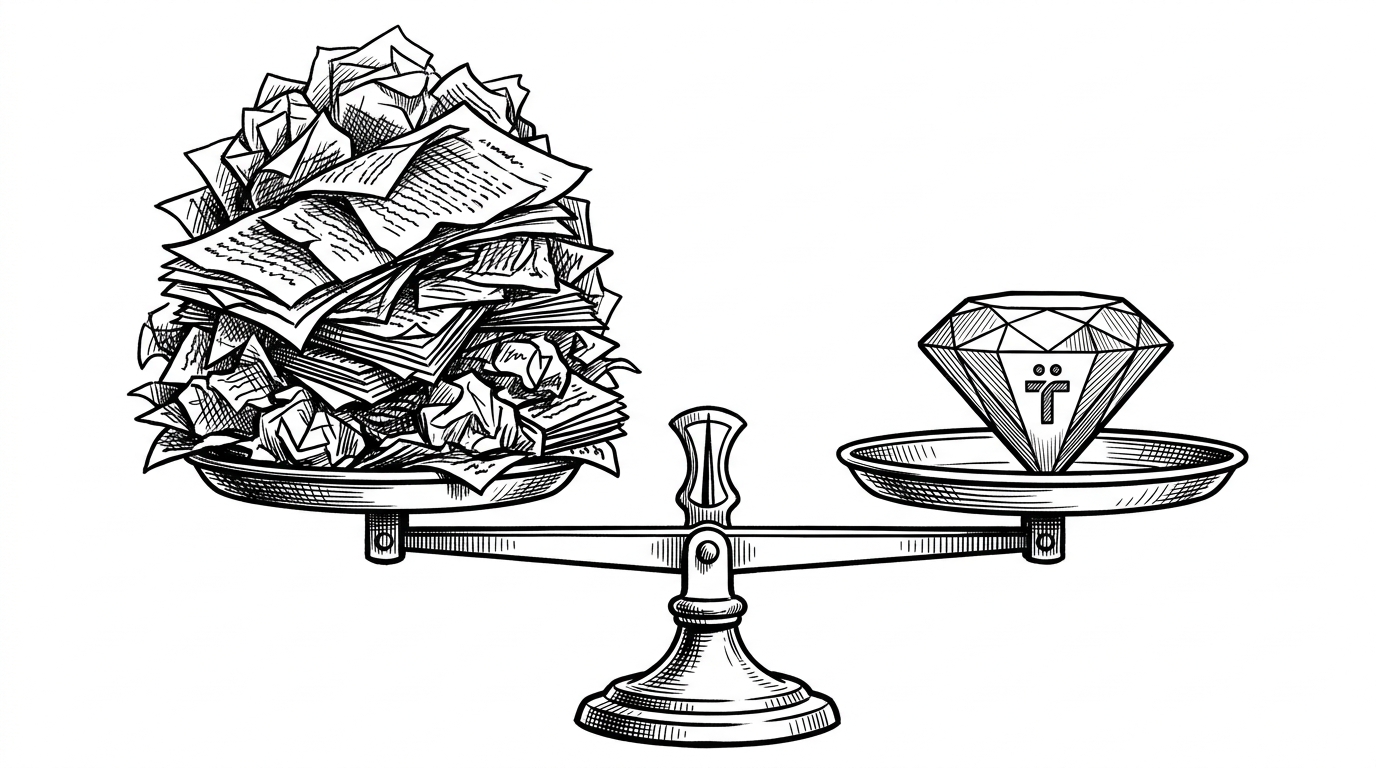
- Memorybench exposes the hidden cost of context window pollution by introducing MemScore, a composite metric of accuracy, latency, and token count.
- The framework forces proprietary memory providers into a single TypeScript interface to enable true apples-to-apples performance comparisons.
- An atomic checkpointing system protects expensive, long-running LLM evaluations from inevitable API rate limits and network failures.
- By replacing fragile string-matching with LLM-based evaluation, the system accurately scores nuanced conversational memory retrieval.
The Vanity Metric of Retrieval
The current state of Retrieval-Augmented Generation (RAG) evaluation is fundamentally flawed. If an AI agent successfully remembers a user's dietary restriction but dumps 5,000 tokens of irrelevant context into the prompt to do so, it fails in a production environment. Accuracy alone is a vanity metric. True performance requires precision.
Memorybench introduces a necessary corrective measure called MemScore. This composite metric divides retrieval accuracy by latency and total context tokens. By penalizing context bloat, it forces memory providers to compete on efficiency rather than brute-force retrieval.
Forcing the Gladiators into the Arena
Evaluating memory solutions has historically required writing custom integration code for every provider. Memorybench strips away these proprietary APIs. It forces systems like Zep, Mem0, and Supermemory into a strict TypeScript architecture defined in src/types/unified.ts.
export interface UnifiedSession {
  sessionId: string;
  interactions: Array<{ role: 'user' | 'assistant'; content: string }>;
  groundTruth?: string;
}

export interface UnifiedQuestion {
  questionId: string;
  text: string;
  haystackSessionIds: string[];
}
This unified interface treats memory as a haystack of sessions. By requiring all benchmarks to map their proprietary formats into these types, the project achieves genuine interoperability. You can finally test different providers side-by-side without rewriting your evaluation logic.
A pluggable benchmarking framework for evaluating memory and context systems.
Surviving the API Minefield
Benchmarking LLMs is expensive and fragile. Running a 5,000-question evaluation suite across three different LLM judges guarantees that you will hit a rate limit or a network timeout. Memorybench survives this reality through a rigorous checkpointing system.
The orchestrator executes in isolated phases: Ingest, Index, Search, Answer, and Evaluate. Every state change is written atomically to a checkpoint.json file using temporary file swapping. If an API fails during the Answer phase, the system resumes exactly where it left off. No tokens are wasted restarting the entire pipeline.
The Judge is an Algorithm
Traditional evaluation scripts rely on exact string matching or simple regex to determine if an answer is correct. This fails completely when evaluating conversational memory, where the same fact can be expressed in countless valid ways.
Memorybench utilizes a judge-agnostic evaluation layer. It uses an LLM to score the generated hypothesis against the ground truth. This qualitative approach handles the structural nuance of conversational retrieval.
Beyond the Ad-Hoc Script
The AI industry has outgrown standalone Python scripts for evaluating memory architectures. Building reliable agents requires treating memory as a distinct infrastructure layer with its own rigorous testing standards.
| Feature | memorybench | Standalone Benchmarks | Internal Ad-Hoc Scripts |
|---|---|---|---|
| Primary Metric | MemScore (Accuracy / Tokens / Latency) | Pure Accuracy | Custom / Subjective |
| Interoperability | Plug-and-play providers | Hardcoded implementations | Single provider lock-in |
| Failure Recovery | Atomic Checkpointing | Start Over | Basic Try/Catch loops |
| Evaluation Engine | Agnostic LLM Judges | Static String Match | Manual Verification |
By standardizing the evaluation pipeline, memorybench allows engineering teams to focus on improving their retrieval algorithms instead of debugging their test harnesses.