RLVR-Directions: The Surgical Geometry of LLM Reasoning
Moving beyond binary correctness to identify and amplify the critical logical pivots within 20,000-token reasoning chains.
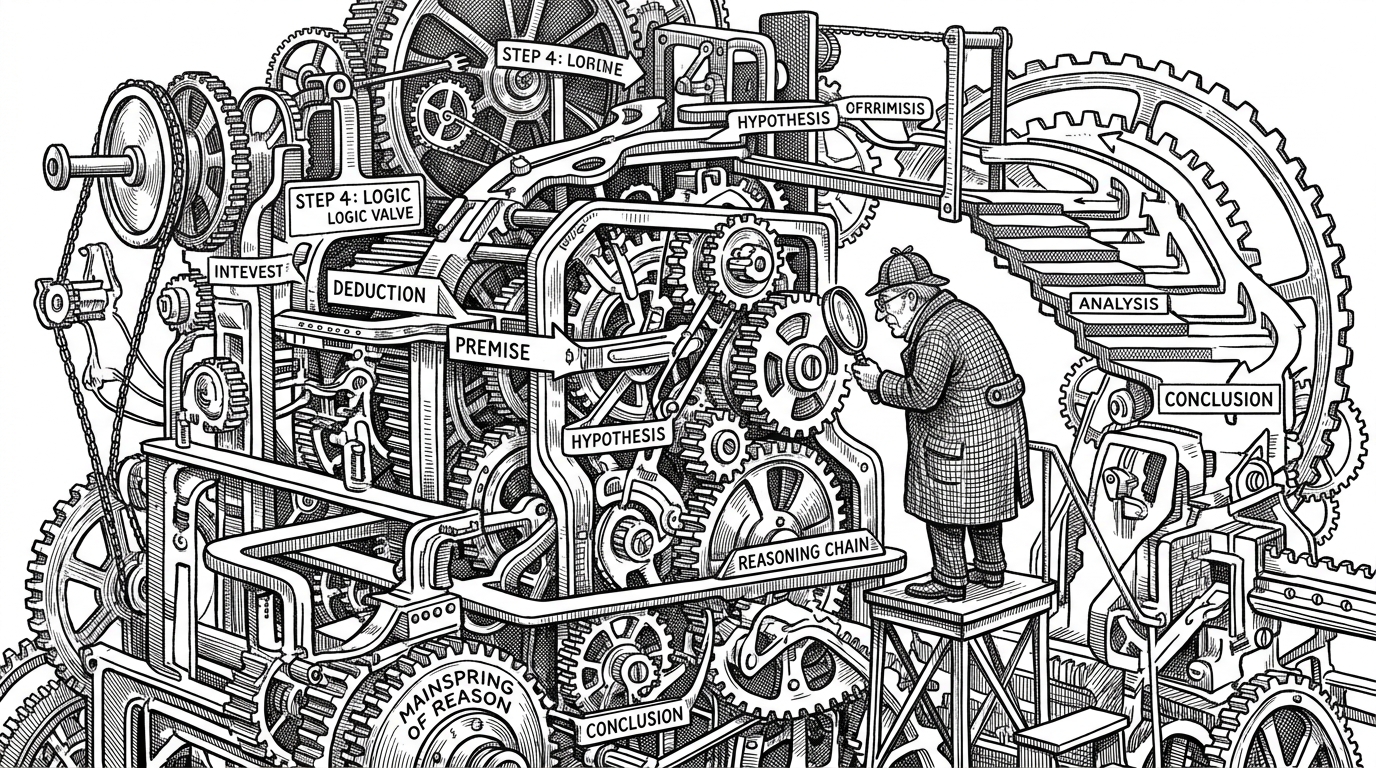
- Token Replacement identifies specific load-bearing tokens that hold long-form mathematical proofs together.
- The framework amplifies directional log-probability vectors rather than focusing solely on reward magnitude.
- Contrastive decoding uses an assistant model to nudge the base model toward more accurate logical extrapolations.
- Ulysses Sequence Parallelism enables the system to process 20,000-token reasoning chains across 128-GPU clusters.
Hunting the Load-Bearing Token
Reinforcement Learning with Verifiable Rewards (RLVR) has a credit assignment problem. If a model generates a 5,000-word mathematical proof and arrives at the correct answer, traditional methods reward the entire sequence. This is the equivalent of carpet bombing. It fails to isolate which specific logical pivot actually solved the problem.
RLVR-Directions takes a surgical approach. By implementing a technique called Token Replacement, the system stress-tests individual tokens during the reasoning phase. It systematically alters words to see if the underlying logic collapses. This mechanistic interpretability isolates the exact load-bearing tokens that hold a proof together.
Beyond the Magnitude: The Directional Shift
Most RLHF research focuses on the magnitude of rewards. The RLVR-Directions architecture shifts the focus to the geometry of the update space. The core metric is the log-probability change across the vocabulary.
Instead of treating all updates equally, the training framework reweights them based on directional consistency. If a token update pushes the model's internal probability distribution toward a verifiably correct logical step, that specific directional vector is amplified.
The Extrapolation Steering Wheel
The repository includes a standalone inference-time toolkit for extrapolated sampling. It pairs a base model with an advanced assistant model. The code calculates the entropy and divergence between the two models to decide exactly when to intervene and nudge the next-token prediction.
def weighted_sampling(base_logprobs, assistant_logprobs, w1, w2):
    # Align vocabularies and calculate the extrapolated logits
    logits = base_logprobs * w1 + assistant_logprobs * w2
    return logits
This contrastive decoding approach amplifies the direction provided by the assistant model. It forces the base model to extrapolate reasoning capabilities it could not reach on its own.
Orchestrating the 128-GPU Symphony
Training a 32B-parameter reasoning model requires massive infrastructure. The repository heavily modifies the ByteDance verl framework to coordinate a 128-GPU Ray cluster. The orchestration scripts separate the actor (the model being trained) from the rollout engine (vLLM).
To handle 20,000-token reasoning chains, the architecture relies on Ulysses Sequence Parallelism. This splits a single massive context window across multiple GPUs, treating length as a soft constraint rather than truncating critical mathematical proofs.
The New Standard for Verifiable Rewards
RLVR-Directions transitions away from traditional Proximal Policy Optimization (PPO). It embraces Group Relative Policy Optimization (GRPO) and Decoupled Clip and Dynamic Sampling Policy Optimization (DAPO).
By enforcing objective spatial and mathematical verification, the model cannot hallucinate its way to a high score. It must mathematically reach the destination, setting a rigorous new benchmark for embodied and logical AI tasks.
| Method | Reward Source | Scaling Limit |
|---|---|---|
| PPO | Human Preference (Subjective) | Memory-bound (Requires Critic) |
| GRPO | Group-Relative (Objective) | Compute-bound |
| DAPO (RLVR-Directions) | Verifiable + Directional | Reasoning-bound |