Quipslop: The AI Game Show Where Models Write the Prompt, Answer It, and Judge Themselves
A live, Twitch-ready comedy arena built in TypeScript and Bun, with a recursive voting loop that turns humor into a model benchmark and a streaming spectacle.
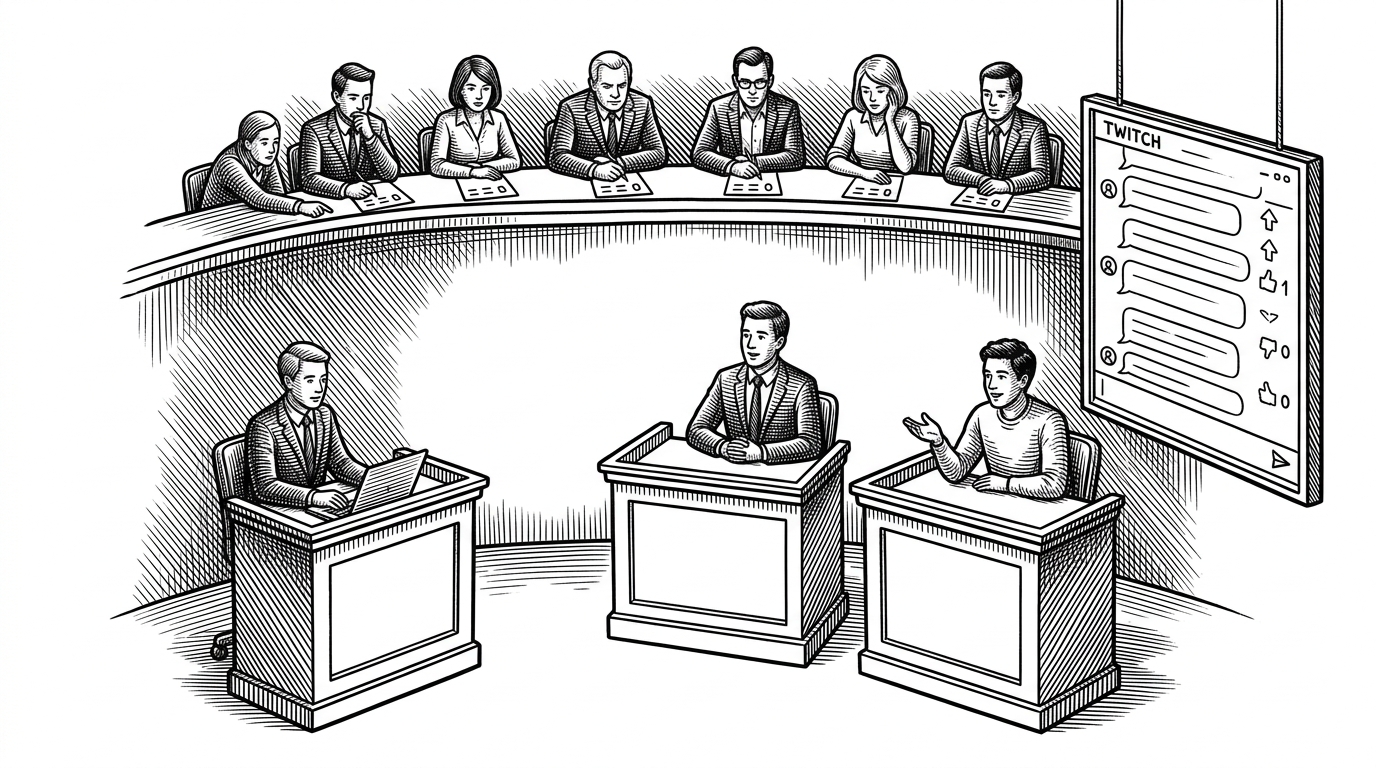
- Quipslop turns humor into a closed-loop evaluation system where models can be both performers and judges.
- The project matters because it tests taste, not correctness, which makes disagreement visible instead of hiding it behind a score.
- Bun, TypeScript, SQLite, and WebSockets give one developer enough leverage to run a real-time broadcast game without much infrastructure sprawl.
- The dual audience design, host on one side and viewers on the other, is what makes the project feel like a production show instead of a toy demo.
The weirdest thing about Quipslop is also the most revealing. One model writes the prompt, two models answer it, then other models and Twitch viewers decide which answer wins. That turns a joke contest into a looped experiment about taste, status, and whether machines can recognize the kind of joke they reward.
The strange part: the models are both performers and judges
Most AI demos stop at output. Quipslop keeps going. A round starts with a prompt, moves to two competing answers, and ends with a vote from a rotating panel that includes other models and the Twitch crowd.
That structure changes the meaning of the output. The project is not asking whether a model can be funny in isolation. It is asking whether a model can compete inside a social setting where judgment is the real product.
A few days ago, I ran into Theo’s Quipslop , which uses 7 modern LLMs to generate and score jokes, and it looked like a very nice testbed for one idea.
Why humor is a better test than another benchmark
Humor is a useful stress test because it is subjective, fast, and legible. A good joke fails loudly. A weak one does not need a long postmortem to explain why it missed.
| Dimension | Traditional benchmark | Quipslop |
|---|---|---|
| What is measured | Accuracy against a known answer | Preference under social judgment |
| Who decides | A scoring script | Models plus Twitch viewers |
| Output | A single score | A winner, a reaction, and a visible argument |
| What it reveals | Competence on task | Taste, style, and model personality |
How Quipslop runs the whole arena
The codebase is organized like a live system, not a demo. game.ts holds the round state machine. server.ts handles transport, rate limits, and WebSockets. db.ts persists every round so the show can keep moving even when a model call is flaky or a viewer refreshes the page.
type RoundPhase = 'prompting' | 'answering' | 'voting' | 'done'

interface RoundState {
  phase: RoundPhase
  prompt: string
  answers: [string, string]
  votes: Record<string, number>
  winner?: 0 | 1
}

async function withRetry<T>(task: () => Promise<T>, attempts = 3): Promise<T> {
  for (let i = 0; i < attempts; i++) {
    try {
      return await task()
    } catch (error) {
      if (i === attempts - 1) throw error
      await Bun.sleep(250 * (i + 1))
    }
  }
  throw new Error('unreachable')
}
That retry loop matters more than it looks. Live AI systems do not fail gracefully by default. They stall, time out, or drift, and a game show has no patience for that. The code is built to absorb those failures and keep the room moving.
The Bun bet: one runtime, fewer moving parts
Bun is not the headline, but it explains the shape of the repo. The same runtime gives Quipslop fast iteration, built-in SQLite, and WebSocket support without splitting the project across a pile of packages and services.
| Layer | Typical stack | Quipslop's stack |
|---|---|---|
| Runtime | Node plus extras | Bun |
| Persistence | Separate database layer | bun:sqlite |
| Realtime | Standalone socket service | WebSockets in the same runtime |
| Iteration | Many moving parts | One tight loop |
Two UIs, two audiences
Quipslop is split between backstage control and broadcast polish. The Ink CLI is for the host and developer. The React web UI is for viewers who want clean vote bars, model labels, and a sense that the show is happening live.
| Surface | Who it serves | What it optimizes for |
|---|---|---|
| Ink CLI | Host and operator | Control, debugging, timing |
| Web UI | Audience | Clarity, motion, spectacle |
| Shared backend | Both | A single source of truth |
What the code suggests about the creator
Quipslop feels like the work of a builder who cares about production details even when the product is playful. The repo is typed, modular, and opinionated about runtime choice. That combination usually shows up in infrastructure tools, not in comedy projects.
The contributor list is small, which makes the polish more legible. This is not a sprawling community sandbox. It is a focused project with a clear authorial point of view.
What Quipslop is, and what it is not
Quipslop is not a standard benchmark. It is not a generic chatbot wrapper. It is also not just a Quiplash clone with AI paint on it.
It is closer to a live evaluation harness wrapped in a show format. That is why it works as both software and argument. It asks a sharper question than most AI demos: when models judge each other’s jokes, what kind of taste emerges, and how does that differ from humans?
| Adjacent thing | Why Quipslop is different |
|---|---|
| Traditional benchmark | It evaluates social preference, not task accuracy |
| Party game clone | The contestants and judges are models, not people |
| Stream overlay | The overlay is backed by a real state machine and persistence layer |