context-score: The Tiny CLI That Grades a Website for AI Comprehension
A single-file Node.js auditor that turns your site into a scorecard for identity, structure, depth, connectivity, and machine-friendly discoverability.
- context-score reframes web auditing around machine comprehension, not search ranking.
- Its five-pillar model turns a vague idea like AI readiness into a concrete scoring system.
- The single-file Node implementation is part of the argument, because the tool is meant to be lightweight, portable, and opinionated.
- The real shift is from optimizing pages for crawlers to making a site easy for AI systems to interpret, cite, and trust.
Websites are no longer read by humans alone. Search bots still matter, but LLMs and AI agents now summarize, cite, and route attention too. context-score asks a sharper question: can a machine understand what this site is for, and trust what it finds?
That shift changes the unit of analysis. Traditional SEO looks for keywords, links, and technical hygiene. This repo treats a site as a bundle of machine-readable promises: identity, structure, depth, connectivity, and discoverability.
Why websites now need a context audit
The point is not to game an algorithm. It is to make meaning legible. If an AI system lands on a site and cannot quickly find the canonical files, the high-value pages, and the semantic signals that explain the content, the site is effectively harder to use.
That is why this project feels timely. It captures a new discipline in one small script: context engineering for the web.
The five pillars of context
The project’s real invention is the scoring model. Instead of a grab bag of SEO checks, it organizes the audit into five pillars that each capture a different kind of machine-readability.
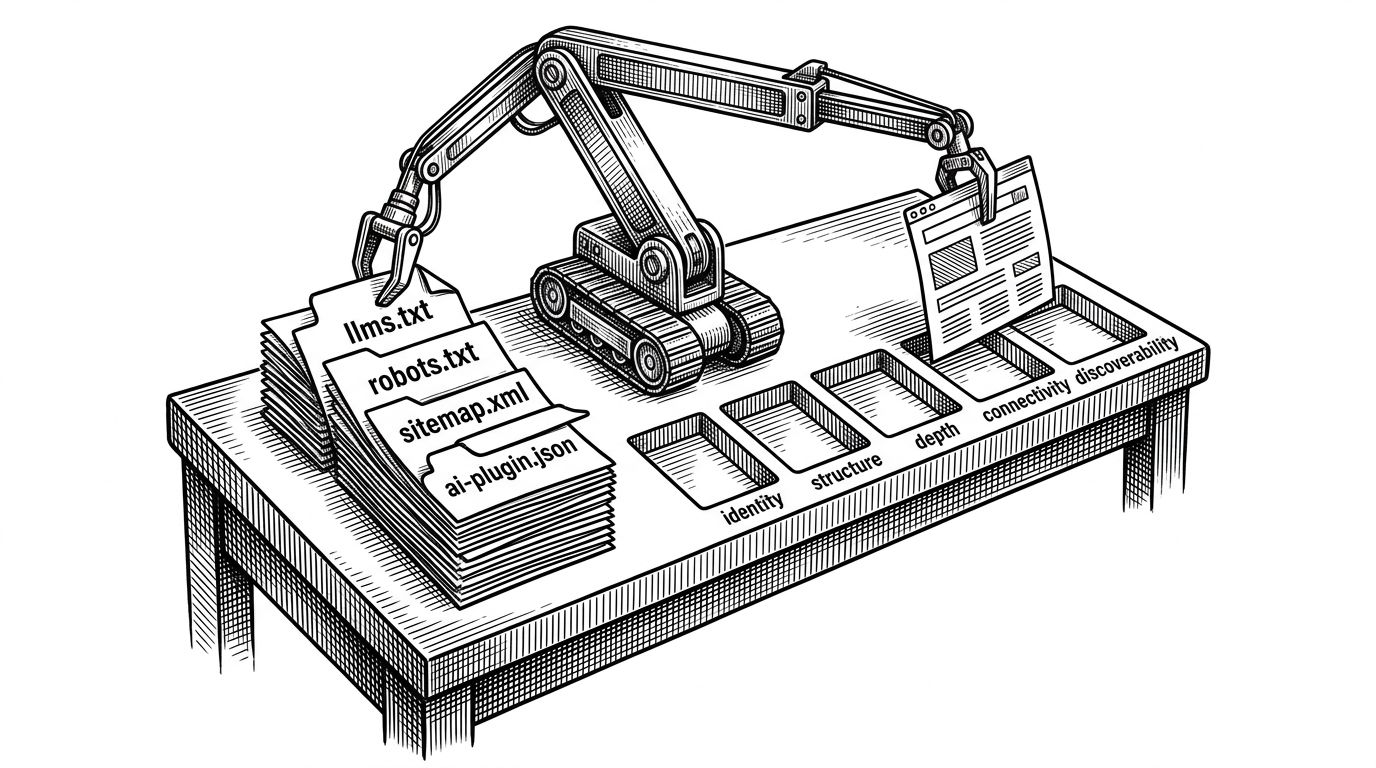
Identity checks whether the site tells machines who it is. Structure looks for the scaffolding that makes a site navigable, like robots.txt and sitemap.xml. Depth rewards pages that actually say something useful, not just pages that exist.
Connectivity measures whether the site explains itself through internal links and related content. Discoverability looks for higher-order signals like SpeakableSpecification and ai-plugin.json. In other words, the score is not just about presence. It is about whether the site behaves like a coherent information system.
What the crawler actually looks for
The audit starts with a homepage fetch, then checks a short list of AI-critical files. It also probes likely high-value paths such as /about, /glossary, and /changelog, because context is often stored where site owners think humans will look, not where crawlers are guaranteed to go.
const knownPaths = ['/about', '/glossary', '/changelog'];
const aiCritical = ['/llms.txt', '/robots.txt', '/sitemap.xml', '/.well-known/ai-plugin.json'];

for (const path of aiCritical) {
  await fetch(new URL(path, siteUrl));
}

for (const path of knownPaths) {
  await fetch(new URL(path, siteUrl));
}
It is an opinionated crawler. It is not trying to be a general-purpose site spider. It is trying to surface the files and pages that help a language model understand what the site is, what it contains, and how to cite it.
Why regex is a feature, not a bug
The engineering choice is almost stubborn in the best way. The repo is a single-file Node script, zero dependencies, and it uses regex to extract enough structure to score a site quickly. That makes it portable and easy to run via npx.
The trade-off is obvious. Regex is fast and lightweight, but it is brittle when a site leans heavily on client-side rendering or exotic HTML structures. This tool is not pretending to be a headless browser. It is making a deliberate bet that a simple heuristic engine is enough to answer an important first-pass question.
const regex = /href=["']([^"'#]+?)["']/g;

function extractInternalLinks(html) {
  const links = [];
  let match;
  while ((match = regex.exec(html)) !== null) {
    links.push(match[1]);
  }
  return links;
}
That restraint is part of the design. The script is meant to be readable, hackable, and fast enough to use as a routine audit, not a framework you need to learn before you can ask a question.
The new SEO is semantic, not mechanical
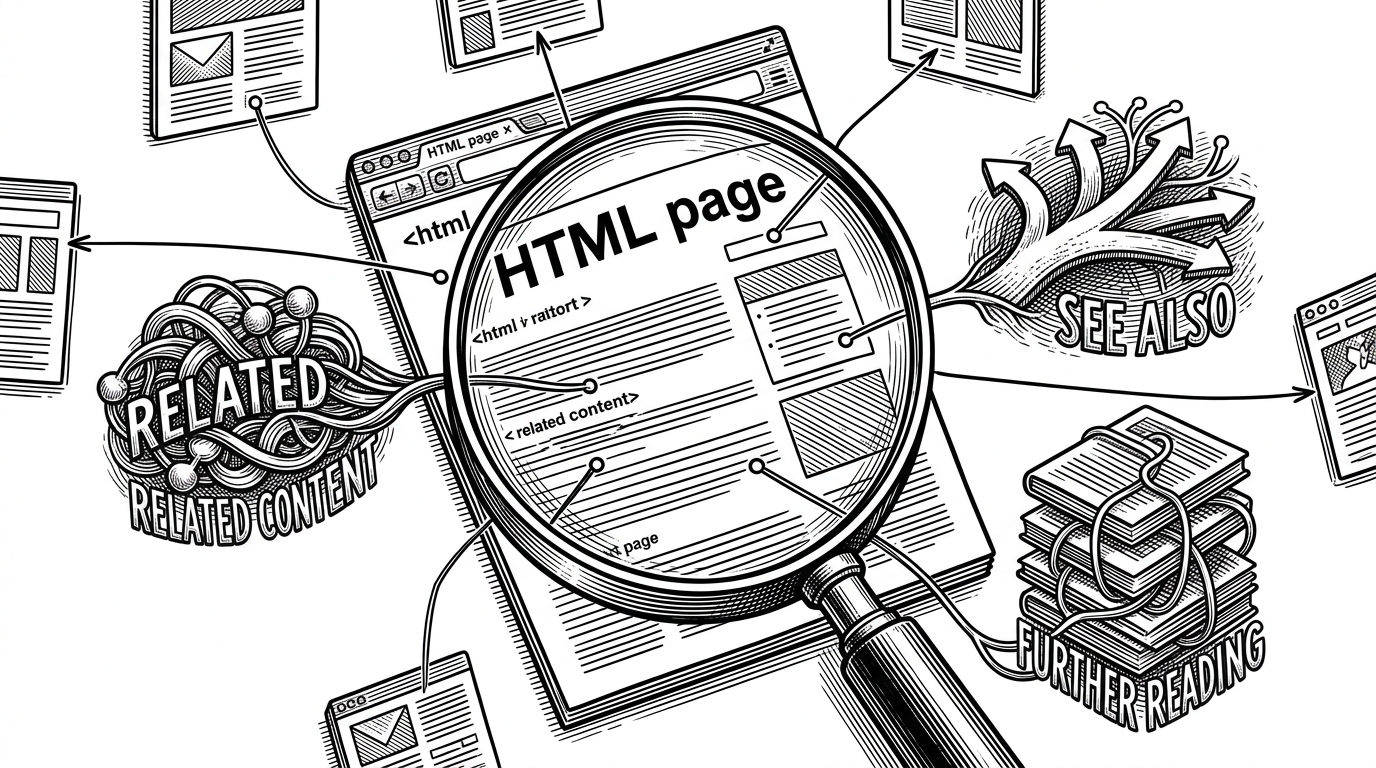
This is where the project gets interesting. It does not merely count links. It looks for the language around links. Headers like related, see also, and further reading matter because they reveal intent. They tell a machine that this page is not an island.
That is a subtle but important distinction. Mechanical checks tell you whether a link exists. Semantic checks tell you whether the site has organized its own knowledge in a way another system can follow.
The same logic applies to speakable markup and plugin metadata. Those signals are not cosmetic. They are instructions about how a machine should interpret, slice, and expose the content.
| Traditional SEO audit | context-score audit | |
|---|---|---|
| Primary audience | Search engines and human visitors | LLMs, AI agents, and machine readers |
| Main output | Ranking and crawlability signals | Context score across five pillars |
| Signals measured | Keywords, backlinks, metadata, page speed | AI-critical files, semantic links, depth, structure, discoverability |
| What good means | Easy to index and rank | Easy to understand, cite, and trust |
| Failure mode | Invisible to search | Opaque to machine interpretation |
| Example files or schema | title tags, meta descriptions, sitemaps | llms.txt, robots.txt, SpeakableSpecification, ai-plugin.json |
That table is the clearest way to see the pivot. The old world cares whether the page can be found. The new one cares whether it can be understood well enough to be used in an answer.
How it compares to classic SEO tooling
Classic SEO tools tend to surface technical issues in service of ranking. context-score uses similar audit instincts, but the goal is different. It wants to know whether the site has made itself extractable and quotable for systems that do not browse like humans do.
That makes the repo feel less like a competitor to SEO software and more like a prototype for a different layer of webmastering. One layer optimizes for discovery. The other optimizes for comprehension.
What this says about the next generation of web tooling
The repository is tiny, but the idea is not. It points toward a future where site quality includes machine comprehension as a first-class requirement. If your content strategy assumes only human readers and search crawlers, it is already incomplete.
context-score is a draft of a new discipline. Not SEO. Not analytics. Context auditing for the machine-readable web.