Benchmarks & Eval
LLM benchmarks, eval harnesses, model comparison tools, and agent performance testing
97 explainers
Benchmarks & Eval
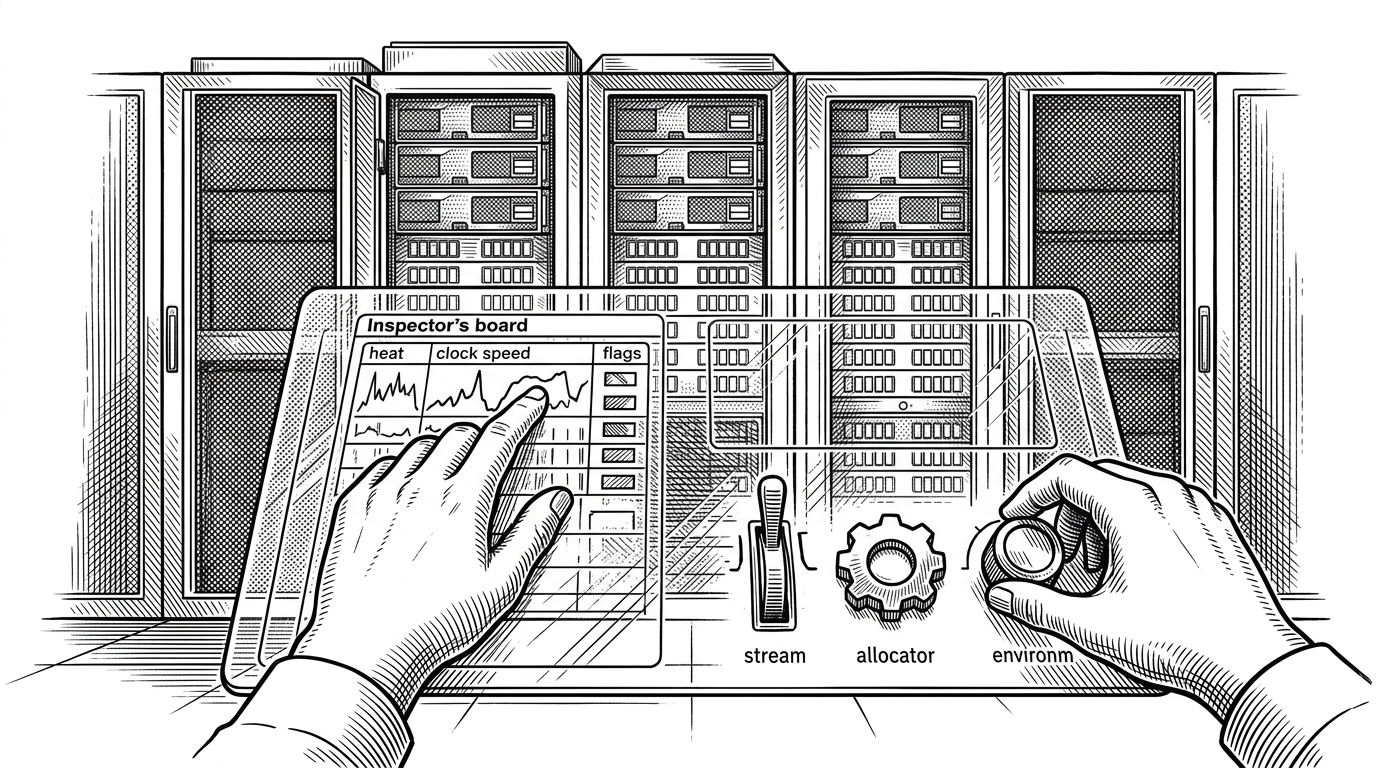
Git.M Runtime: The GPU Optimizer That Refuses to Touch Your Code
By tracing workload shape, attributing stalls causally, and testing interventions with rollback guards, Git.M turns runtime behavior into a performance control surface.
Benchmarks & Eval
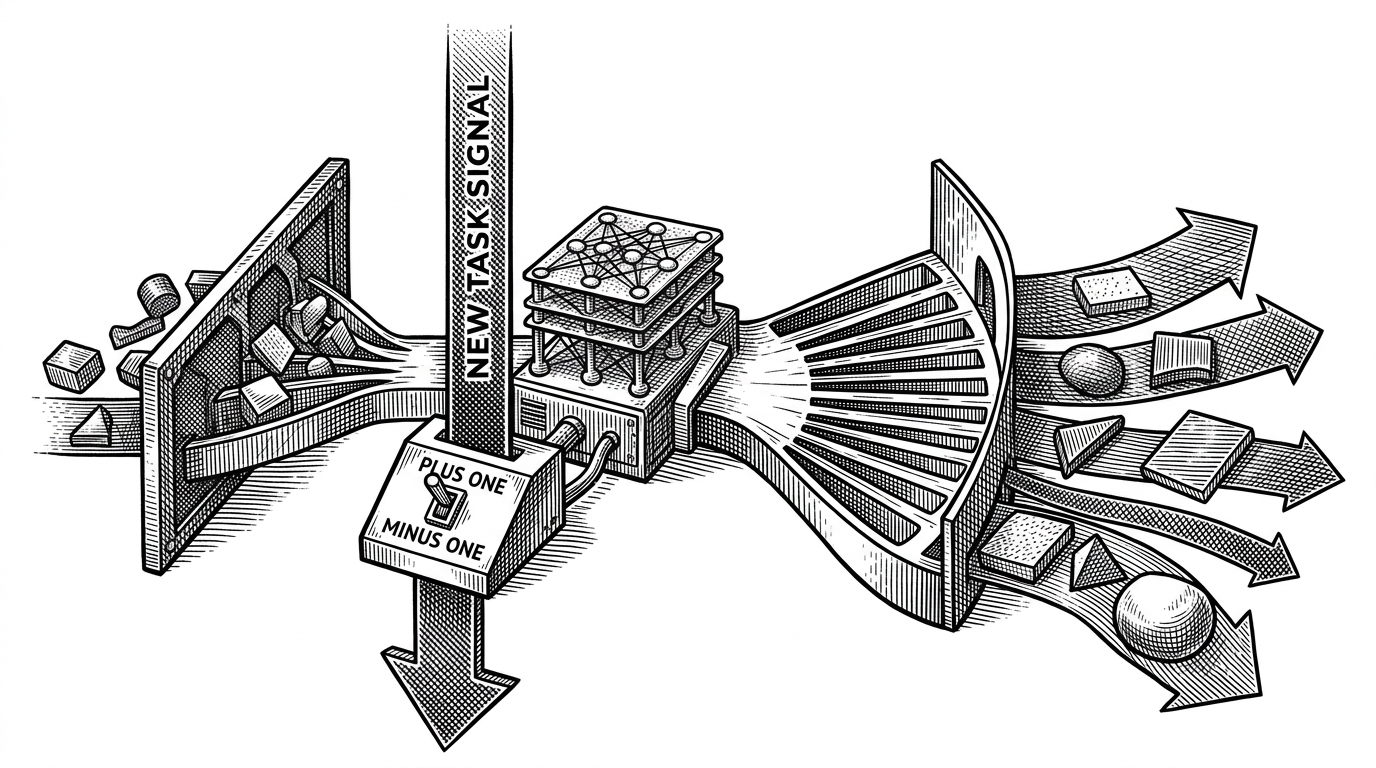
rl-razor-mnist: How a Tiny Task Flag Reveals Why RL Forgets Less
A minimal replication of Sakana AI’s RL’s Razor experiment, where a single extra input bit, a KL-minimal oracle, and group-relative RL turn catastrophic forgetting into something you can inspect, compare, and predict.
Benchmarks & Eval
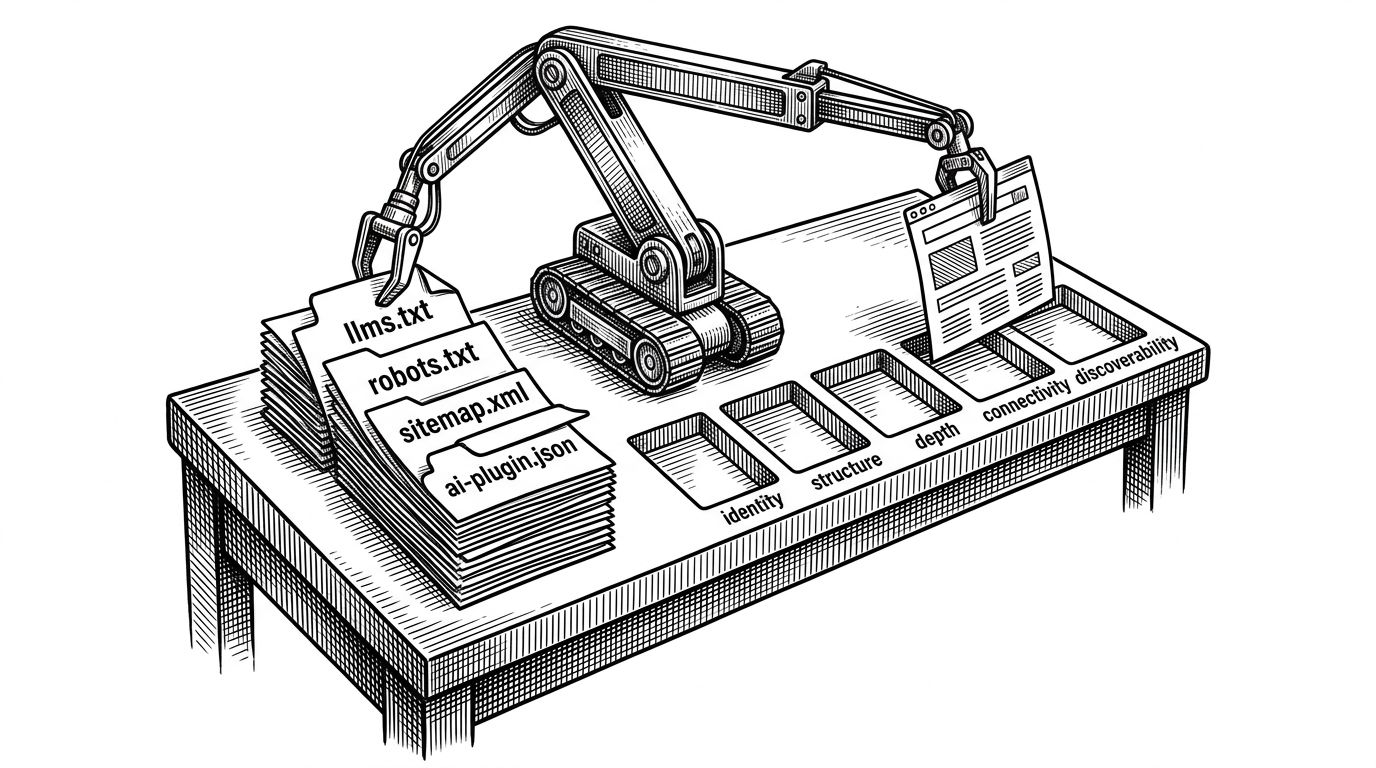
context-score: The Tiny CLI That Grades a Website for AI Comprehension
A single-file Node.js auditor that turns your site into a scorecard for identity, structure, depth, connectivity, and machine-friendly discoverability.
Benchmarks & Eval
react-bench: React Bench: The Benchmark That Tests Whether AI Can Find the Right React File
Aiden Ybai built a deliberately cursed Next.js app to measure source-file retrieval, not code generation. The result is a benchmark for the browser era of AI coding.
Benchmarks & Eval
openai/model_spec_dataset: case law for a model constitution
A benchmark where the payload is a rubric, not an answer key, and the real test is whether a model can follow instruction hierarchy, refuse safely, and stay objective.
Benchmarks & Eval
Async Witness: The Testing Framework That Treats Vite Like a Black Box Recorder
It does not just check whether your app rendered. It records how Vite behaved, whether HMR was accepted, and whether a passing test was quietly contaminated by hidden failures.
Benchmarks & Eval
CS-Fundamentals-Interview-Questions: The Three-File Blueprint for CS Interview Recall
A tiny markdown repository that distills DBMS, operating systems, and computer networks into interview-sized mental models, with analogies that make the fundamentals stick.
Benchmarks & Eval
SimpleTES: The Search Engine That Lets an LLM Evolve Real Scientific Code
A training-free system for scientific discovery that spends compute on proposals, execution, and selection instead of longer chains of thought.
Benchmarks & Eval
NodeSynth: The Taxonomy Engine for AI Safety Testing
A Google Research prototype that decomposes policy into a concept graph, then recombines it into grounded synthetic eval prompts.
Benchmarks & Eval
hallucinations-paper-experiments: The notebook that measures how truth gets taxed
OpenAI's reproduction code for hallucination research shows how evaluation rules can push models toward guessing, and how a consistency check tries to pull them back.
Benchmarks & Eval
SakanaAI/google-code-golf-2025: The Repo That Turns ARC Reasoning Into Byte-Count Combat
A deep dive into the judge, minifier, and prompt loop that squeeze correct solutions down to the smallest possible Python.
Benchmarks & Eval
Artemis2: The Moon Mission Benchmark That Grades Reasoning, Not Answers
Inside a Flight Director simulator where telemetry checks, anomaly handling, and burn decisions are scored by deterministic physics.
Benchmarks & Eval
model_spec_evals: When an AI constitution becomes a passing score
openai/model_spec_evals turns OpenAI’s Model Spec into an executable test suite, where a judge model writes the critique, median sampling reduces noise, and 6 becomes the line between pass and fail.
Benchmarks & Eval
`darnir/nsga2-Windows`: The C Code That Teaches Machines How to Compare the Incomparable
A compact NSGA-II implementation shows how Pareto ranking, constraint handling, and crowding distance turn multi-objective optimization into a survival game.
Benchmarks & Eval
langchain-ai/ai-evals-hw-langsmith: The Homework Repo That Teaches You to Debug AI Like a System
A five-part LangSmith curriculum that starts with a recipe bot and ends with trace replay, judge alignment, retrieval metrics, and transition-matrix failure analysis.
Benchmarks & Eval
Swiggy-End-To-End-Data-Analytics: Swiggy End-To-End Data Analytics: When a Churn Model Becomes a Retention Playbook
A portfolio project that moves from SQL and Power BI to machine learning and a Flask app, then turns customer risk into concrete business action.
Benchmarks & Eval
Inside `wanshuiyin/AAAI-2023-The-Learnability-of-Nonlinear-SSL`: A Proof You Can Run for How Nonlinear SSL Learns
A hand-coded NumPy simulator turns an AAAI theory paper into a geometric story about basins of attraction, augmentations, and feature recovery.
Benchmarks & Eval
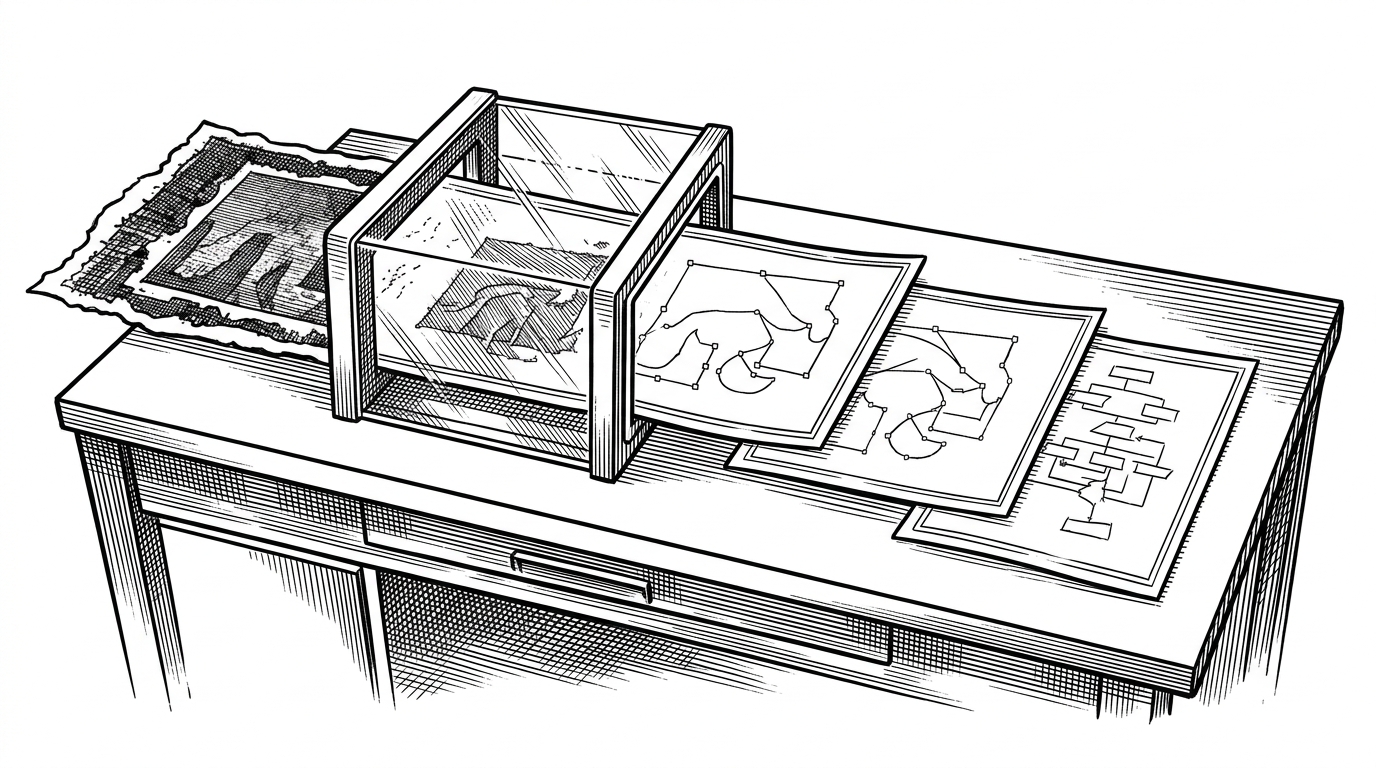
`img2svg-bench`: The Benchmark That Turns SVG Taste Into Numbers
A local-first harness for comparing raster-to-vector pipelines, stripping away background noise, extracting fast metrics, and making “better SVG” less subjective.
Benchmarks & Eval
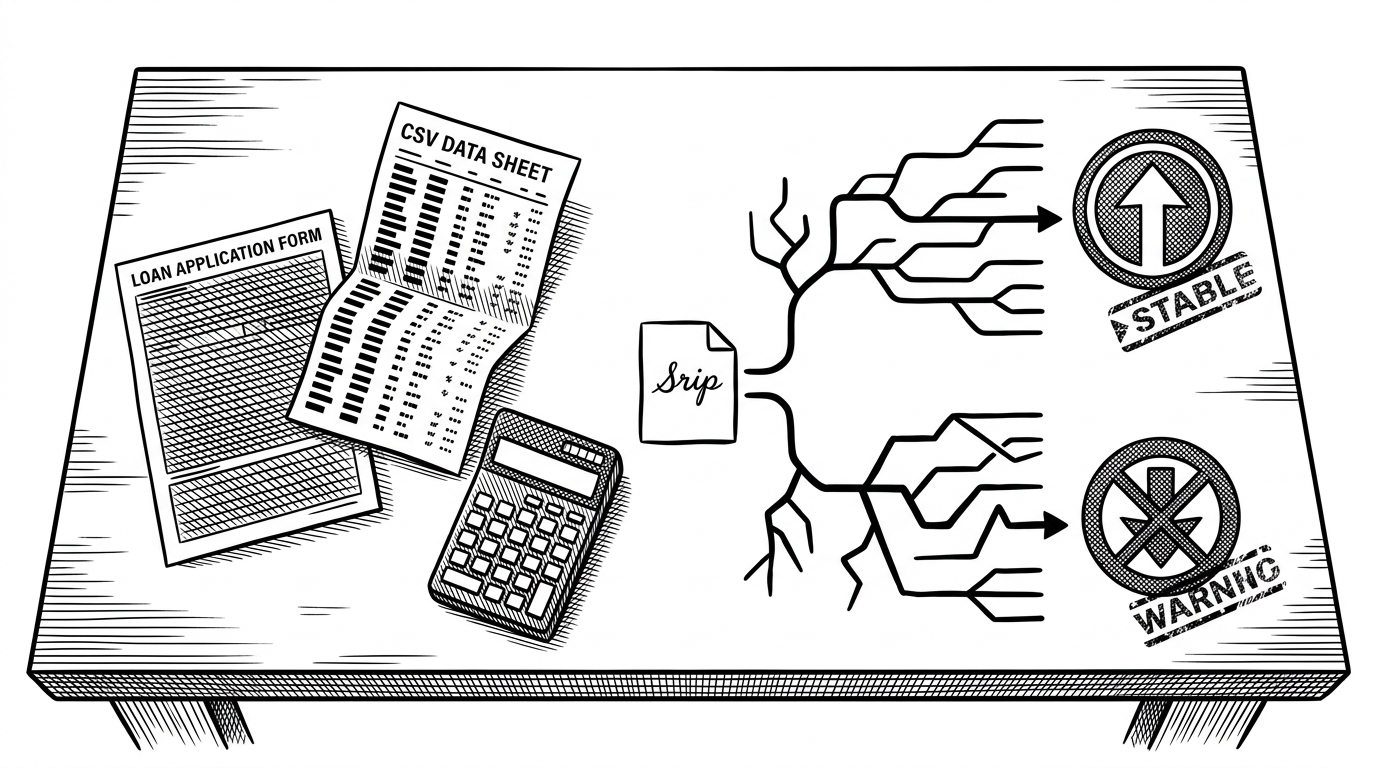
loan-default-risk-analyzer: The Small Script That Tries to Decide Who Gets a Loan
A one-file Python pipeline turns raw applicant data into a credit-risk prediction, exposing the tradeoffs between speed, interpretability, and production readiness.
Benchmarks & Eval
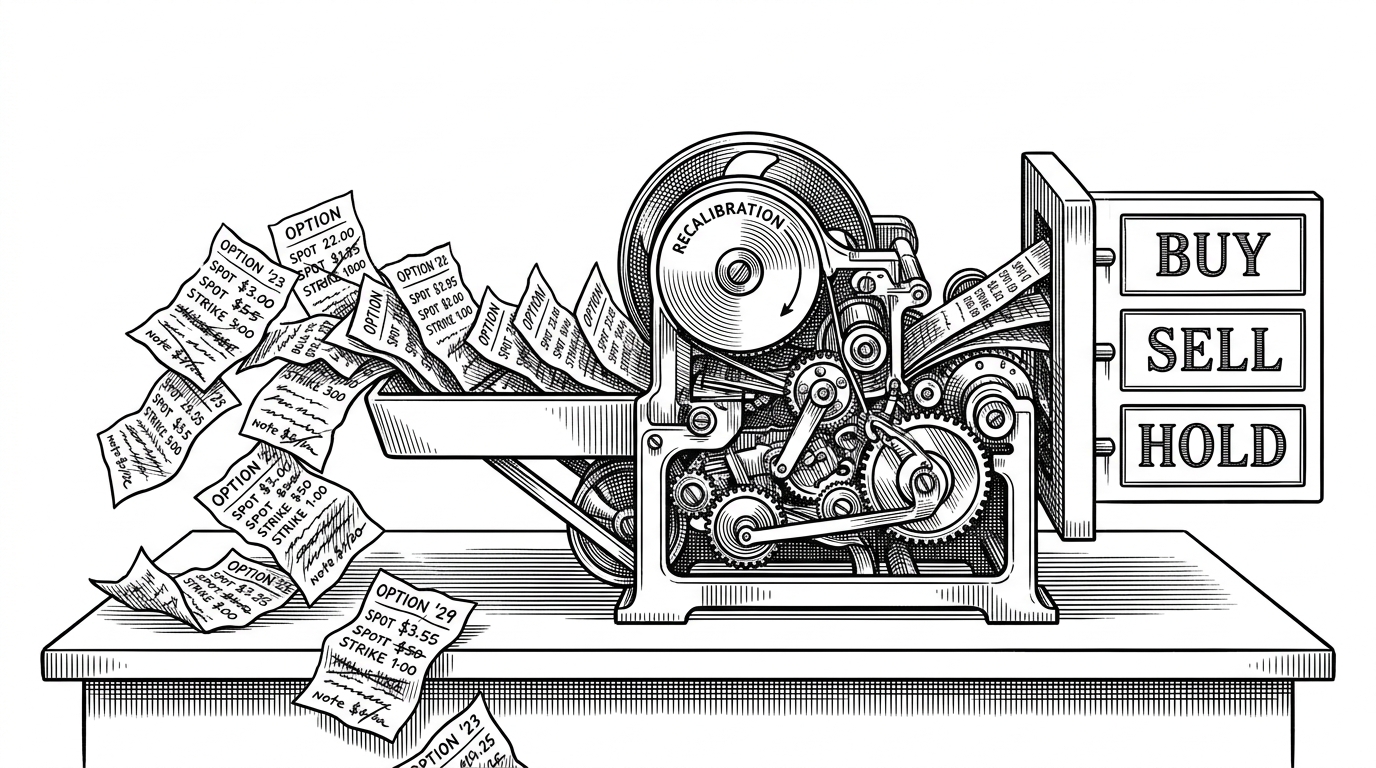
Machine-Learning-Framework-for-option-mispricing: The XGBoost Pipeline That Keeps Repricing the Market
A practical trading framework for NSE BANKNIFTY options that combines defensive data cleaning, cross-sectional z-scores, and walk-forward retraining to surface mispricing signals.
Benchmarks & Eval
rl_directional_straddle: Teaching an AI Trader to Obey the Market
`rl_directional_straddle` is a deep RL options system for NIFTY50 that masks invalid actions, simulates margin pressure, and treats survivability as part of the objective.
Benchmarks & Eval
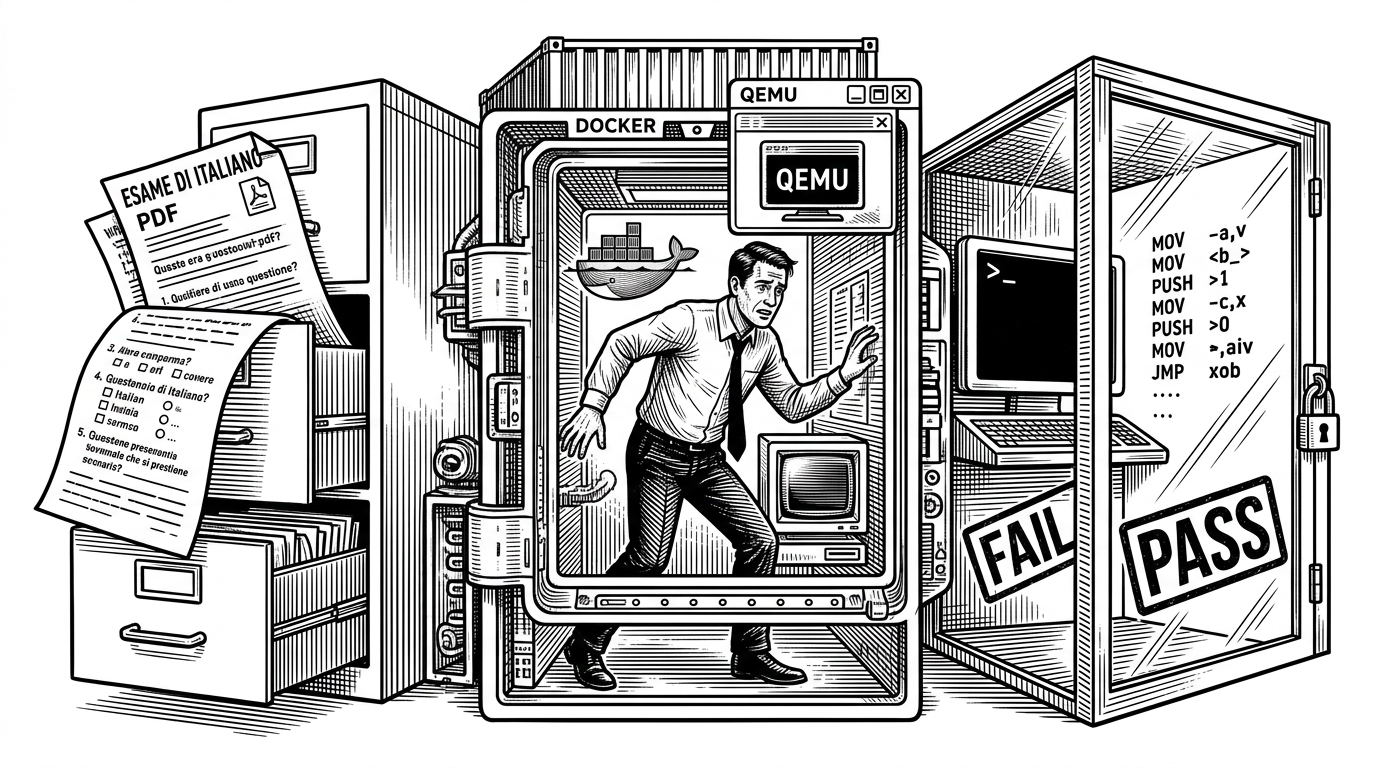
calcolatori-bench: The Benchmark That Makes LLMs Read Italian, Boot a Kernel, and Prove They Weren’t Cheating
A deep dive into the University of Pisa-style systems exam harness that turns agent evaluation into a full-stack stress test: translation, compilation, emulation, and exact-output verification.
Benchmarks & Eval
claude-introspection-paper-gpt5check: The Repo That Turns Introspection Into a Context Test
A text-only baseline for the Claude introspection claim, using semantic marination, corrupted logs, and judge loops to ask whether “self-awareness” is just prompt pressure in disguise.
Benchmarks & Eval
obedience-benchmark: The benchmark for when agents know the answer but ignore the instructions
a5c-ai/obedience-benchmark measures process fidelity, not just task completion, with Docker isolation, structured logs, and a judge that scores how closely an agent followed the script.
Benchmarks & Eval
model-selection-benchmark: The benchmark that asks whether your model can actually act
model-selection-benchmark scores models on tool use, multi-step behavior, latency, and accuracy, so teams can choose an LLM for agentic work without guessing.
Benchmarks & Eval
The DIY Chatbot Arena: Inside instructkr/elo-leaderboard-archive
How a localized LLM leaderboard uses manual stream parsing and a mathematical "underdog bias" to solve the Elo cold-start problem.
Benchmarks & Eval
The 224-Pixel Sledgehammer: Inside shrijacked/dl
How a medical imaging pipeline upscales tiny 28x28 CT scans to hijack massive Vision Transformers, achieving 99.69% accuracy on transient GPU clouds.
Benchmarks & Eval
sandbox-benchmarking: Measuring the 6-Second Ghost in Vercel Sandbox
How a minimal benchmarking suite exposed the hidden first-command penalty haunting ephemeral compute.
Benchmarks & Eval
spotify-genre-analysis: Can a Cluster Beat a Genre Label?
A notebook-built experiment that turns Spotify’s audio features into machine-made groupings, then asks whether genre is acoustic truth or just metadata with better branding.
Benchmarks & Eval
F1-Race-Analysis: The Repo That Turns F1 Telemetry Into Overtake Probabilities
A Streamlit strategy room that fuses live timing, historical priors, and XGBoost predictions to guess when a move is coming before the TV graphics do.
Benchmarks & Eval
ConvoBench-AI: The Benchmark That Breaks Evaluation Into Tiny, Verifiable Judgments
A deep dive into the batch-and-score system that evaluates conversation turns across hundreds of facets, from linguistic quality to highly specific domain and persona signals.
Benchmarks & Eval
`ipl-analytics`: The IPL Predictor That Refuses to Lie About Cricket
A Streamlit dashboard, an explainable ensemble model, and a data pipeline built around one hard truth: T20 cricket is noisy, and good models should admit it.
Benchmarks & Eval
Bank-Loan-Prediction: A Tiny Notebook That Tries to Make Loan Rejection Explainable
Inside a compact credit-risk pipeline that stages a model showdown, confronts class imbalance, and uses SHAP to turn predictions into defensible reasons.
Benchmarks & Eval
SQL-PROJECT: A Portfolio Repo That Turns Messy Netflix Data Into an SQL Interview Drill
A compact MySQL case study that uses synthetic data, string hacks, and window functions to teach the part of analytics most demos skip: coping with bad structure and still producing usable answers.
Benchmarks & Eval
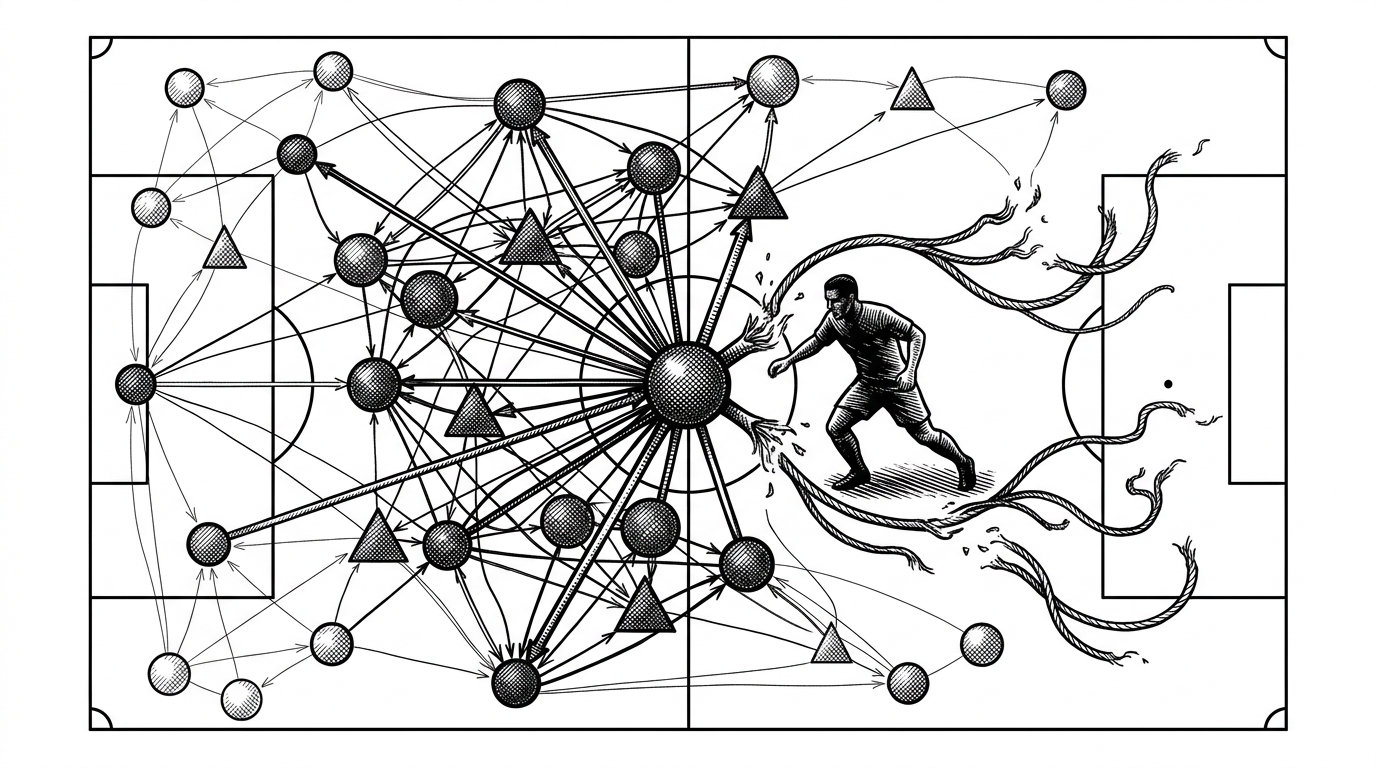
Defensive-Packing-Pass-Network-Disruption-Index: The metric that turns pressing into a graph attack
NavjotML’s model scores defenders not just for winning the ball, but for breaking the opponent’s passing structure, especially when the target is a central node.
Benchmarks & Eval
RubiksCubeSolver: The C++ Trick Is Not the Search, It’s the State
A close look at how this solver turns a cube into arrays, then bitboards, then a search engine that treats every move like a cheap register operation.
Benchmarks & Eval
CS-GO-Stats-Analysis Turns Demo Files Into a Theory of Awareness
A Python pipeline that syncs kills to game state, measures crosshair geometry, and clusters players into roles without relying on gut feel.
Benchmarks & Eval
NLEx: The Repo Building a Translator for Black-Box NLP Models
A fine-tuned LLM, classic interpretability methods, and a deliberately structured research workflow aimed at turning model internals into explanations people can read.
Benchmarks & Eval
agents-lab: Five Ways to Build the Same J-League Analyst
A controlled shootout between OpenAI Agents, CrewAI, LangGraph, Google ADK, and Microsoft Agent Framework, all pointed at the same sports workflow.
Benchmarks & Eval
parameter-golf: Parameter Golf: The OpenAI Repo Where Model Size Becomes the Game
A 16MB challenge that turns transformer design into compression engineering, with depth recurrence, Muon, and quantization as the main weapons.
Benchmarks & Eval
theDakshJaitly/HandsOnML_Aurelien-Geron: The notebook that teaches machine learning without the hype
A tiny study repo built from Hands-On Machine Learning Chapter 2, where stratified sampling, pipelines, and data hygiene do the real work.
Benchmarks & Eval
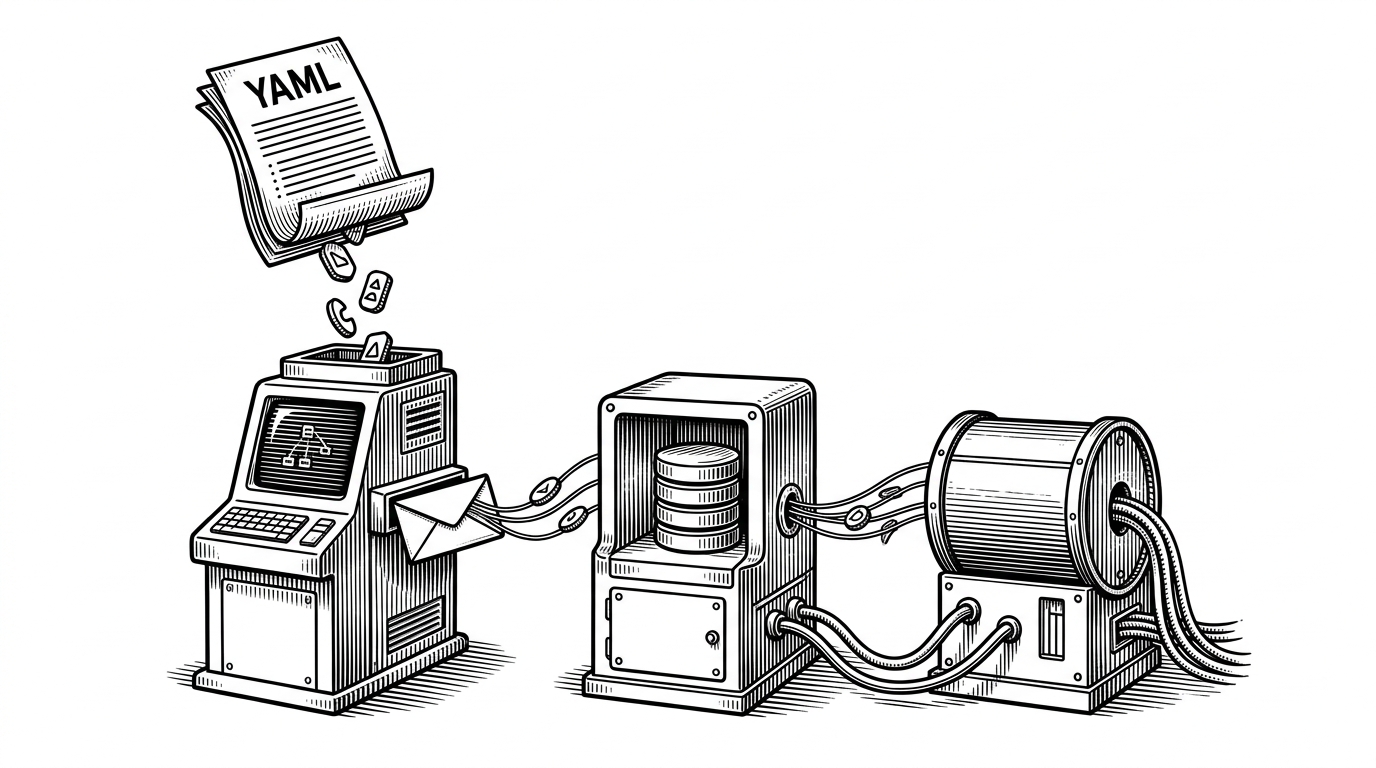
code-chaos: The stress tester that treats state as the product
code-chaos turns YAML into repeatable backend workflows, stitching HTTP calls, SQL, and message brokers into one execution loop.
Benchmarks & Eval
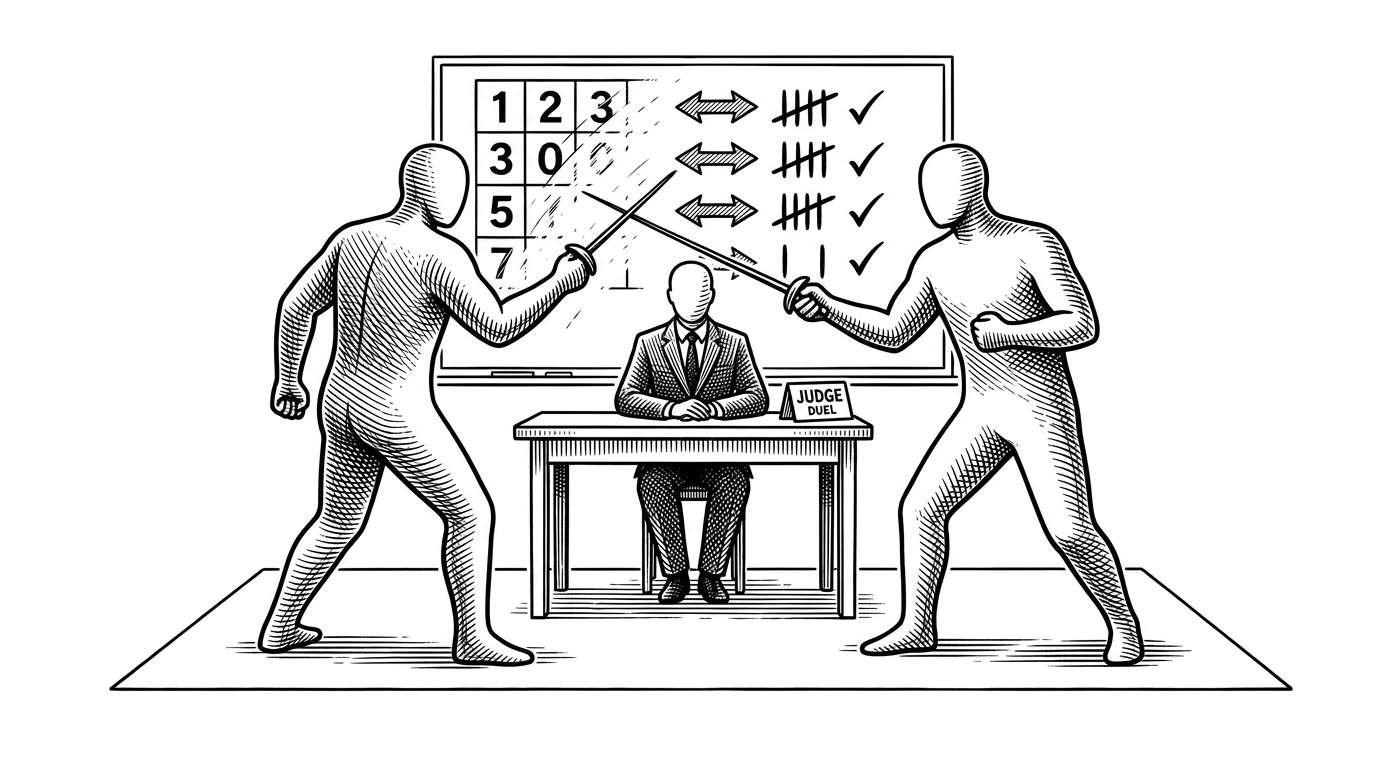
DuelingUCB: Learning the Best Choice Without Ever Seeing a Score
A compact Python repo that turns pairwise wins into an Upper Confidence Bound loop, showing why preference feedback can be more useful than numeric reward.
Benchmarks & Eval
roerohan/slate: Teaching AI to See Its Own UI Bugs
How a render-and-compare reinforcement learning loop uses computer vision to train Vision-Language Models for pixel-perfect Tailwind generation.
Benchmarks & Eval
mattbeane/research-quals: The Competency Gate for the AI Era
How a Python CLI uses LLM evaluators to withhold advanced automation until researchers prove they can do the work manually.
Benchmarks & Eval
Beyond Significance: Betting on bayesian_ab_tester
Why the next generation of experimenters is ditching the p-value for the Probability of Being Best.
Benchmarks & Eval
bayesian-ab-tester: Bayesian A/B Testing Without the Server
How hwong103/bayesian-ab-tester moves 100,000 Monte Carlo simulations from the cloud into a single browser tab.
Benchmarks & Eval
The Cartography of Intelligence: Inside hgayan7/machine-learning-resources
Why the most important tool in the modern AI stack isn't a library, but a map of the from-scratch intuition required to move beyond prompt engineering.