mattbeane/research-quals: The Competency Gate for the AI Era
How a Python CLI uses LLM evaluators to withhold advanced automation until researchers prove they can do the work manually.
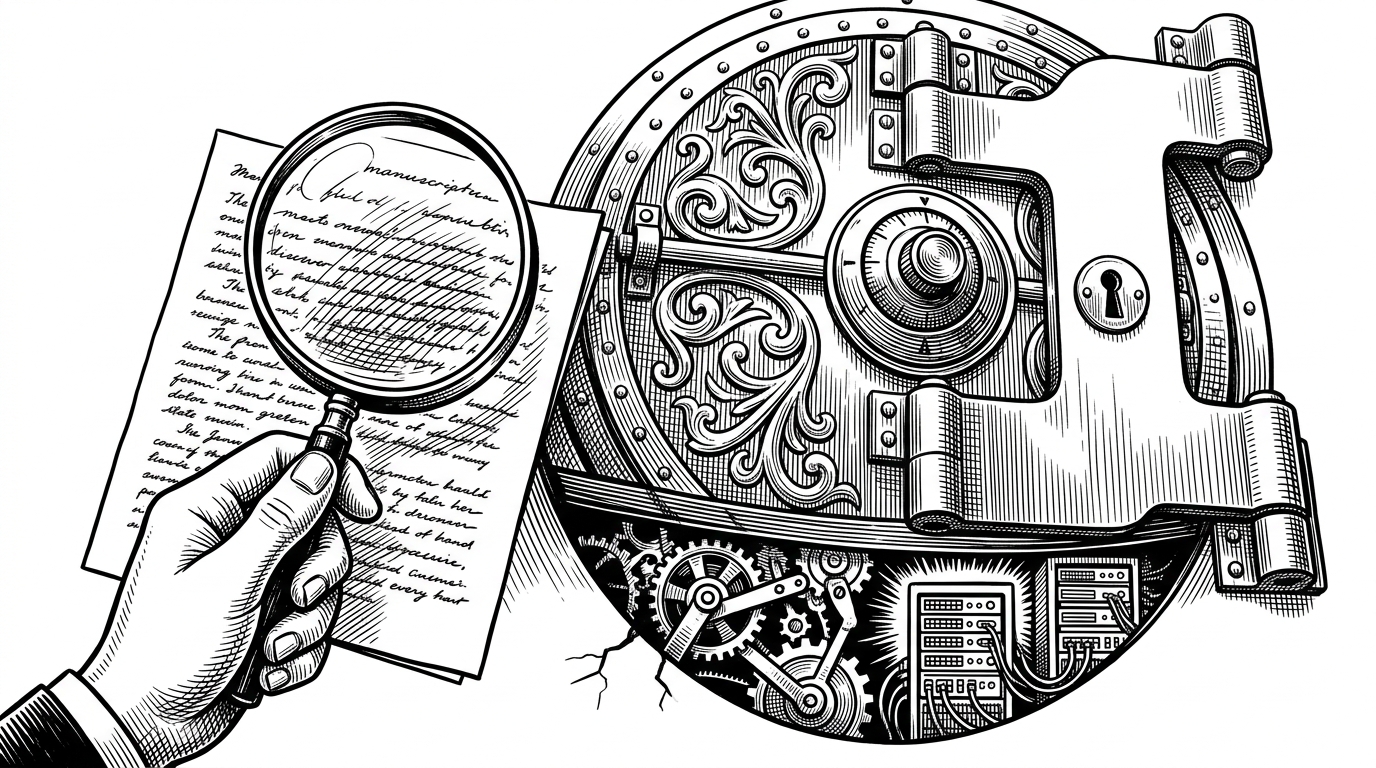
- The repository flips the standard AI agent model by actively refusing to automate tasks until users pass rigorous, LLM-graded competency tests.
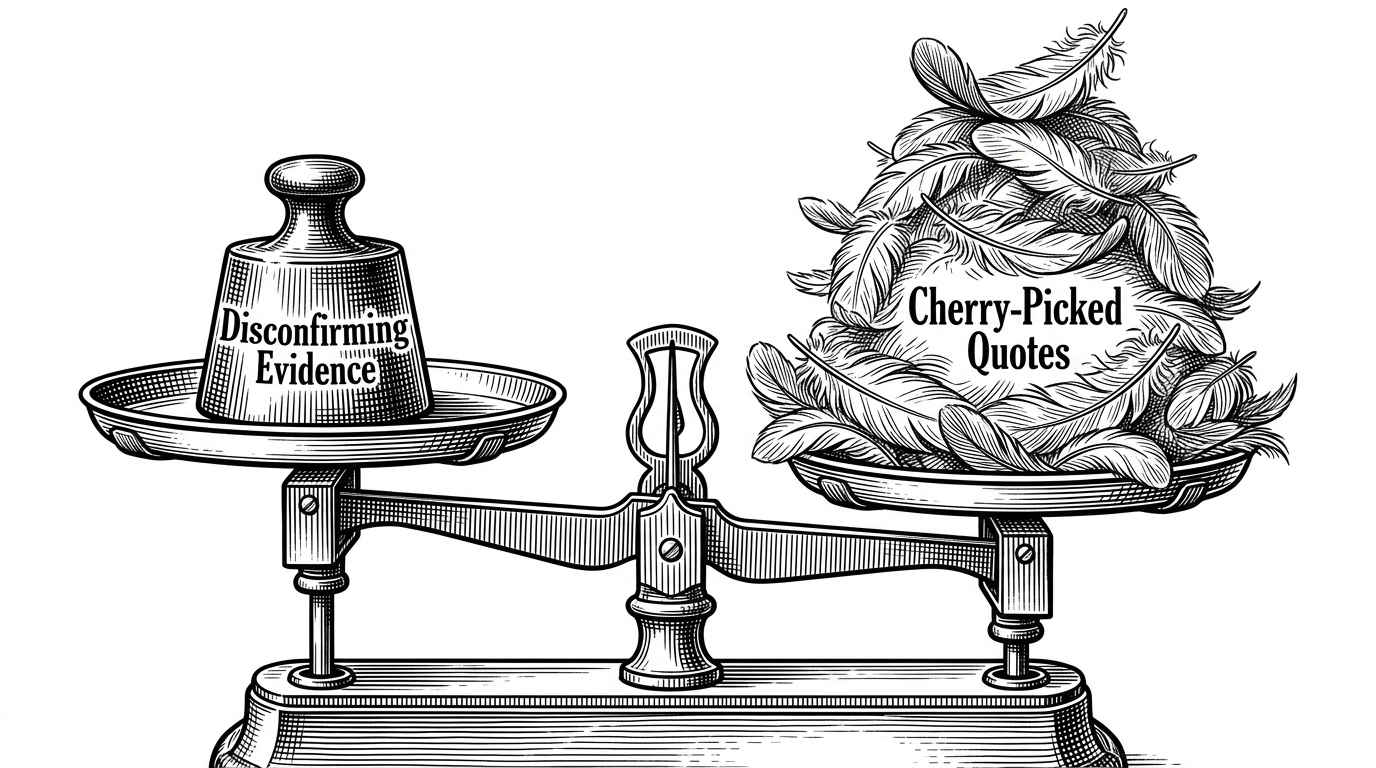
- An automated evaluator compares student submissions against expert baselines using strict rubrics, penalizing cherry-picked data.
- Competency is tracked locally via a UUID-backed JSON state machine that acts as a cryptographic academic transcript.
- Passing the competency gates unlocks access to theory-forge, a separate ecosystem of advanced AI orchestration tools.
The Automation Embargo
While the rest of the software world is building AI agents that do the work for you, research-quals uses AI to stop you from automating your work. It is an educational lockbox. The core of this system is an abstraction called the UNLOCK_MAP, located inside cli/competency_gate.py. This file acts as a bouncer for your terminal.
Attempting to run an advanced research command without the prerequisite student level results in a hard block. The software actively refuses to execute commands. It demands that you prove your foundational tacit knowledge first. You must do the work manually, submit it, and let the machine grade your human effort.
Grading the Vibe
Qualitative research is notoriously subjective. To solve this, cli/evaluator.py uses Few-Shot Prompting and Anthropic to compare a student's Markdown submission against an expert_baseline.md. The programmatic rubrics are unforgiving. For instance, the system has a hard-coded requirement demanding that students find at least 50 percent of disconfirming evidence to pass.
The system does not just look for keywords. It compares the distribution of findings against what a senior scholar would identify. This is a technical implementation of adversarial evidence, a core tenet of rigorous qualitative research. If you fail, the system enforces a cooldown period of 7 to 30 days to prevent brute-forcing the LLM evaluator.
Cryptography for Pedagogy
Once the LLM evaluator approves the work, the state must be maintained. The lib/credentials architecture handles this by minting UUID-backed badges. The issuer.py script writes these badges to a local record.json file. This creates a portable proof of work for academic competency.
{
  "student_id": "usr_9a8b7c6d",
  "badges": [
    {
      "type": "DOMAIN",
      "domain_id": "domain-1",
      "uuid": "8f92a1b3-4c5d-6e7f-8a9b-0c1d2e3f4a5b",
      "issued_at": "2024-01-15T10:30:00Z",
      "score": 85
    }
  ],
  "current_level": 1
}
This JSON file is the ultimate source of truth for the local environment. It is a simple, stateless approach to managing user progression without requiring a complex database backend.
The Theory-Forge Ecosystem
The ultimate payoff is access to the theory-forge ecosystem. The research-quals project is not a standalone application but a licensing engine. Contrast this with fully autonomous pipelines that take a prompt and output a formatted paper. Those systems risk hallucination and weak theoretical foundations.
Gated AI represents a sustainable path forward for rigorous disciplines. By forcing humans to remain in the loop during the foundational phases, the system ensures that when the advanced AI agents are finally unlocked, they are guided by a competent human orchestrator.