langchain-ai/ai-evals-hw-langsmith: The Homework Repo That Teaches You to Debug AI Like a System
A five-part LangSmith curriculum that starts with a recipe bot and ends with trace replay, judge alignment, retrieval metrics, and transition-matrix failure analysis.
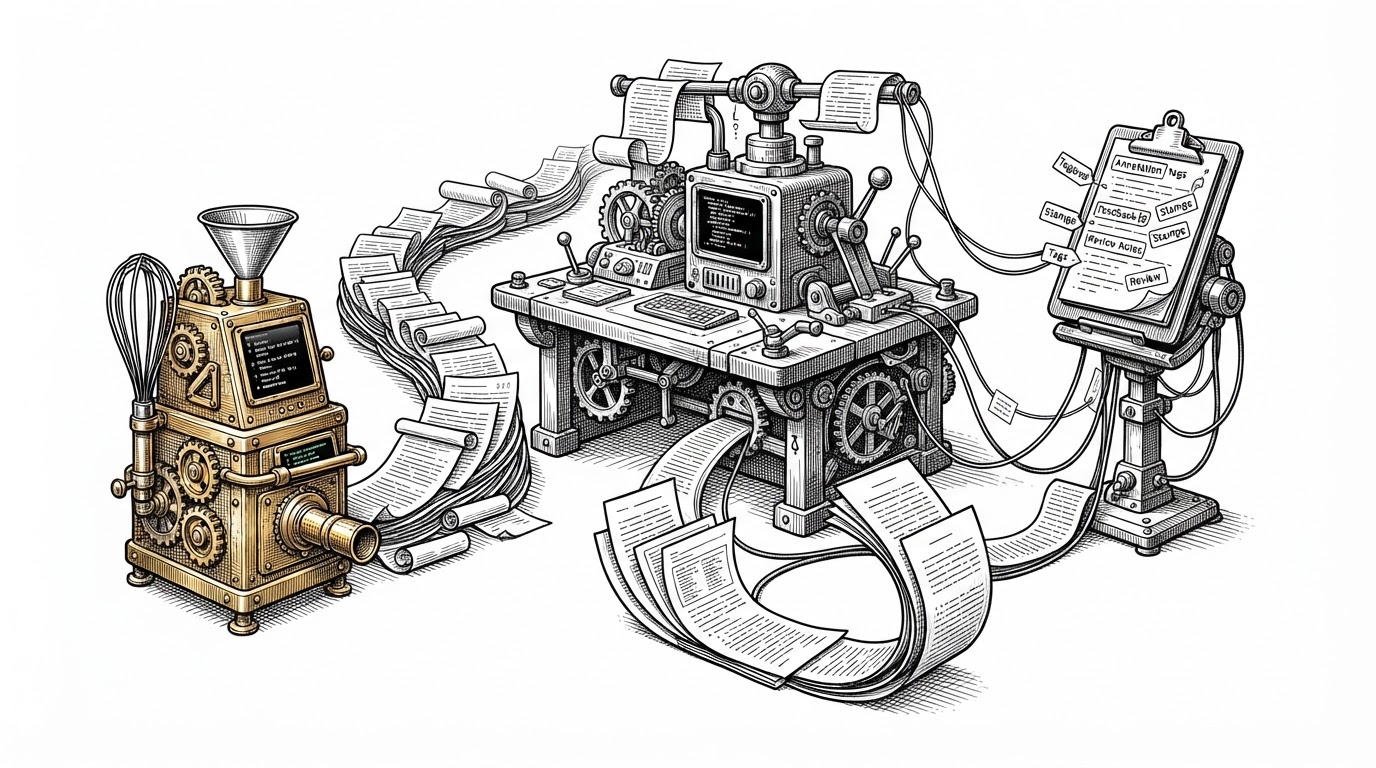
- This repo teaches evaluation as a trace-first workflow, not as a one-off grading step.
- Its real lesson is that one agent run becomes more valuable when human annotation, LLM judging, retrieval metrics, and transition analysis all inspect the same trace.
- The five homework modules form a debugging pipeline that moves from agent construction to failure diagnosis and then back into better tests.
- Compared with generic eval platforms, the project stands out for method clarity and LangChain-native pedagogy.
A Fake Production Dashboard That Teaches the Real Thing
The most interesting thing in this repo is not the homework structure. It is the illusion of production. By replaying traces, feedback, and failures into LangSmith, it gives you a living system to inspect before you ever see real traffic.
LangSmith Evaluation lets you evaluate agent performance, grounded in real production trace data and aligned to human judgment.
That matters because most eval tutorials start with abstract metrics. This repo starts with evidence. You are not told to trust a score. You are shown the trace behind it, the annotation that challenged it, and the workflow change that followed.
Why This Is More Than a Prompting Course
The course is really about lifecycle thinking. Prompting is only the first move. The bigger discipline is observe, annotate, judge, compare, and revise until the agent becomes a system you can reason about.
That shift changes the mental model. Instead of asking whether a prompt is clever, you ask whether the agent is measurable. Instead of asking whether a response sounds good, you ask which failure mode produced it and which test would catch it next time.
The Five Homeworks Form a Full AI Debugging Pipeline
The homeworks are sequenced like a lab, not a lecture. hw1 builds the agent and the trace. hw2 introduces annotation and error analysis. hw3 aligns the judge. hw4 measures retrieval. hw5 inspects transition patterns across tools.
| Homework | Main question | Primary lens |
|---|---|---|
| hw1 | Can the agent run and trace cleanly? | Basic observability |
| hw2 | What kinds of mistakes are humans seeing? | Manual annotation |
| hw3 | Can an LLM judge match human judgment? | Judge alignment |
| hw4 | Is retrieval finding the right evidence? | Recall@K and MRR |
| hw5 | Where do multi-tool chains become brittle? | Transition matrices |
The Judge Has to Be Evaluated Too
The sharpest idea in the repo is that the evaluator is itself a model artifact. If you let an LLM grade output without calibration, you are just moving uncertainty into a different box.
Every company when building a mission-critical agent will build benchmarks for that agent.
That is why hw3 matters. It does not just ask you to score responses. It asks you to compare scores against human review in the Evaluator Playground, then tighten the rubric until the judge becomes useful instead of merely confident.
How the Repo Moves Data Through the Loop
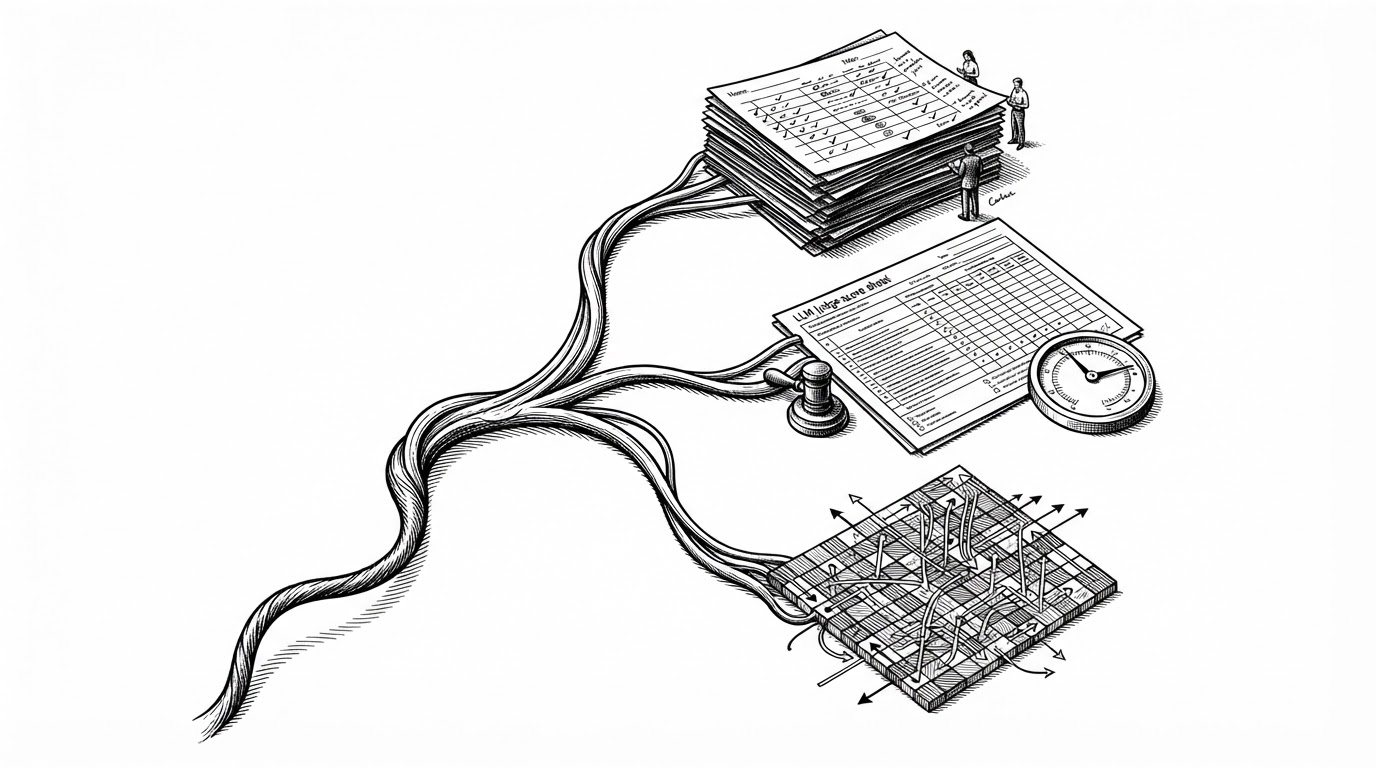
The mechanics are straightforward and useful. Traces are uploaded, feedback is attached, and synthetic datasets stand in for real traffic. That makes the course feel like production without requiring production.
# Conceptual flow, based on the repo's scripts
agent_run = run_agent(user_prompt)
trace_id = upload_traces(agent_run)
attach_feedback(trace_id, human_review)
judge_score = llm_judge(trace_id)
retrieval_metrics = compute_recall_at_k(trace_id)
transition_profile = build_transition_matrix(trace_id)

# Then use the failures to improve the next run
revise_rubric()
revise_prompt()
revise_tool_chain()
That loop is the whole point. Observability becomes input, not output.
RAG Metrics and Transition Matrices Make Failure Visible
hw4 and hw5 widen the frame. hw4 asks whether the retriever finds the right recipe evidence, using Recall@K and MRR. hw5 asks a different question: once the agent starts moving between tools, where does the sequence become fragile?
That distinction matters. Retrieval metrics tell you whether the right context was available. Transition matrices tell you whether the agent used that context well enough to move through the task without getting stuck or derailed.
| Lens | What it measures | What it misses |
|---|---|---|
| Retrieval metrics | Whether the right evidence was surfaced | Whether the agent used that evidence well |
| Transition analysis | How the agent moves between tools | Whether the final answer is fluent |
| Final answer grading | Surface quality | Process quality and hidden brittleness |
Where It Fits in the Eval Landscape
This repo does not try to out-platform Langfuse, Phoenix, DeepEval, or Braintrust. It does something narrower and rarer: it teaches a method inside the LangChain ecosystem.
| Project | Primary strength | What makes it different here |
|---|---|---|
| LangSmith homework repo | Trace-first pedagogy | Teaches the workflow, not just the tool |
| Langfuse | Open observability platform | Broader platform, less instructional sequencing |
| Phoenix | RAG and drift analysis | Strong analysis, less curriculum structure |
| DeepEval | Offline testing style | Good for unit-test thinking, not trace replay |
| Braintrust | High-throughput eval execution | Enterprise eval muscle, different teaching goal |
The distinction is clarity of method. The repo is not trying to be the biggest suite. It is trying to make the mental model obvious.
Why This Repo Matters
The broader lesson is simple. AI debugging is becoming trace-driven, not prompt-driven. The useful unit of work is no longer a clever string. It is a recorded behavior you can replay, judge, annotate, and improve.
That is why this repo lands. It gives learners a realistic failure archive, a scaffold for evaluating it, and a way to turn the result back into better tests. That is not just coursework. It is the shape of the job.