`ipl-analytics`: The IPL Predictor That Refuses to Lie About Cricket
A Streamlit dashboard, an explainable ensemble model, and a data pipeline built around one hard truth: T20 cricket is noisy, and good models should admit it.
- `ipl-analytics` treats uncertainty as a feature, not a bug, and that makes its prediction story more credible than the usual sports-model hype.
- The repo’s real edge is not raw accuracy, but disciplined feature design, flip-team augmentation, and explainability that exposes what the model actually learns.
- The app stays lightweight by combining a flat Streamlit structure, hosted data, and SVGs generated in code instead of shipped as static assets.
- Its most useful output is not just a win probability, but a sharper way to separate cricket folklore from measurable pre-match signal.
The first thing this project gets right is admitting uncertainty
Most sports prediction projects oversell certainty. They chase a flashy accuracy number and quietly smuggle in leakage, hindsight, or both. `ipl-analytics` does the opposite. It treats a mid-50s model as a serious result because T20 cricket is messy enough that honesty matters more than swagger.
This repo provides a complete analytical overview of IPL data. The analysis is done using Python, Pandas, Matplotlib and Seaborn.
That framing matters. If a predictor is trained only on pre-match inputs and still lands in a modest range, that is usually a sign the model is respecting the problem. In this repo, the point is not to claim the future can be nailed down. The point is to show what signal survives once folklore is stripped away.
Why the model’s low accuracy is the real flex
The repo’s stated target is not the kind of number that gets clicks. It is the kind that gets trust. That is the clue. A model that lives in the 54 to 55 percent range is not trying to impress you with impossible certainty. It is trying to behave like a model in a high-noise environment.
The standout signal in the repo is the collapse of toss mythology. Once you control for pre-match features, the toss barely moves the needle. That is a useful correction to cricket common sense, and SHAP makes the correction legible. The model is not only predicting. It is explaining which variables matter and which ones do not.
How the predictor avoids fooling itself
The core modeling trick is simple and smart. Every match is duplicated in reverse, so Team A versus Team B becomes Team B versus Team A. That flip-team augmentation removes order bias, which is exactly the kind of accidental pattern a model will happily learn if you let it.
def flip_match(row):
    return {
        "team1": row["team2"],
        "team2": row["team1"],
        "venue": row["venue"],
        "team1_form": row["team2_form"],
        "team2_form": row["team1_form"],
        "team1_venue_winrate": row["team2_venue_winrate"],
        "team2_venue_winrate": row["team1_venue_winrate"],
    }

train_rows = []
for _, match in matches.iterrows():
    train_rows.append(match)
    train_rows.append(flip_match(match))

X = build_pre_match_features(train_rows)
model.fit(X, y)
That structure pairs with rolling form, venue differentials, and other pre-match features. The important part is what is missing. No mid-game leakage. No hidden future context. No stat that only exists because the match has already happened. That restraint is what makes the resulting probability worth reading.
The app is built like a careful prototype, not a bloated product
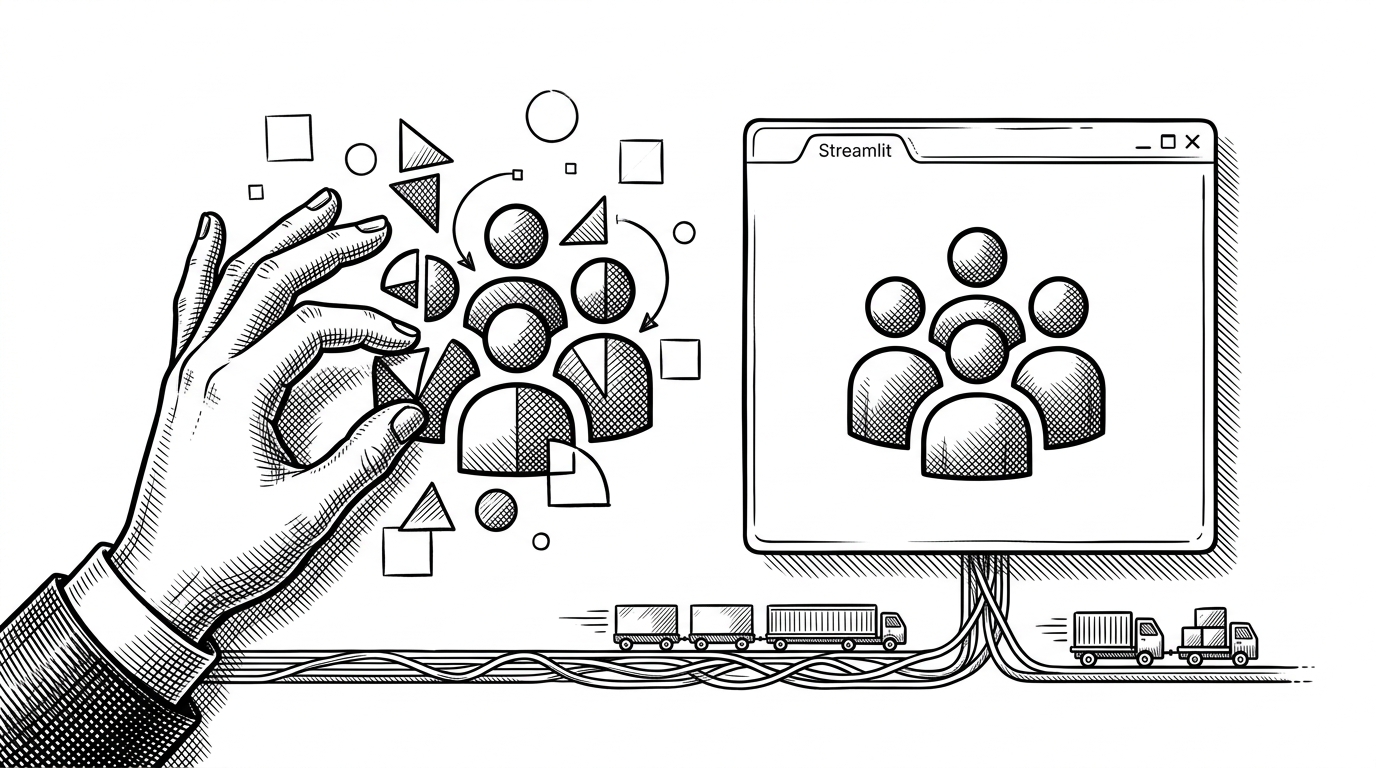
The engineering choices are pragmatic. The app uses a flat Streamlit layout, session state for navigation, and hosted data so the repository does not have to carry a giant payload. The code even generates team logos with SVG instead of relying on static image files. That is not just neat. It is the difference between a playful notebook and a deployable product.
Matchups are where the cricket gets sharpest
The dashboard becomes more interesting when it stops talking only about match winners. Style analytics turn the project into a strategy tool. Left-hand batters against left-arm spin. Venue splits. Player style profiles. Those are the kinds of questions coaches and analysts actually use.
| Lens | Typical notebook | `ipl-analytics` |
|---|---|---|
| Goal | Describe the league | Predict and explain outcomes |
| Model depth | Usually none or shallow | Ensemble model with engineered features |
| Explainability | Charts only | SHAP-backed feature interpretation |
| Leakage control | Often weak | Explicitly pre-match |
| Product form | Notebook or static report | Streamlit app with routing |
| Deployment readiness | Low | High for a lightweight repo |
That comparison explains the repo’s niche. Most IPL projects stop at charts. Some chase prediction without much rigor. `ipl-analytics` sits in a narrower, better lane. It combines analysis, modeling, and product thinking without pretending cricket is more predictable than it is.
Sources and project references
Repository: shibangmaity/ipl-analytics. Author avatar: shibangmaity on GitHub. Quote source: ipl-analytics README. Background research on comparable IPL analytics repos informed the comparison section, including notebook-first EDA projects and predictive notebooks that favor accuracy over restraint.