Decoding the Visual Syllabus: Avik-Jain/100-Days-Of-ML-Code
How a solo learner's visual shorthand became the de facto curriculum for the Scikit-Learn era.
Then one day out of nowhere I come across a video on Youtube by Siraj Raval, in which he talked about something called #100DaysOfMLCode Challenge. It means coding and studying machine learning for at least an hour, every day for the next 100 days.
- Avik Jain’s repository prioritizes pedagogical UX by translating abstract Scikit-Learn logic into a consistent visual language.
- The curriculum uses a standardized preprocessing pipeline on Day 1 to serve as a foundation for all subsequent machine learning models.
- The 100-day structure functions as a modular system that builds mathematical intuition through manual calculations before introducing high-level library abstractions.
- The visual shorthand for decision boundaries demystifies complex classification mechanics by plotting different algorithms against the same feature space.
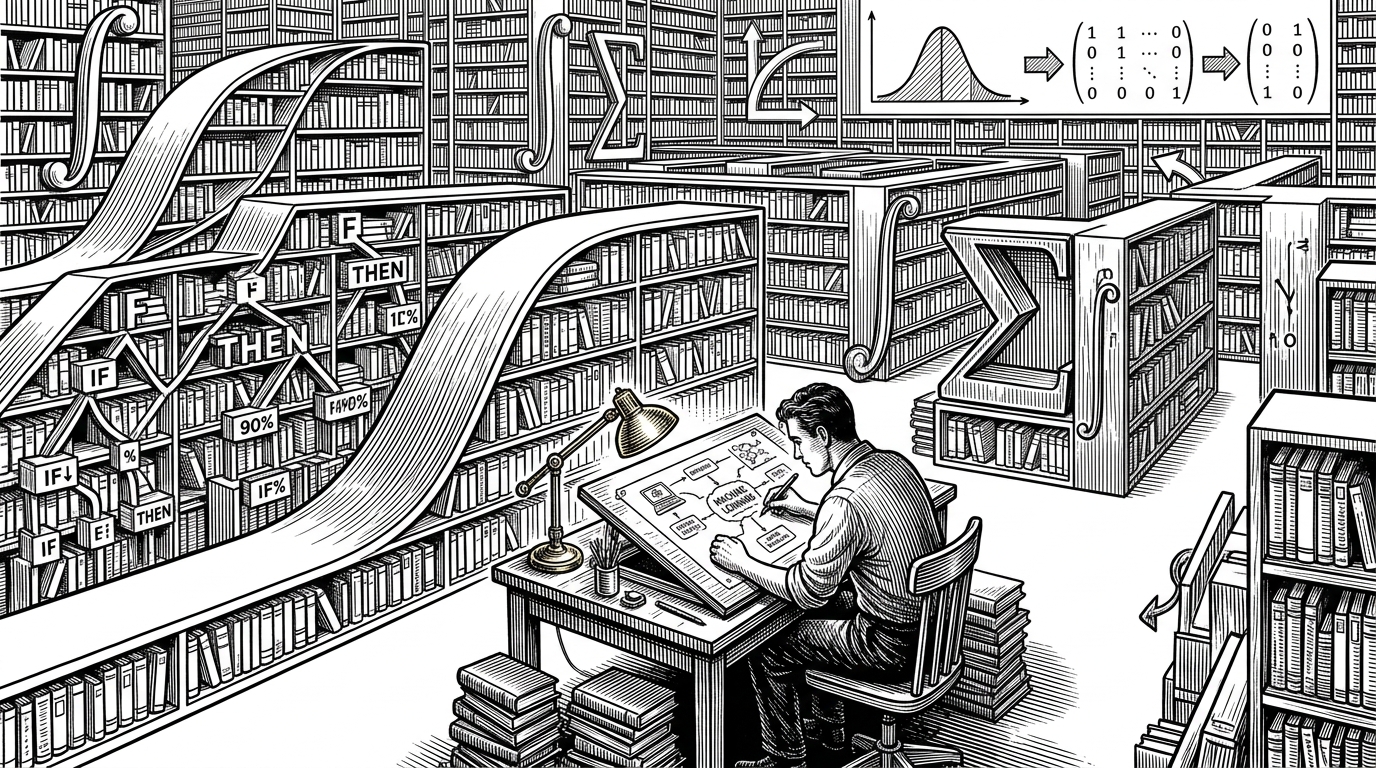
Most open-source success stories emphasize novel architectures, performance breakthroughs, or developer experience. Avik Jain's 100-Days-Of-ML-Code achieved its status through a completely different vector: pedagogical UX. It is a masterclass in treating a learning journey as an architectural blueprint.
The repository began as a personal log inspired by a community movement, but it quickly evolved into a global standard because it translated abstract Scikit-Learn logic into a consistent visual language. It combined a chronological challenge with cheat-sheet aesthetics.
The Geometry of a Classifier
The defining feature of the repository is its visual approach to decision boundaries. By consistently using ListedColormap to plot how different algorithms cut through the exact same feature space, the repository demystifies the mechanics of classification.
The Day 1 Protocol
Day 1 establishes the canonical preprocessing pipeline used throughout the repository. This six-step process acts as the base class for the entire 100-day journey. It handles missing values, encodes categorical variables, splits the dataset, and applies feature scaling.
| Raw Data State | Processed Data State |
|---|---|
| Missing values (NaN) | Imputed mean values |
| Categorical strings (France, Spain) | One-Hot Encoded binary columns (0, 1) |
| Single unified dataset | Train/Test split (e.g., 80/20 ratio) |
| Varying numerical scales (Salary vs Age) | Standardized scales (Mean=0, Variance=1) |
Habit as Architecture
The 100-day format is not merely a timeline. It is a modular system of increasing friction. Early days focus on manual calculations of cost functions, while later days transition to high-level library abstractions. This progression builds intuition before introducing convenience.
As I continually learned new things about ML, I’ve also updated therepositorywith the code for implementing ML algorithms along with some info-graphics for better understanding.
A Snapshot in Time
Because the repository was built during a specific era of Scikit-Learn, it contains legacy API calls. For example, it relies on the deprecated cross_validation module rather than model_selection. Yet, the underlying mathematical logic and the visual pedagogy remain entirely relevant.
# Legacy API used in the repository
from sklearn.cross_validation import train_test_split
X_train, X_test, y_train, y_test = train_test_split(X, y, test_size = 0.2, random_state = 0)

# Modern Scikit-Learn equivalent
from sklearn.model_selection import train_test_split
X_train, X_test, y_train, y_test = train_test_split(X, y, test_size = 0.2, random_state = 0)