kademlia-rs Gives Kademlia a Reputation System
The original paper evicts peers with a single ping. This Rust implementation tracks latency, success rates, and adaptive timeouts instead. A single line of code quietly makes all of it moot.
- Kademlia's eviction policy asks one question: is the oldest peer still alive?
- kademlia-rs replaces that single ping with a three-tier reputation system built on success rates, latency averages, and adaptive timeouts.
- On inspection, the code meant to feed those stats back into the bucket appears to drop them, which would make the first eviction tier dead code.
- The confirmed weaknesses sit in the plumbing, not the design: an unbounded replacement cache and key collisions in from_bytes.
The One Rule Kademlia Has for Forgetting You
Kademlia's routing table is built from k-buckets. Each bucket holds up to 20 peers, ordered by when they were last heard from. When a bucket is full and a new peer shows up, the original 2002 paper gives you exactly one instruction.
Ping the oldest peer in the bucket. If it answers, keep it and throw the newcomer away. If it does not, replace it. That is the whole policy. No latency column, no success rate, no history.
That minimalism is the point. A node that has been up for hours is more likely to be up in another hour, and the paper bets on that. It also means Kademlia never spends bandwidth measuring peers it can simply ask. Two decades later, that is still why it scales.
The 160-Bit Address Book
Every peer and every key gets a 160-bit identifier. Distance between two IDs is their bitwise XOR. It sounds arbitrary, but XOR gives Kademlia a metric that is symmetric and satisfies the triangle inequality, which is what makes greedy routing work.
The routing table sorts peers into buckets by the length of the shared prefix between their ID and yours. A peer whose ID differs in the first bit goes in bucket 0. A peer whose ID matches your first 159 bits goes in the last bucket.
The consequence is lopsided. Bucket 0 covers half the keyspace. The last bucket covers a sliver measured in single IDs. That is deliberate: you keep many contacts far away and few nearby, so any lookup can halve the remaining distance on every hop.
The code makes this concrete. bucket_index() finds the most significant set bit of the XOR distance, and that position is the bucket number. The math is one line; the routing behavior falls out of it.
The Reliability Ledger
Here is where kademlia-rs departs from the paper. Every contact carries a ResponseStats struct alongside its ID and address.
ResponseStats holds three things. Saturating counters for successes and failures. An exponential moving average of response latency, with alpha set to 0.2, so recent responses weigh more than old ones. And an adaptive_timeout(multiplier, base) method that computes average times multiplier plus base, capped at 30 seconds.
So a peer that has been answering in 40ms gets a short timeout. A peer that has been sluggish gets a longer one. The timeout tunes itself per contact instead of staying a fixed constant.
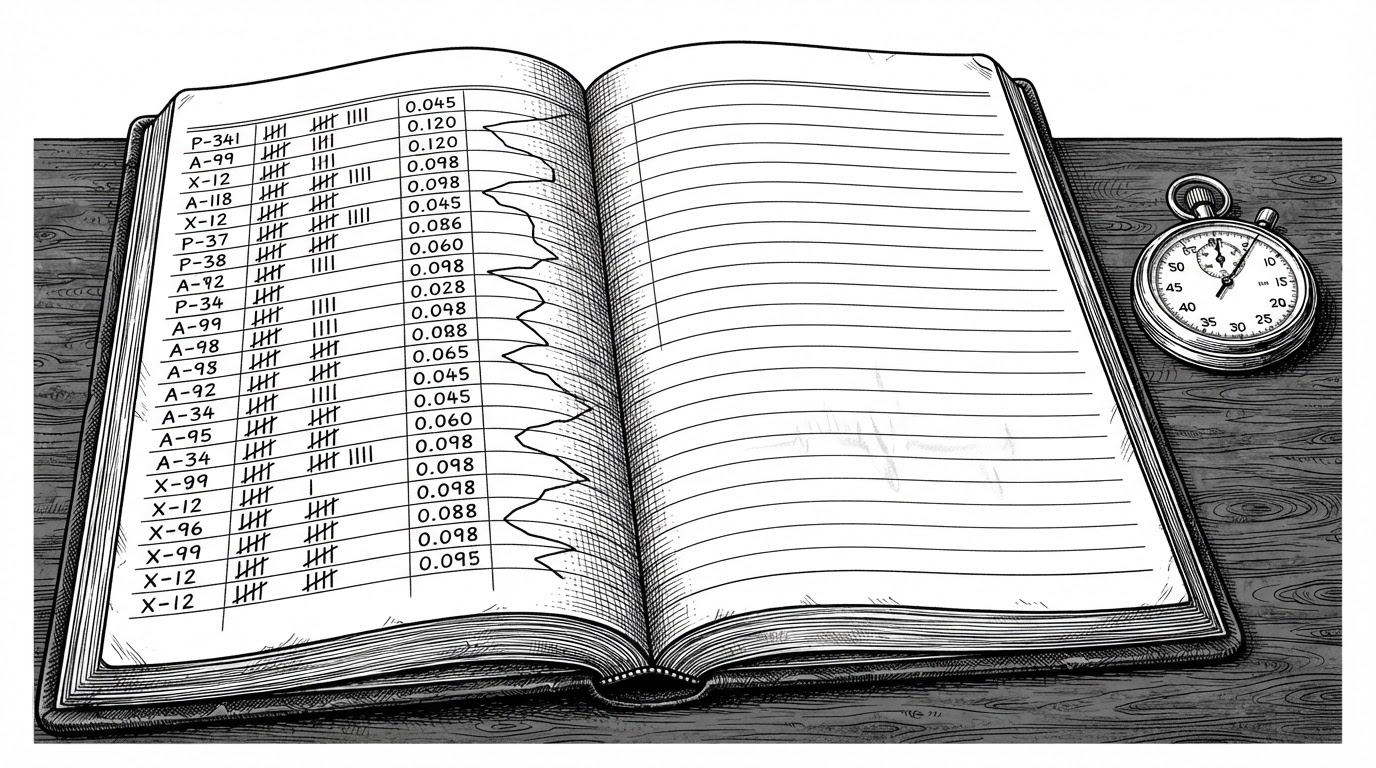
There is a benefit-of-the-doubt rule worth noting. A node with no history returns success_rate() == 1.0. New contacts are presumed good until they prove otherwise.
The timekeeping is deliberately boring. LastSeen stores Unix seconds rather than a Rust Instant, so it can be serialized and sent over the wire. The tradeoff is resolution: the tests acknowledge that sub-second timeouts cannot be tested. is_active also treats a backwards clock as active, which is a defensible if unusual choice.
None of this exists for its own sake. The ledger is there to feed the eviction policy in the next section.
Three Tiers Before You Ping
The eviction logic lives in KBucket::update(). When a bucket is full and a new contact arrives, the code does not go straight to the paper's ping. It walks three tiers.
Tier one: if any node in the bucket has a success rate below 0.5, evict it immediately. No ping. The newcomer takes its slot.
Tier two: if no node is unreliable, check the least-recently-seen node. If it has been inactive for more than 15 minutes, evict it and slot the newcomer in.
Tier three: if neither condition holds, the bucket is healthy. The newcomer goes into a replacement_cache, and the front node is returned as PendingPing so the caller can check whether the oldest peer still answers.
This is a real departure from the paper, and it is worth arguing about. The paper's prefer-long-lived-nodes property gets weaker here. A fresh peer with one timeout has a success rate of 0.0, which is below 0.5. If the bucket is full and a newcomer arrives, that one timeout is enough to evict it without a ping.
Whether that is good engineering depends on what you are optimizing for. If you want a table that holds only responsive peers, tier one is aggressive and effective. If you want stability, it is a way to churn contacts on a single bad packet.
The Ledger That Never Gets Written
The three-tier policy is the most interesting thing in the repo. So it is worth asking where the numbers that drive tier one actually come from.
They come from RoutingTable::record_success and record_failure. Those methods take the stored contact, clone it, update the clone's stats, and hand the clone to bucket.update(). Now look at what update() does with a contact it already knows: it finds the stored node, removes it, refreshes its last_seen, and pushes it back. It never reads the fields on the argument that was passed in.
// RoutingTable::record_success (simplified)
let mut node_clone = node.clone();
node_clone.record_success();
node_clone.record_response_time(elapsed);
bucket.update(node_clone);          // the updated clone goes in...

// KBucket::update, existing-node branch (simplified)
if let Some(pos) = self.nodes.iter().position(|n| n.id == node.id) {
    let mut existing = self.nodes.remove(pos);
    existing.last_seen = LastSeen::now();
    self.nodes.push_back(existing); // ...and the stored node comes back out
    return UpdateResult::Updated;
}
If that reading is right, the clone carrying the fresh stats is discarded, and the stored node with its old numbers is reinserted. The reputation layer records nothing. Tier one never sees a success rate below 0.5, because no success rate is ever written back.
This is a code-reading finding, not a proven one. It deserves a targeted unit test before anyone treats it as fact: call record_failure, then read the node's stats back out of the bucket. If the numbers move, the plumbing is fine and the design is intact. If they do not, one line has quietly disabled the repo's headline feature.
Two other issues need no such caveat. The replacement_cache is created with a capacity hint but has no size check on push_back. Under sustained traffic from unknown peers to a full bucket, it grows without limit, which is a resource-exhaustion vector. And NodeId::from_bytes does not hash despite its doc comment saying it does. Short keys are zero-padded and long keys are truncated, so b"a" and b"a\0" land on the same ID, and any two keys sharing a 20-byte prefix collide. That reaches the key-value store, since STORE and FIND_VALUE key on NodeId.
How It Stacks Up
kademlia-rs is not the only Rust Kademlia in the world, and it is not the most mature. What it is, is the only one with a reliability layer inside its eviction policy.
The table below is a snapshot from public documentation. Where a project does not document a detail, the cell says so rather than guessing.
| Project | Ecosystem | Key size | k-bucket representation | Eviction policy | Transports | Maintenance features | Maturity signal |
|---|---|---|---|---|---|---|---|
| kademlia-rs | Rust, standalone | 160-bit | LRU queue plus replacement cache | Three-tier: unreliable first, then stale, then ping (paper's policy plus reliability layer) | UDP, TCP, in-memory mock | TTL on stored values; refresh and republish not documented | Single contributor; README lists future improvements |
| libp2p-kad | Rust, libp2p ecosystem | 256-bit | Not documented here | Paper's ping-oldest policy | libp2p transports | Integrated with libp2p behaviours | Actively maintained, widely deployed |
| kad crate | Rust, generic | Configurable | Not documented here | Not documented here | Any, via futures | Value expiry, bucket refresh, republishing listed incomplete | Self-described work in progress |
| jeffrey-xiao/kademlia-dht-rs | Rust, library | 256-bit | Growable vector | Paper's policy | Not documented here | Caching and republishing not implemented | Documents its tradeoffs |
| MatsDK/Kademlia-rs | Rust plus Tauri interface | Not documented here | Not documented here | Not documented here | Tauri test interface | Expiry, replication, republishing marked complete | Small, includes testing UI |
Read the table as a decision tool, not a scoreboard. If you are already on rust-libp2p, libp2p-kad is the integrated choice, and its main gotcha is wiring up Identify with Behaviour::add_address, or discovery stays limited to boot nodes.
If you want a generic, futures-based implementation with configurable transport and encoding, the kad crate is that, though its own README calls it work in progress and lists value expiry, bucket refresh, and republishing as incomplete.
kademlia-rs's only column-leading entry is the eviction policy. Everywhere else it is a small, standalone project with a single contributor and an honest future-improvements list. That is not a criticism. It is the positioning.
What a Small DHT Is Actually For
The README names persistence, NAT traversal, security, and failure handling as open work. That honesty is useful. It tells you exactly what this is: a readable implementation of a famously clever protocol.
The learning value is concrete. There is an in-memory mock network for tests, so you can run a full lookup without opening a socket. There is a simple_node CLI that runs bootstrap, join, store, and get. There are design documents on the roadmap for malicious-node mitigation and NAT traversal.
The constants are worth knowing by heart, because they are the protocol in miniature.
- K = 20 peers per bucket
- NODE_TIMEOUT = 15 minutes
- MIN_SUCCESS_RATE = 0.5
- 160-bit identifiers, XOR distance
None of this makes it production infrastructure, and it does not claim to be. What it does make it is a good place to read Kademlia in Rust, with a reputation layer bolted on that is worth understanding whether or not the plumbing ends up carrying it.