Blog_writing_Agent: The Writing Bot That Knows When to Research
A LangGraph pipeline that routes topics by epistemic mode, fans out section drafts in parallel, and patches visuals into the final article only after the argument is clear.
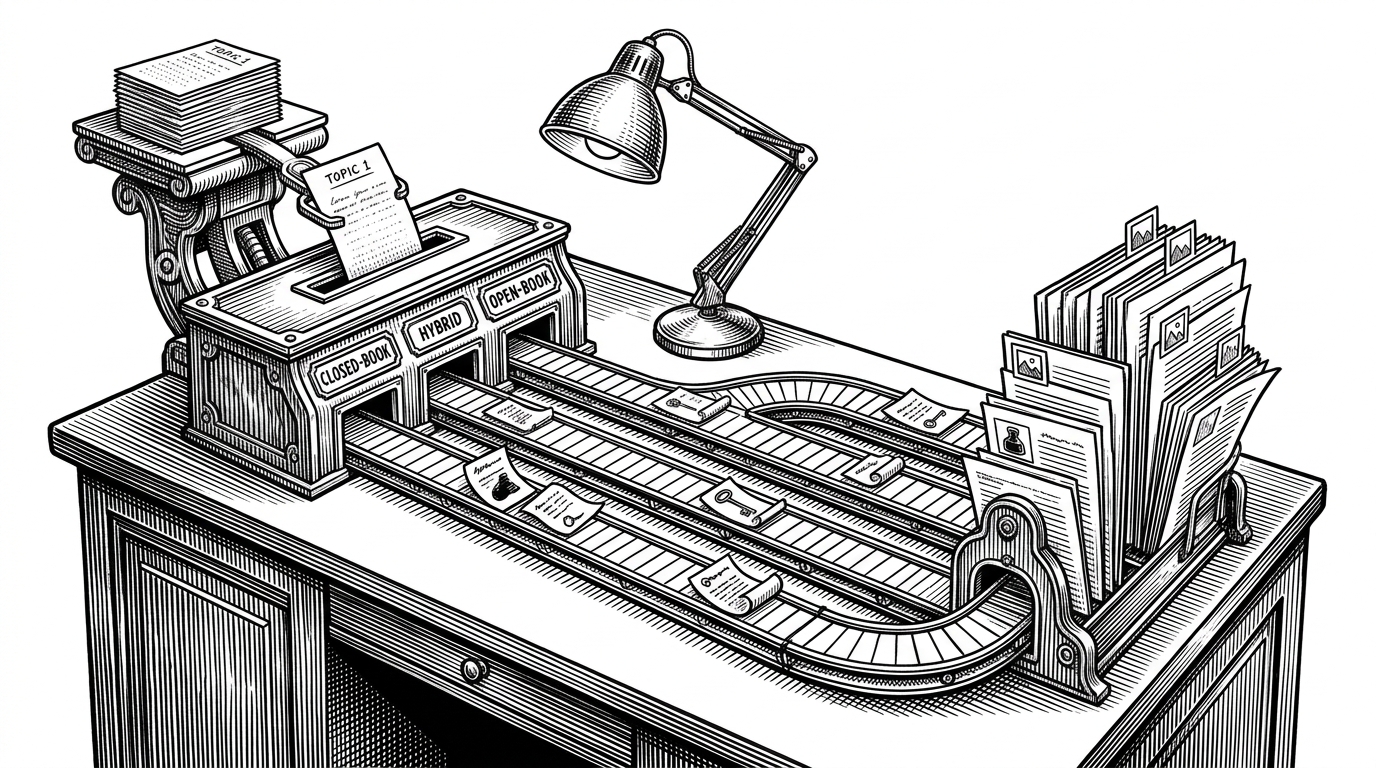
- Blog_writing_Agent treats editorial judgment as a routing problem, so the first decision is not what to write but how much research the topic deserves.
- Its real differentiator is epistemic mode, which lets the system switch between closed-book, hybrid, and open-book workflows instead of using one generic generation path.
- The LangGraph state machine turns that judgment into parallel drafting, so research, planning, and section writing stay structured even as the workload fans out.
- The frontend and image-patching steps make the system product-shaped, but the article pipeline still waits until the argument is clear before it adds visuals.
The real product is judgment
This repo is not trying to be a smarter autocomplete box for blogs. It is trying to teach an agent how to decide what kind of knowledge problem a topic is before it writes a word.
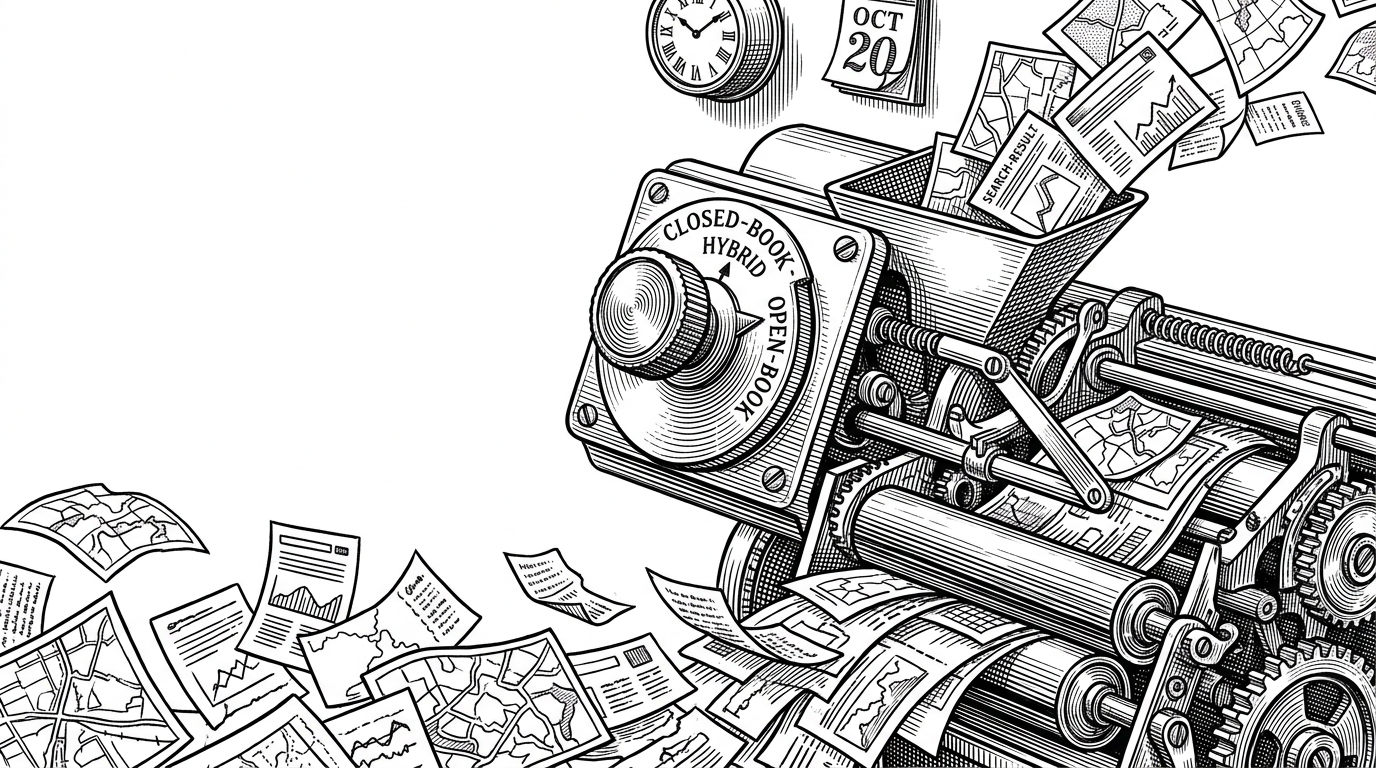
That is the striking part of Blog_writing_Agent. The system routes topics into closed-book, hybrid, or open-book modes, then changes how much search, evidence, and drafting it performs.
Most writing tools assume every request is the same. This one does not. A stable concept, a fast-moving library release, and a current AI news topic do not deserve the same workflow, so the agent starts by classifying the epistemic risk.
Why the router matters more than the writer
The backend research points to a recency-aware design. The router does not just decide whether to search. It also adjusts how far back the system should look, with short windows for volatile topics and very long windows for evergreen ones.
That matters because a lot of AI writing failures are really freshness failures. The model sounds fluent, but it grounds the article in stale facts, outdated product behavior, or generic examples that no longer reflect the state of the world.
| Mode | Research posture | Best fit | Failure mode |
|---|---|---|---|
| Closed-book | No search, direct drafting | Stable definitions and timeless explanations | Can over-explain with generic knowledge |
| Hybrid | Targeted search around recent evidence | Topics that need context plus freshness | Can miss edge cases if the search window is too narrow |
| Open-book | Broad search and heavier evidence use | Fast-moving tools, releases, and news | Can slow the workflow if the topic is actually stable |
How the graph turns a topic into a plan
The repo’s backbone is a LangGraph state machine. A shared `State` object carries the topic, the research notes, the plan, the drafted sections, and the final merge through each node.
The useful pattern here is not just statefulness. It is structured state. The router returns a machine-readable decision, the planner returns a task list, and the workers consume that structure instead of improvising their own instructions.
class State(TypedDict):
    topic: str
    mode: str
    recency_days: int
    research: list[str]
    plan: list[Task]
    sections: Annotated[list[tuple[int, str]], operator.add]

router_decision = llm.with_structured_output(RouterDecision)
result = router_decision.invoke({"topic": topic})
mode = result.mode
recency_days = result.recency_days
That `sections` field is doing real work. The reducer pattern lets multiple workers append their outputs without trampling each other, which is exactly what you want when a long article is being assembled from independent pieces.
Parallel drafting without losing structure
This is where the repo stops feeling like a demo and starts feeling like an actual production workflow. The orchestrator turns one topic into tasks, then LangGraph fans those tasks out to workers in parallel.
Each worker gets a bounded job. That keeps the model focused and makes the output easier to merge. The system is not asking one agent to hold an entire article in memory while also managing research, style, and section order.
| Pattern | What it optimizes for | Why it matters here |
|---|---|---|
| Single-pass generation | Speed | Fast, but brittle when the article needs evidence or structure |
| Sequential drafting | Coherence | Safer than one-shot writing, but slower as sections multiply |
| Fan-out plus reducer | Scalability with structure | Matches long-form writing, where sections can be authored independently and merged cleanly |
That is also why the repository’s writing process feels editorial instead of purely generative. The model acts more like a managing editor assigning sections than a novelist improvising a chapter.
The frontend is not a shell
The Streamlit frontend is doing more than wrapping a backend call. It handles the practical friction that turns an agent from a script into something a person can actually use.
According to the repository analysis, it streams progress, resolves locally generated markdown images into usable paths, and supports the live review loop that makes long generation jobs feel tractable. That matters because content systems fail in the handoff as often as they fail in the model.
def render_markdown_with_local_images(markdown_text):
    # Resolve generated image paths before rendering
    updated = re.sub(r'!\[(.*?)\]\((.*?)\)', replace_local_image, markdown_text)
    return updated

for chunk in try_stream(graph, inputs):
    st.write(chunk)
Visuals are added after the argument exists
The image pipeline is another sign of discipline. The repository’s flow first merges content, then decides where images would help, then generates and places those images.
That sequence matters. It keeps illustrations subordinate to the structure of the article rather than treating them as decorative filler. The visuals arrive after the argument is formed, which is exactly the right order for technical writing.
Generating illustration...
That restraint is part of the project’s quality. A lot of AI content systems use imagery as camouflage. This one uses it as a final explanatory layer.
What it beats, and what it does not
The cleanest comparison is not just feature by feature. It is workflow philosophy versus workflow philosophy.
| Approach | Primary user | Research model | Customization | Cost model | Strength | Weakness |
|---|---|---|---|---|---|---|
| Blog_writing_Agent | Developer or technical writer | Router decides closed-book, hybrid, or open-book | High, because the code is open | Open source plus API costs | Encodes an editorial process instead of a prompt | Requires technical setup |
| Jasper, Copy.ai, Writesonic | Marketer or general content user | Usually product-driven templates and built-in flows | Moderate | Subscription | Polished UX and quick onboarding | Less control over the pipeline |
| LangChain, CrewAI | Builder | Whatever the developer assembles | Extreme | Open source plus API costs | General-purpose flexibility | You still have to design the writing workflow yourself |
The important distinction is that this repo is not trying to out-template Jasper or out-framework LangChain. It is trying to encode a better editorial process for one specific job: research-aware long-form writing.
That makes it narrower than a platform and more opinionated than a toolkit. Narrow is not a drawback here. It is the reason the system has a point of view.
What this repo suggests about AI writing
The bigger lesson is that AI writing is moving from prompt craft to orchestration design. The interesting unit is no longer the paragraph. It is the workflow that decides what kind of knowledge the paragraph should be built on.
If that trend continues, the human role changes too. Writers become editors of process, not just authors of sentences. The highest-leverage skill becomes choosing when to search, when to trust the model, and when to force structure before prose.
Blog_writing_Agent is useful because it makes that shift concrete. It is a writing system that knows writing starts with judgment.