Redlining the GPU: The Architecture of Insanely Fast Whisper
How staying in Python, and breaking the rules of sequential processing, created the world's fastest open-source transcription pipeline.
"Transcribe 150 minutes of audio in less than 98 seconds (powered by Transformers & Tri Dao's Flash Attention 2)."
- Insanely Fast Whisper achieves record-breaking speeds by leveraging Flash Attention 2 and aggressive batching within a pure Python environment.
- The architecture prioritizes high-end GPU throughput over universal compatibility by enforcing 16-bit precision and hardware-specific optimizations.
- The system integrates speaker identification by using a fuzzy matching algorithm to align independent diarization and transcription timelines.
- This project proves that opinionated Python orchestration can outperform custom C++ implementations on modern enterprise silicon.
The 98-Second Benchmark
The Python ecosystem carries a reputation for sluggish execution. For years, the standard playbook for scaling AI models involved rewriting them in C or C++. This is exactly what the community did with OpenAI's original Whisper model, creating highly optimized ports designed to run on everything from Raspberry Pis to MacBooks.
Then came a benchmark that shattered assumptions. A pure Python implementation processed 150 minutes of audio in under 98 seconds on an NVIDIA A100 GPU. It did not rely on a custom C++ engine. Instead, it leveraged the exact tools the industry had dismissed as too heavy: the Hugging Face Transformers library.
This is the architecture of Insanely Fast Whisper. It is not a new model. It is a masterclass in hardware-aware orchestration. By enabling specific hardware cheat codes, it proves that staying within the Python ecosystem yields the fastest results on modern silicon.
The Three Pillars of Throughput
Most transcription tools prioritize real-time processing. They take incoming audio, process a few seconds, and return the text. Insanely Fast Whisper Abandons this sequential approach entirely.
The architecture relies on three distinct pillars to maximize GPU utilization. First, it enforces 16-bit precision (fp16) by default, halving the memory footprint without a noticeable drop in transcription quality. Second, it integrates Flash Attention 2, a highly optimized memory-efficient algorithm that drastically speeds up Transformer calculations on Ampere-architecture GPUs.
The final pillar is aggressive batching. Standard implementations process small chunks of audio. Insanely Fast Whisper defaults to a batch size of 24. It loads the GPU memory to its absolute limit, processing two dozen audio segments in parallel. This shifts the bottleneck from compute speed to memory bandwidth.
The Diarization Stitch
Whisper is exceptional at turning speech into text. It is entirely ignorant of who is speaking. To solve this, developers typically run a separate speaker identification model (diarization). The architectural challenge lies in merging these two independent data streams.
Insanely Fast Whisper handles this through a post-processing alignment phase. It runs the audio through Whisper to generate text timestamps. It then runs the same audio through a Pyannote diarization model to generate speaker boundaries.
The alignment engine does not force the models to communicate. Instead, it uses a fuzzy matching algorithm. By applying `numpy.argmin`, the system snaps the speaker labels onto the nearest text chunk boundaries. It zips two independent timelines into a single, cohesive transcript.
# Simplified representation of the alignment logic
def post_process_segments_and_transcripts(segments, diarization_result):
    for segment in segments:
        # Find the speaker blob closest to the text segment's start time
        closest_speaker_idx = np.argmin([
            abs(segment["start"] - speaker["start"])
            for speaker in diarization_result
        ])
        segment["speaker"] = diarization_result[closest_speaker_idx]["label"]
    return segments
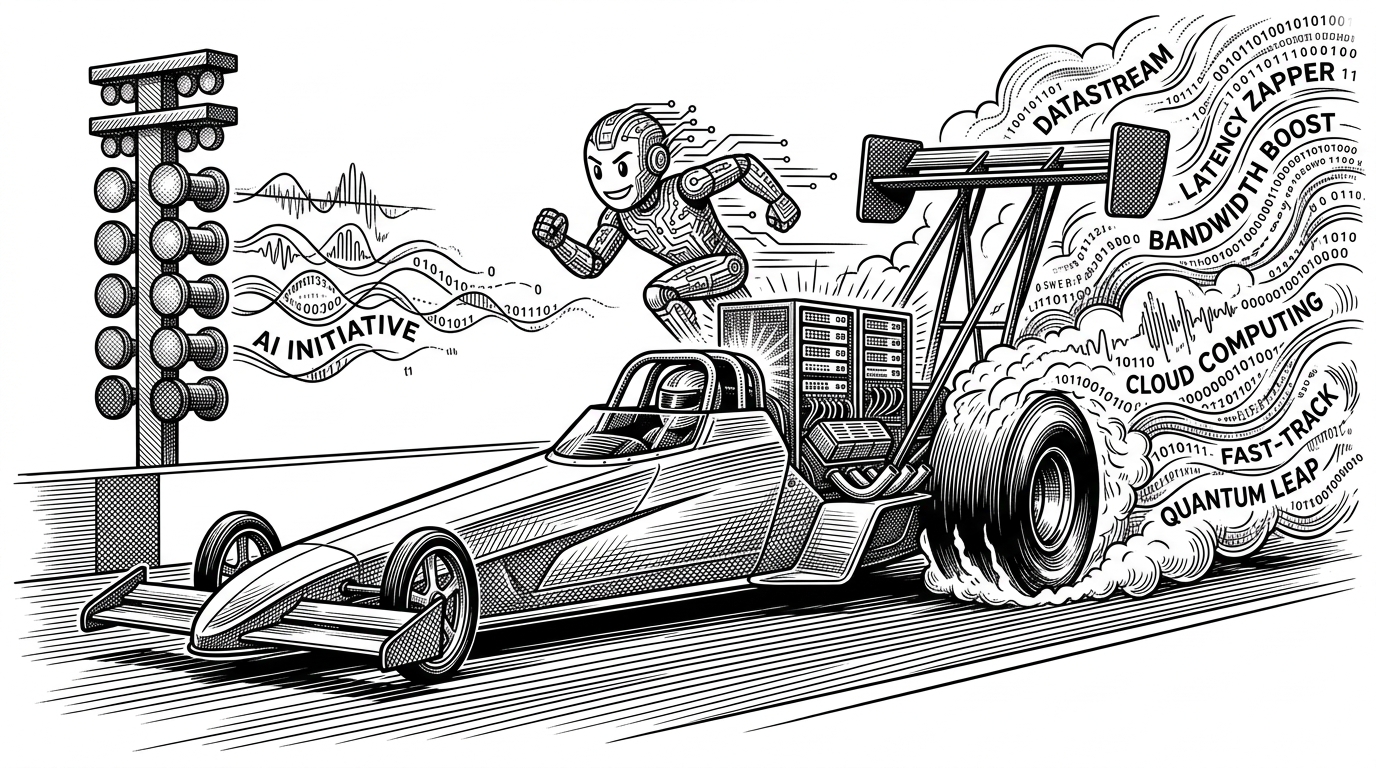
C++ vs. The Python Drag Racer
The open-source transcription landscape is heavily fragmented. Choosing the right tool depends entirely on the deployment environment.
| Project | Core Engine | Best Environment | Primary Optimization |
|---|---|---|---|
| whisper.cpp | Custom C/C++ | Edge Devices, CPUs, MacBooks | Zero dependencies, ultimate portability. |
| faster-whisper | CTranslate2 (C++) | Production Servers | Low latency, strong CPU and GPU balance. |
| insanely-fast-whisper | Python (Transformers) | High-End GPUs (A100, H100) | Maximum throughput via Flash Attention 2. |
If the goal is to transcribe a podcast on a Raspberry Pi, a C++ port is mandatory. If the goal is to chew through ten thousand hours of archival audio on an enterprise GPU cluster, Insanely Fast Whisper wins decisively.
The Power of Opinionated Defaults
The success of the project stems from what it refuses to do. It does not attempt to fall back gracefully on older hardware. It assumes the user has access to modern silicon and configures the environment to exploit it.
By wrapping complex dependencies like Flash Attention 2 inside a single CLI command, the project lowers the barrier to entry for extreme performance. It proves that abstraction does not always require a performance penalty, provided the orchestrator understands the hardware beneath the code.
Sources