Local LLM Inference
On-device inference, MLX, vLLM, local/offline AI serving, and Apple Silicon stacks
125 explainers
Local LLM Inference
The Packaging of Intelligence: How Ollama Standardized the Local Model
By treating Large Language Models like containers, a simple Go wrapper solved the AI deployment crisis and sparked a local-first ecosystem.
Local LLM Inference
The C++ Rebellion: Unpacking llama.cpp
How a zero-dependency engine bypassed the Python ecosystem and turned consumer laptops into the world's most popular AI workstations.
Local LLM Inference
Unsloth: The Local AI OS That Refuses to Break
From custom Triton kernels to spawned training workers and live data recipes, Unsloth Studio turns fine-tuning, inference, and model juggling into one self-healing local workflow.
Local LLM Inference
The 300-Line LLM Engine: Inside nanoGPT
Andrej Karpathy stripped away the enterprise bloat of modern AI frameworks. What remains is a masterclass in raw PyTorch performance.
Local LLM Inference
karpathy/nanochat: The $100 Full-Stack LLM
How Andrej Karpathy collapsed the entire generative AI pipeline from raw tokens to a conversational web UI into a single hackable codebase.
Local LLM Inference
Exo: The Local AI Cluster That Turns Macs Into a Frontier-Model Machine
How a Python-and-Rust orchestration layer, topology-aware sharding, and RDMA over Thunderbolt let Exo run oversized models on consumer hardware without forcing developers to rewrite their apps.
Local LLM Inference
DuckDB: The Database That Refuses to Become a Server
How an in-process, vectorized SQL engine turned local files, notebooks, and apps into first-class analytics environments.
Local LLM Inference
BitNet: The Repo That Tries to Make a CPU Think in Ternary
Microsoft’s `bitnet.cpp` turns 1.58-bit models into a new inference stack, where packed weights, custom kernels, and cache-aware math matter more than floating-point precision.
Local LLM Inference
The PC Part Picker for Local AI: Unpacking llmfit
How a Rust-based diagnostic engine uses bandwidth math and hardware probes to solve the 'will it run' problem before you download a single weight.
Local LLM Inference
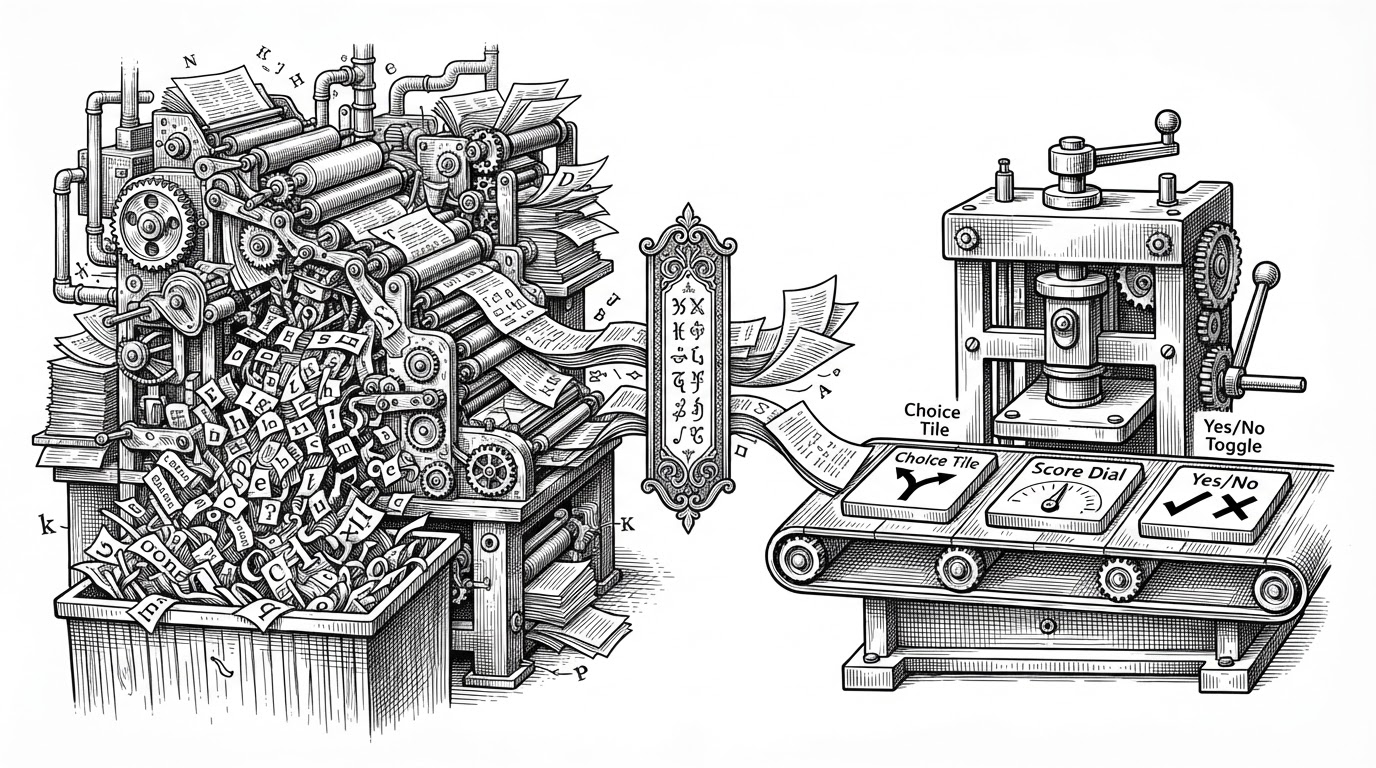
Laya: The Decision Engine That Refuses to Generate Text
A deep look at the system that turns BERT-style encoders, calibrated scoring, and script-aware routing into a low-latency reflex layer for classification, moderation, and structured decisions.
Local LLM Inference
tinygrad: The Radical Minimalism of Software Sovereignty
How 25 universal operations and a "no-module" policy are dismantling the complexity of modern deep learning.
Local LLM Inference
Hands-On-Large-Language-Models: Inside HandsOnLLM: Cracking Open the Black Box
How a textbook companion repository became the definitive curriculum for language models by embracing hardware constraints and exposing raw tensors.
Local LLM Inference
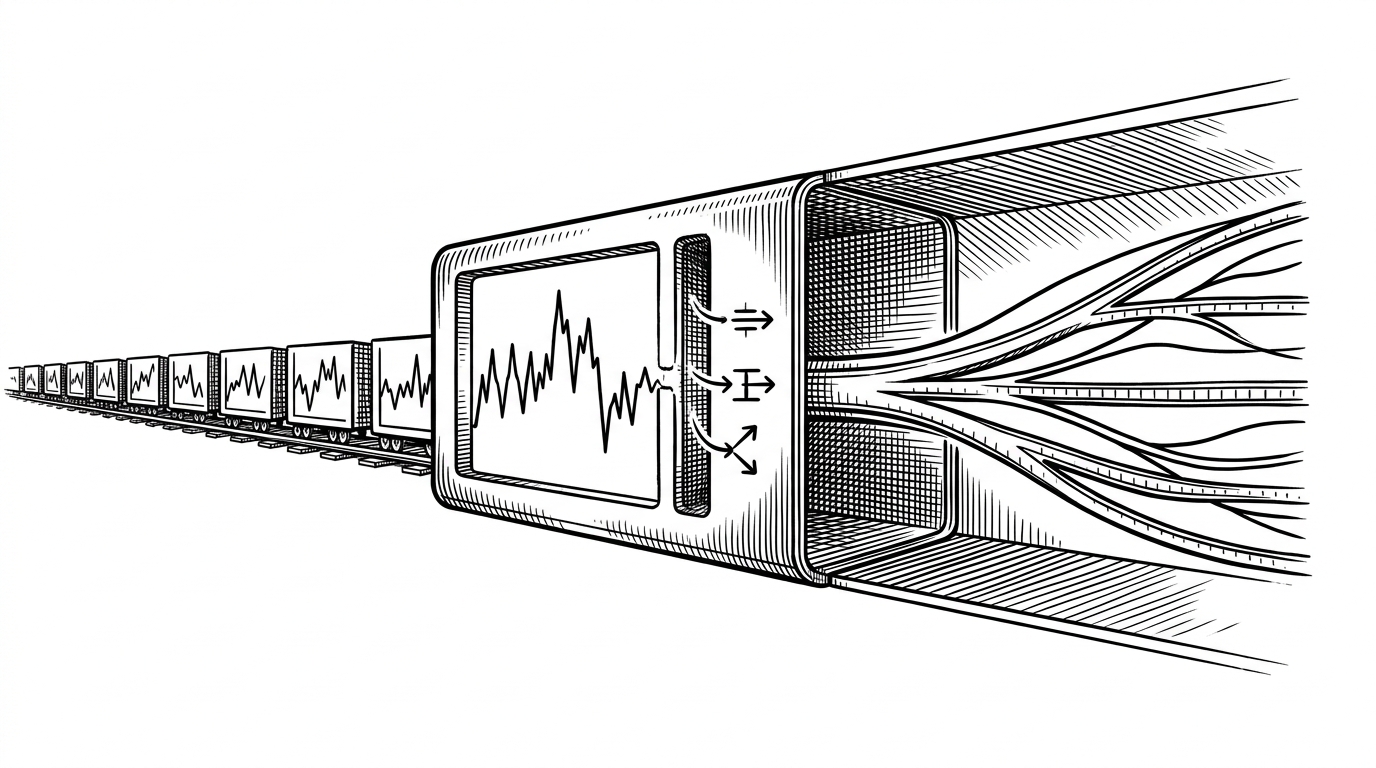
TimesFM: Google’s Forecasting Model That Thinks Like an LLM
A decoder-only time-series foundation model that replaces per-dataset training with zero-shot prediction, patch-based decoding, and probabilistic forecasts.
Local LLM Inference
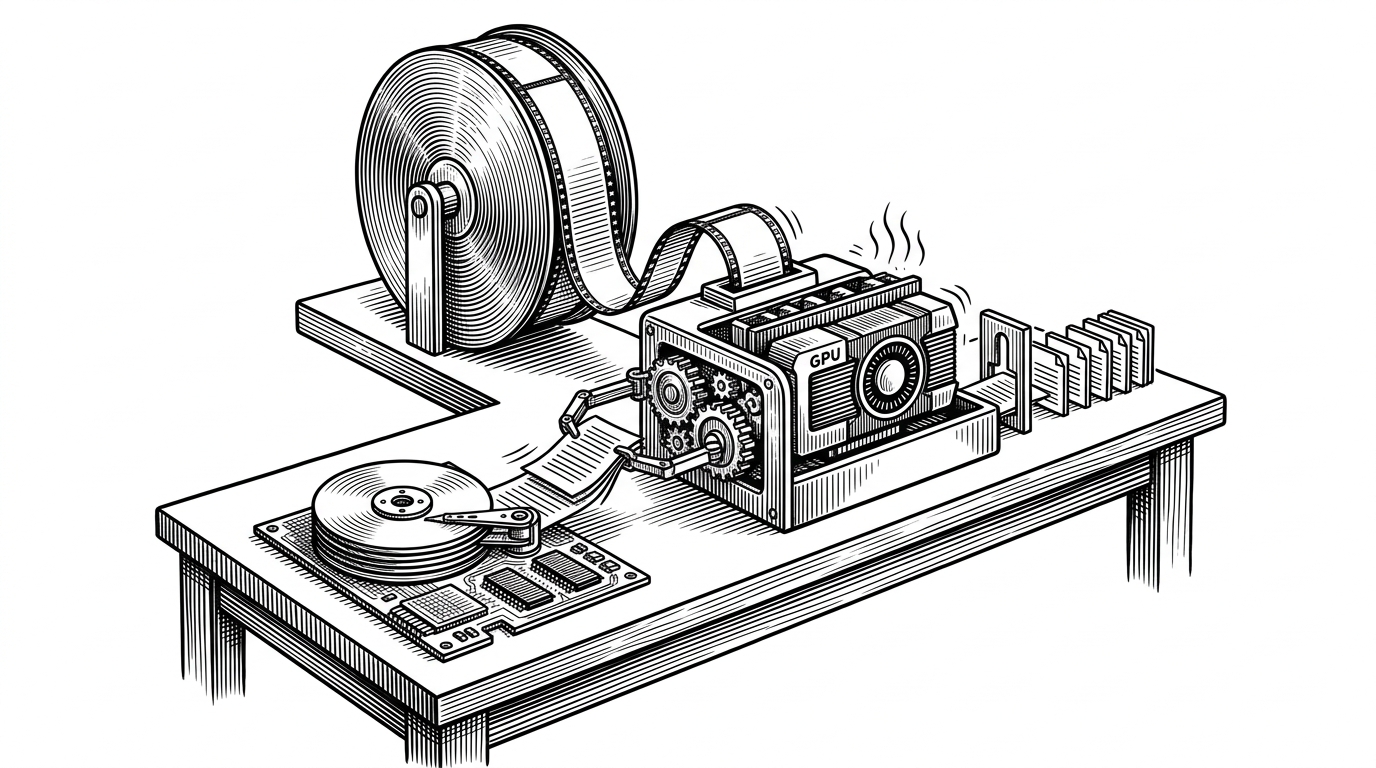
ds4: The DeepSeek Engine That Treats Inference Like a Storage Problem
Salvatore Sanfilippo’s narrow C engine turns one model family into a readable, hardware-shaped pipeline for long-context local inference.
Local LLM Inference
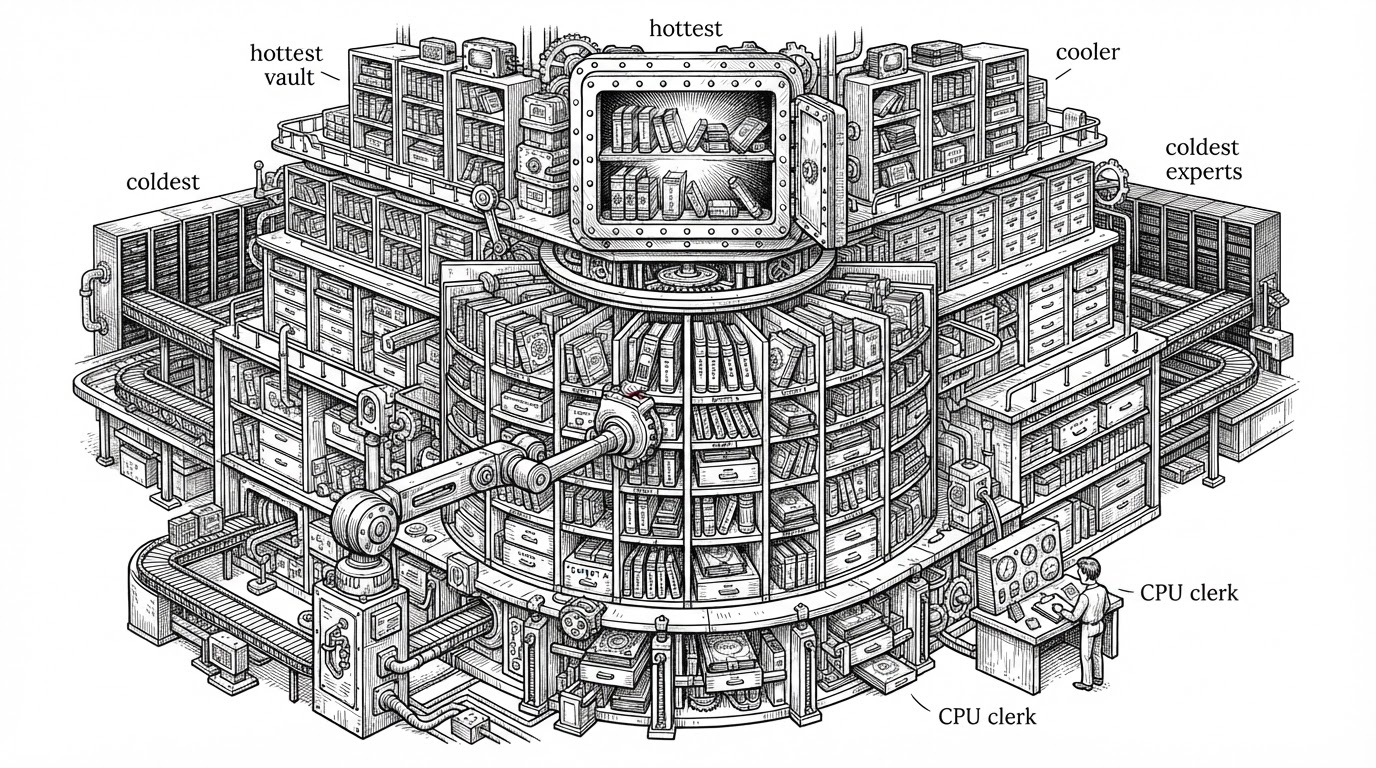
Strata: The Inference Engine That Runs a 125B MoE Like a Memory Cache
How a C++ and CUDA engine turns expert routing, graph capture, and aggressive quantization into a practical way to run server-class models on consumer GPUs.
Local LLM Inference
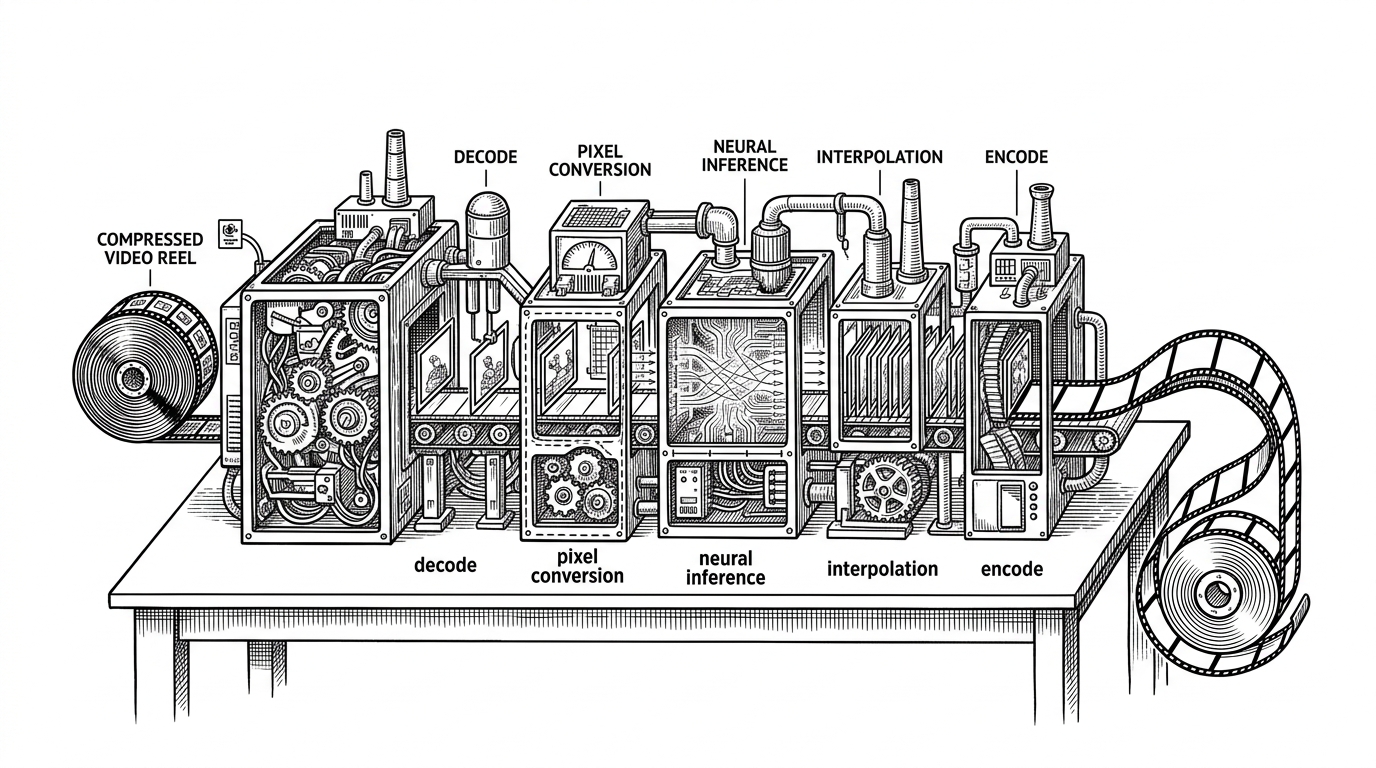
Video2X: The Open-Source Upscaler That Rebuilt Itself as a Native Media Engine
A look at the C++ rewrite, the zero-disk pipeline, and the GPU-agnostic design that turns local video enhancement into infrastructure.
Local LLM Inference
Heretic: The Optuna Engine for Removing Refusal from Open Models
A deep dive into how a LoRA-based patch, geometric analysis, and automated search turned abliteration from a manual trick into a repeatable system.
Local LLM Inference
Nano-vLLM: The Small Codebase That Explains How LLM Serving Actually Works
A Python-first inference engine that makes PagedAttention, prefix caching, preemption, and tensor parallelism feel understandable instead of opaque.
Local LLM Inference
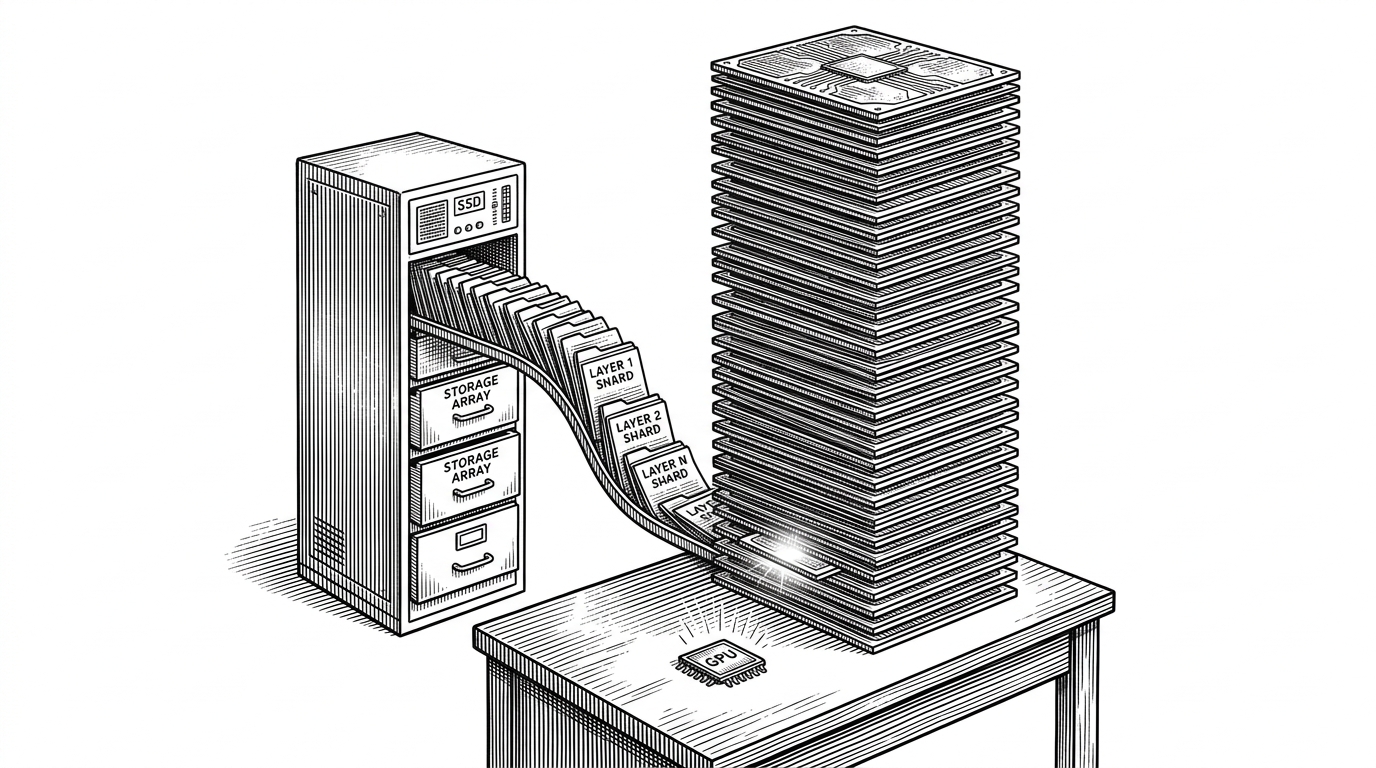
AirLLM: The LLM Engine That Lives on Disk, Not in VRAM
A layer-streaming inference library that makes 70B to 405B models run on consumer hardware by treating GPU memory as a transient workspace, not a home.
Local LLM Inference
ACE-Step-1.5: ACE-Step 1.5: The Open-Source Music Model That Plans the Song Before It Makes a Sound
A deep dive into the planner-plus-diffusion architecture, the VRAM tricks that make local generation practical, and the API design that turns a research model into a product.
Local LLM Inference
Redlining the GPU: The Architecture of Insanely Fast Whisper
How staying in Python, and breaking the rules of sequential processing, created the world's fastest open-source transcription pipeline.
Local LLM Inference
kimi-k3-in-c: How a C99 Engine Turns RAM Into a Dial for a 2.78T-Parameter Model
A zero-dependency inference engine streams weights, caches experts, and keeps outputs reproducible, even when the model is far larger than memory.
Local LLM Inference
Kimi-K3: The Open-Weight Model That Bets on Selective Intelligence
A 2.8-trillion-parameter system with 1M-token memory, native multimodality, and a MoE design built to stay sharp by activating less.
Local LLM Inference
OpenMythos: The Recurrent Transformer That Tries to Think Before It Stops
A deep dive into the looped backbone, adaptive halting, and depth-aware attention behind an open reconstruction of Claude-like architecture.
Local LLM Inference
The Universal Engine: Inside mistral.rs
How a zero-config Rust architecture is turning local LLM inference into a multimodal, agentic runtime.
Local LLM Inference
The Death of Symmetric Memory: Inside TheTom/turboquant_plus
By proving that LLM Value caches can be aggressively compressed without lobotomizing the model, this experimental integration is rewriting the rules of local inference.
Local LLM Inference
OBLITERATUS: How to Cut Refusal Out of an LLM Without Retraining
A research-grade toolkit that treats safety guardrails as geometry, then uses SVD, projection, and feedback loops to excise them while trying to preserve the rest of the model.
Local LLM Inference
laya-mlx: The Apple Silicon Runtime That Turns AI Into Instant Decisions
A native MLX port of Laya replaces token-by-token generation with bidirectional, typed inference for routing, moderation, scoring, and other low-latency decisions.
Local LLM Inference
Eventual-Inc/Daft: The DataFrame Built for the Multimodal Era
How a Rust-powered execution engine bypasses the JVM tax to treat images, video, and audio as first-class data citizens.
Local LLM Inference
Gemma: The JAX Blueprint for an Open Multimodal Frontier Model
Inside Google DeepMind’s Gemma repo, where text, vision, audio, attention tricks, and fine-tuning utilities come together in one modular Python stack.
Local LLM Inference
mlx-vlm: The MacBook's Native Vision Engine
How a lightweight Python framework exploits Apple's unified memory to bring multimodal fine-tuning and autonomous GUI agents to consumer hardware.
Local LLM Inference
SemIf: The Open Source Project That Turns an LLM Into a Logit Reader
Instead of generating JSON and fixing it afterward, SemIf reads option probabilities directly, reuses cached prefixes across many questions, and makes local inference feel like a typed decision engine.
Local LLM Inference
openjev: SemIf: Turning a Language Model Into an If Statement
A local-first research baseline that reads logits instead of generating text, so LLMs can make fast typed decisions on consumer hardware.
Local LLM Inference
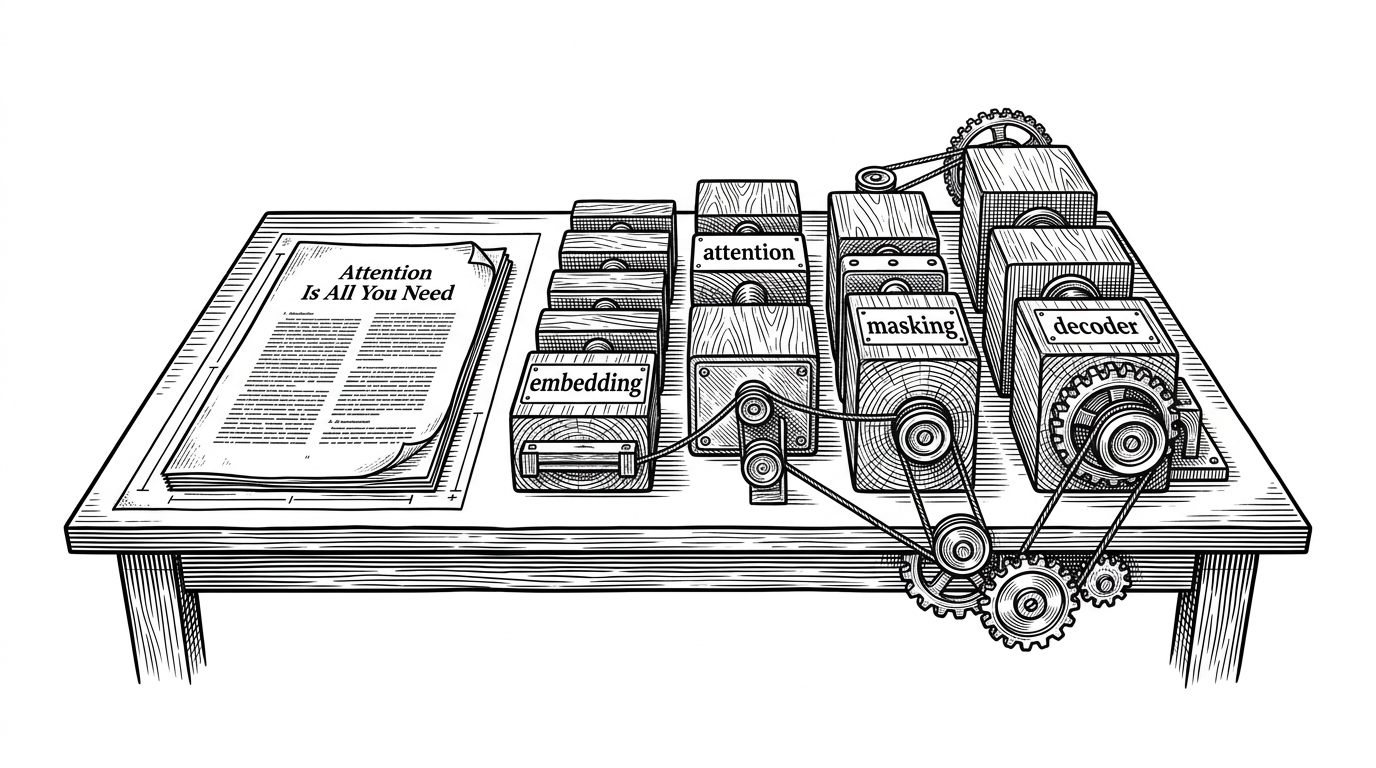
hyunwoongko/transformer: The Transformer Repo That Reads Like the Paper
A from-scratch PyTorch build that turns multi-head attention, masking, and positional encoding into a file tree you can actually follow.
Local LLM Inference
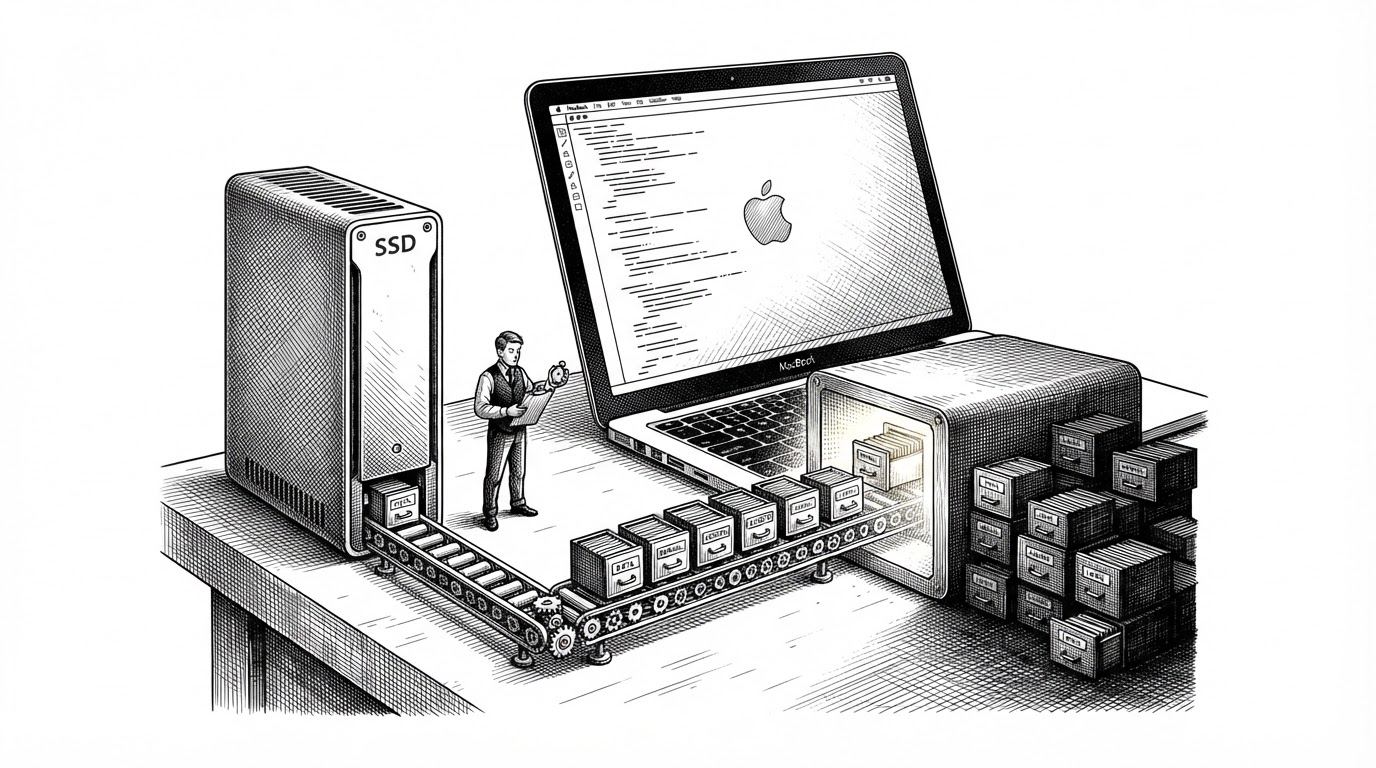
Edge0: The MoE Engine That Hides SSD Latency in Plain Sight
A deep dive into the prerouter, streaming expert offload, and Recover-LoRA, the three ideas that let a 35B-class model behave like it belongs on a MacBook.
Local LLM Inference
Inside GLM-OCR: How a 0.9B Parameter Pipeline Outsmarts Giant VLMs
By pairing a tiny vision-language model with a structural layout engine and speculative decoding, Zhipu AI built a local-first OCR system that beats the 235B-parameter giants.
Local LLM Inference
Flash-MoE: The Apple Silicon Engine That Makes a 397B Model Behave Like It Has More Memory
A pure C and Metal inference stack for Apple Silicon that streams MoE experts from SSD, leans on macOS page cache instead of custom caching, and turns hardware constraints into the architecture.
Local LLM Inference
GuppyLM: The Fish That Makes LLMs Legible
A tiny transformer, synthetic conversations, and browser deployment turn one open-source repo into a clean tour of how language models are actually built.
Local LLM Inference
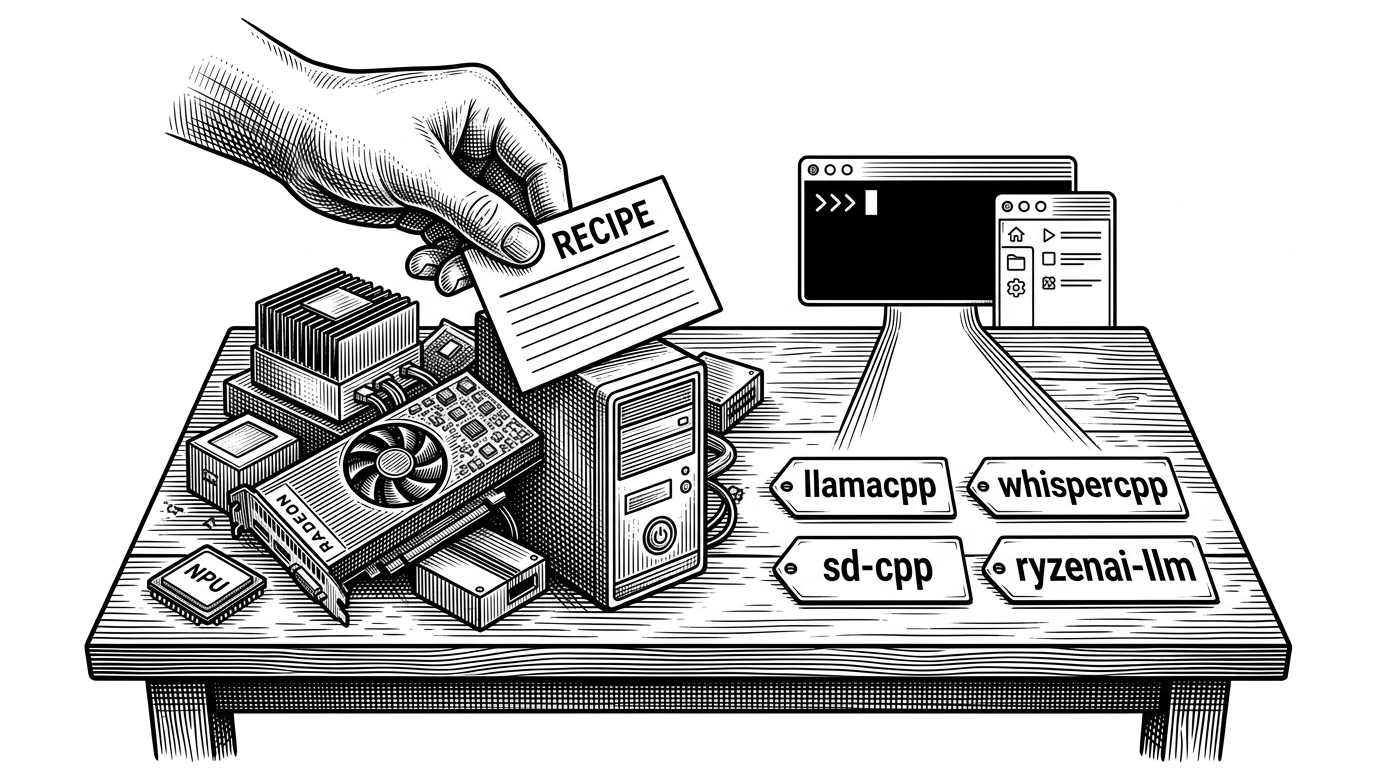
Lemonade SDK: The Recipe Layer for Local AI
How one open-source stack hides hardware chaos behind a single OpenAI-compatible interface, then routes work to the right NPU, GPU, or CPU backend automatically.
Local LLM Inference
h3.c: When SSD Becomes VRAM
A bare-metal MiniMax-H3 engine for Apple Silicon that streams huge model blocks, skips wasted recomputation, and turns terminal inference into an interactive workflow.
Local LLM Inference
NOOP: The WHOOP Clone That Treats Your Strap Like a Local Database
A reverse-engineered, local-first companion that pulls raw data over Bluetooth, scores recovery on-device, and only trims the strap when the bytes are safely stored.
Local LLM Inference
DFlash: The Repo That Lets an LLM Draft Its Next 16 Tokens in Parallel
By borrowing hidden-state signals from the target model, DFlash turns speculative decoding into a block-level system that is faster, lighter, and stranger than the usual one-token-at-a-time loop.
Local LLM Inference
gemma-tuner-multimodal: The MacBook Fine-Tuner That Refuses to Train Blind
A guided Apple Silicon stack for multimodal Gemma tuning, with hardware preflight checks, runtime model patches, and cloud-streamed data pipelines that keep local training honest.
Local LLM Inference
`jamesob/local-llm`: The Home Lab That Treats PCIe Like a Data Center
A deep dive into how one repo turns local LLMs into a hardware-first discipline, where interconnects, VRAM, and routing matter more than app-layer convenience.
Local LLM Inference
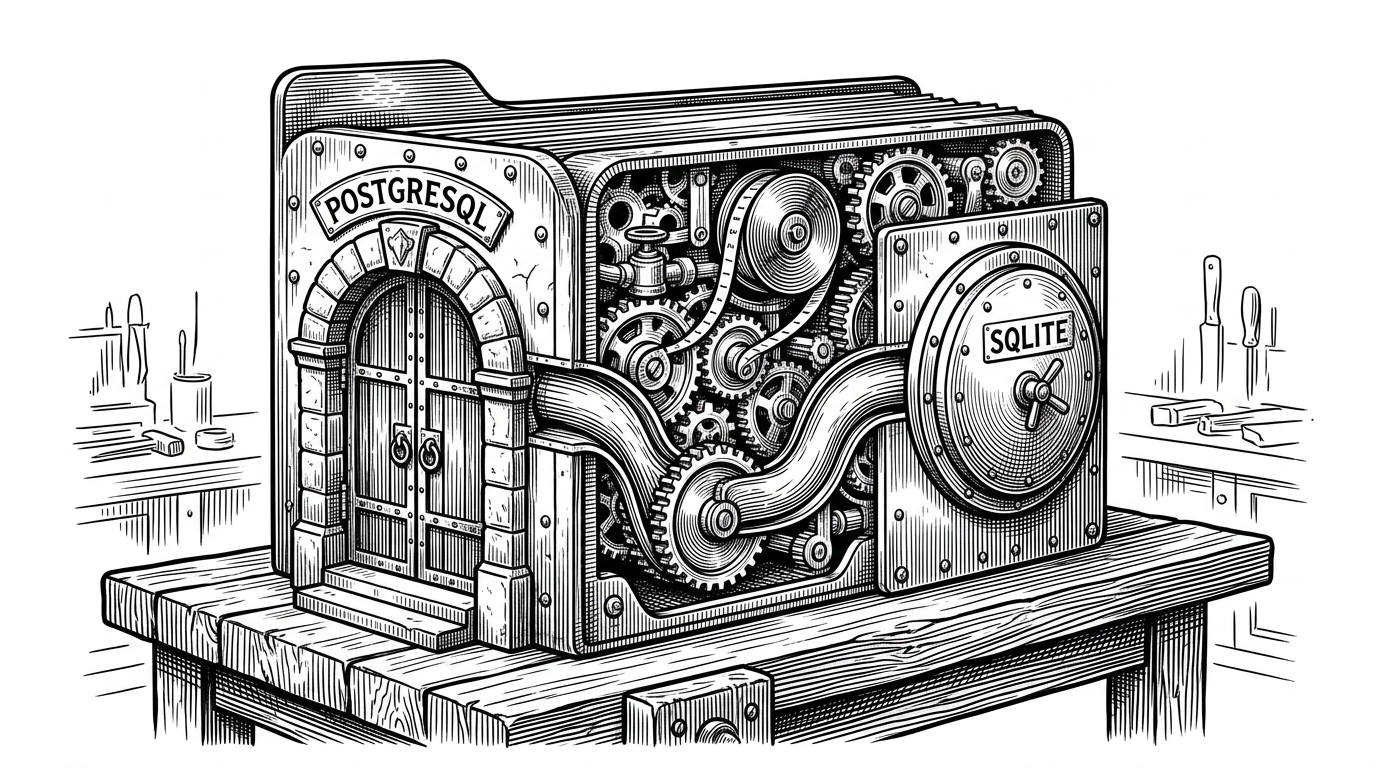
pgmicro: The Database That Speaks PostgreSQL and Sleeps Like SQLite
An embeddable Rust engine that parses real Postgres syntax, compiles straight to SQLite-style bytecode, and makes one file feel like two databases.
Local LLM Inference
TriAttention: The KV Cache Compressor That Reads Long Reasoning in the Frequency Domain
By inverting RoPE, calibrating Q/K statistics, and monkeypatching standard LLMs at runtime, TriAttention makes long-context reasoning fit on far smaller GPUs without rebuilding the model stack.
Local LLM Inference
dflash-mlx: Speculative Decoding Gets a Tape Recorder
A Mac-native DFlash engine that drafts tokens in blocks, verifies them losslessly, and rewinds hybrid model state without rebuilding everything from scratch.
Local LLM Inference
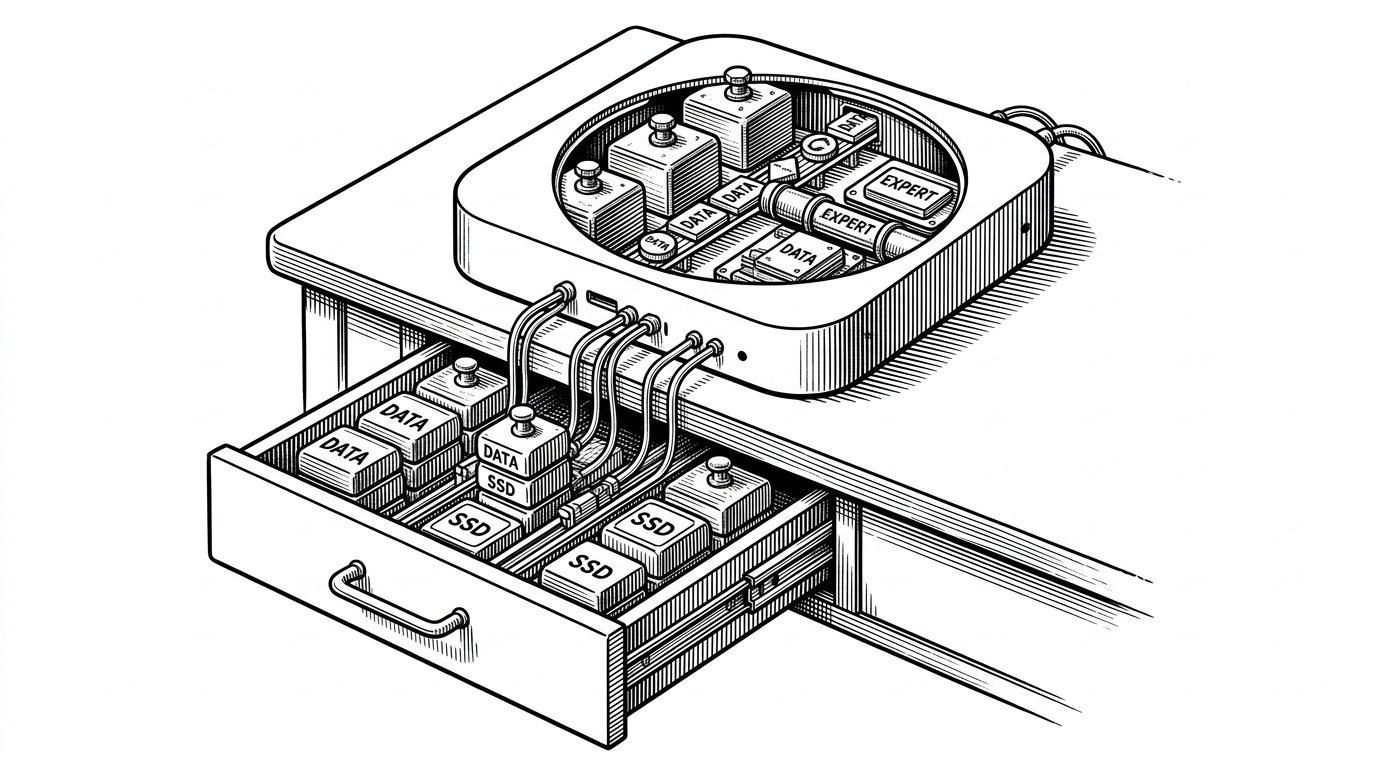
mac-code: The Mac SSD as RAM for Giant Local Models
A local coding agent that treats model weights, expert routing, and conversation memory as separate layers. The result is a small-Mac system that can run surprisingly large MoE models without surrendering to swap death.