Local LLM Inference
On-device inference, MLX, vLLM, local/offline AI serving, and Apple Silicon stacks
125 explainers
Local LLM Inference
Brain-Tumor-Detection: When a CNN Becomes a One-Click Medical Demo
A Flask front end, a pre-trained classifier, and a ZIP-bundled codebase turn MRI inference into a recruiter-friendly product. The interesting part is not just the model, but how the whole project is packaged to be understood instantly.
Local LLM Inference
pg-llm-usodb: The PostgreSQL Server That Makes Up Its Own Database
It speaks the wire protocol, fools real clients, and uses an LLM plus virtual state to fabricate tables, rows, and metadata on demand.
Local LLM Inference
healthtwin-ai: HealthTwin AI: The Health Simulator That Turns One Form Into Five Predictions
A fast, offline-first digital twin uses model translation, Monte Carlo forecasting, and SHAP-ranked advice to turn raw health data into something a person can actually act on.
Local LLM Inference
molecular-similarity-search: When Chemistry Becomes a Matrix Problem
A small Flask app that turns SMILES strings into fingerprints, fingerprints into HDF5, and similarity search into one fast NumPy operation.
Local LLM Inference
Plant-Disease-Detection: When a CNN Repo Becomes a Portable Plant Lab
A small Python project hides a bigger idea: sometimes the most useful open-source ML repo is the one that ships the data, the model, and the whole experiment in one place.
Local LLM Inference
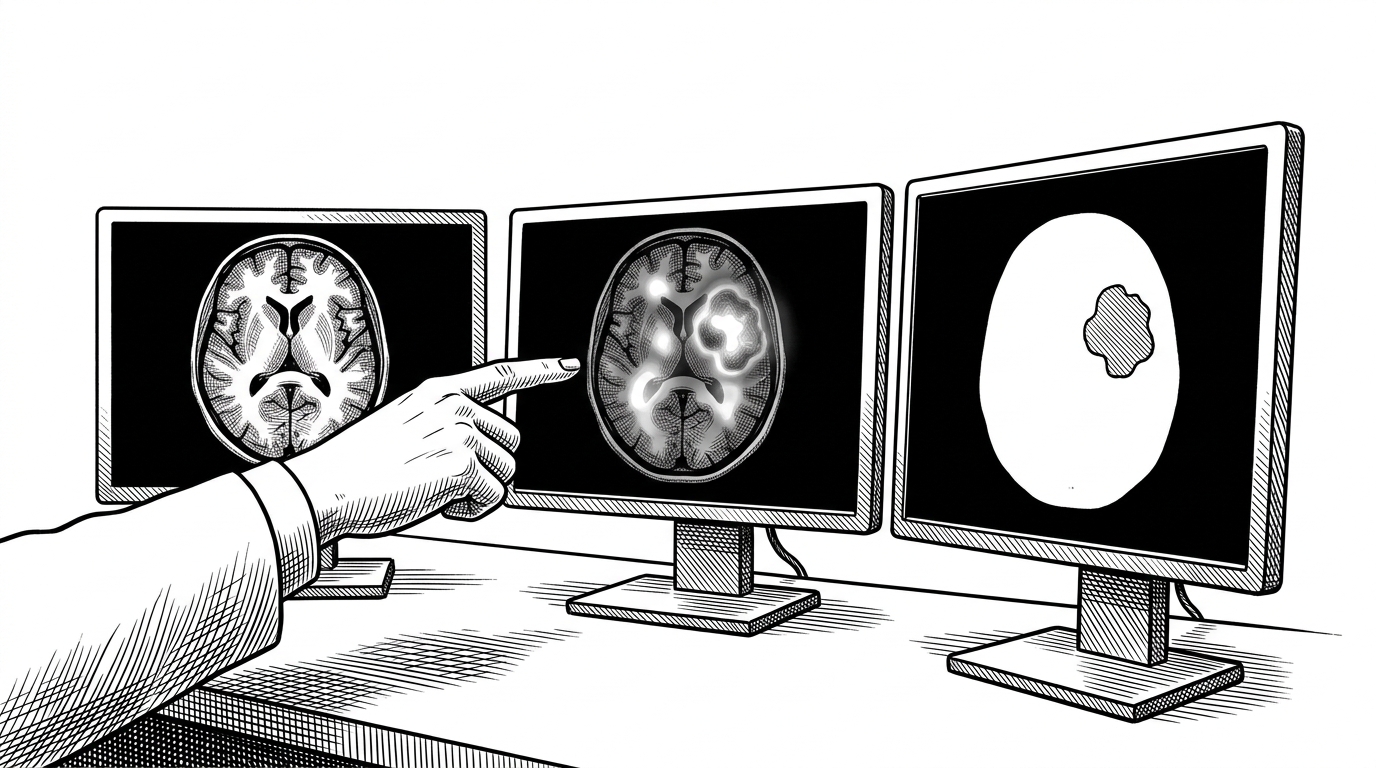
Brain_Tumor: A Tiny Medical AI That Tries to Explain Its Own Diagnosis
A three-stage pipeline combines classification, segmentation, and Grad-CAM so the model can say what it sees, where it sees it, and why it thinks the scan matters.
Local LLM Inference
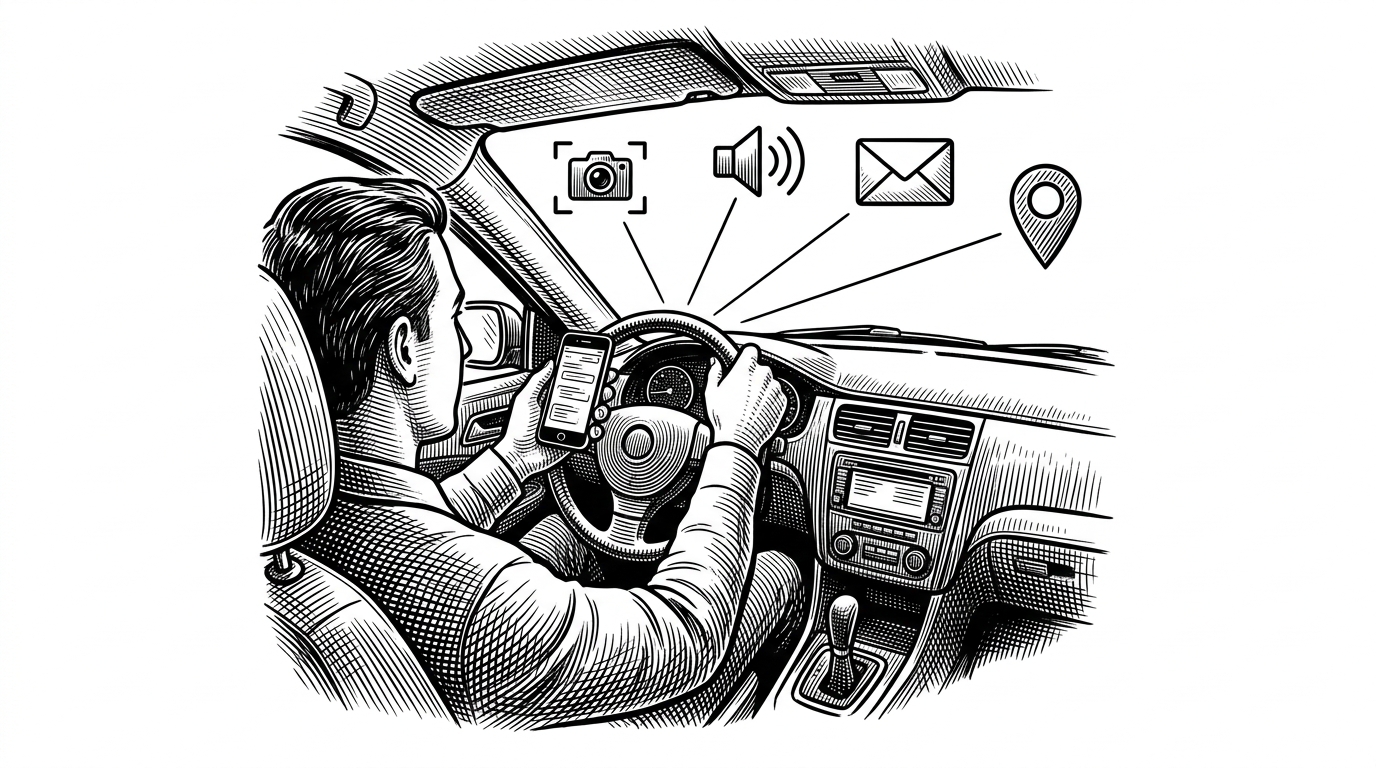
Distracted-Driver: The Open-Source Safety System That Turns a Webcam Into an Alarm Stack
A ResNet50 classifier is only the beginning. This repo shows the messy, revealing last mile of driver monitoring: live video, label smoothing, audio warnings, email alerts, and location lookup.
Local LLM Inference
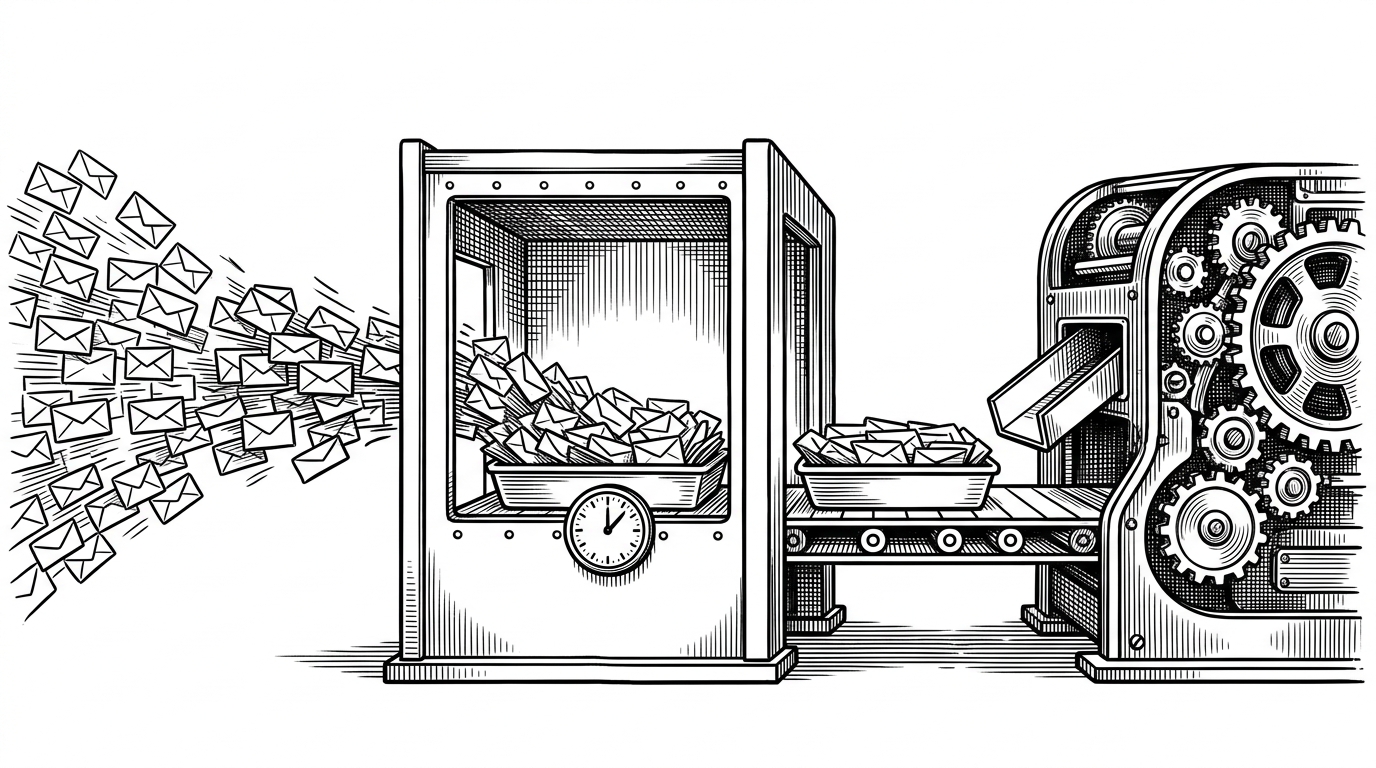
ml-inference-gateway: How Java Virtual Threads Turn ML Traffic Into Efficient Batches
A production-minded inference gateway that uses imperative code, adaptive batching, Redis rate limits, and gRPC resilience to squeeze more throughput out of ML systems without drowning in async complexity.
Local LLM Inference
Stock_Price_Prediction_Project: When a Forecast Gets Smoothed Before You See It
A small FastAPI and LSTM stock app that makes one pragmatic choice over and over: it blends raw model output with the previous close so the chart looks usable, not just literal.
Local LLM Inference
EV-Charging-Station-Predictor Turns City Maps Into Placement Math
A geospatial ML pipeline that reads OpenStreetMap like a satellite, learns from negative samples, and scores where EV chargers should go.
Local LLM Inference
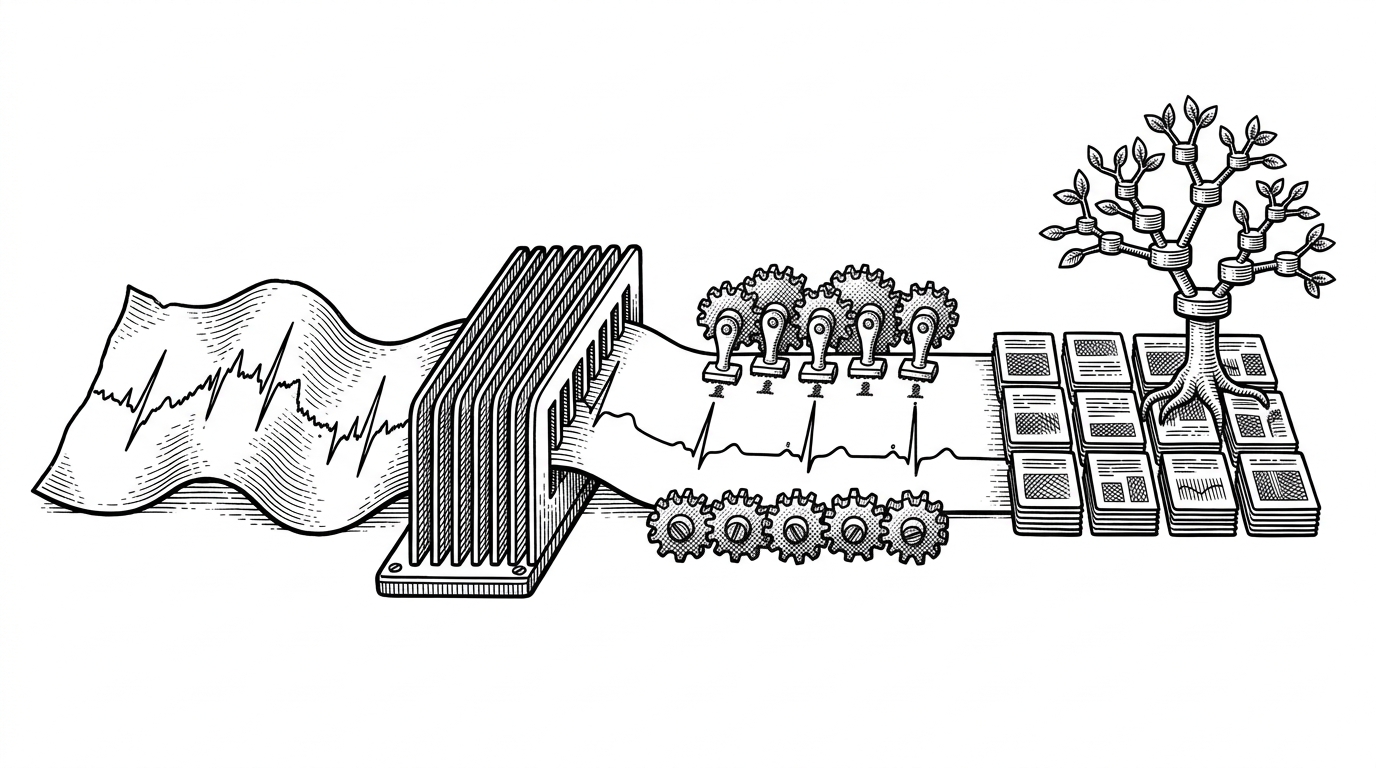
chhayaproject4: How a Heartbeat Becomes a Feature Table, Then a Prediction
A compact ECG notebook that turns noisy physiological signals into interpretable inputs for XGBoost, showing why medical AI often works better as engineering than as end-to-end magic.
Local LLM Inference
Finsight: Turning Financial Statements Into a Conversation
A focused open-source app that uses long-context Gemini to read dense PDFs, extract structure, and surface the kind of narrative insights finance teams actually want.
Local LLM Inference
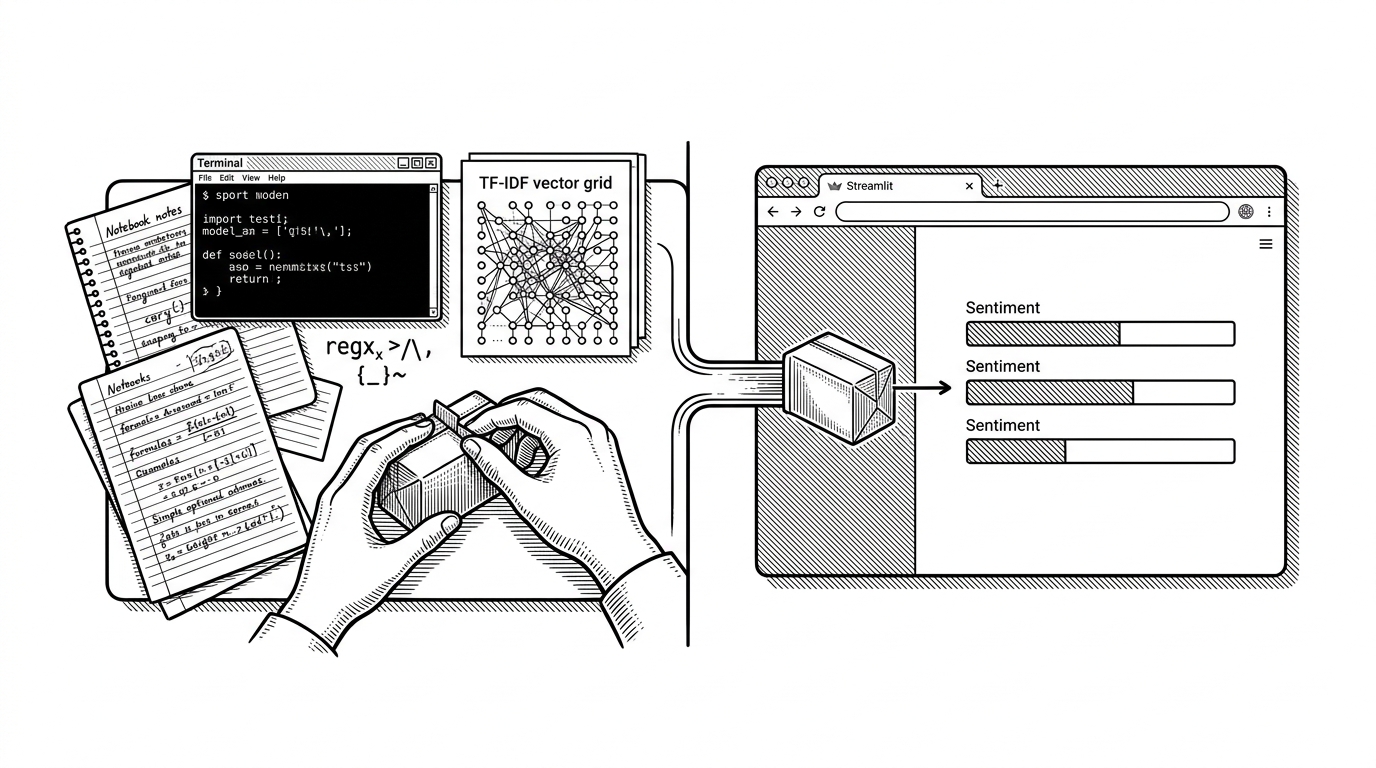
Sentiment-Analyzer: The Cleanest Part of This Repo Is Not the Model
A Streamlit sentiment app that shows how to turn notebook-era NLP into a shareable tool, with mirrored preprocessing, cached model loading, and a pragmatic workaround for large model files.
Local LLM Inference
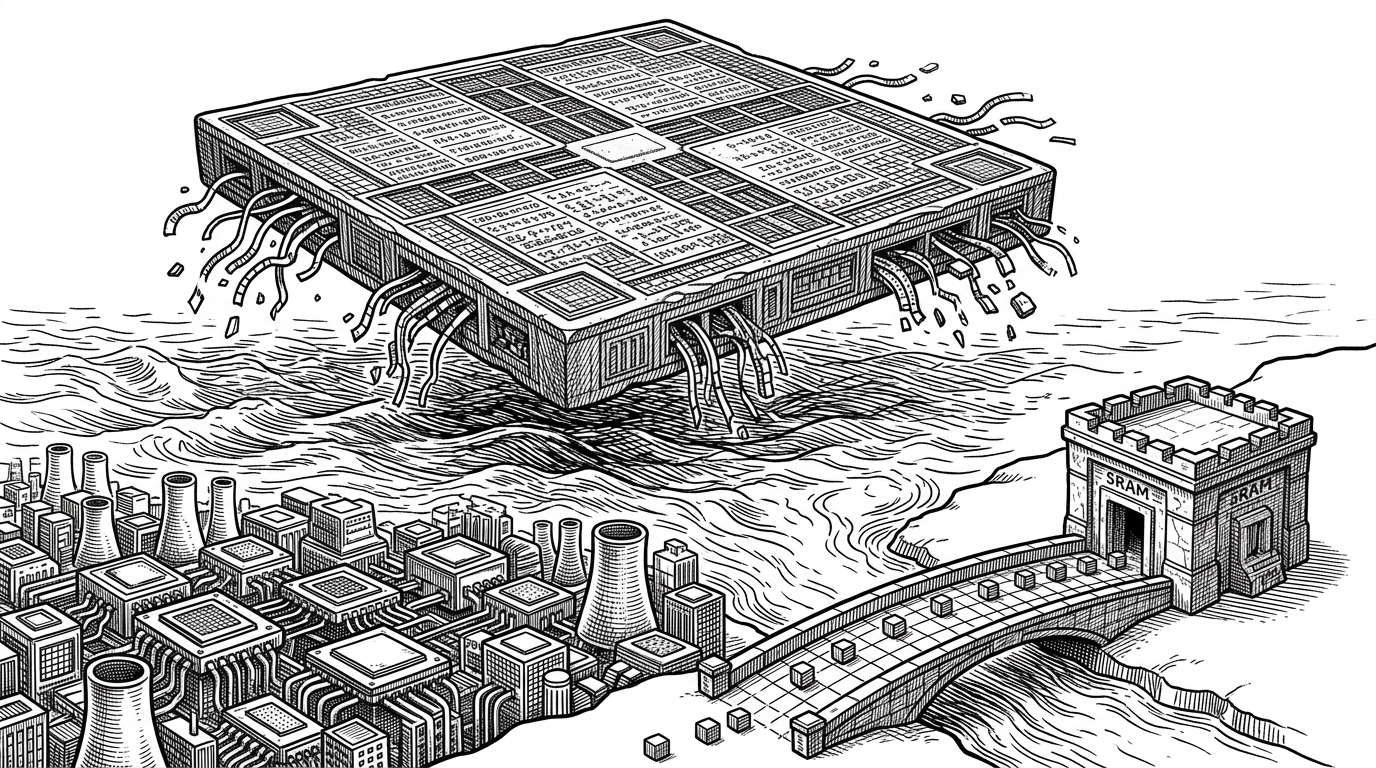
flash-attention: FlashAttention: The Algorithm That Beat the Memory Wall
How a tiled, IO-aware CUDA kernel turned exact attention into something GPUs can actually afford to run at scale.
Local LLM Inference
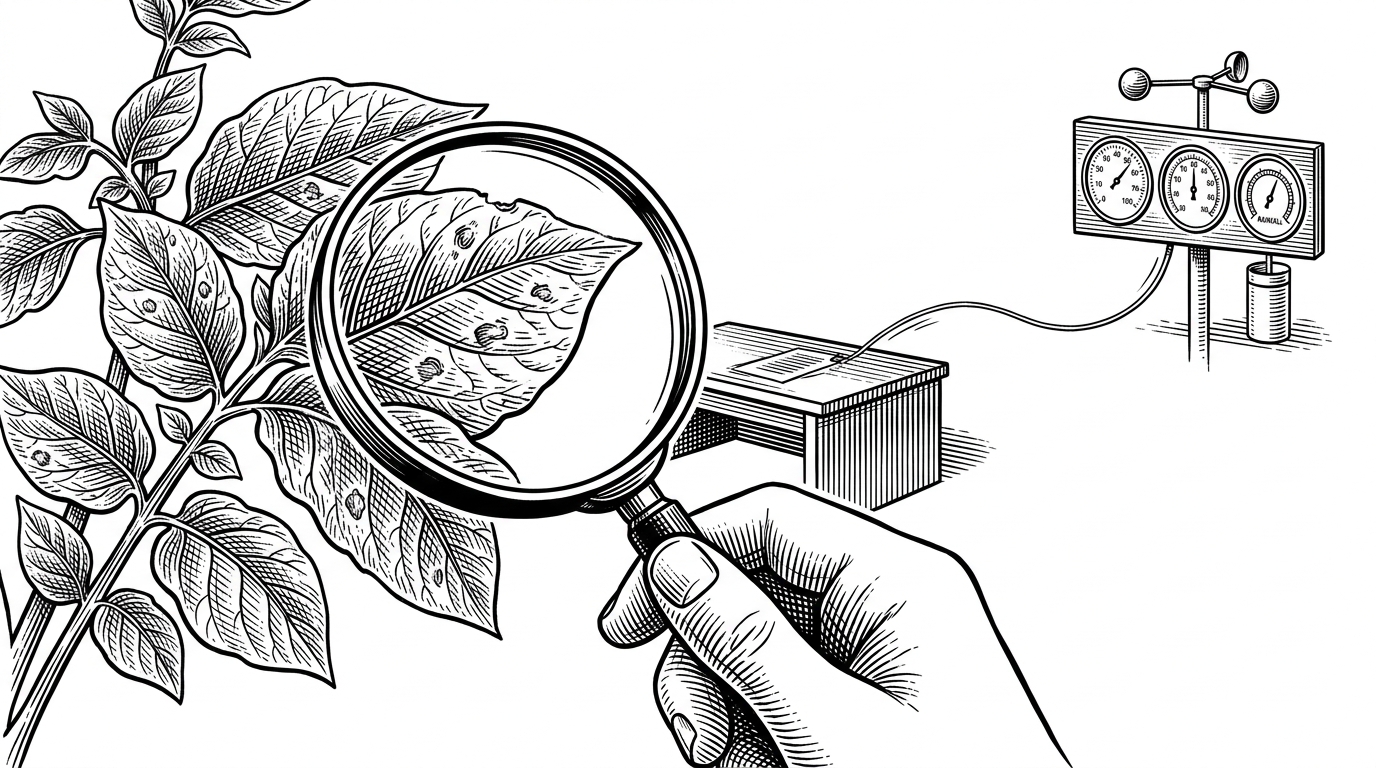
`potato-disease`: The Tiny CNN That Starts With a Leaf and Ends With the Weather
A notebook-built potato disease detector does more than classify spots. It hints at a next step where humidity, temperature, rainfall, and leaf texture all matter.
Local LLM Inference
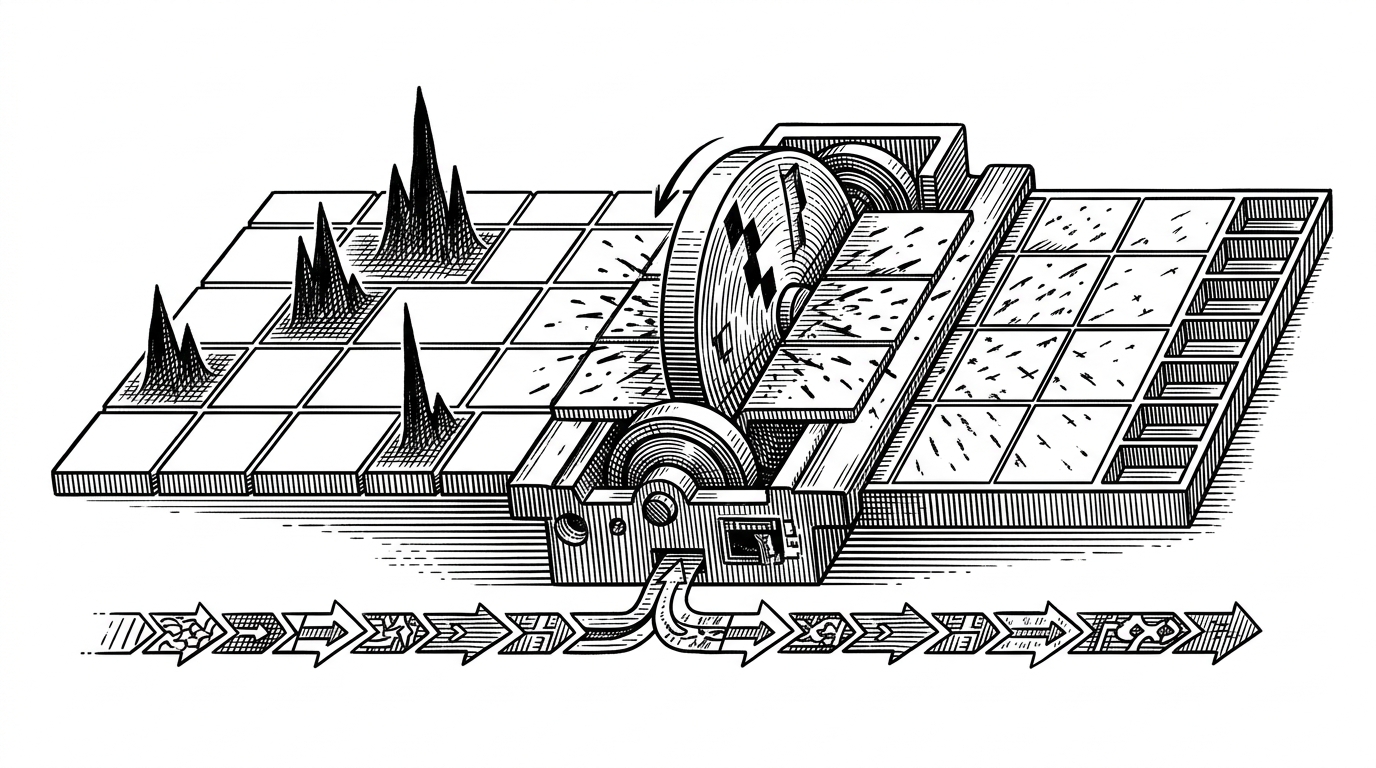
saw-int4: The Hadamard Trick That Makes 4-Bit KV Caches Work in Real Serving Systems
A system-aware quantization stack that rotates away KV outliers, keeps accuracy close to BF16, and treats inference speed as a kernel problem, not a paper abstraction.
Local LLM Inference
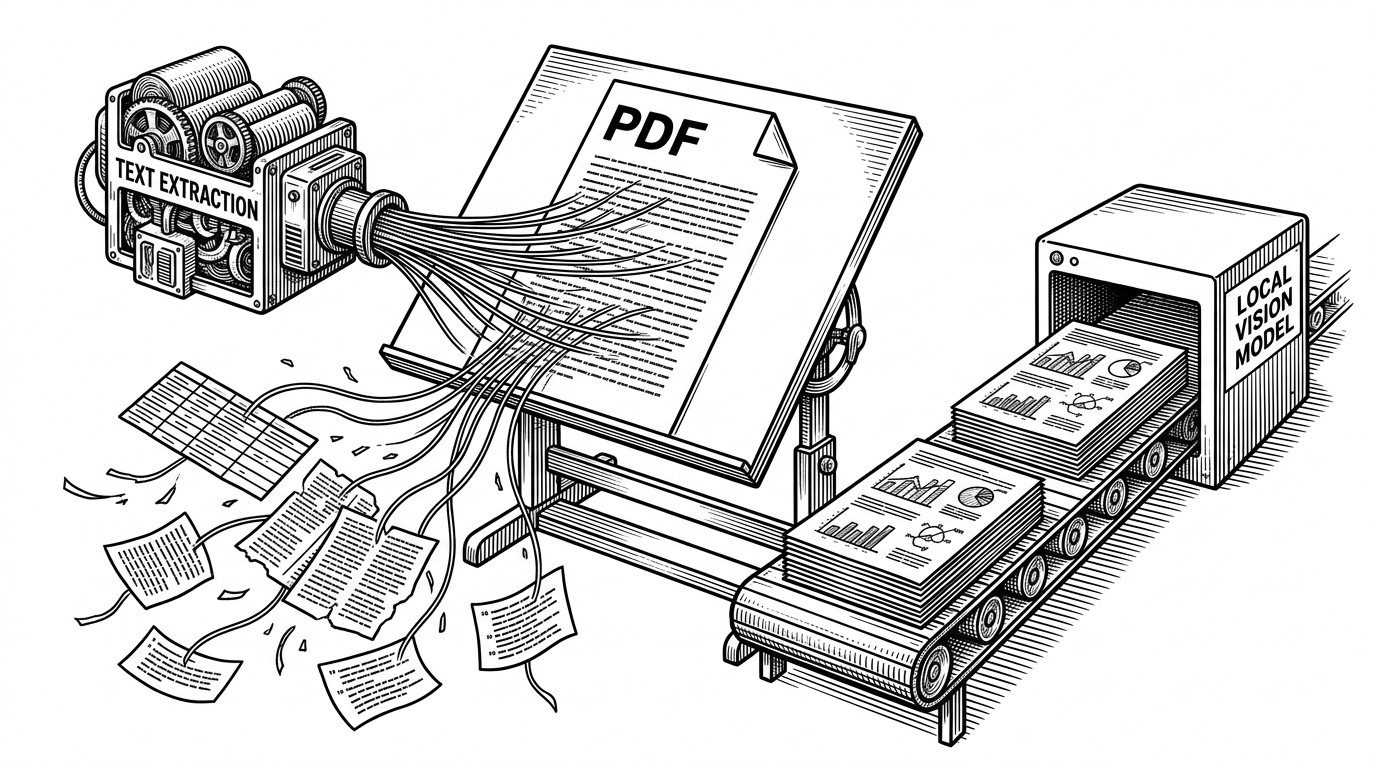
bulldra/local-llm-pdf-chat: Why This PDF Chat App Refuses to Extract Text
A local-first PDF assistant that treats documents as images, streams pages progressively, and lets MCP tools read them through an in-process FastAPI bridge.
Local LLM Inference
modelctl: The Rust CLI That Treats Local LLMs Like System Services
A thin, transparent manager for detached model servers, runtime adapters, and Apple Silicon telemetry.
Local LLM Inference
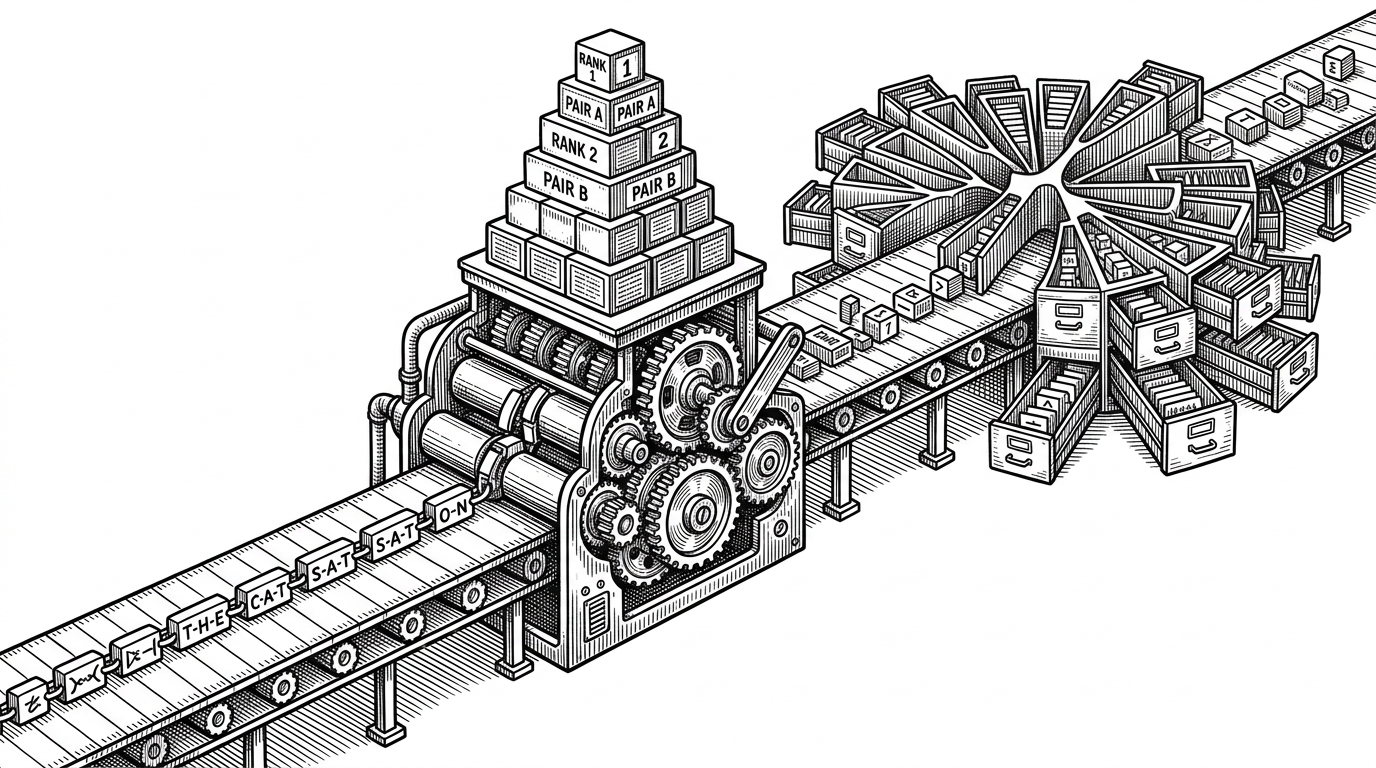
GPT-implementation: The Repo That Makes Tokenization the Main Character
A clean GPT-1 build in Python, but the real lesson is the tokenizer engine underneath it: heaps, linked lists, tries, and the kind of optimization most from-scratch projects skip.
Local LLM Inference
AISTATS_VESDE: The Diffusion Repo That Already Knows the Answer
By swapping a learned score network for a closed-form Gaussian mixture, this tiny research codebase turns sampler design into a test of discretization error, correction steps, and variance schedule choice.
Local LLM Inference
cog-official-openai-clip: The 12-Second Way to Ship CLIP
A production-minded wrapper around OpenAI’s multimodal model, where the real problem is not inference. It is getting a 3.4GB model to wake up fast, stay cached, and return useful embeddings through a tiny Cog API.
Local LLM Inference
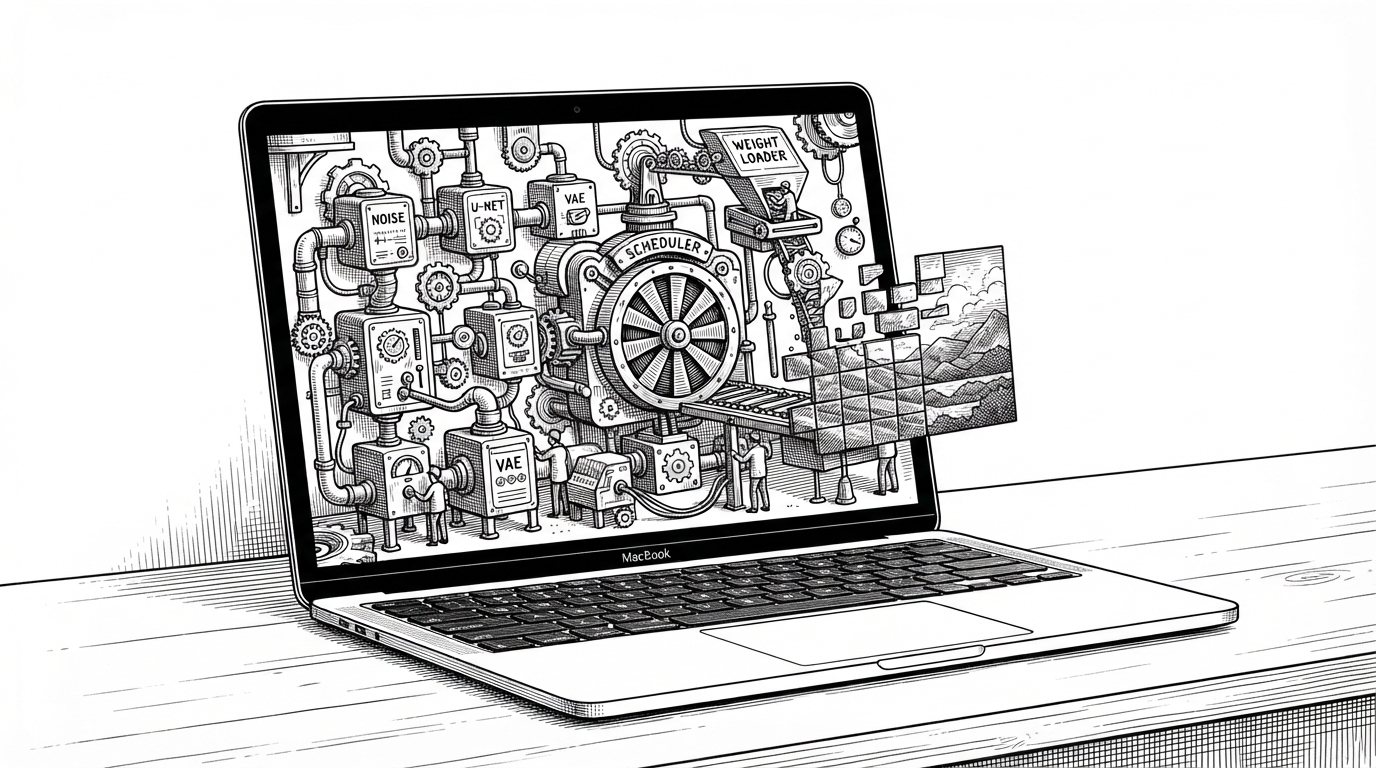
MFLUX: The MLX Rewrite That Makes FLUX Feel Native on Mac
A minimalist, Apple-Silicon-first image generation stack that trades framework bloat for readable code, low-RAM execution, and surprisingly deep support for modern diffusion workflows.
Local LLM Inference
The Invisible LLM: How tomsalphaclawbot/gemma4-local Turns Apple Silicon into an AI Daemon
By stripping away the chat UI and relying on shell scripts and macOS system services, this inference wrapper transforms massive Gemma 4 models into persistent, memory-safe background utilities.
Local LLM Inference
offline-llm-device-analysis: The Blueprint for the Offline AI Appliance
How a zero-dependency benchmarking suite uses capital efficiency to prove that the future of local LLMs belongs on cheap edge hardware, not in the cloud.
Local LLM Inference
The Paranoid Laboratory: Inside turboquant-t4-colab-lab
How a defensive, self-verifying notebook squeezes 128k context windows out of aging free-tier GPUs and survives the chaos of bleeding-edge LLM forks.
Local LLM Inference
The Anatomy of a Pixel: Deconstructing chenglou/diffusion
How a frontend pioneer stripped Denoising Diffusion Probabilistic Models down to a single PyTorch file.
Local LLM Inference
Beyond the Notebook: Engineering On-Device Intelligence with hgayan7/Tutorials
A masterclass in bridging the gap between raw ML models and the disciplined architecture of production-ready Android apps.
Local LLM Inference
The Spreadsheet-Powered Face: Dissecting Face-Recognizer
How an unusual weight-loading strategy turns a complex Inception network into a transparent, educational anatomy lesson.
Local LLM Inference
oMLX: The SSD-Backed Memory Tier for Apple Silicon
How a native macOS inference server uses tiered KV caching and continuous batching to eliminate the "Cold Start" problem for local agents.