Local LLM Inference
On-device inference, MLX, vLLM, local/offline AI serving, and Apple Silicon stacks
125 explainers
Local LLM Inference
claude-code-local: The Proxy That Lets Claude Code Run Entirely on Your Mac
A local MLX server impersonates Anthropic’s API, rewrites tool calls, reuses prompt cache, and turns Claude Code into a privacy-first Mac-native coding stack.
Local LLM Inference
mlxstudio: MLX Studio: The Local AI App That Tries to Replace Your Cloud Model Stack
A native macOS wrapper around vMLX, MLX Studio turns Apple Silicon into a polished local AI workstation with chat, image generation, tool calls, and API compatibility that can stand in for cloud endpoints.
Local LLM Inference
The CPU Strikes Back: Unpacking huggingface/optimum-intel
How a single boolean flag hides a massive C++ compiler, turning standard processors into viable LLM inference engines.
Local LLM Inference
OpenMythos: The Transformer That Thinks by Looping the Same Brain
A theoretical recurrent-depth architecture that treats depth as a runtime choice, stabilizes recurrence with control-theory logic, and uses halting plus shared weights to make inference feel like adjustable thought.
Local LLM Inference
rvLLM: The Inference Engine That Lets TPUs Compete by Writing Less Kernel Code
A deep dive into the project that pairs Rust orchestration, handcrafted CUDA, and a flat JAX scan to turn Gemma 4 inference into a compiler problem instead of a kernel-burden problem.
Local LLM Inference
Filtlong: The Long-Read Filter That Lets Short Reads Decide What Is Real
A small C++ tool with a big idea: score noisy Nanopore and PacBio reads against length, quality, and optional reference evidence, then keep the parts most likely to help assembly.
Local LLM Inference
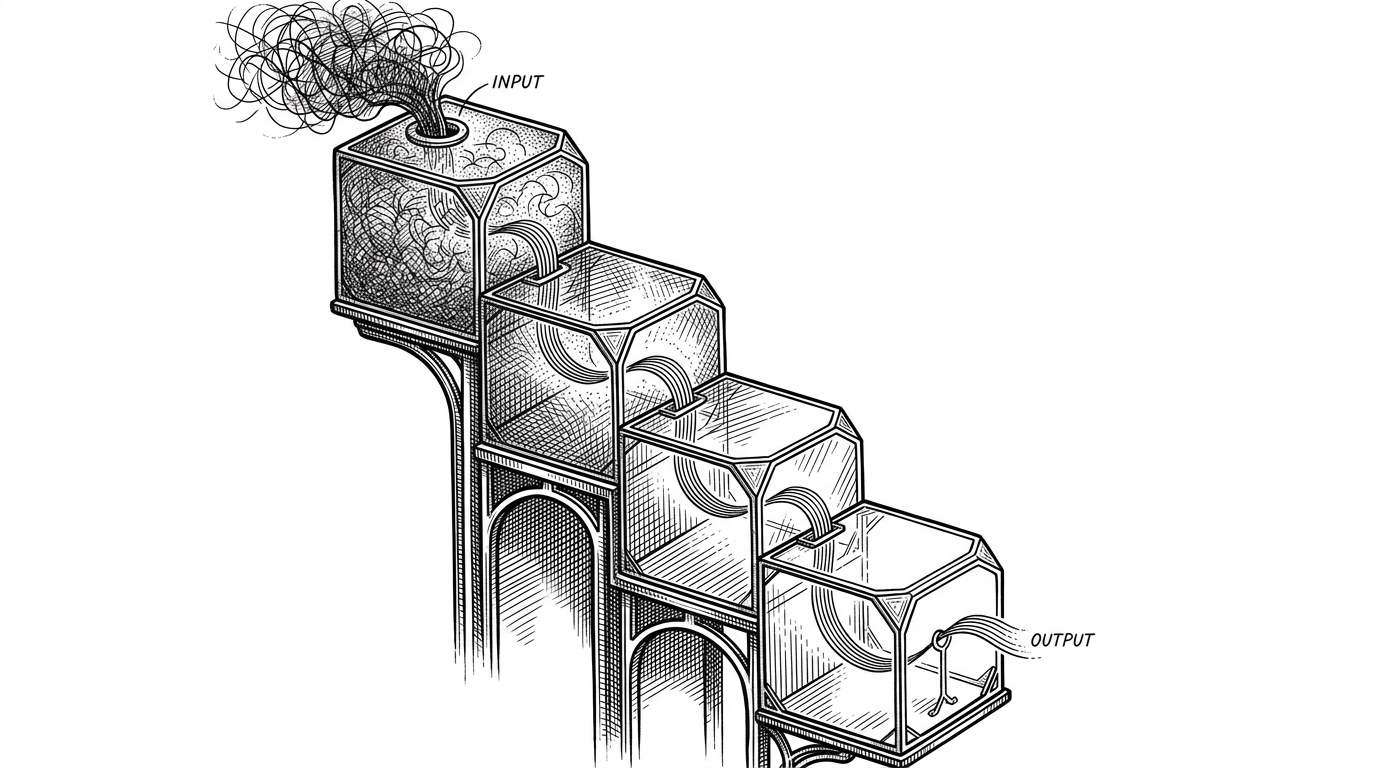
DiffusionBlocks: When Transformer Depth Becomes a Noise Schedule
This research repo treats training as denoising, splits ViT into independently trainable blocks, and uses diffusion math to rethink the memory wall.
Local LLM Inference
ArtSpew: The Prompt Is the Experiment
Inside a Stable Diffusion engine that injects random tokens, chases visual accidents, and uses extreme throughput to make discovery feel immediate.
Local LLM Inference
Inside `google-research/flood-forecasting`: How Google Built a Flood Model for Broken Data
A deep dive into the code behind FloodHub, where basin embeddings, masked feature aggregation, and probabilistic outputs keep river forecasts useful even when the inputs are incomplete.
Local LLM Inference
SakanaAI/sparser-faster-llms: How TwELL Makes Sparse Transformers Run Like They Were Built for Hopper
A deep dive into the repo that couples activation sparsity with H100-tuned CUDA kernels, so the model’s zeros become real speed, lower memory use, and lower energy.
Local LLM Inference
DroPE: The LLM Context Trick That Works Better After You Drop the Map
Sakana AI’s repo extends pretrained models by removing positional embeddings, then recalibrating just enough to unlock longer context windows without brute-force long-context fine-tuning.
Local LLM Inference
nvalchemi-toolkit: The Chemistry Stack Built Like a GPU Queue
NVIDIA’s ALCHEMI toolkit treats atomistic simulation as a live pipeline, with inflight batching, composable stages, and model wrappers that keep GPU work flowing.
Local LLM Inference
Bypassing the ROCm Trap: Inside ZINC
How a Zig-based inference engine uses Vulkan to turn consumer AMD graphics cards into production-grade AI servers.
Local LLM Inference
RePo teaches LLMs to rearrange their own context
Sakana AI’s open-source stack turns token order into a learnable layer. The payoff is strongest when the input is messy, the signal is uneven, and rigid sequence order gets in the way.
Local LLM Inference
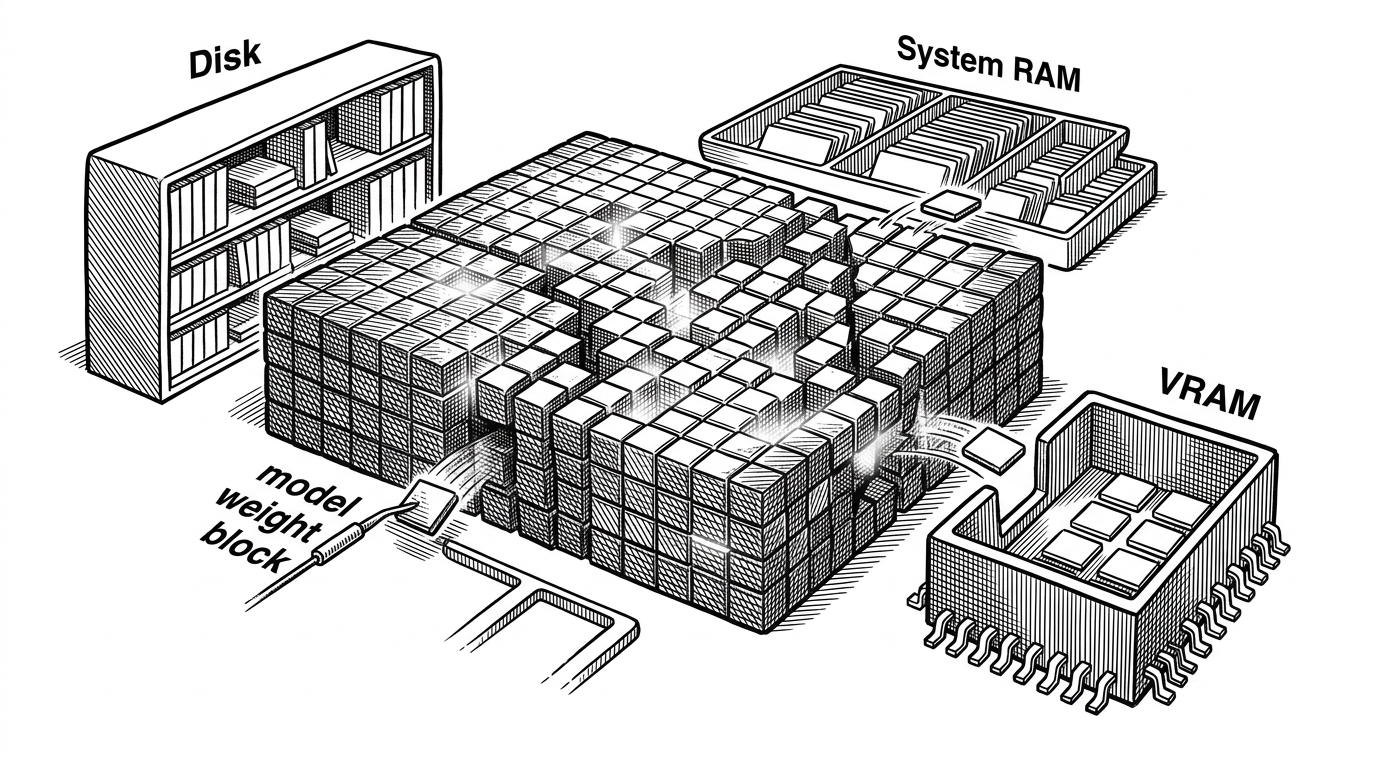
ComfyUI-MemoryVisualization: Turning VRAM Into a Live Map of Model Residency
A real-time ComfyUI diagnostic tool that shows not just how much memory is used, but which model pages are actually sitting in GPU memory, how they move, and why OOM bugs become visible.
Local LLM Inference
Swirl-Jatmos: The Atmospheric Simulator That Lets JAX Do the MPI
A TPU-first Python framework for 3D weather physics, where sharding, pressure solves, and checkpoints are handled as compiler-aware infrastructure, not hand-built cluster code.
Local LLM Inference
rvllm-serverless: The thin wrapper that makes a Rust LLM engine feel instant
A Python shell, a baked-in model layer, and a health-gated startup loop turn rvLLM into a serverless endpoint without dragging in a heavy serving stack.
Local LLM Inference
Evading the PyTorch Dependency Tax: Inside chroma-core/onnx-embedding
How the ChromaDB team stripped a massive Transformer down to its bare mathematical essentials to build a frictionless, zero-config vector database.
Local LLM Inference
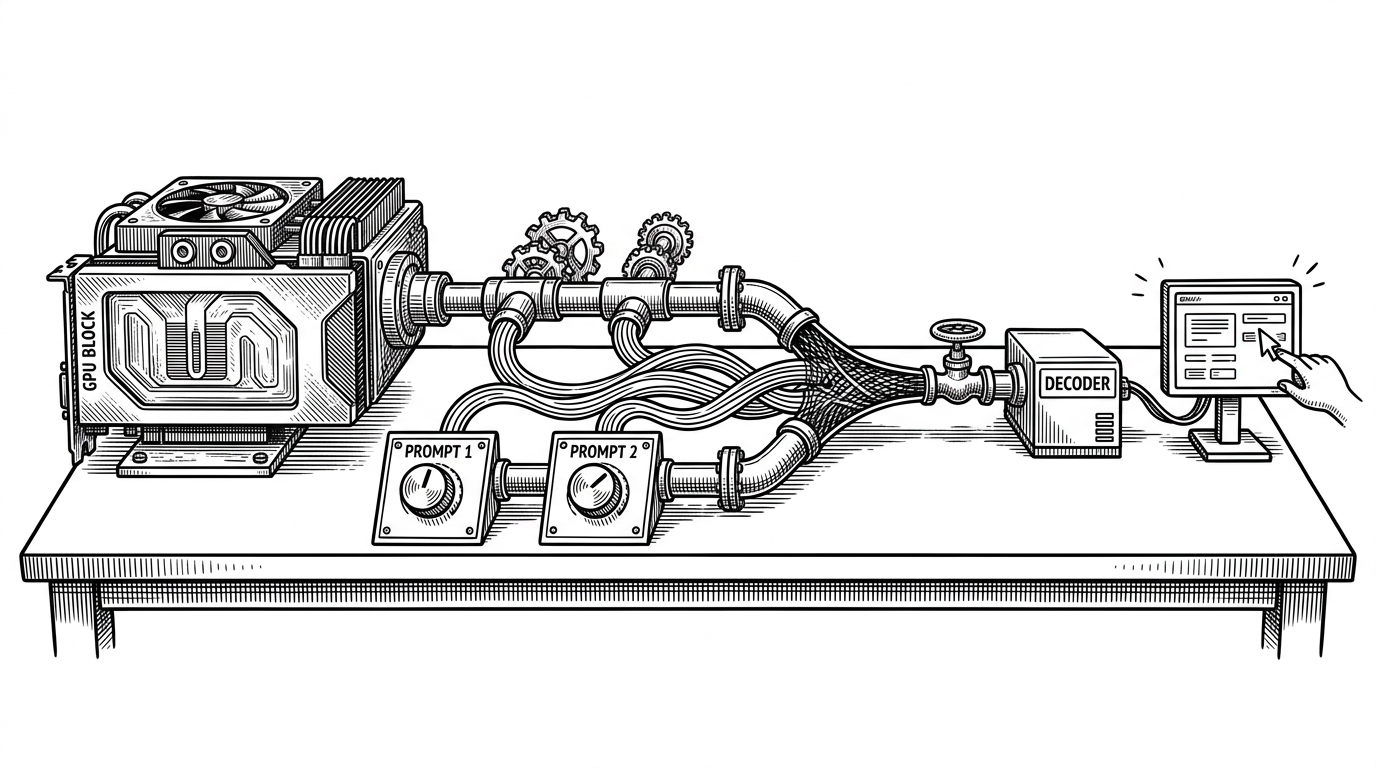
sdzoom: The Stable Diffusion Testbed That Treats Your Desktop Like a Bottleneck
A lean Latent Consistency Model playground that swaps waiting for live prompt blending, tiny autoencoding, and ruthless performance hacks.
Local LLM Inference
TNCO: The Tensor Optimizer That Makes Impossible Problems Fit
A hybrid Python and C++ engine that searches contraction trees, uses simulated annealing, and slices giant tensor networks into exact pieces when memory is the wall.
Local LLM Inference
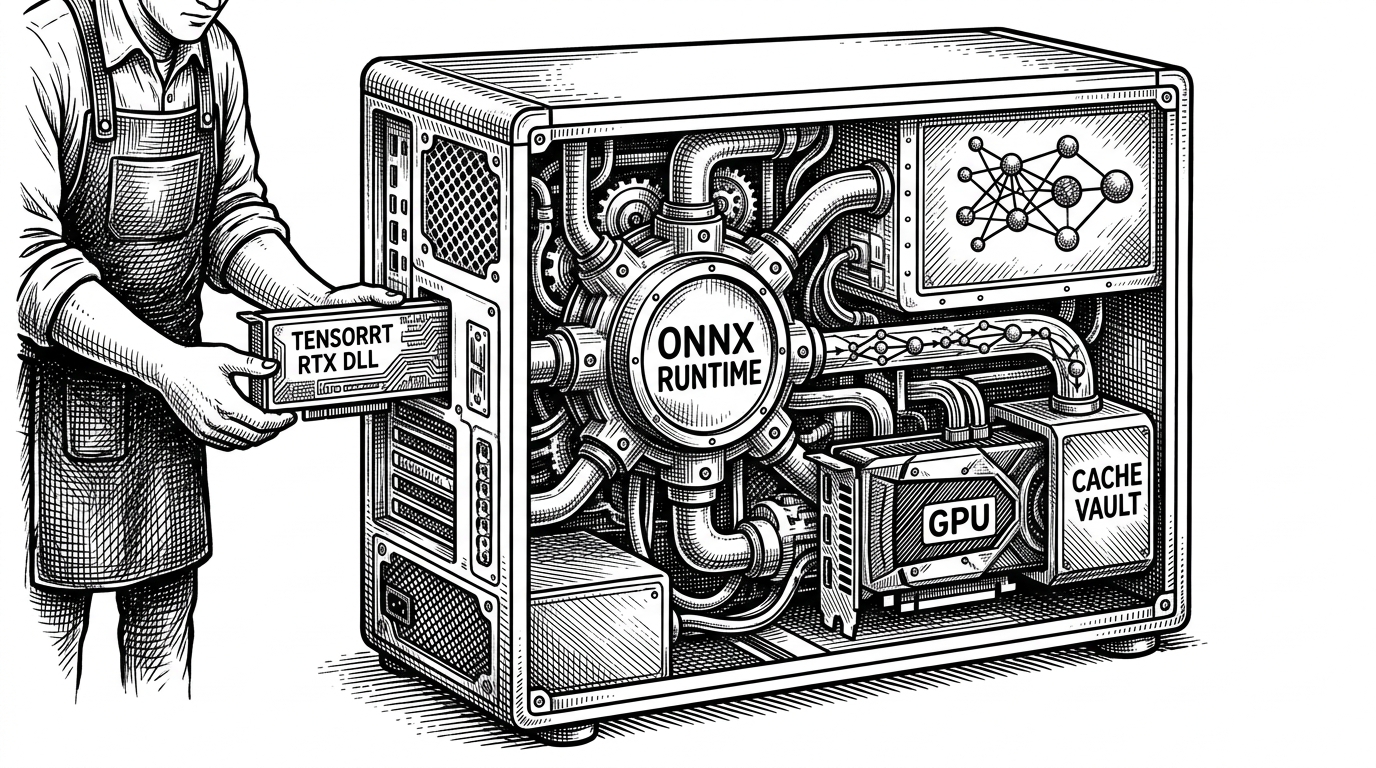
TensorRT-RTX-EP-ABI: NVIDIA TensorRT RTX Execution Provider: The Plugin That Turns ONNX Runtime Into a Hardware Socket
A deep look at how NVIDIA split high-performance RTX inference out of the monolith, using ORT’s EP ABI, adaptive JIT compilation, and GPU memory tricks to make desktop deployment feel surprisingly modular.
Local LLM Inference
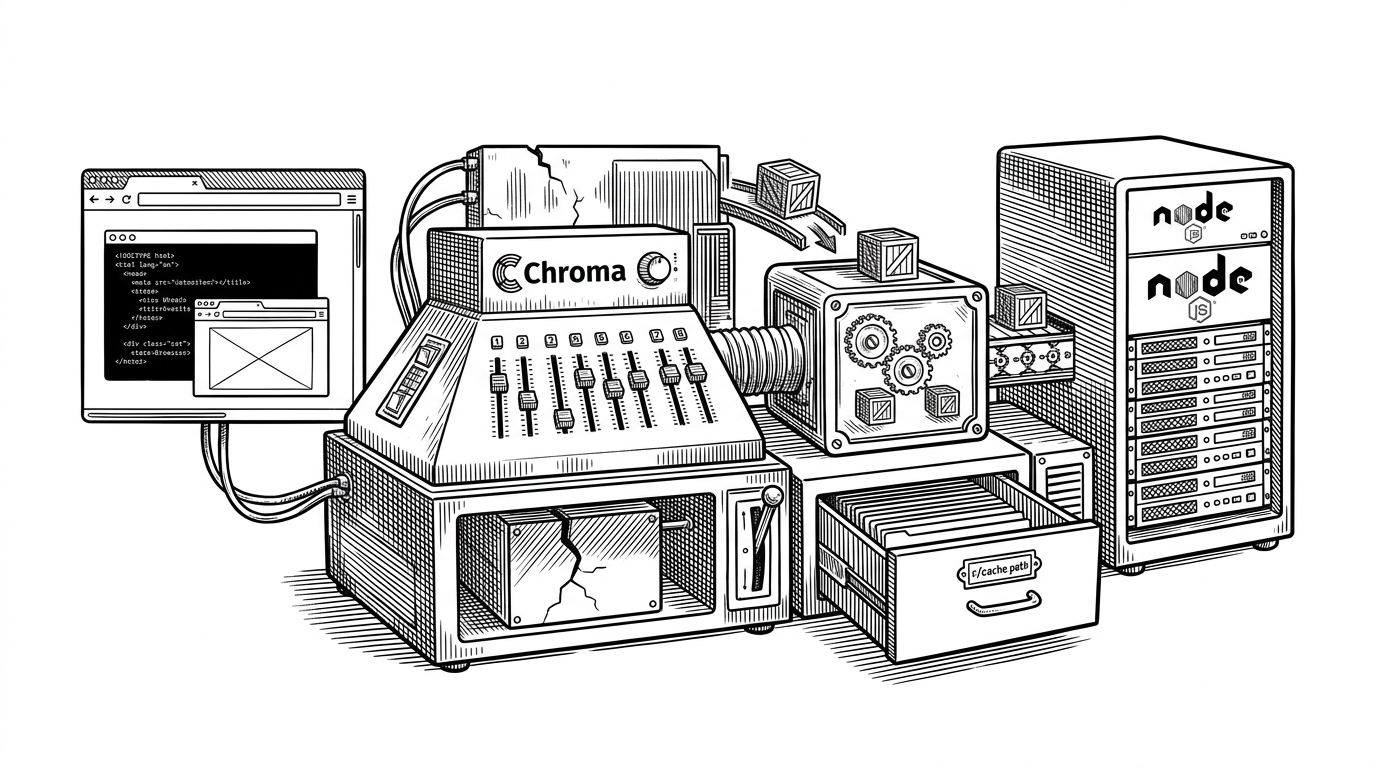
`chromadb-default-embed`: The Fork That Makes Embeddings Feel Native in JavaScript
A zero-config, isomorphic embedding engine that hides model loading, tokenization, and backend fallbacks behind one Chroma-friendly default.
Local LLM Inference
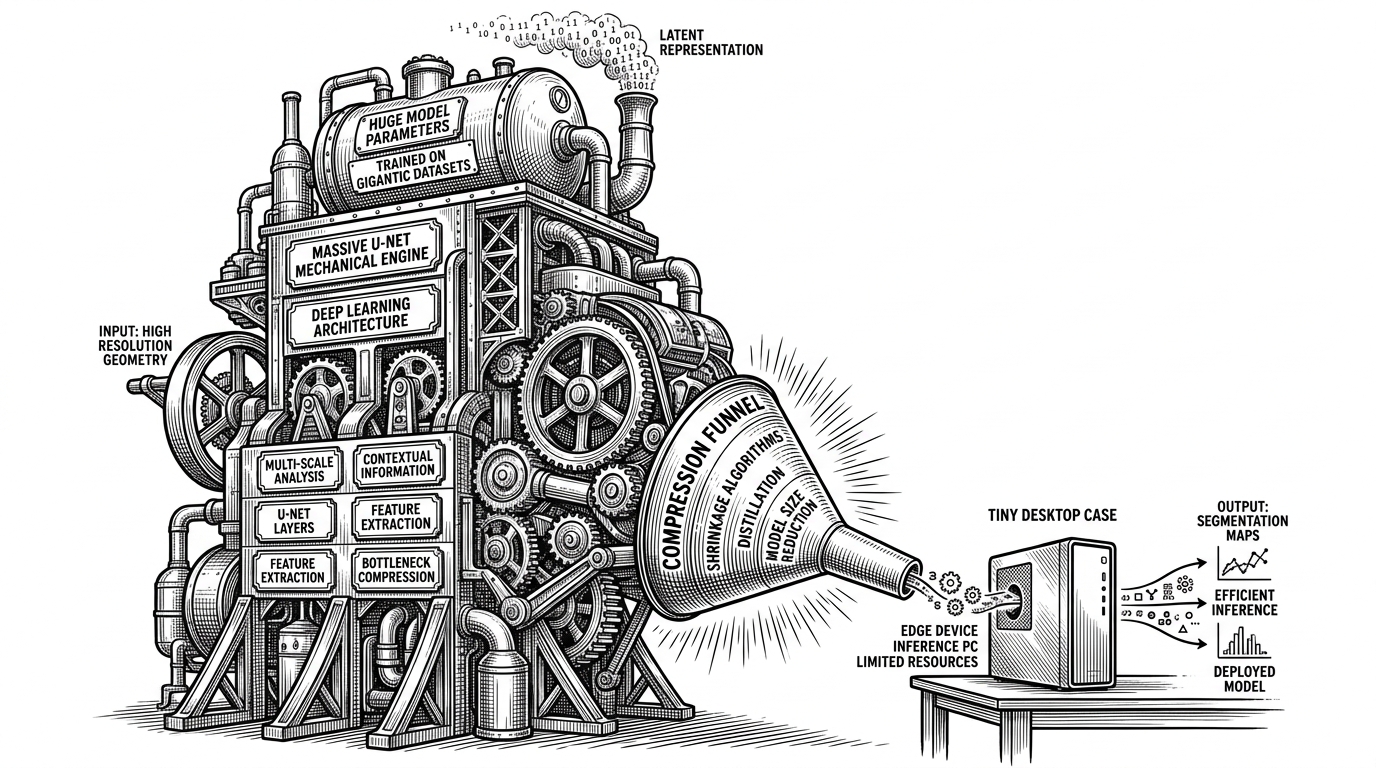
Aozora_SDXL_Training: Aozora: The 12GB VRAM Miracle for SDXL
How custom optimizers and "sliding window" memory management brought professional-grade diffusion fine-tuning to the consumer desktop.
Local LLM Inference
KVTC: The Open-Source KV Cache Codec That Treats LLM Memory Like Media
A RoPE-aware compression pipeline uses PCA, adaptive bit allocation, and entropy coding to shrink transformer memory without treating every token like it deserves full precision.
Local LLM Inference
EconoJax: The Economic Simulator That Trades 2D Worlds for GPU Speed
A JAX-native rework of the AI Economist that strips away spatial clutter, vectorizes the whole world, and turns taxation research into something you can actually iterate on.
Local LLM Inference
replicate/qwen-image-lora-trainer: The End of the Trigger Token
A deep dive into the trainer that turns Qwen-Image personalization into plain-English prompt engineering, and what that reveals about modern LoRA workflows.
Local LLM Inference
Aura: the local AI repo that keeps a pulse
A deep dive into an Apple Silicon agent that steers affect in the residual stream, runs a 1 Hz heartbeat, and treats memory like an organism.
Local LLM Inference
UnifiedTask: The Sigmoid Gate That Lets One Model Borrow Another’s Skill
A tiny Python package turns capability transfer into selective weight surgery, so a model can import a new behavior without flattening what it already knows.
Local LLM Inference
Skulk: The Local AI Cluster That Plans for Failure
A hard-forked Mac inference stack that pools memory, survives master loss, and keeps token flow coherent across a messy local network.
Local LLM Inference
local-image-search: The High-Performance Private Eye for AI Agents
How an MLX-powered MCP server turns Apple Silicon into a local vector warehouse, giving Claude secure access to your photo library without a single pixel leaving your machine.
Local LLM Inference
The Zero-Trust Bridge for Giant Models: Inside hf-mount-encrypted
How a high-performance Zig engine and the AEGIS cipher are turning Hugging Face repositories into secure, lazy-loaded local drives.
Local LLM Inference
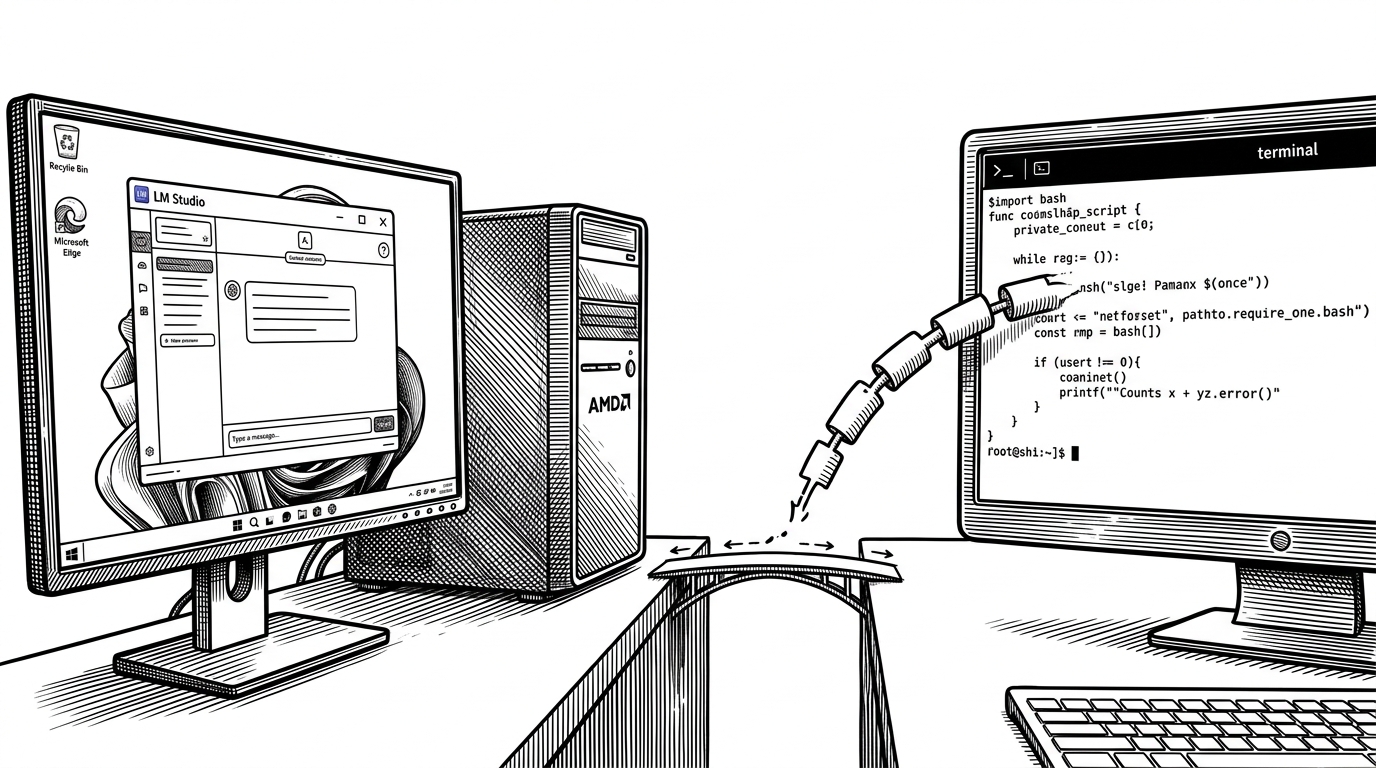
quickstartclaw: The One-Script Bridge Between WSL2, AMD GPUs, and a Local OpenClaw Agent
A Bash orchestrator that finds the Windows host, enables the right Linux plumbing, and turns a painful multi-step agent setup into a local workflow that feels nearly plug-and-play.
Local LLM Inference
The SQLite Moment for Vector Search: Inside chroma-android
How a raw JNI bridge and a Rust core are bringing privacy-preserving AI memory directly to the mobile edge.
Local LLM Inference
`generalized-pde-emulator`: The Neural Operator That Reads the Equation
Google Research turns PDE coefficients into a control signal, then uses FiLM, spectral layers, and physics-informed losses to push one model across held-out parameters and even new equation families.
Local LLM Inference
inference-mirror: The GPU Document Factory Behind marker
Datalab's wrapper turns PDF-to-Markdown into a parallel pipeline, splitting big documents across workers, sharing GPU capacity efficiently, and reassembling structured output at the end.
Local LLM Inference
masked-text-diffusion: Escaping the DOM: Inside chenglou/pretext and the Userland Text Rebellion
How a two-phase architecture severed text measurement from the browser's synchronous layout cycle, unlocking high-performance typography for custom renderers.
Local LLM Inference
ike: Sakana AI’s Modular Shell Around DeepSpeed
A closer look at the framework that turns distributed LLM training into a plug-in architecture for data, loss functions, configs, and checkpoints.
Local LLM Inference
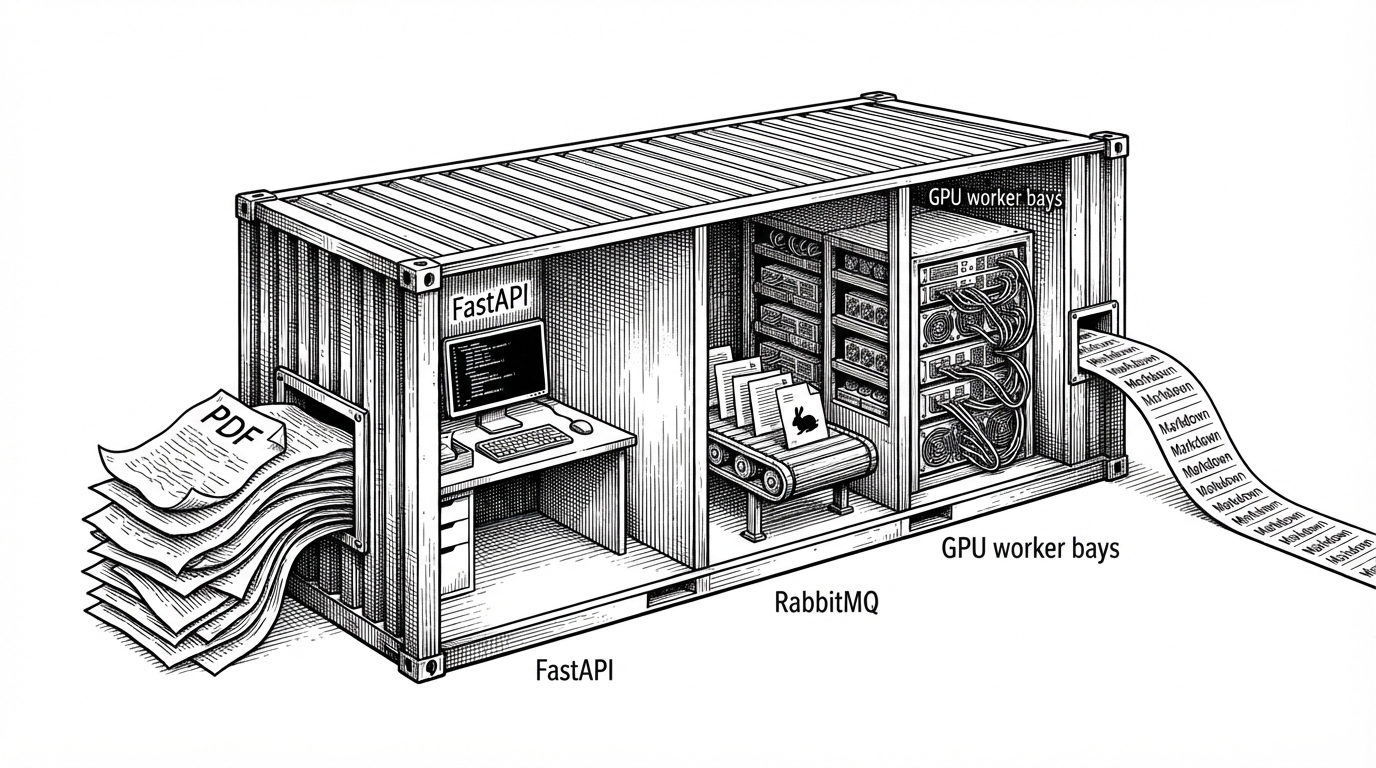
datalab-to/oss_container: The One-Container Cluster That Turns PDFs Into Markdown at GPU Speed
A FastAPI front end, RabbitMQ queue, and GPU workers all live inside one image, with chunking and merge logic that make large document conversion feel parallel, predictable, and self-hosted.
Local LLM Inference
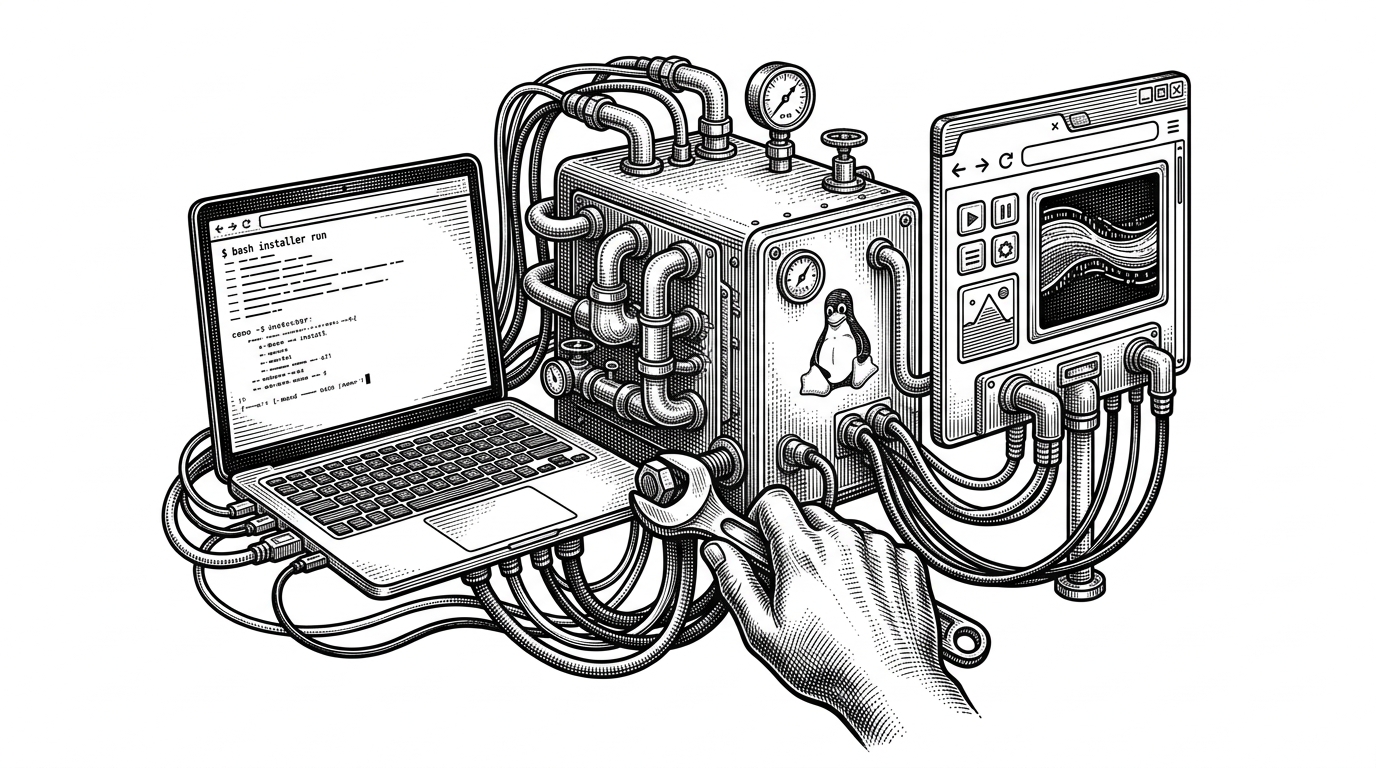
lemonclaw_bash: The One-Command Stack That Turns a Linux Box Into a Local AI Agent
A tiny Bash installer quietly does the hard work of wiring up inference, browser control, context management, and model lifecycle cleanup so OpenClaw can behave like a real local operator.
Local LLM Inference
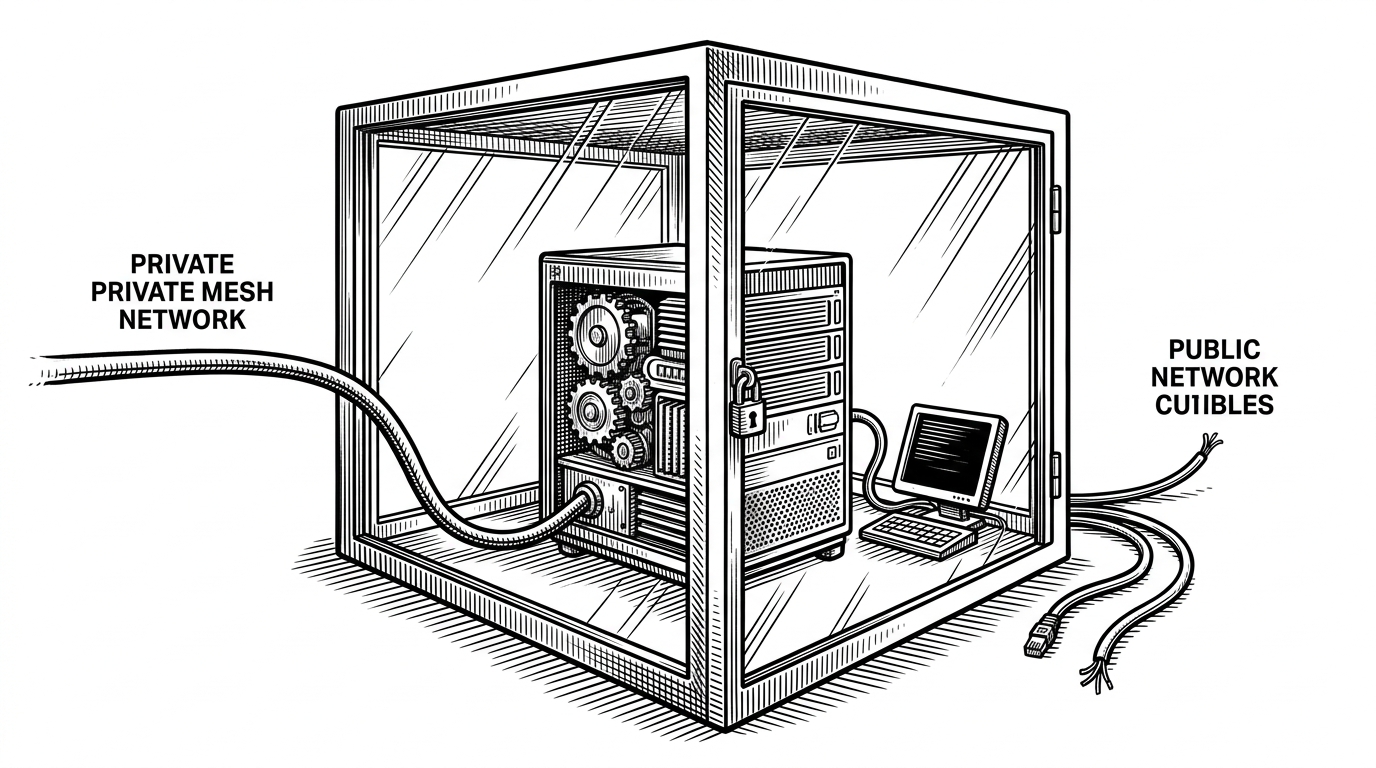
dgx-serve-vllm-gemma4: A private Gemma 4 server that behaves like infrastructure, not a demo
anthonywu's deployment stack turns vLLM, Tailscale, Docker, and systemd into a bootable AI appliance for DGX hardware.
Local LLM Inference
The Architecture of Empty Space: Inside instructkr/jax-study
How a masterfully crafted .gitignore file reveals the exact tooling, philosophy, and future of a modern machine learning collaborative environment.
Local LLM Inference
The No-Math AI: Deconstructing chenglou/mnist
How a React pioneer built a digit classifier without neural networks, backpropagation, or a single machine learning dependency.
Local LLM Inference
200 Lines to Symphony: The Minimalist Anatomy of tiny-musicgen
Stripping Meta's MusicGen down to its mathematical bones to run state-of-the-art generative audio on a laptop.
Local LLM Inference
mlx: The Zero-Config Lab Notebook for the Minimalist Researcher
A local-first experiment tracker that replaces heavy cloud infrastructure with a hidden folder and a punchy CLI.
Local LLM Inference
FMML_COURSE_ASSIGNMENTS: A Repo That Teaches Machine Learning by Showing Its Gears
A notebook-first curriculum from IIIT Hyderabad that turns linear algebra, distance metrics, and data augmentation into something students can actually see.
Local LLM Inference
minor-project: What a Transformer Looks Like in Raw C
A from-scratch neural network framework that turns backprop, attention, and image operators into explicit loops, buffers, and pointer math.
Local LLM Inference
text2sql-assistant: Nexus AI Query: The Local-First Text-to-SQL Copilot That Keeps Your Schema at Home
A FastAPI, React, and Ollama stack that turns natural language into PostgreSQL queries without sending your data to a cloud model.
Local LLM Inference
appwrite/docker-ollama: Baking AI Models Into Docker Layers
How Appwrite uses a build-time Ollama server, multi-arch Docker tricks, and pre-pulled weights to make local inference start instantly.