ml-inference-gateway: How Java Virtual Threads Turn ML Traffic Into Efficient Batches
A production-minded inference gateway that uses imperative code, adaptive batching, Redis rate limits, and gRPC resilience to squeeze more throughput out of ML systems without drowning in async complexity.
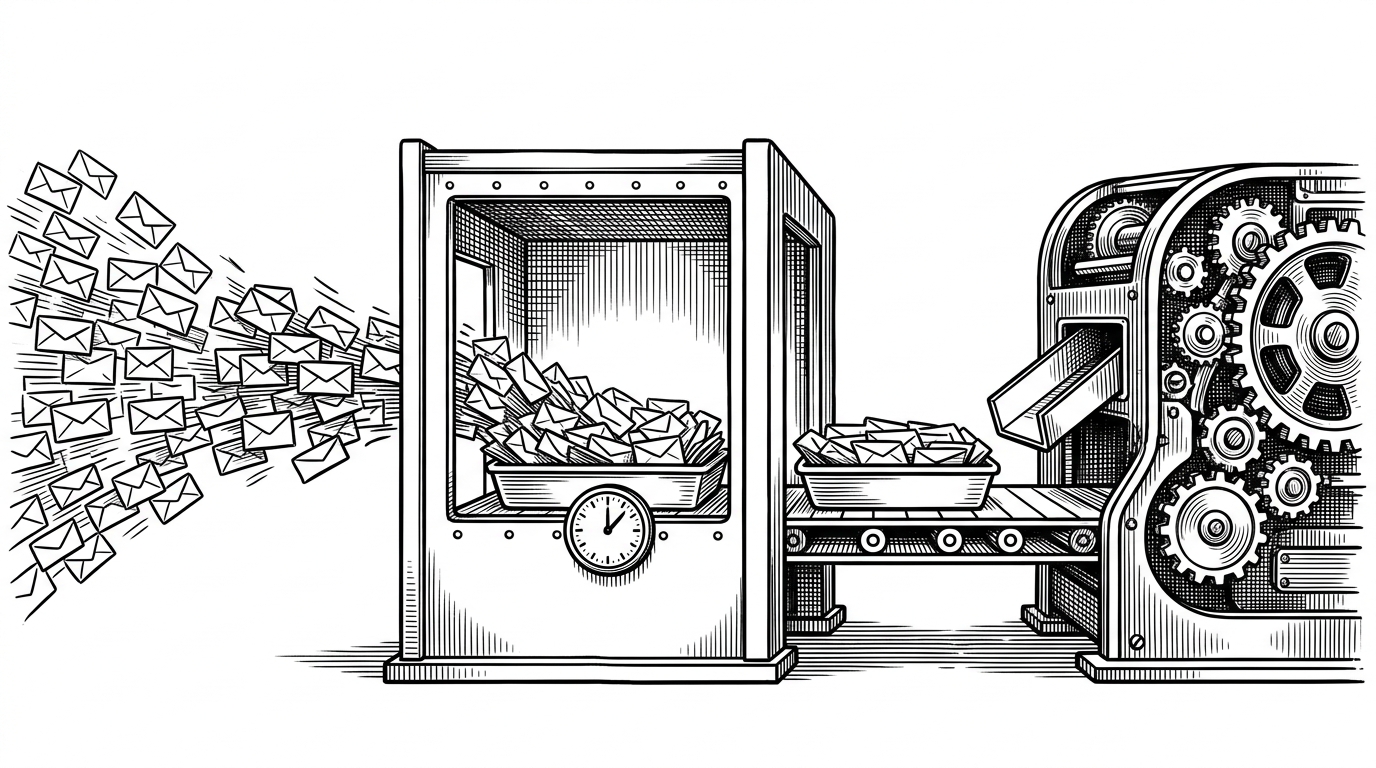
- The repo’s core idea is that a small, deliberate wait can raise total throughput when the downstream model server prefers batches.
- Java 21 virtual threads let the gateway stay imperative and debuggable without giving up high-concurrency behavior.
- Adaptive batching is only half the story, because Redis rate limits, idempotency, and Resilience4j keep the fast path from becoming a fragile one.
- This is best read as a production-minded reference architecture, not a finished platform.
Most gateways try to answer every request as soon as it lands. This one makes a different bet: if you wait a few milliseconds, you can group traffic into batches that the model server can process more efficiently. That tradeoff is the whole article.
The trick is not speed. It is waiting on purpose.
The gateway’s most interesting move is not a new protocol or a fancy routing layer. It is a 15ms batching window. Requests arrive as ordinary REST traffic, but the gateway does not immediately forward each one to inference. It lets a queue fill, then ships a batch when the queue reaches size or the timer expires.
That sounds like a latency penalty. In ML systems, it is often the opposite. Model inference frequently gets cheaper per request when it runs on a batch, especially when the backend is tuned for vectorized work or GPU utilization. The gateway is simply moving a little latency upstream to save much more work downstream.
A Java gateway that refuses to become reactive
The architectural choice that makes this repo stand out is Java 21 virtual threads. Instead of forcing the whole stack into a reactive mental model, the gateway keeps a straightforward imperative style. That matters because the code is easier to read, easier to debug, and easier to change under pressure.
Virtual threads change the economics of blocking. A controller can wait on a future without tying up a platform thread, so the gateway can tolerate high concurrency without turning the codebase into callback soup. It is a practical way to get scale without making the developer experience pay the tax.
@PostMapping("/predict")
public ResponseEntity<?> predict(@RequestBody PredictionRequest request) {
    rateLimiterService.checkLimit(request);
    return idempotencyService.executeOnce(request, () -> {
        CompletableFuture<PredictionResult> future = adaptiveBatcher.submit(request);
        PredictionResult result = future.get();
        return ResponseEntity.ok(result);
    });
}
The point of this shape is not the exact syntax. The point is that the blocking call stays readable because Loom absorbs the concurrency cost. That is a very different trade from the usual WebFlux-first gateway design.
AdaptiveBatcher is the real engine
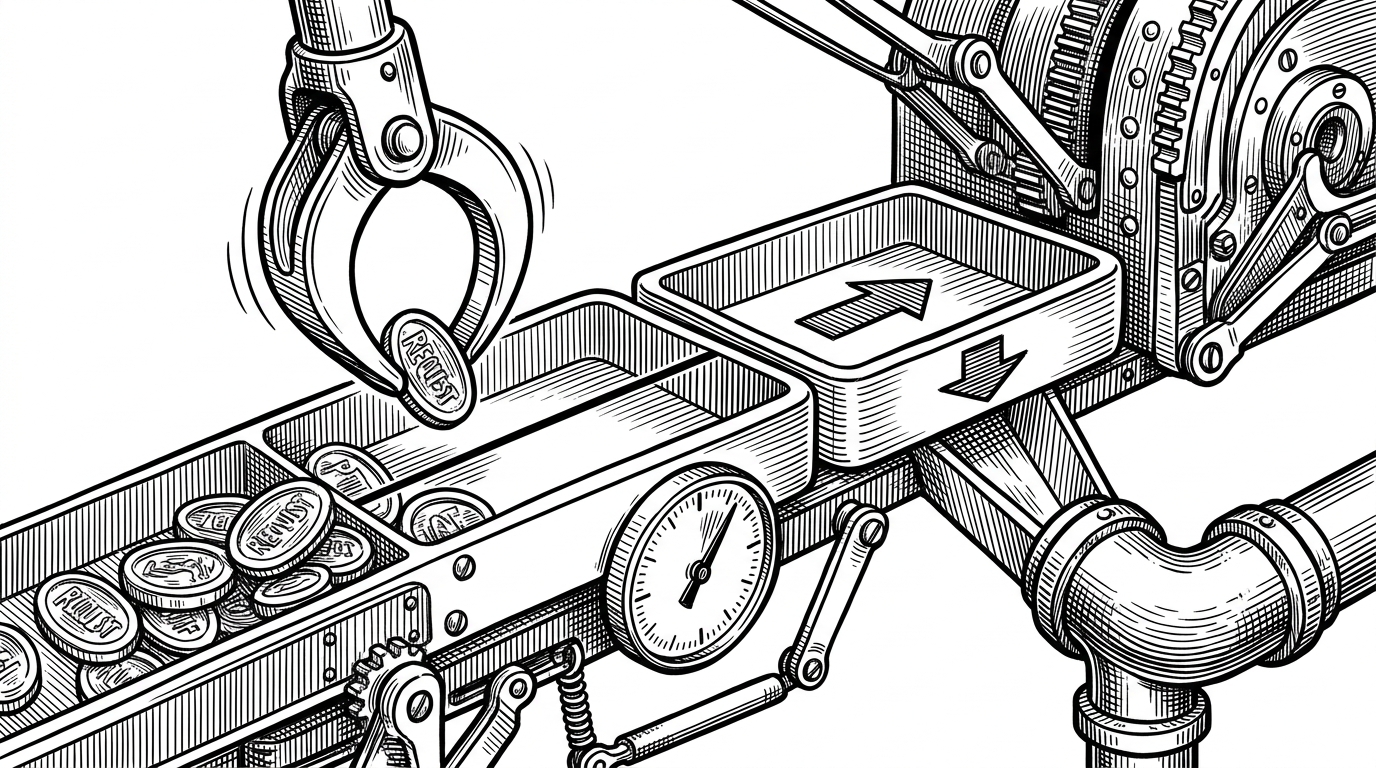
`AdaptiveBatcher` is the component that turns individual requests into efficient inference payloads. It uses a blocking queue and a background worker, then applies a simple rule: send now if the batch is full, or send now if the wait window expires. The logic is plain, which is exactly why it works as a reference design.
while (running) {
    List<Request> batch = queue.drainTo(new ArrayList<>(), maxBatchSize);
    if (batch.isEmpty()) {
        batch.add(queue.poll(maxWaitMs, TimeUnit.MILLISECONDS));
    }
    if (!batch.isEmpty()) {
        inferenceClient.sendBatch(batch);
    }
}
This is the important systems insight: the gateway is not trying to be universally optimal. It is optimizing for a workload where one extra request’s worth of waiting can unlock better utilization in the model server. That is a very ML-specific move, and it is why the design feels intentional rather than generic.
The gateway is wrapped in guardrails
Speed alone would make this brittle. The repo adds a second layer of discipline around the batching path: distributed rate limiting, idempotency, and Resilience4j. Each one protects a different failure mode.
| Guardrail | What it protects | Why it matters |
|---|---|---|
| Redis rate limiting | Abuse and traffic spikes across instances | Keeps the limit accurate even when the gateway is scaled horizontally |
| PostgreSQL idempotency | Duplicate work from retried requests | Prevents the same inference from being paid for twice |
| Resilience4j bulkhead, circuit breaker, retry | Slow or failing model-server calls | Stops one bad backend from dragging down the whole gateway |
The architecture is interesting because these are not decorative features. They are the difference between a demo and something that can survive real traffic patterns. The gateway is trying to be fast, but it is also trying to be hard to abuse.
Why gRPC is the right bridge here
The repo splits the system cleanly between a Java gateway and a Python model server, with protobuf and gRPC as the contract. That is a good fit. The gateway gets a compact binary protocol, and the model server gets a simple, language-agnostic interface for inference.
| Option | Upside | Downside |
|---|---|---|
| REST between gateway and model server | Simple to debug | More overhead and weaker typing for the internal hop |
| gRPC with protobuf | Fast, typed, compact | Less human-readable on the wire |
| Shared language runtime | Fewer translation layers | Forces the whole stack into one ecosystem |
try {
    InferenceResponse response = grpcClient.predict(batch);
    return response;
} catch (StatusRuntimeException ex) {
    throw translateGrpcException(ex);
}
The exception translation matters more than it looks. A good gateway does not leak transport internals to callers. It maps backend failures into sane HTTP responses, so the system behaves like one service even though it is really several.
What this looks like next to the alternatives
This repo sits in a different niche from the larger inference gateway ecosystem. It is not trying to be a generalized cloud control plane. It is closer to a focused reference architecture for teams that want to keep the gateway layer in Java while still taking batching seriously.
| Approach | Programming model | Best fit |
|---|---|---|
| This repo | Imperative Java with virtual threads | Teams that want readable code and batch-aware throughput |
| Reactive gateway | Non-blocking event-driven flow | Teams already invested in WebFlux or Netty |
| Cloud-managed inference gateway | Managed control plane and policy stack | Teams optimizing for platform convenience |
The tradeoff is clear. Reactive systems are powerful, but they often demand a different way of thinking. This project argues that you can keep the code comprehensible and still get most of the concurrency advantage by combining Loom with a batching strategy that respects the workload.
The limitations tell you this is real
The repo is honest about its constraints, which makes it more credible. The gRPC plaintext setup would need TLS in a serious deployment, and the public footprint is still small. That does not weaken the architecture. It places it correctly: a strong, production-minded reference, not a battle-tested platform.
That is also why the project is worth studying. It shows a clean path to a hard problem: build a gateway that stays understandable, then reclaim performance through batching, concurrency primitives, and guardrails that fit the workload.