SemIf: The Open Source Project That Turns an LLM Into a Logit Reader
Instead of generating JSON and fixing it afterward, SemIf reads option probabilities directly, reuses cached prefixes across many questions, and makes local inference feel like a typed decision engine.
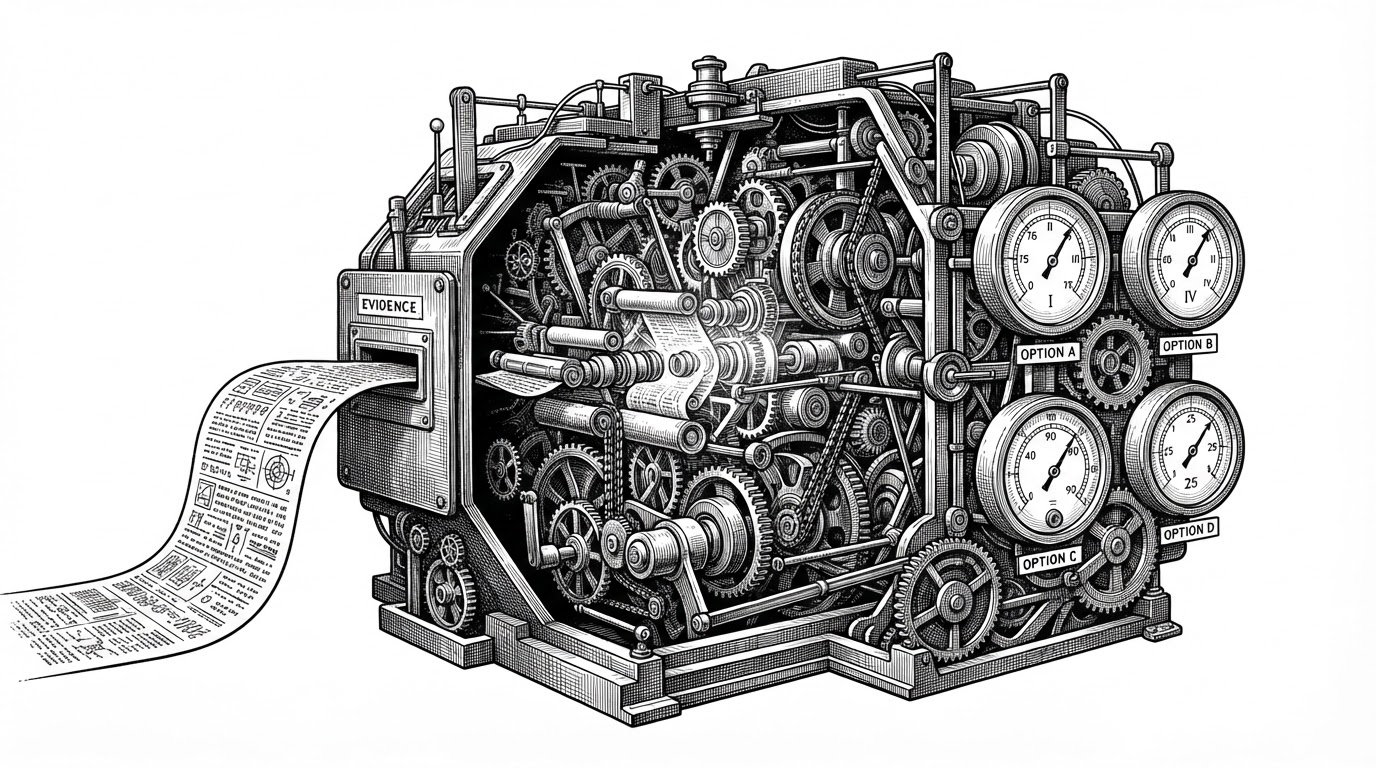
- SemIf reframes an LLM as a logit reader, which makes structured choices feel closer to classification than generation.
- Its real speed advantage comes from skipping the decoding loop and reusing one evidence prefix across many questions.
- The project is strongest when the task is a typed decision, not open-ended text production.
- Its browser demo and reproducibility discipline make the idea feel portable instead of experimental theater.
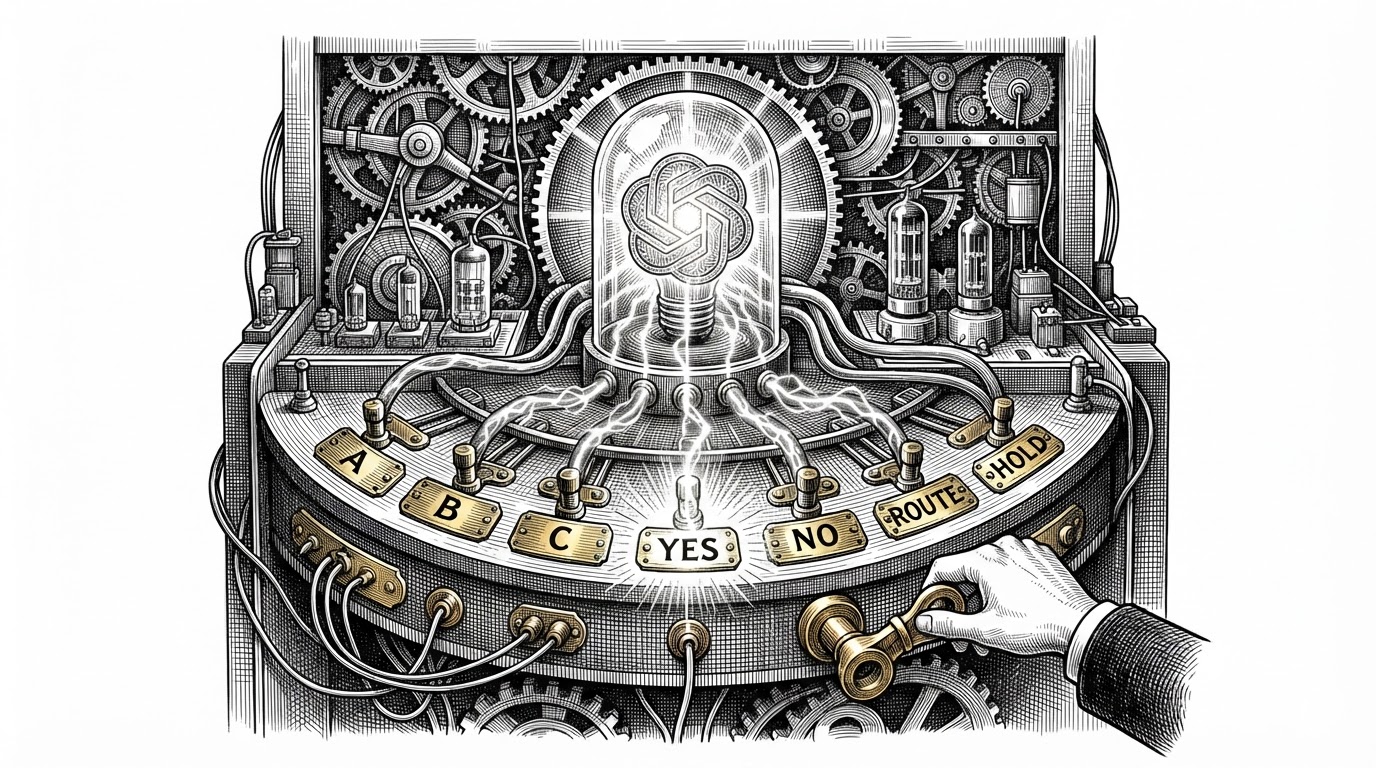
The model is not writing. It is voting.
That is the move SemIf makes. It does not ask a model to draft an answer, then clean up the mess. It asks the model to expose which option it prefers, directly from the logits.
That sounds subtle until you compare it with the usual structured-output stack. The default pattern is still some variation of prompt, generate, parse, repair, retry. SemIf cuts across that workflow and treats the model more like a typed decision engine.
Most agent decisions are small: route this, retry that, does the evidence support X? A chat model can answer them, but it spends time generating text that software immediately parses back into an if statement.
Why that matters for structured decisions
SemIf is aimed at workloads where the answer is one of a few declared options. Think route this, retry that, accept or reject, support this claim or not. In those cases, full text generation is mostly overhead.
The usual costs show up fast. You pay for decoding tokens you do not need. You spend time repairing malformed output. You build retry logic for failures that are not really model failures, just interface friction.
| Tool | Core method | Generates text? | Best fit | Main tradeoff |
|---|---|---|---|---|
| SemIf | Reads declared option logits directly | No | Binary and N-way decisions | Specialized, not general text generation |
| Outlines | Constrains decoding with schema rules | Yes | Structured text output | Still pays the generation cost |
| Instructor | Parses model output into typed objects | Yes | Pydantic-style workflows | Needs validation and retries |
| LM Format Enforcer | Filters tokens during generation | Yes | Schema-constrained completion | Still runs the decode loop |
That comparison is the whole point. SemIf is not trying to be a better JSON parser. It is trying to make JSON unnecessary for this class of task.
From OpenJev to SemIf
The repo is framed as an open-source reproduction of a closed hosted pattern, but the important detail is the stance. It is local-first, hardware-aware, and explicit about its constraints. It is built for commodity GPUs and Apple Silicon, not for a glossy hosted abstraction.
That positioning matters because the project is not selling general intelligence. It is selling a narrow interface: fast, typed decisions on top of smaller open models.
How the direct scorer works
The core files make the design unusually legible. In core.py, SemIf validates a row so every decision has an id, a state, a question, and a list of options. In direct.py, it maps those options to slot tokens such as A, B, C, and then reads the logits for those tokens from a single forward pass.
def score(model, tokenizer, state, question, options):
    prompt = build_prompt(state, question, options)
    outputs = model(**tokenizer(prompt, return_tensors="pt"), logits_to_keep=1)
    slot_ids = [tokenizer.convert_tokens_to_ids(letter) for letter in option_letters(options)]
    logits = outputs.logits[0, -1, slot_ids]
    probs = softmax(logits)
    return probs
The important detail is what is missing. There is no decoding loop. There is no sentence to repair. The model is being used as a scorer, not a narrator.
The hidden superpower is prefix reuse
SemIf becomes more interesting once the evidence block gets large. A long document can be prefetched once, then reused across many downstream questions. That is where shared.py and serial.py matter.
The machine stays warm on the same prefix, then branches into short question suffixes. In practice, that turns one expensive read into many cheaper decisions.
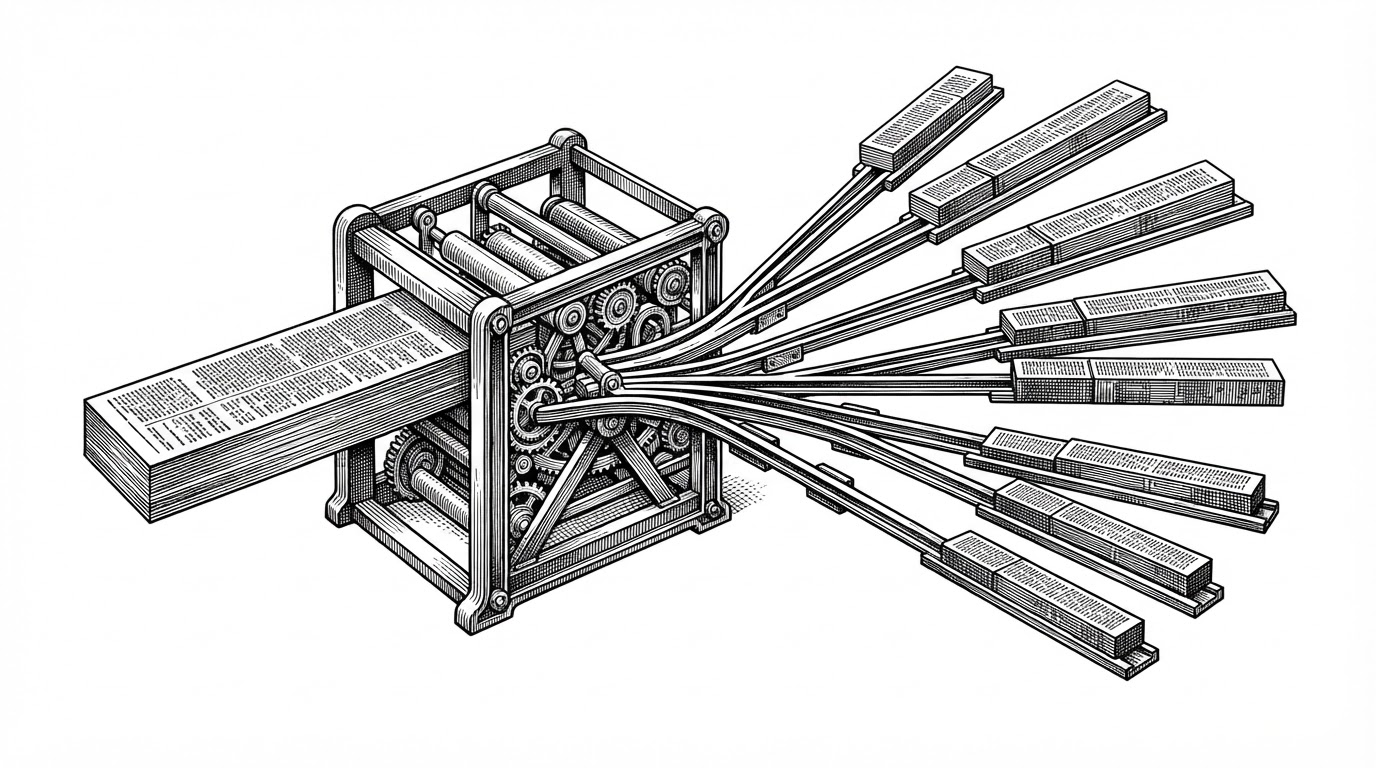
That is also why the project is more than a one-off benchmark trick. It is a pattern for repeated decisions over shared context.
What SemIf beats, and where it does not
SemIf beats tools that still insist on generating text first. If your task is fundamentally a choice among declared options, bypassing the generation loop is cleaner and usually faster.
But that specialization is also the boundary. If you want open-ended text, rich extraction, or flexible schema filling, a constrained generator like Outlines or LM Format Enforcer is still the better fit. SemIf is sharper, not broader.
That tradeoff is honest. The repo is not pretending to replace the whole structured-output ecosystem. It is carving out the slice where direct scoring is the right primitive.
Why the repo feels research-grade
The engineering discipline shows up in the boring places, which is usually a good sign. The project includes benchmark data, raw results, pinned revisions, and SHA256 checksums. The model path is not meant to drift underneath the numbers.
That kind of reproducibility matters because the central claim is performance. If you are arguing that one forward pass is materially better than a decode-and-parse pipeline, you need the receipts.
SemIf has them, at least in structure. That makes the repo feel like a small research system, not just a clever demo.
The browser demo matters more than it looks
The WebGPU demo is doing more than showing off. It proves the interface is not tied to one GPU stack. The idea can travel into a browser, which is a strong signal that the pattern is portable.
That widens the story from a benchmark on a workstation to a deployable decision layer. The point is not just speed. It is that the interface stays simple enough to move.
SemIf, renamed from OpenJev, reads the probability of each answer you allow straight out of a small open model in a single forward pass. Nothing is written out — no answer sentence, no JSON to repair, no decoding loop.