laya-mlx: The Apple Silicon Runtime That Treats AI Like a Decision Function
A native MLX port of Laya that skips token generation, caches prefixes, and turns ModernBERT into a low-latency engine for structured choices, scores, and booleans.
- laya-mlx matters because it rejects token-by-token generation and turns AI into a calibrated decision function.
- Its real trick is not just MLX performance, but the way caching and shortlist routing remove wasted inference work.
- The repo is built for local software loops where latency, typed output, and offline execution matter more than prose fluency.
- The result sits between an LLM runtime and a typed API, which makes it feel like a new primitive for Apple Silicon apps.
The End of Token-by-Token Thinking
Most AI tools still assume the same basic ritual: send text in, wait for text out, then parse what you got. laya-mlx breaks that habit completely. It is built for decisions, not prose.
That sounds like a small shift until you use it inside software. A spam flag, a route choice, a ranking score, a boolean guard, these are all answers that do not need a paragraph. They need speed, calibration, and a stable interface.
This is why the project feels more like a runtime than a chatbot. It treats AI as a function that returns typed outputs, not as a narrator that tries to sound useful.
What Laya Is Actually Optimized For
It provides a native Apple MLX runtime that executes Laya typed decision models directly on Apple Silicon, bypassing text generation and PyTorch to deliver structured classification or decision outputs in 7–14 ms on M3 Max hardware.
That sentence is the whole thesis. Laya models are not trying to write responses. They are trying to choose, score, or classify with enough confidence that software can act on the result immediately.
from laya_mlx import Agent

agent = Agent.load("english")
result = agent.score(
    state="Customer asked for a refund after delivery.",
    question="Is this likely a support escalation?"
)

print(result.probability)  # typed decision, not generated text
That output shape changes the product design around it. Instead of prompting for creativity, you define a decision boundary and wire the result into the next step of the system.
Why MLX Changes the Economics
| System | Output style | Hardware target | Latency profile | Strength | Limitation |
|---|---|---|---|---|---|
| laya-mlx | Choice, score, boolean | Apple Silicon via MLX | Single-digit to low-teens milliseconds | Local, typed, fast | Mac-only runtime |
| Upstream Laya | Choice, score, boolean | General PyTorch runtime | Fast, but heavier | Reference implementation | More overhead on-device |
| Cloud typed-decision API | Choice, score, boolean | Remote server | Network-bound | Simple to call from anywhere | Latency and dependency on the network |
| General local LLM runtime | Generated text | CPU or GPU | Token-by-token | Flexible prose output | Wrong tool for structured decisions |
The economics are simple. If a task is really a decision, paying for text generation is wasteful. MLX helps because it lets the model run natively on Apple Silicon without dragging along a heavyweight PyTorch stack.
That matters even more when the decision loop is part of an interactive product. A network round trip can dominate the whole experience. A local inference pass can disappear into the background.
Inside the Runtime: Encoder, Heads, Cache
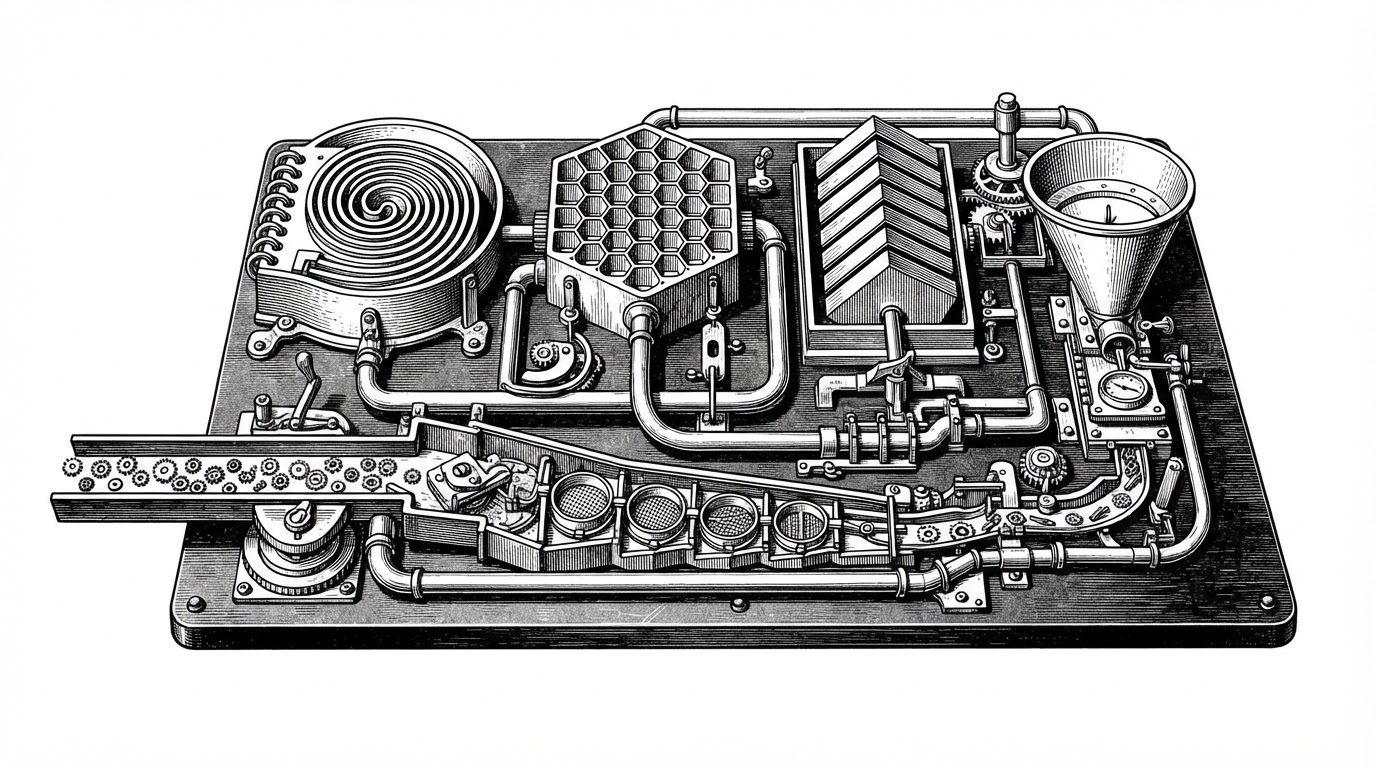
The codebase is split into a few ideas that matter more than the directory names. model.py ports ModernBERT with full and sliding attention. agent.py handles decision heads and calibration. prepared.py caches tokenized prefixes. shortlist.py trims large option sets before full scoring.
# Conceptual flow
state -> prepared.prefix_cache -> tokenization -> ModernBERT encoder
encoder -> choice / score / noul heads
large option set -> shortlist filter -> final head

# Why this matters
# repeated question prefixes are reused instead of recomputed
The important detail is that the model is doing less, not merely doing it faster. Prefix caching removes repeated tokenization. Shortlisting prevents the encoder from wasting attention on options that will never win.
Why Snake Is the Perfect Demo
Generating illustration...
Snake is not a gimmick here. It is a stress test. If the model can keep up with a moving game state, then the runtime is fast enough for reactive software, not just offline classification.
Following Jev? Laya-MLX is worth a look. It's an open-source MLX port of Laya for Apple silicon. You give it text and possible actions; it returns probabilities for each, with zero output tokens. I ran its Snake demo on my Mac Studio M4 Max and recorded the clip below. Around h
How It Compares to Jev, Laya, and Other Decision Engines
| System | Output style | Hardware target | Latency profile | Strength | Limitation |
|---|---|---|---|---|---|
| laya-mlx | Typed local decisions | Apple Silicon | Very low, local | Open and on-device | Mac focused |
| Upstream Laya | Typed decisions | General purpose Python runtime | Low to moderate | Reference behavior and breadth | More overhead than MLX |
| Jev | Typed decisions | Cloud API | Moderate, network bound | Simple hosted service | Not local, not open |
| Ollama or llama.cpp | Generated text | CPU or GPU | Depends on model size | Great for chat and completion | Not optimized for typed decision heads |
The niche becomes obvious once you compare them side by side. laya-mlx is not trying to be a general model host, and it is not trying to be a remote API. It is trying to be the fast local decision layer inside software on a Mac.
What This Suggests About Local AI
The larger lesson is that not every AI task wants a chatbot. Some tasks want a tiny, calibrated, low-latency answer that can be consumed by software immediately.
That is the interesting future here. If local hardware can make decisions fast enough, then AI stops being a destination UI and becomes a primitive, something closer to a function call, a router, or a guardrail.
That is the real promise of laya-mlx: not prettier text, but a better contract between models and programs.