`absoluteappsec/nextgen`: The AppSec Lab That Teaches AI to Read Code, Think Like a Pentester, and Police Itself
A hands-on framework for turning LLMs into private security agents, with RAG, hybrid context, few-shot reasoning, and prompt-injection guardrails built into the curriculum.
- NextGen treats AppSec as an AI workflow design problem, not a chatbot demo.
- Its real value is private, local-first analysis that keeps source code inside the team boundary.
- The repo pairs retrieval, hybrid context, and few-shot examples so the model reasons more like a security analyst.
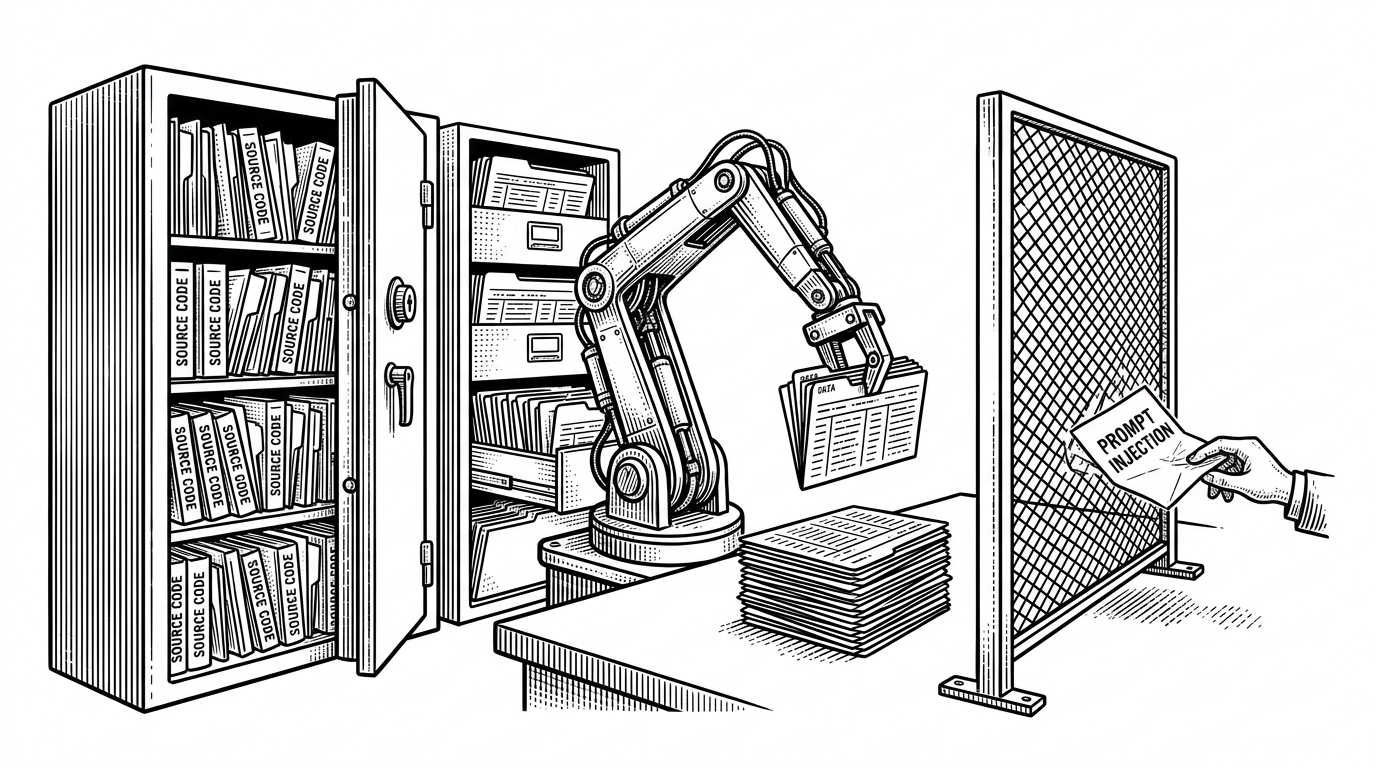
- Prompt injection is not an afterthought here, because the assistant itself becomes part of the attack surface.
The most interesting thing about absoluteappsec/nextgen is not that it uses an LLM for security. It is that it refuses to pretend the LLM is harmless. The repo builds a private security assistant, then immediately adds the controls needed to keep that assistant from being manipulated.
That tension makes the project feel unusually honest. In security, the tool you trust is often the tool you need to distrust first.
We built NextGen to fill a gap we saw in available vulnerable applications. Many existing options are either too simplistic or outdated, not reflecting the complexities of modern web development.
Ken Johnson and Seth Law frame the project as a living curriculum, but the repository itself is more interesting than the pitch. It is organized like a workshop that starts with simple retrieval and ends with an adversarial agent that has to earn the right to act.
Why Local-First Changes the Game
For AppSec teams, privacy is not a philosophical preference. It is the reason the system can exist at all. `nextgen` leans on local inference paths like Ollama and local embeddings because source code, architecture notes, and incident context are often too sensitive to ship to a third-party API.
| Dimension | Cloud-first AI | Local-first NextGen |
|---|---|---|
| Data boundary | Source code leaves your environment | Code stays inside your environment |
| Operational fit | Easy to prototype | Better for proprietary or regulated code |
| Security posture | Adds vendor trust | Reduces external exposure |
| Primary trade-off | Convenience | More setup and hardware discipline |
That shift changes the product category. This is not a general-purpose assistant that happens to know security words. It is a security system designed around the reality that the codebase itself may be the crown jewel.
The Pipeline: From Source Tree to Retrieval
The ingestion path in `loaders/load_juice_shop_ollama.py` is the first real clue to how the repo works. It clones a target codebase, chunks it with a recursive text splitter, embeds the pieces locally, and stores them in FAISS so the model can search a codebase without pretending the whole tree fits in context.
retriever = vectorstore.as_retriever(
    search_type="mmr",
    search_kwargs={"k": 30}
)

results = retriever.invoke(user_question)
answer = llm.invoke(prompt.format(context=results, question=user_question))
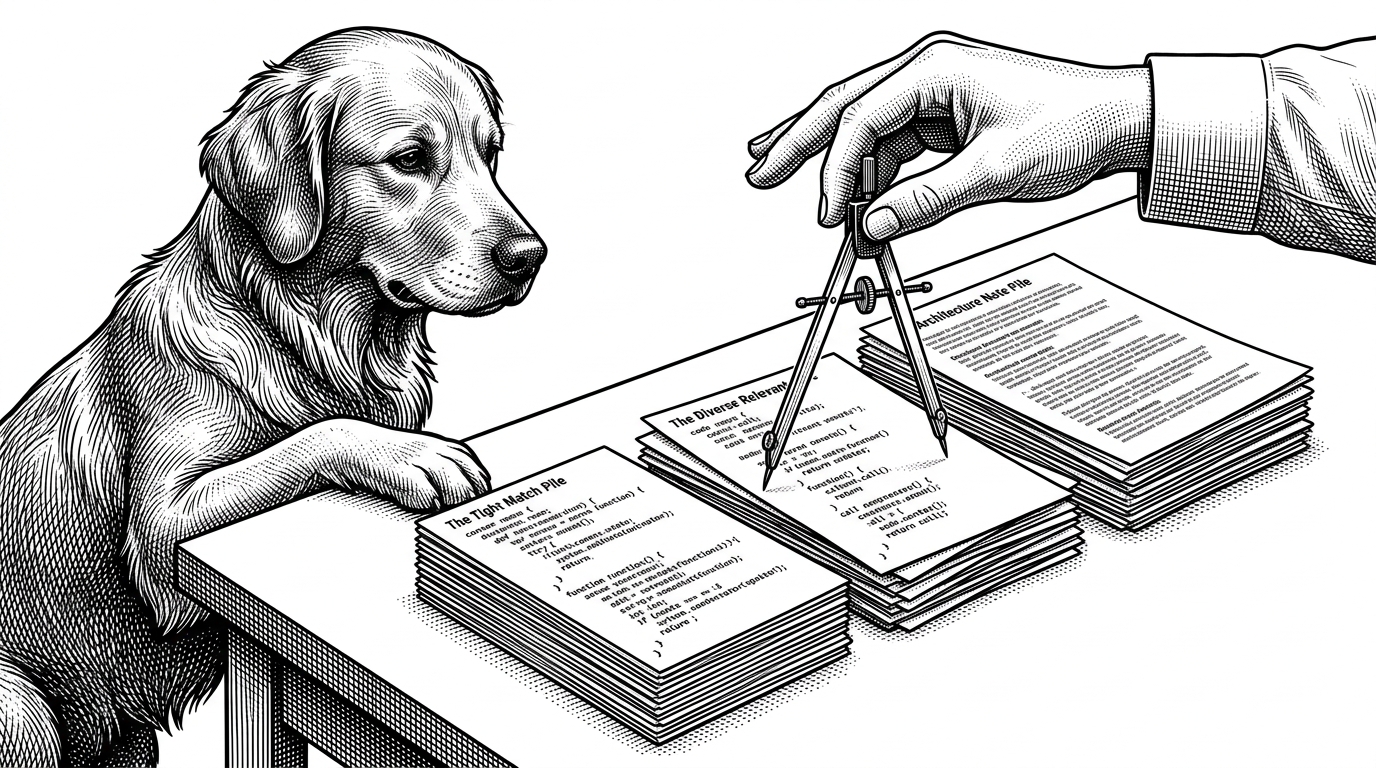
The important choice is not just retrieval. It is retrieval with diversity. The MMR setting in `exercise-00/chatbot.py` pushes the assistant toward a broader evidence set, which matters when a bug is distributed across files instead of sitting in one cleanly named function.
Why MMR Matters for Cross-File Bugs
A plain nearest-neighbor search rewards similarity. Security analysis needs something subtler. MMR keeps the retriever from collapsing onto one narrow cluster of code and helps surface the odd, relevant fragment that changes the conclusion.
| Retrieval strategy | What it optimizes for | What it risks missing |
|---|---|---|
| Nearest match | Closeness to the query | Alternative evidence from other files |
| MMR with high k | Coverage and diversity | Some low-similarity noise |
| Hybrid retrieval | Code plus architecture context | More moving parts to tune |
That is why the repo feels less like a chatbot tutorial and more like evidence handling. The model is being taught to collect enough of the scene before it starts making claims.
Hybrid Context Beats Blind RAG
`exercise-02/building_with_context.py` pairs retrieved code with a static knowledge base. That matters because code tells you what exists, but architecture docs tell you why it exists, which trust boundaries matter, and which paths the model should treat as sensitive.
This hybrid setup is the difference between pattern matching and actual security reasoning. A function call can look safe in isolation and still be wrong once you understand the system around it.
From Generic Chat to Security Reasoning
The few-shot examples in `exercise-06/sca_deterministic_few_shot.py` push the model past vague bug hunting. Instead of saying, "find vulnerabilities," the repo teaches the model the shape of a security judgment, including the difference between suspicious code and merely unfamiliar code.
few_shot_prompt = FewShotChatMessagePromptTemplate(
    examples=security_examples,
    example_prompt=example_prompt,
)

messages = [
    system_message,
    few_shot_prompt,
    user_message,
]
That is a practical distinction. A model can only be useful in AppSec if it learns to reason in the language of the stack it is inspecting, not just in the language of generic software advice.
NextGen is designed to be a living project, constantly evolving to include new vulnerabilities and technologies as they emerge. It's a crucial tool for keeping security professionals up-to-date.
The repository's evolution toward deeper agent structures reinforces that point. The goal is not a clever conversational layer. It is a workflow where skills, context, and control boundaries are explicit.
DeepAgents: A Smarter Shape for Security Work
The transition away from plain ReAct-style agents toward `deepagents` is one of the most interesting design choices in the project. It suggests the authors want constrained expertise, not open-ended autonomy. That is usually the right instinct in security.
| Agent shape | Strength | Weakness |
|---|---|---|
| ReAct-style loop | Simple to understand | Can drift and over-call tools |
| Structured DeepAgent | Clear skills and boundaries | More upfront design work |
| Deterministic middleware | Predictable guardrails | Less flexible in edge cases |
That trade-off is the whole game. In security tooling, more autonomy is not automatically more value. Sometimes the better product is the one that knows exactly what it is allowed to do.
The Guardrail Is Part of the Product
`exercise-05/chatbot_prompti_prevention_example.py` makes the project’s philosophy explicit. The guardrail runs before the agent acts, looking for jailbreak phrases and suspicious instruction patterns. That is not a patch. It is part of the architecture.
class PromptInjectionGuardrail(AgentMiddleware):
    def before_agent(self, state):
        if looks_like_jailbreak(state.input):
            return {"blocked": True}
        return state
This is where the repo becomes more than a learning scaffold. It demonstrates a useful rule for AI security products: if the assistant can be manipulated, then the manipulation path is part of the attack surface, not an edge case.
How NextGen Compares to Classic Vulnerable Labs
Juice Shop, DVWA, WebGoat, and NodeGoat are still the right references for vulnerability training. `nextgen` is doing something different. It is not mainly teaching you how to break a vulnerable app. It is teaching you how to build the assistant that helps you analyze one.
| Project | Primary goal | Main stack | Interaction model | What it teaches best | Where NextGen differs |
|---|---|---|---|---|---|
| OWASP Juice Shop | Practice OWASP Top 10 exploitation | Node.js, Angular | Gamified web app | Finding classic web flaws | AI-assisted analysis infrastructure |
| DVWA | Learn fundamentals of web vuln testing | PHP, MySQL | Simple vulnerable app | Manual exploitation basics | Local RAG and agent workflow |
| WebGoat | Teach mitigation and lesson-driven security | Java, Spring Boot | Guided lessons | Conceptual vulnerability education | Security reasoning with LLMs |
| NodeGoat | Show Node.js-specific weaknesses | Node.js, MongoDB | Deliberate vulnerable app | Framework-specific pitfalls | Private code analysis and guardrails |
| NextGen | Build private AI AppSec workflows | Python, LangChain, FAISS, Ollama | Retrieval + reasoning + defense | How to assemble a security assistant | It is the analysis layer, not the target |
That is the real distinction. The older labs train your hands. `nextgen` trains the system you would use to think with those hands.
What This Repo Is Really Teaching
The lasting lesson of `absoluteappsec/nextgen` is that AI-native security tooling has to be private, modular, and adversarially aware. Retrieval, examples, and guardrails are not separate features. They are the minimum viable shape of a serious assistant.
That is why the project stands out. It does not sell you on intelligence alone. It shows you how intelligence survives contact with security reality.