Datalab
Developing state of the art document intelligence models.
Explained projects
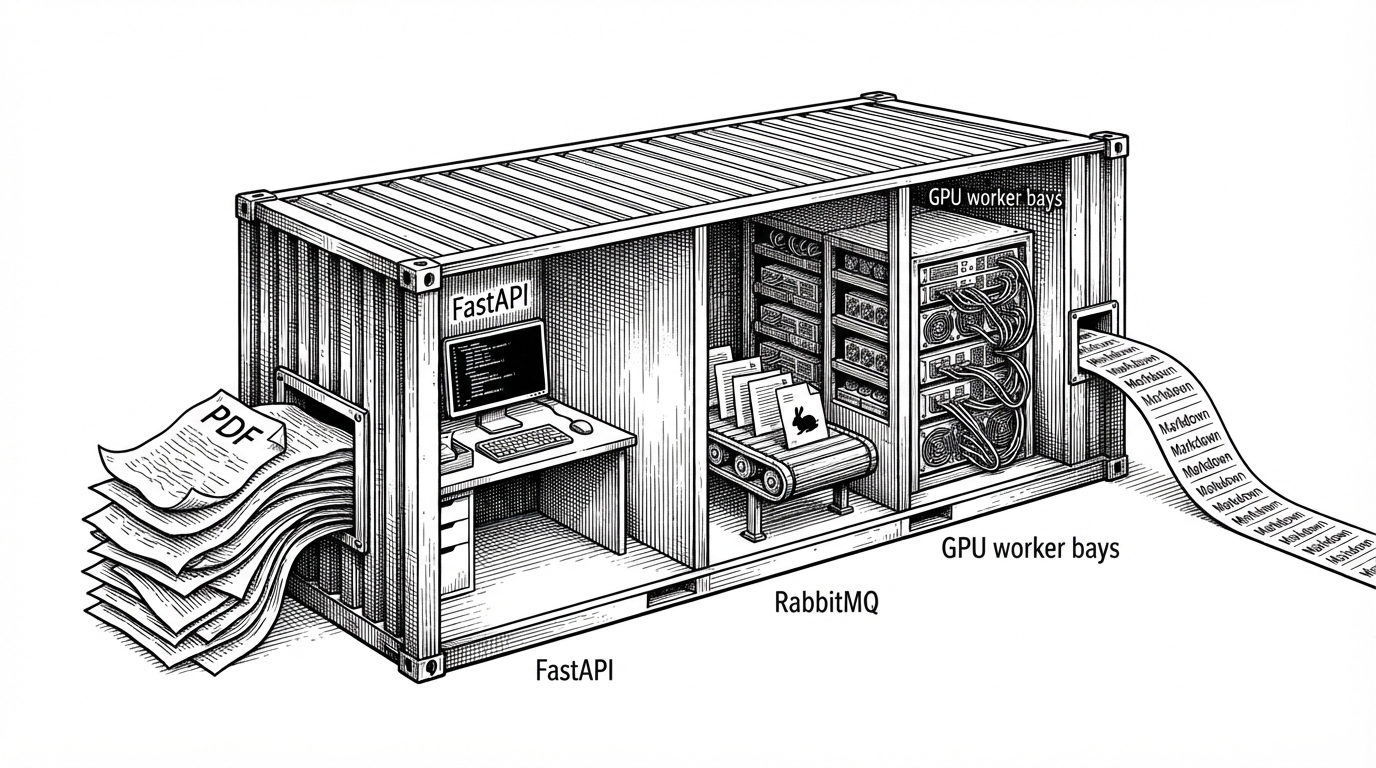
datalab-to/oss_container: The One-Container Cluster That Turns PDFs Into Markdown at GPU Speed
A FastAPI front end, RabbitMQ queue, and GPU workers all live inside one image, with chunking and merge logic that make large document conversion feel parallel, predictable, and self-hosted.
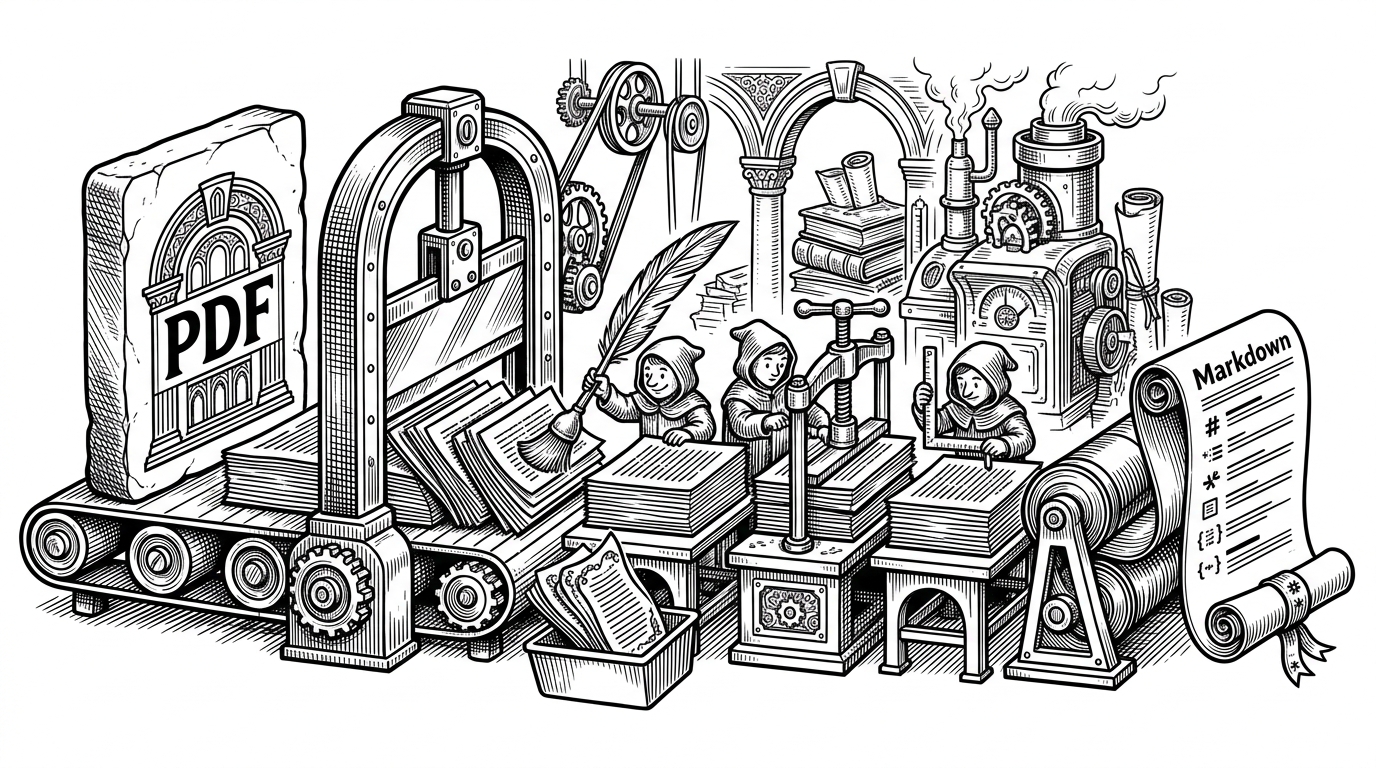
inference-mirror: The GPU Document Factory Behind marker
Datalab's wrapper turns PDF-to-Markdown into a parallel pipeline, splitting big documents across workers, sharing GPU capacity efficiently, and reassembling structured output at the end.
The Stateful Document: Unpacking the Datalab SDK
How a resilient Python wrapper turns long-running PDF extraction into a predictable, asynchronous pipeline.
The Geometry of Reading: Unpacking pdftext
How an Apache-2.0 mandate forced developers to reconstruct PDF layouts from raw C++ character dumps.
datalab-to/datalab-on-prem: The LLM-ification of Document Parsing
How a handful of Bash scripts orchestrate multi-GPU Vision-Language Models to bring air-gapped, state-of-the-art OCR to the enterprise.
datalab-to/marker: The Vision-First End to the PDF Bottleneck
How a custom OCR pipeline and polygon geometry turned thirty years of printer-optimized documents into structured data for AI agents.
Surya and the Vision-First Reconstruction of the Document
How Vik Paruchuri's high-performance toolkit replaced legacy OCR with a multimodal understanding of layout, logic, and reading flow.
Chandra and the End of the OCR Assembly Line
How full-page multimodal decoding is replacing twenty years of fragile document pipelines to finally solve the messy reality of handwriting and math.