The Stateful Document: Unpacking the Datalab SDK
How a resilient Python wrapper turns long-running PDF extraction into a predictable, asynchronous pipeline.
We decided that we needed to move to full page decoding. This led us to look around at the existing open source models. Unfortunately, nothing quite hit the set of features and accuracy that we needed.
- The Datalab SDK bridges the gap between instantaneous LLM wrappers and slow document parsing by treating OCR as a stateful pipeline.
- Relying on aggressive polling and exponential backoff, the dual async/sync client prevents rate-limit exhaustion during massive batch jobs.
- The introduction of Checkpoints allows developers to parse a PDF once and run multiple extraction queries against a cached intermediate state.
- A declarative JSON workflow engine transforms the SDK into an orchestrator for complex, multi-stage document intelligence.
The Millisecond Mismatch
Modern AI engineering suffers from a fundamental disconnect. Developers expect API wrappers to return text instantly. Turning complex, unstructured PDFs into clean Markdown requires heavy GPU inference that shatters standard HTTP timeouts. The datalab-to/sdk repository abandons the illusion of instantaneous document parsing. Instead, it treats conversion as a long-running, asynchronous workload that demands a robust polling lifecycle.
Polling for Reality
The heart of the SDK lives in datalab_sdk/client.py. It features a dual-client architecture built around an AsyncDatalabClient that uses aiohttp for non-blocking requests. A synchronous wrapper allows simpler script execution without async overhead. Because document intelligence takes minutes rather than milliseconds, the client relies heavily on the tenacity library. This handles 429 Rate Limit errors and introduces exponential backoff jitter. This jitter prevents the catastrophic thundering herd problem when processing massive document batches.
@retry(
    retry=retry_if_exception_type(RateLimitError),
    wait=wait_exponential_jitter(initial=1, max=60),
    stop=stop_after_attempt(10)
)
async def _poll_result(self, endpoint: str, max_polls: int = 120):
The Checkpoint Paradigm
The most powerful feature of the SDK data models is the checkpoint_id. Traditional API wrappers treat document parsing as a stateless action: you upload a file, get text back, and the server discards the context. If you want to change your extraction prompt, you must re-upload and re-parse the entire 100-page PDF.
Datalab shifts this to a stateful paradigm. The initial upload converts the document and caches its intermediate state. Developers can then run multiple lightweight extraction or segmentation queries against that saved state. This drastically reduces GPU inference time and API costs.
Escaping the Pipeline
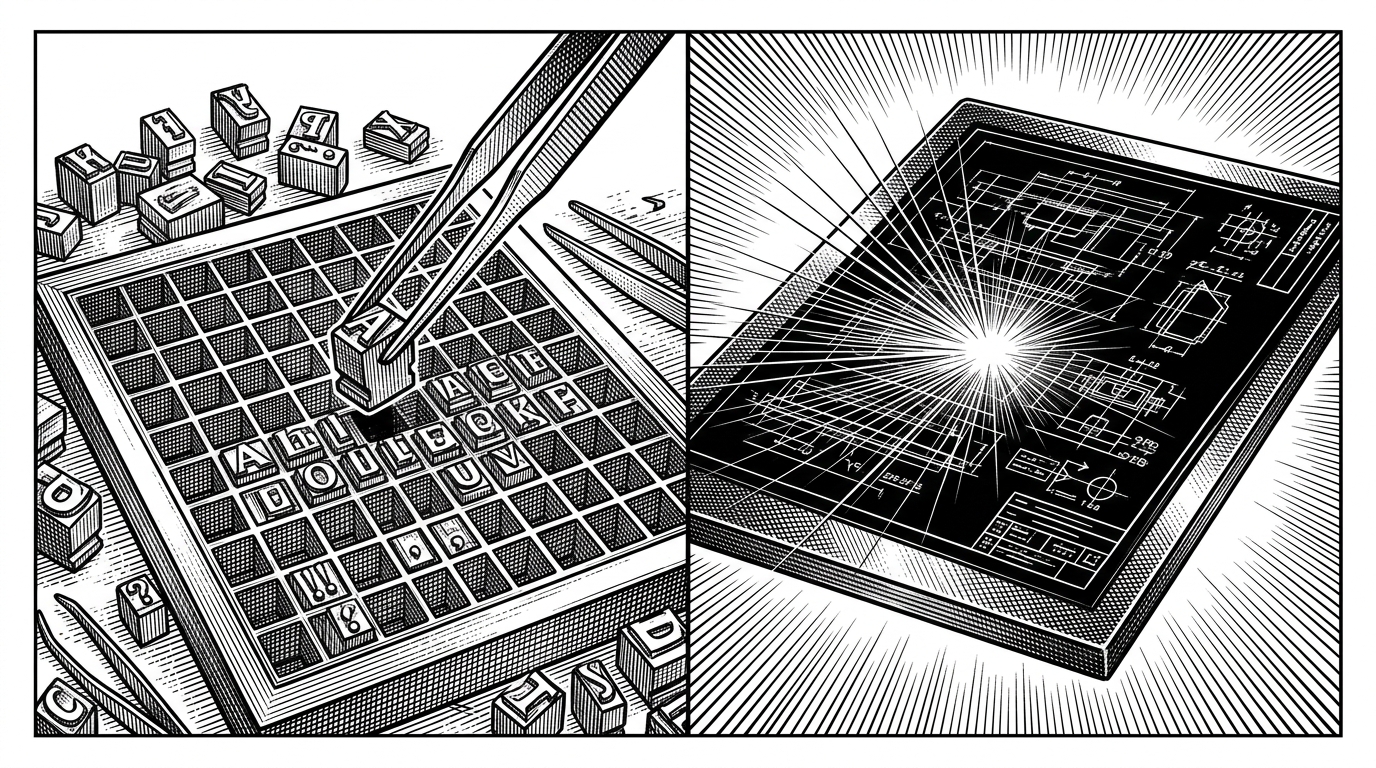
To understand the SDK architecture, you have to look at the evolution of the underlying models. Datalab co-founder Vik Paruchuri previously built the widely adopted open-source tools Marker and Surya. These tools utilized a pipeline-based approach that segmented pages into blocks before running inference. That approach struggled with highly complex documents containing math, varied layouts, and handwriting.
The result was Chandra, a new OCR model capable of full-page decoding and layout awareness. The sheer computational power required for full-page decoding is exactly why the Python SDK requires such a heavy-duty, state-aware polling mechanism to function reliably at scale.
JSON as the Orchestrator
The SDK provides a glimpse into its future through the recipes/workflows directory. By acting as a Directed Acyclic Graph executor, the SDK allows developers to chain Conversion, Segmentation, and Extraction steps via a declarative JSON configuration. This moves the repository away from being a simple wrapper and positions it as a complete orchestration engine for document intelligence pipelines.
{
  "name": "Invoice Processing Pipeline",
  "steps": [
    {
      "id": "convert_to_markdown",
      "action": "convert"
    },
    {
      "id": "extract_totals",
      "action": "extract",
      "depends_on": ["convert_to_markdown"]
    }
  ]
}