The Bureaucracy Hacker: Inside slavingia/va
How a pragmatic Python suite uses hybrid LLMs, aggressive caching, and defensive regex to parse the deep state.
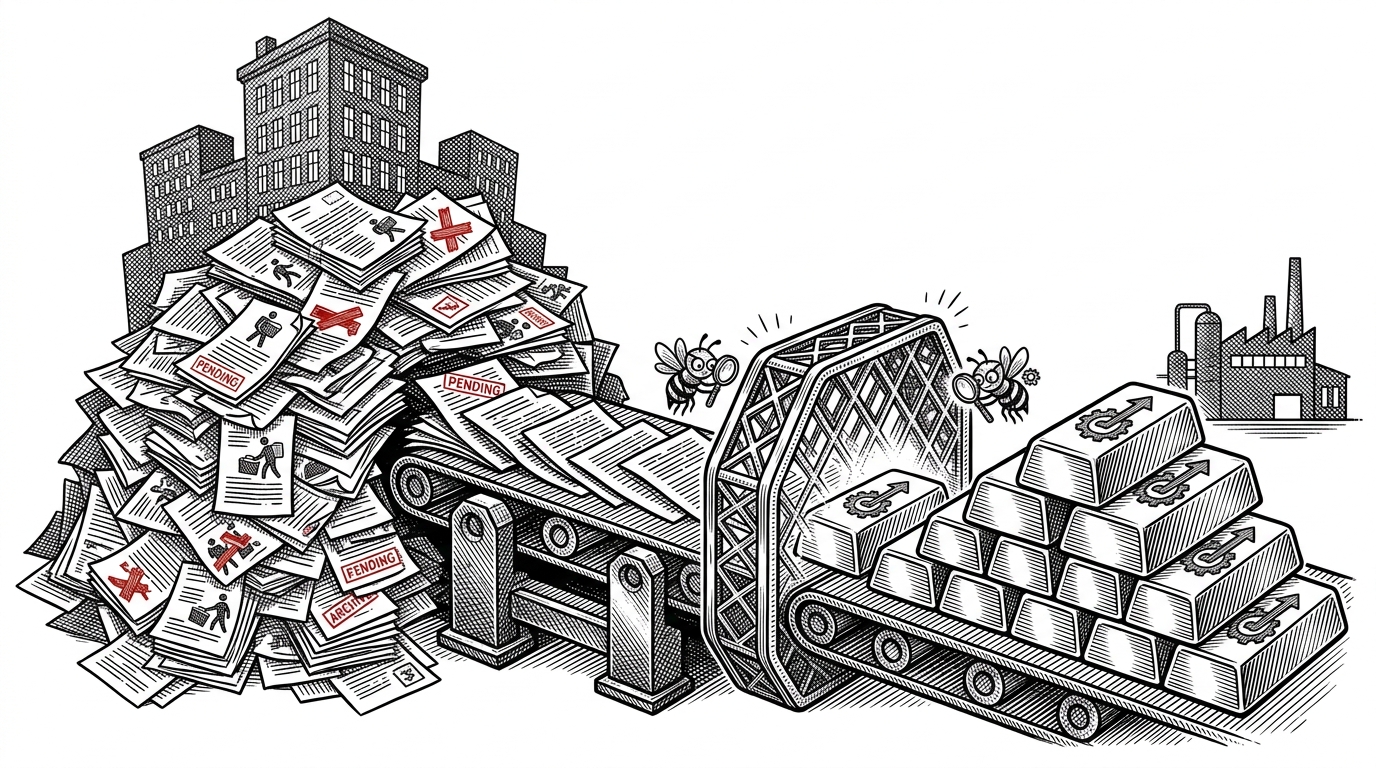
- The slavingia/va repository proves that AI's highest value in government is acting as an automated data janitor.
- Defensive programming and regex formatting are required to protect LLMs from the hallucinations caused by OCR errors in scanned federal documents.
- Aggressive MD5 cryptographic caching and staggered rate limiting prevent massive cloud bills and API throttling during bulk processing.
- Bottom-up data generation combined with D3.js makes sprawling federal hierarchies legible to human reviewers.
The Hostile Terrain of Federal Data
Silicon Valley builds AI tools for pristine APIs and clean data. The reality of government administration is much darker. Federal data consists of decades of scanned vendor PDFs, OCR-corrupted contracts, and massive administrative backlogs. The slavingia/va repository is built specifically for this hostile terrain.
When parsing Executive Orders or Department of Veterans Affairs contracts, an LLM alone will fail. A string like "$1.2.00.00 USD" will cause standard extraction prompts to hallucinate wildly. This repository solves the problem by wrapping advanced language models in paranoid, battle-hardened Python.
Defensive Programming in the LLM Era
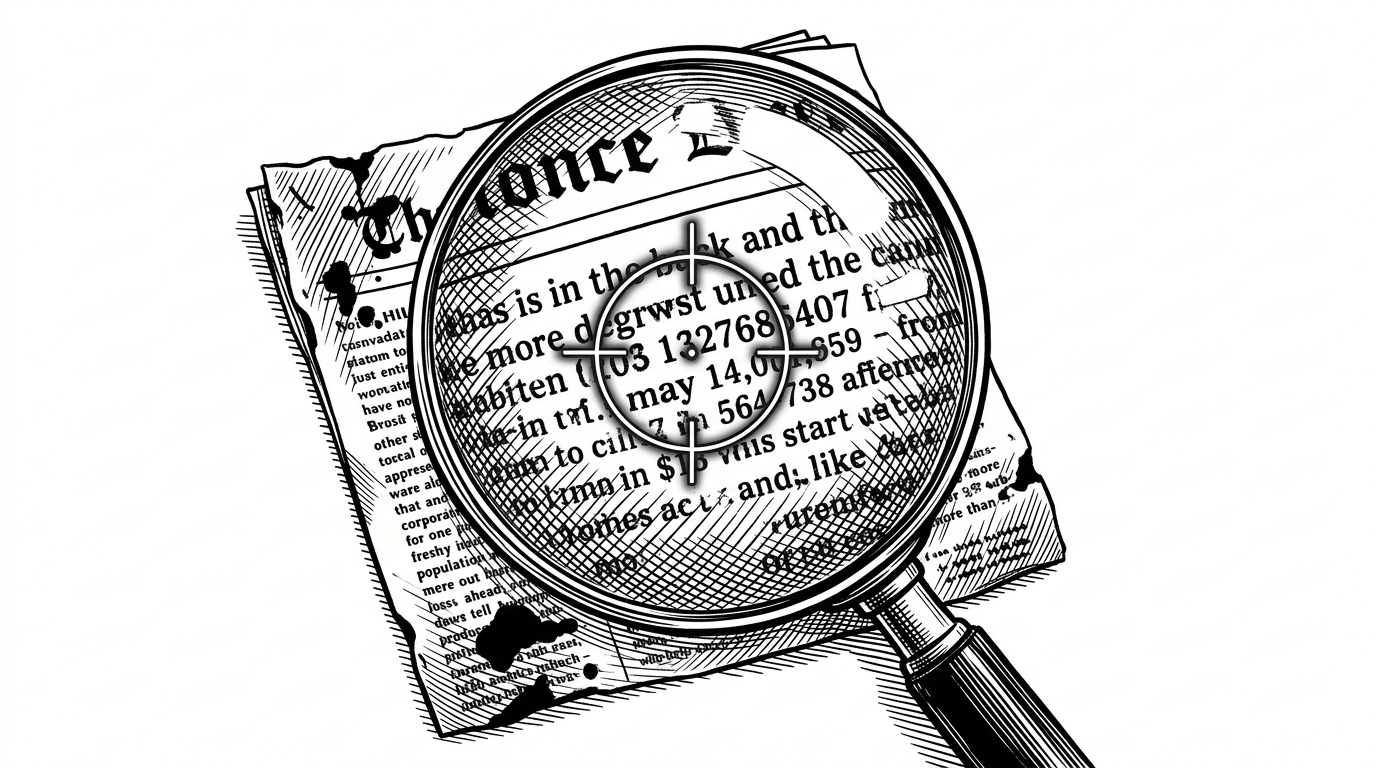
The smartest component of the AI pipeline is not the prompt. It is the rigorous string formatting that happens before and after the LLM sees the data. The analyze_contracts.py script relies heavily on defensive regex.
The clean_currency function acts as the unsung hero of the extraction process. It normalizes messy government strings into standard floats, handling multiple decimal points and non-numeric artifacts natively. This deterministic fallback is mandatory when building resilient systems.
def clean_currency(value):
    # Defensive regex to strip OCR artifacts from government financial data
    import re
    cleaned = re.sub(r'[^0-9\.]', '', str(value))
    # Handle multiple decimals caused by bad scans
    if cleaned.count('.') > 1:
        parts = cleaned.split('.')
        cleaned = parts[0] + '.' + ''.join(parts[1:])
    return float(cleaned) if cleaned else 0.0
The Staggered Pipeline
Processing thousands of PDFs requires careful orchestration. The process_contracts.py script implements a StaggeredRateLimiter to prevent OpenAI API throttling. It explicitly holds the queue, allowing exactly 5 documents to pass concurrently.
Cost management is equally critical. The pipeline uses hashlib.md5 to hash document paths, creating a robust local cache. This aggressive caching strategy ensures that documents are never re-processed unnecessarily, preserving API credits.
Rendering the Administrative State
| Feature | Standard AI Parsers | slavingia/va Pipeline |
|---|---|---|
| Rate Limiting | Fails on bulk upload API limits | Staggered concurrency via asyncio |
| Data Quality | Assumes clean Markdown text | Defensive regex for OCR artifacts |
| Cost Management | Re-processes documents on every run | Aggressive hashlib.md5 path caching |
| Deployment | Cloud-only infrastructure | Hybrid router for Azure and general OpenAI |
Beyond extraction, the repository tackles visualization. The org_charts module processes massive HR CSV files to map the federal hierarchy. It calculates maximum depths from the bottom up, piping the structure into a D3.js front-end.
AI as the Ultimate Bureaucrat
The ultimate goal of this tooling is not autonomous execution. It is designed to organize reality so human reviewers can do their jobs faster. The code exists to empower public servants, acting as an intelligent sieve for the administrative state.