Smart-Internship-Placement-Management-System.: Inside SIPMS: The Django Placement Portal That Treats Matching Like a Systems Problem
A clean service layer, role-based access, and profile scoring turn a student internship portal into a surprisingly disciplined hiring workflow.
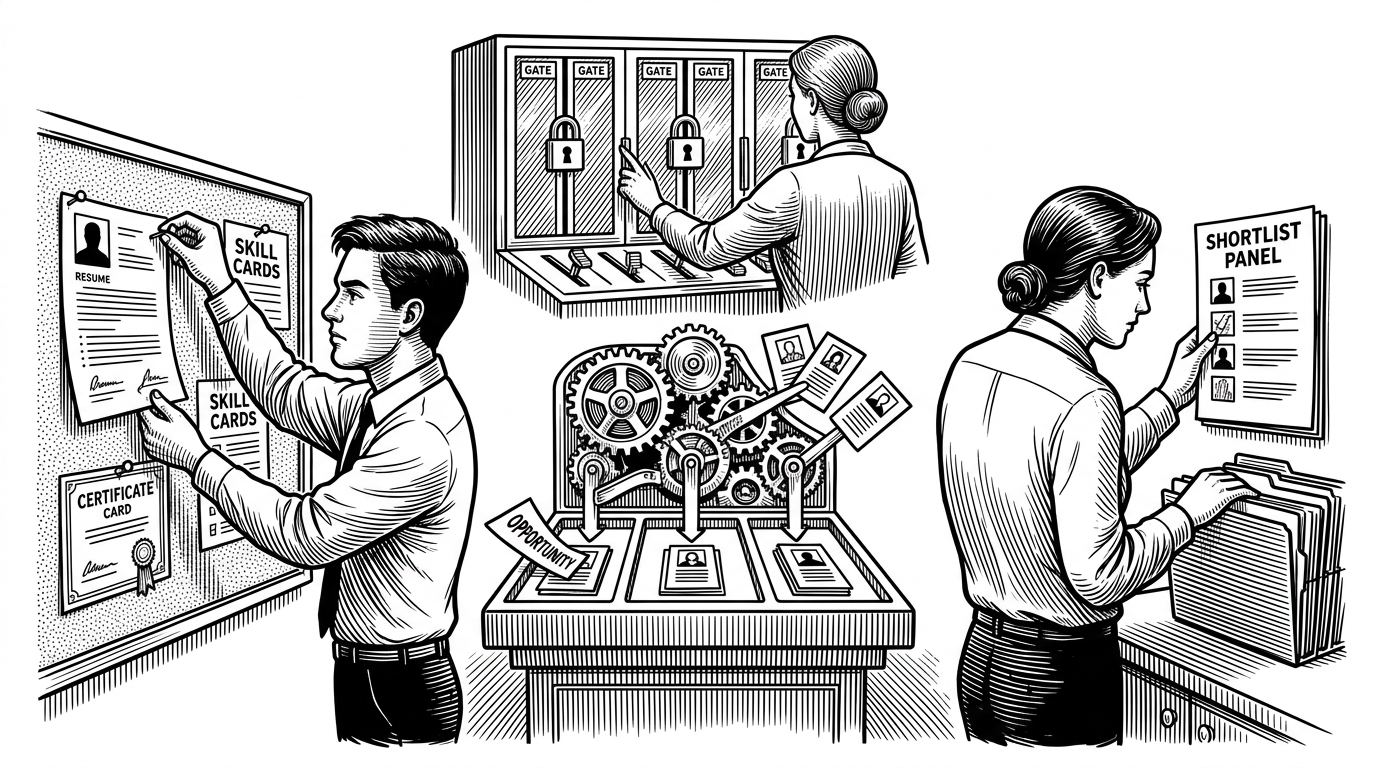
- SIPMS is most interesting because it uses small, readable rules to make a placement workflow feel intelligent instead of bloated.
- Its service layer turns profile data, resumes, and skill overlap into testable matching signals without burying logic in views.
- The application model is disciplined enough to represent jobs and internships cleanly while preventing ambiguous or duplicate submissions.
- RBAC is doing product work here, because the same system becomes safer and clearer when each role only sees the paths it should follow.
Most placement portals are glorified bulletin boards. SIPMS is closer to a workflow engine with opinions. It has to serve students, recruiters, and admins without letting any one of them break the system for the others.
The portal that does more than list jobs
The repo frames itself as a student internship and placement management system, but the useful mental model is a three-sided marketplace. Students bring profiles and resumes, recruiters bring openings, and admins keep the whole thing coherent. That means the system is doing two jobs at once: matching people to opportunities and enforcing rules around access and data integrity.
The Student Internship Placement Management System (SIPMS) is a web-based application designed for the training and placement department of our college. The system provides a secure and efficient platform for students to upload and manage their personal and educational information.
That description is accurate, but it undersells the architecture. The interesting part is not the form-filling. It is the way the repo converts student data into placement signals and then routes those signals through role-specific workflows.
The clever part lives in services, not views
# backend/students/services.py
# The pattern is the point: keep matching logic in pure functions.

def calculate_profile_completion(student):
    weights = {
        "resume": 0.20,
        "skills": 0.15,
        "education": 0.15,
        "projects": 0.20,
        "experience": 0.15,
        "certifications": 0.15,
    }
    score = 0
    for field, weight in weights.items():
        if getattr(student, field, None):
            score += weight
    return round(score * 100, 2)


def recommend_opportunities(student, opportunities):
    owned = set(student.skills.values_list("name", flat=True))
    recommendations = []
    for opportunity in opportunities:
        required = set(opportunity.skills.values_list("name", flat=True))
        match_percent = (len(owned & required) / len(required) * 100) if required else 0
        recommendations.append((opportunity, round(match_percent, 2)))
    return sorted(recommendations, key=lambda item: item[1], reverse=True)
This is the right kind of intelligence for a system like this. It is explainable, easy to test, and cheap to reason about. More important, it stays separate from request handling, which keeps the views thin and the rules reusable.
The traditional manual approach to managing internship placement is time-consuming and error- prone, as it involves handling large amounts of data and communicating with multiple stakeholders. To address these challenges, web-based internship placement management systems have been developed in recent years.
One application model, two listing types, zero ambiguity
The best data model decisions are the ones that remove ambiguity before it reaches the user. SIPMS treats jobs and internships as distinct listing types, but the application flow still stays disciplined: one application, one target, one meaning. That keeps recruiter queues clean and prevents ghost records that look valid in the UI but fail under the hood.
| System type | Primary audience | Matching logic | Permission model | Architecture quality | Best fit |
|---|---|---|---|---|---|
| SIPMS | Students, recruiters, admins | Heuristic profile scoring and skill overlap | Explicit Django role permissions | Modern Django plus React, TypeScript, DRF | University placement cells that want a self-hostable workflow |
| Generic placement portal | Students and staff | Usually simple search and filters | Often coarse admin flags | Frequently monolithic | Basic listing and announcement needs |
| Older PHP and MySQL student project | Students and staff | Usually manual or thin logic | Often page-level checks | Tightly coupled and harder to extend | Small internal deployments |
| Enterprise ATS or career platform | Large employers and universities | Advanced ranking, compliance, scheduling | Deep enterprise permissions | Mature but heavyweight | High-volume institutional hiring |
SIPMS is not trying to beat a commercial ATS at scale or depth. It sits in a more useful middle ground: specialized enough for a university placement cell, modern enough to be maintainable, and small enough to understand.
Three roles, three views of the same system
The access-control layer is doing more than blocking bad requests. It changes what each user believes the product is for. Students see opportunities and progress, recruiters see applicants and postings, and admins see the control plane that keeps the rest honest.
Why the stack feels production-minded
This repo reads like a team that cared about boundaries. Django REST Framework handles the backend API, React and Vite keep the frontend quick, TypeScript adds contracts where the UI needs them, and JWT auth keeps session handling explicit. On the backend, `select_related` and `prefetch_related` signal a real awareness of query costs, not just happy-path functionality.
// frontend/src/services/portalService.ts
// Thin API wrappers keep UI components from knowing transport details.

export async function fetchOpportunities(role: 'student' | 'recruiter') {
  const endpoint = role === 'student' ? '/api/student/opportunities/' : '/api/recruiter/opportunities/';
  const response = await api.get(endpoint);
  return response.data;
}

export async function submitApplication(payload: { jobId?: number; internshipId?: number }) {
  return api.post('/api/applications/', payload);
}
That is the kind of boring that pays off. When the frontend talks through service functions instead of reaching straight into endpoints, the application becomes easier to change, easier to test, and easier to reason about.
What this repo is really competing with
| System type | Primary audience | Matching logic | Permission model | Architecture quality | Best fit |
|---|---|---|---|---|---|
| SIPMS | University placement cells | Readable heuristics and explicit rules | Role-based Django permissions | Strong for a small team | Specialized campus workflow |
| Handshake-style platform | Universities and employers | Enterprise ranking and scheduling | Deep enterprise governance | Very mature | Large institutional programs |
| Generic open-source portal | Schools and departments | Basic filters or manual review | Often shallow | Mixed quality | Simple listing systems |
| Older campus web app | Students and staff | Manual matching | Page-level access checks | Usually dated | Legacy internal use |
The comparison is useful because it clarifies the real lane. SIPMS is not a giant enterprise product and should not be judged like one. Its value is that it offers a focused, self-hostable pattern for modern campus placement workflow design.
Why this matters as a template
SIPMS is worth studying because it makes the hidden rules visible. It isolates business logic, encodes constraints in the model, uses permissions as product design, and keeps the frontend type-aware without overcomplicating the stack. That combination is rare in student-led software, and it is exactly why this repo feels credible.
The broader lesson is simple. Smart software does not always come from adding more intelligence. Sometimes it comes from adding structure, and then letting a small amount of logic do clean work inside that structure.