AIHOT: The Open-Source Newsroom That Turns LLMs Into Editorial Infrastructure
A TypeScript monorepo that uses queues, clustering, release-bound caching, and prompt benchmarks to turn noisy feeds into ranked daily briefings.
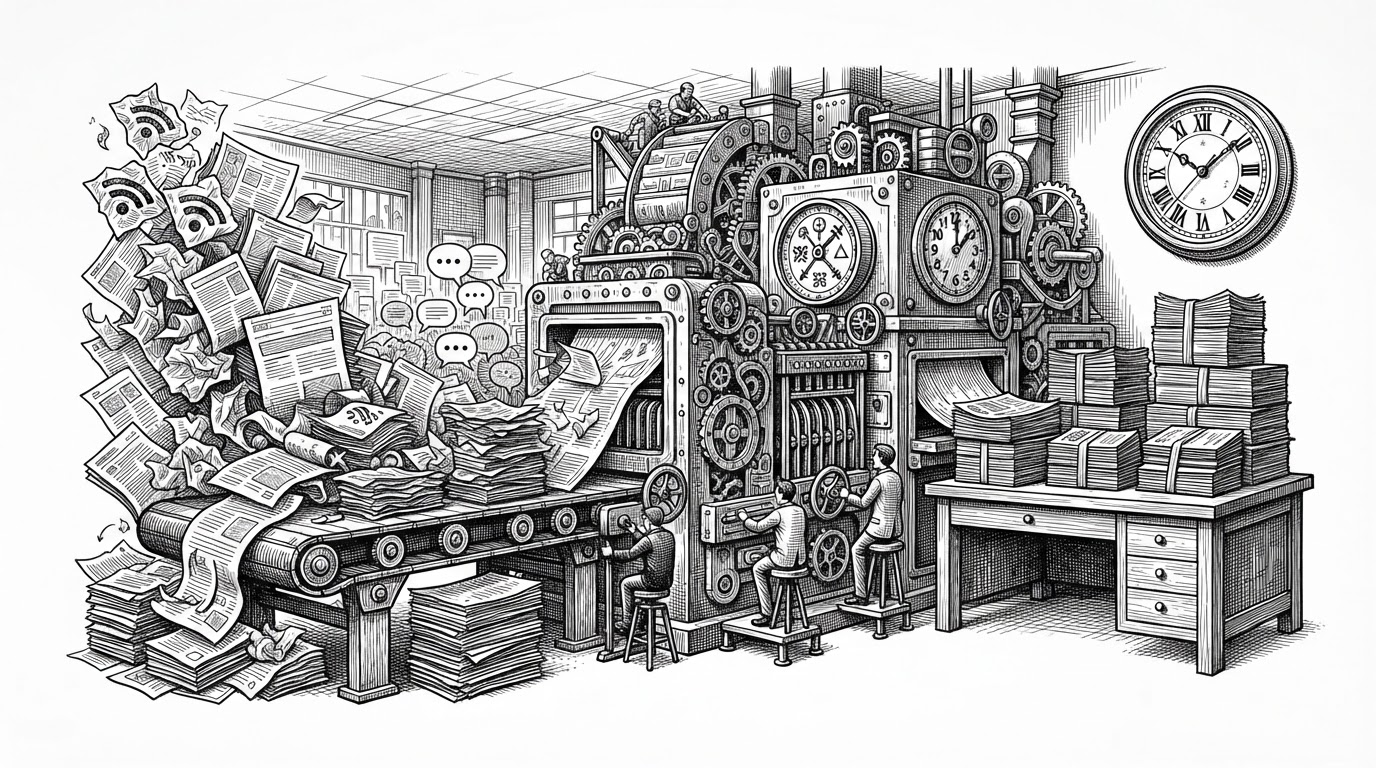
- AIHOT is built like an editorial system, not a news app, because it turns sources into events and events into scheduled briefings.
- Its biggest architectural choice is to keep the web, API, and worker layers separate so LLM work stays off the request path.
- The project’s real intelligence comes from event clustering, deduplication, and decay-weighted hotness instead of article-by-article summarization.
- AIHOT is a template for vertical intelligence products because it packages prompts, queues, and publication logic into one self-hostable stack.
The newsroom, not the bot
AIHOT looks like a news product, but its real subject is editorial automation. It takes in a noisy stream of sources, scores them, clusters related coverage into events, and publishes timed briefings that feel curated rather than generated.
That difference matters. A summarizer answers what does this say?. AIHOT asks what deserves attention, what belongs together, and when should it be published? Those are newsroom questions, not chatbot questions.
这个月活百万的AI热点站AIHOT,正式开源了。采集流程、精选评分、聚簇机制,连生产环境里的全部Prompt,能开源的都开源给大家了。
A monorepo built like a production system
The repo is a TypeScript monorepo split around the work that actually has to happen: collection, orchestration, serving, and presentation. `apps/api` handles the Fastify layer, `apps/worker` runs scheduled jobs, `apps/web` renders the UI, and shared packages keep contracts and backend logic aligned.
That shape is the point. The repository does not organize itself around pages or prompts. It organizes itself around the editorial workflow: ingest, screen, cluster, rank, publish.
// web calls the API, not the database
const API_BASE = process.env.API_BASE_URL || 'http://127.0.0.1:3001';

export async function apiGet(path: string) {
  const res = await fetch(`${API_BASE}${path}`, {
    headers: { accept: 'application/json', 'x-aihot-ssr': '1' }
  });
  return res.json();
}
The web app never touches the database
One of the cleanest decisions in the repo is also one of the easiest to miss: the web app does not talk to PostgreSQL directly. Server-side rendering fetches from the internal API over loopback instead.
That gives AIHOT a sharper boundary. The API becomes the source of truth, caching and policy live in one place, and the web layer can stay focused on rendering. It is a small architectural move with big consequences for deployability and safety.
| Approach | What it buys you | What it costs | Where AIHOT lands |
|---|---|---|---|
| Direct DB access from web | Fewer hops | Tight coupling and messy boundaries | Avoided |
| Loopback SSR through API | Clean separation and policy reuse | One extra internal request | Used |
| BFF-style gateway | Convenient aggregation | Can become a second app to maintain | Close in spirit |
The real engine runs on time, not on demand
AIHOT does not wait for a user request to do the hard work. Scheduled jobs sweep content, translate and shape it, compute hot rankings, and publish reports on a cadence. The system behaves like a newsroom clock.
That rhythm is crucial. LLM calls are expensive and slow, so the worker layer absorbs them in the background. The user-facing app sees finished editorial output, not half-built computation.
This is where the repo stops looking like a content app and starts looking like operations software. The timing is part of the product.
Hotness is computed at the event level
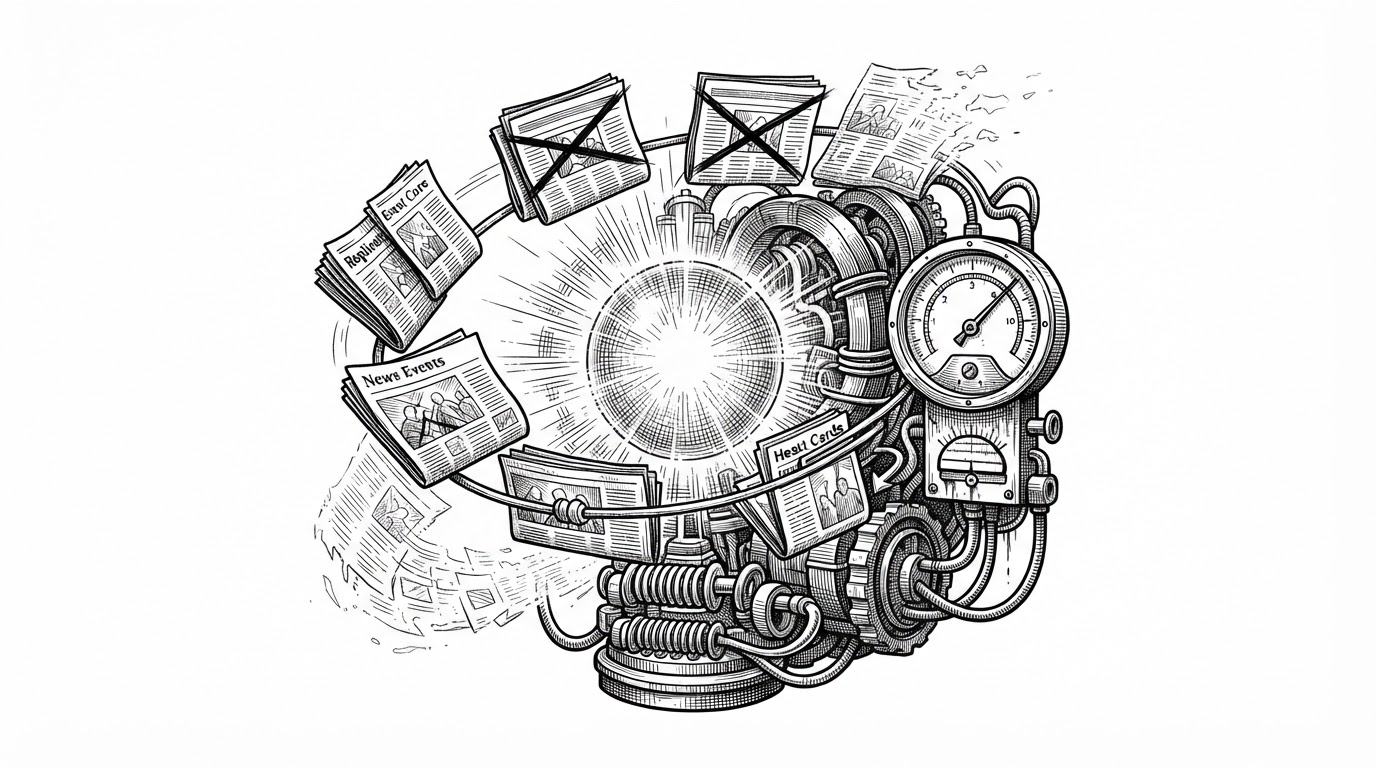
This is the conceptual heart of AIHOT. It does not rank article volume as a proxy for importance. It groups coverage into an event, suppresses duplicates, and lets time decay older signals so the ranking reflects editorial weight instead of raw chatter.
That shift from article-level to event-level judgment is what makes the product feel intelligent. It is also what makes it hard to fake with a simple RSS reader and a prompt.
Why this beats a plain RSS stack
| Approach | Strength | Blind spot | AIHOT's advantage |
|---|---|---|---|
| Plain RSS aggregation | Broad collection | No selection logic | Adds screening and ranking |
| Semantic search | Flexible retrieval | Search is not publication | Turns retrieval into briefing output |
| Generic LLM summarizer | Fast prose | No state or cadence | Wraps LLMs in queues and release timing |
| Human-curated tech site | Strong taste | Manual scaling limits | Automates editorial judgment |
AIHOT sits between tooling and media. It collects like an aggregator, reasons like a lightweight newsroom, and publishes like a vertical intelligence product.
That is why the project is more interesting than a summarization demo. It is a self-hostable blueprint for turning a model into a publication pipeline.
What the repo says about vertical intelligence
AIHOT suggests a larger pattern. The next wave of useful AI products may not be chat interfaces at all. They may be pipelines that encode editorial policy, cost control, and publication timing around a model that never appears to the end user.
That framing is valuable for founders and product teams. If your domain has messy signals, repeated coverage, and a recurring briefing rhythm, the product is probably not a better prompt. It is a better operating system for judgment.