LexAI-AI-Courtroom-Debate-Simulator: LexAI: The Courtroom Simulator That Turns Argument Into a State Machine
A lean Node, MySQL, and vanilla JS stack coordinates judge, counsel, and advisor agents into a structured legal debate system that remembers, scores, and teaches.
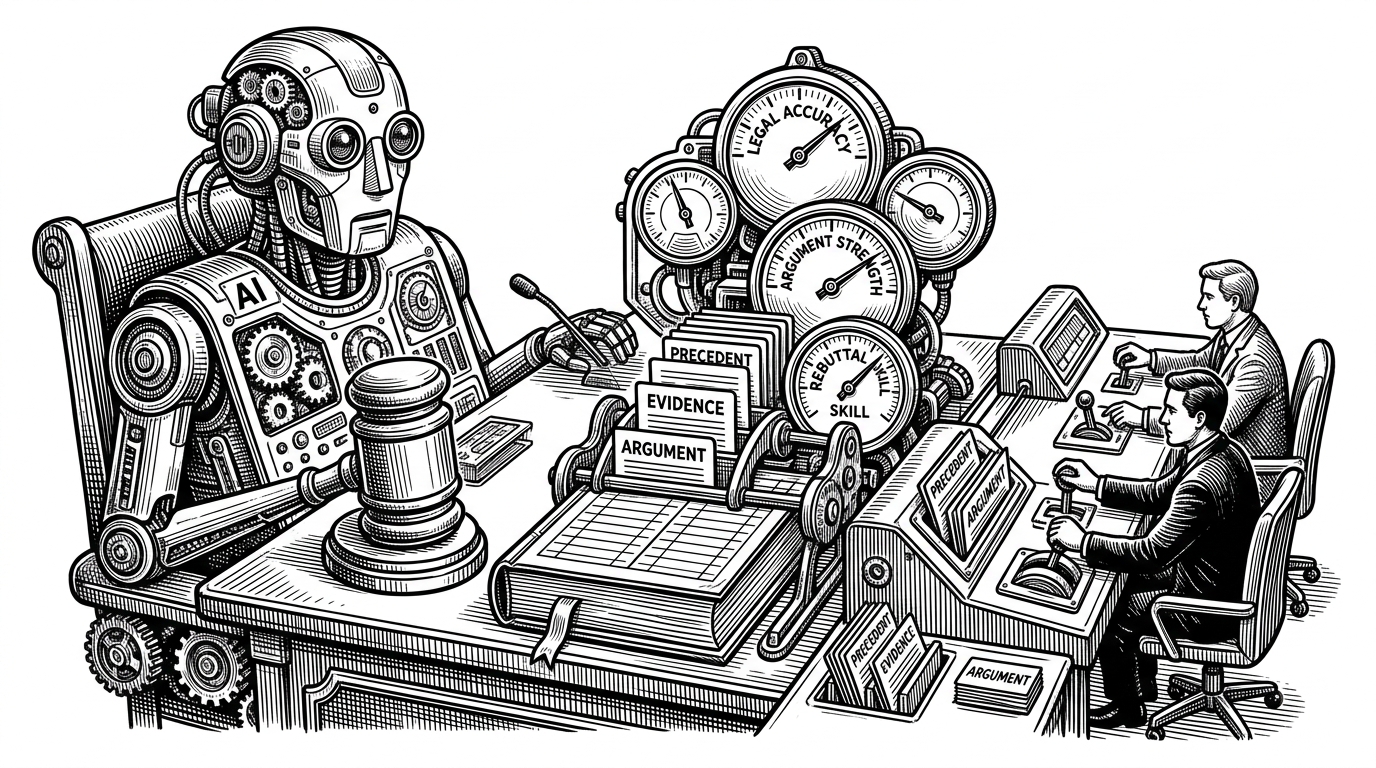
- LexAI is interesting because it treats legal debate like software state, not conversation.
- The app makes a stateless model behave by storing each turn, reconstructing session context, and forcing structured JSON outputs.
- Its three-role design turns judgment into feedback, which makes the simulator feel more like a teaching tool than a chatbot.
- A plain Node, MySQL, and vanilla JS stack is enough when the product’s real innovation lives in workflow, memory, and scoring.
LexAI-AI-Courtroom-Debate-Simulator does not try to be a clever legal chatbot. It tries to be a legal process. That distinction changes everything: the app does not just answer, it stages a dispute, preserves the transcript, grades the argument, and feeds the result back into the next round.
Introducing LexAI - your autonomous open-source debate simulator. Witness AI agents lock horns, refine arguments, and present compelling cases with unparalleled precision.
Not a Chatbot, a Debate Engine
The easiest way to miss LexAI is to file it under “AI app.” It is more specific than that. It splits a single dispute into distinct roles, then makes each role contribute to a structured legal loop: user argument, judge response, advisor hint, score update, next turn.
That is why the project feels different from a normal assistant. A chatbot tries to be helpful in one stream of text. LexAI separates intent, opposition, and instruction. The result is closer to a simulator than a conversation window.
The Courtroom Is a Workflow
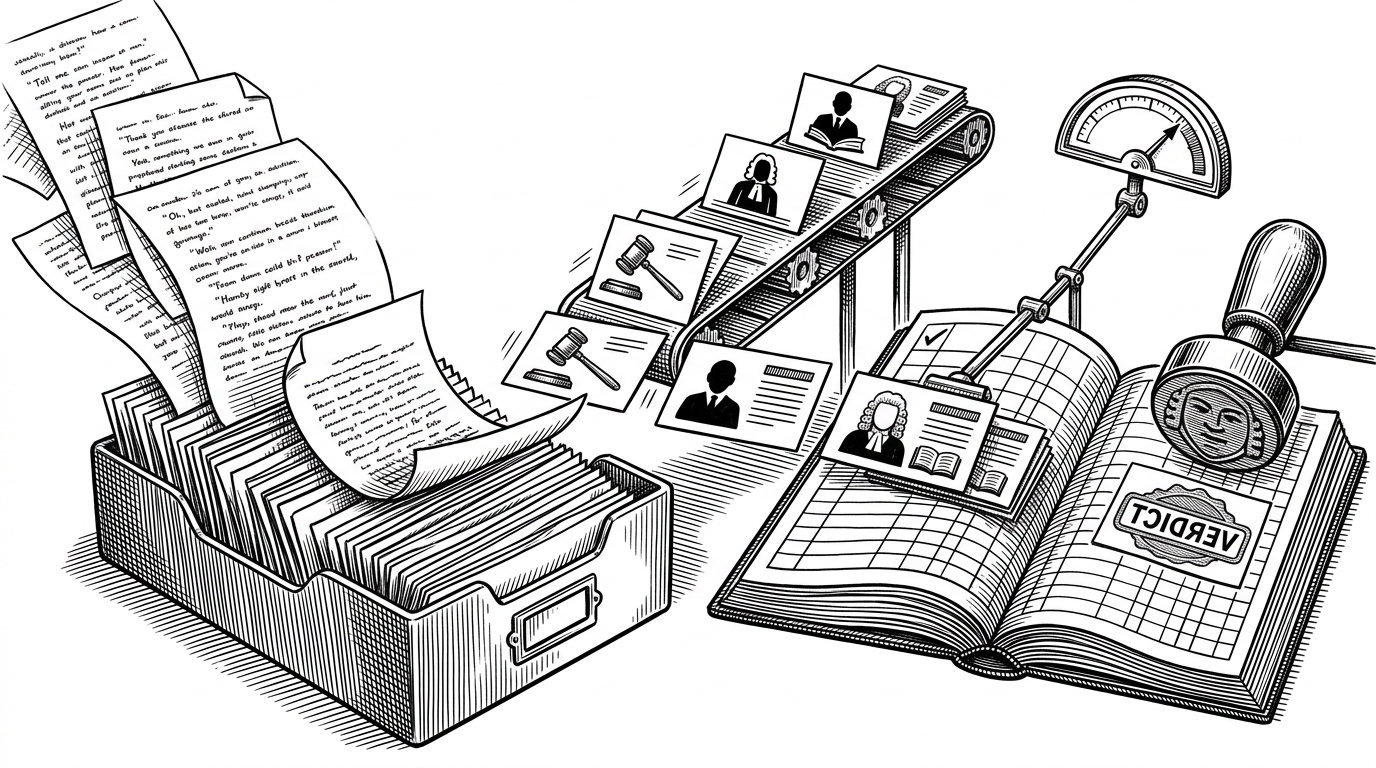
The user journey is simple on the surface. A case is loaded, a round begins, the user argues, the judge responds, and the system scores performance across multiple dimensions. Underneath, each turn is written back into session history so the next prompt is not blind.
This matters because the model is not trusted to remember on its own. The app supplies memory from the outside. That makes the simulation stable enough to teach from, instead of drifting into generic legal talk.
How LexAI Keeps a Stateless Model Honest
The technical core is constraint. LexAI’s AI layer uses role-specific prompts and a strict JSON response format, so the output can be parsed, stored, and reused without fragile text scraping. That is the difference between a demo and a system.
async function callJsonCompletion({ prompt, schema }) {
  const response = await openai.chat.completions.create({
    model: "gpt-4o-mini",
    messages: [{ role: "user", content: prompt }],
    response_format: { type: "json_object" }
  });

  return JSON.parse(response.choices[0].message.content);
}

async function loadSessionContext(sessionId) {
  const session = await getSession(sessionId);
  const caseData = await getCase(session.case_id);
  const transcript = await getTranscript(sessionId);

  return {
    caseContent: caseData.content,
    history: transcript,
    currentRound: session.current_round
  };
}
The important move is not the specific model. It is the shape of the contract. The backend asks for structured fields, not prose, then writes those fields into the database as the source of truth.
That lets the next prompt rebuild context from durable records. In practice, the app manufactures memory by joining session data, case data, and transcript history before every new turn.
The Advisor Whisper Is the Secret Sauce
LexAI’s three-role design is what keeps the experience from collapsing into a generic duel. Judge and counsel are adversarial. Advisor is supportive. That split creates a teaching loop, not just a win-or-lose contest.
The advisor pattern is especially useful because it changes the emotional tone of the app. The user is not only challenged. They are coached. That makes the simulator feel closer to a training environment than a chat interface pretending to be a courtroom.
| Role | Behavior | Output | Why it matters |
|---|---|---|---|
| Judge | Evaluates the exchange | Scores and feedback | Creates accountability |
| Counsel | Pushes the opposing case | Argumentative response | Forces rebuttal |
| Advisor | Guides the user | Strategic hints | Turns debate into learning |
Why the Schema Matters
LexAI’s database is not just storage. It is the memory system. The transcript, the round scores, and the user stats rollup all serve a single purpose: preserve the debate as a sequence of state changes, not an amorphous chat log.
That matters because stateful products need more than message history. They need normalized records that can support dashboards, scoring, and future context reconstruction. In LexAI, the schema is part of the product, not an implementation detail.
| Table | Job | What it stores | Why it is useful |
|---|---|---|---|
| arguments | Transcript history | Role, content, round | Rebuilds the debate |
| round_scores | Performance tracking | Argument strength, legal accuracy, rebuttal score | Makes feedback explicit |
| user_stats | Rollup metrics | Totals and strongest topic | Supports the dashboard |
| sessions | Case state | Current round and session metadata | Keeps the simulation moving |
A Lean Stack With Strong Opinions
The stack is plain in a good way. Node and Express handle the API. MySQL holds the state. JWT and bcrypt cover auth. Vanilla JavaScript powers the frontend. Nothing here is decorative, and that restraint helps the product stay legible.
That choice also signals a product philosophy. LexAI is not chasing framework complexity. It is optimizing for a narrow workflow where the interesting problems are prompt control, persistence, and feedback. A smaller stack makes those trade-offs easier to see.
Where It Sits in the Landscape
LexAI is narrower than a general agent framework and more educational than a commercial legal product. It is not trying to solve every agent problem, and it is not trying to replace legal research tools. It is trying to simulate argument with enough structure that a user can improve inside the loop.
| Tool | Primary purpose | Strength | Weakness relative to LexAI | Best use case |
|---|---|---|---|---|
| LexAI | Courtroom debate simulation | Role-based scoring and memory | Narrower domain | Training, demos, experimentation |
| LangChain | LLM application orchestration | Flexible building blocks | Not opinionated about courtroom flow | General AI app development |
| AutoGPT | Autonomous task execution | Broad agent experimentation | Too open-ended for structured debate | Agent research and prototypes |
| Casetext / CoCounsel | Legal research assistance | Practical practitioner workflows | Not a simulation environment | Professional legal work |
| Generic chatbot | Open-ended conversation | Easy to use | No persistent courtroom structure | Casual Q&A |
That comparison is the point. LexAI is not trying to win on breadth. It wins on specificity. By narrowing the interaction to a courtroom workflow, it can teach something the broader tools usually leave implicit.
Why This Pattern Scales Beyond Law
The real lesson here is portable. Any serious LLM product that needs progression, evaluation, and memory can borrow the same pattern: separate roles, constrain outputs, persist each turn, and score on dimensions that users can act on.
That applies to training systems, review tools, simulations, and decision support products. LexAI is interesting because it shows how far a small stack can go when the workflow is the product and the model is only one component of it.