VGOT23/Job_Application_Tracking Turns a Job Tracker Into a Resume Reader
A MERN stack app that tracks applications, parses uploaded PDFs, and turns basic keyword frequency into a useful ATS lens.
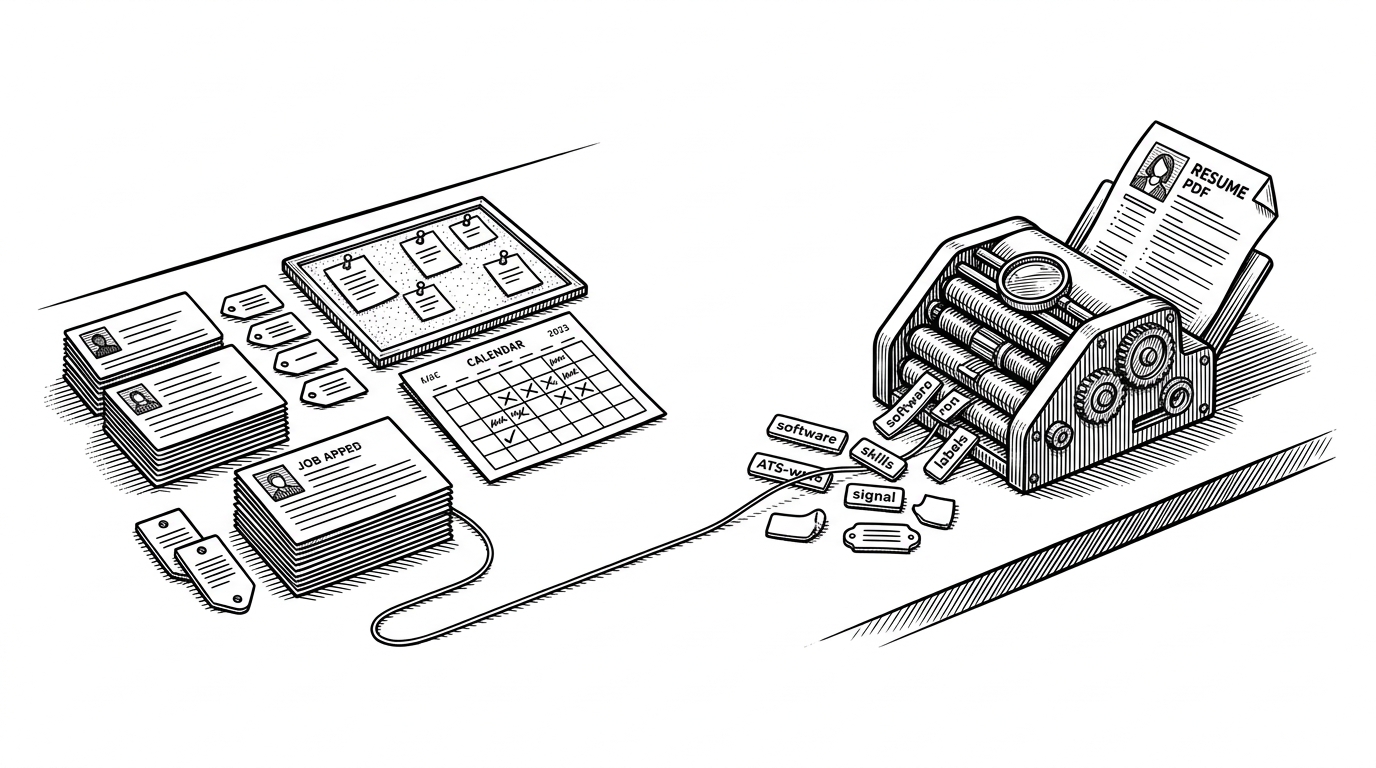
- The repo’s real hook is the resume pipeline, which turns uploaded PDFs into keyword signal instead of treating documents as dead attachments.
- Its backend feels unusually mature for a personal tracker because the service layer, validation, ownership checks, and indexing are shaped around real use.
- The frontend keeps authentication quiet and centralized, so the app behaves like a coherent product instead of a pile of screens.
- In the job-search tooling landscape, it lands between polished SaaS trackers and generic DIY boards, with more intelligence than a spreadsheet and more control than a subscription app.
The Job Tracker That Reads Your Resume
Most job trackers stop at status columns. This one goes a step further: it reads the resume you upload, extracts text from the PDF, filters the noise, and counts the terms that matter. That makes the app less like a static checklist and more like a small ATS feedback loop.
That is the important shift. The tracker is useful because it ties application management to document analysis, so the user is not just logging outcomes. They are looking at the content of the resume itself and asking whether it matches the market they are applying to.
A Personal Tool Built Like a Real App
The repository looks like a self-directed project, but it is not assembled like a toy. The codebase is split cleanly between backend and frontend, with services, controllers, middleware, models, and React state kept in separate lanes. That structure matters because it lets a small app behave like a serious one.
The stack is familiar MERN territory. MongoDB and Mongoose handle persistence, Express routes the requests, React and Vite power the UI, JWT handles auth, and `pdf-parse` does the heavy lifting for resume analysis. Nothing here is exotic, which is part of the appeal. The project shows how far disciplined basics can go.
The Resume Pipeline
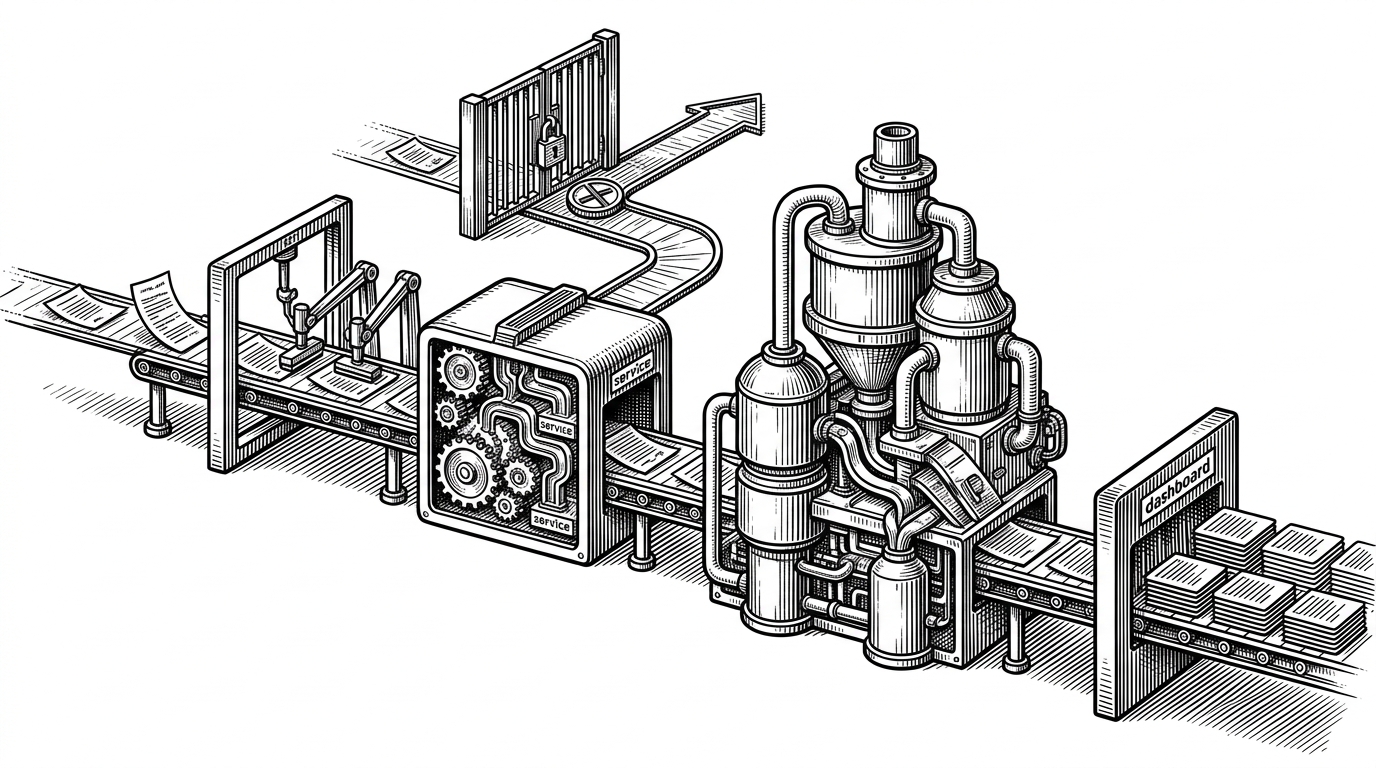
The standout feature starts with a PDF upload and ends with a ranked list of terms. The backend uses `multer` for file handling, `pdf-parse` to pull raw text from the document, and a keyword extraction utility that strips common stop words before counting term frequency. The result is a practical summary of what the resume emphasizes.
That flow is simple, but it is also revealing. A `Set` for stop words makes filtering efficient, and the frequency pass turns unstructured text into something a user can act on. It is not full NLP. It does not need to be. For a job seeker trying to spot ATS-heavy language, a lightweight signal is enough.
const STOP_WORDS = new Set(['the', 'and', 'with', 'for', 'to', 'of']);

function extractKeywords(text) {
  const words = text
    .toLowerCase()
    .replace(/[^a-z0-9\s]/g, ' ')
    .split(/\s+/)
    .filter(Boolean)
    .filter(word => !STOP_WORDS.has(word));

  const frequency = {};
  for (const word of words) {
    frequency[word] = (frequency[word] || 0) + 1;
  }

  return Object.entries(frequency)
    .sort((a, b) => b[1] - a[1])
    .slice(0, 10);
}
Why the Backend Feels Mature
The backend avoids the usual trap of stuffing everything into controllers. Business logic lives in services, which makes the app easier to test and easier to reason about. That choice shows up in the way job queries are built, how stats are aggregated, and how access is checked before a record is returned.
The maturity signal is in the details. Validation chains protect routes, centralized error handling keeps failure paths consistent, and compound indexing on job records matches the access pattern of the dashboard. It is the kind of architecture that usually appears after a project has already broken a few times.
| Pattern | Strength | Weakness | Best for | Where this repo differs |
|---|---|---|---|---|
| Thin controllers, service layer | Keeps business logic isolated and testable | Adds a little structure overhead | Apps with more than a few CRUD flows | The job and resume logic are separated cleanly instead of being buried in routes |
| MongoDB aggregation | Fast dashboard summaries in one query | Can be harder to read at first glance | Stats-heavy views | Stats are computed at the database layer, not in the UI |
| Ownership checks and RBAC | Prevents cross-user data leaks | Requires discipline across the stack | Multi-user tools | Personal records are still handled with access boundaries |
| Route validation | Rejects bad input early | Needs maintenance as forms evolve | Any public-facing form flow | The app treats validation as part of the architecture, not an afterthought |
The Frontend Keeps Auth Invisible
The React side follows the same discipline. Auth lives in context, Axios attaches the token through an interceptor, and the app verifies session state on load instead of forcing each page to reinvent the same logic. That makes the UI feel coherent even though the underlying auth flow is doing real work.
This is good product design, not just clean code. Users should not have to think about token plumbing. They should log in, land on the dashboard, and move through the app without auth becoming a recurring distraction.
// Pseudocode for the auth flow
useEffect(() => {
  api.get('/auth/me')
    .then(({ data }) => setUser(data.user))
    .catch(() => setUser(null));
}, []);

api.interceptors.request.use(config => {
  const token = localStorage.getItem('token');
  if (token) config.headers.Authorization = `Bearer ${token}`;
  return config;
});
Where It Fits in the Job-Search Tooling Landscape
Compared with SaaS trackers like Huntr, Teal, and JibberJobber, this repo is narrower and more hands-on. It does not try to win with polished integrations or broad feature breadth. Instead, it gives one user a custom workflow with resume analysis baked in.
Compared with Trello, Notion, or Airtable, it is more opinionated and more intelligent. Generic tools can be bent into a job tracker, but they do not understand the document side of the problem. This repo does. That is the difference between storing data and interpreting it.
| Tool type | Strength | Weakness | Best for | Where VGOT23/Job_Application_Tracking differs |
|---|---|---|---|---|
| Polished SaaS trackers | Feature-rich, refined UX, broad integrations | Subscription cost and less control | Users who want a turnkey workflow | This repo is lighter, self-owned, and more focused on resume signal |
| DIY boards and databases | Flexible, familiar, easy to start | No built-in intelligence | People who want manual control | This repo adds parsing and keyword extraction instead of only status tracking |
| This repo | Custom workflow plus resume analysis | Less feature breadth than mature products | A technically minded job seeker | It sits between a spreadsheet and a productized platform |
What This Project Suggests About Modern Solo Full-Stack Work
The interesting lesson is not that someone built a job tracker. The lesson is that a small solo project can still carry real product judgment: security, validation, indexing, clean separation of concerns, and a feature that actually changes how the tool is used.
That combination is what makes the repo worth noticing. It is practical without being generic, and structured without feeling overbuilt. In a crowded space of tracker templates, that is enough to stand out.