PageIndex: Teaching RAG to Read the Table of Contents Before It Reads the Page
A vectorless retrieval framework that replaces chunk-and-embed guesswork with hierarchical document maps, reasoning-based navigation, and verification loops for complex PDFs and Markdown.
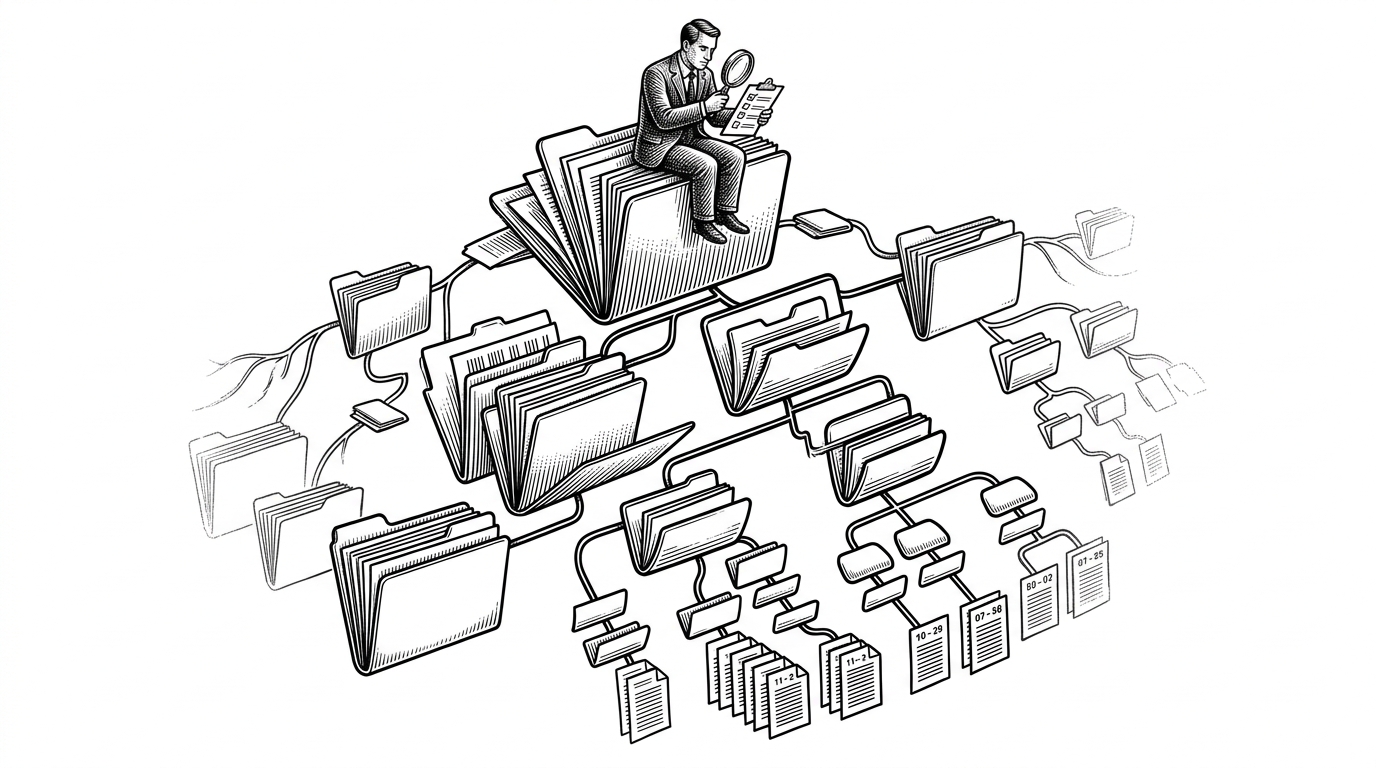
- PageIndex treats retrieval as a reasoning problem, so it starts with document structure instead of embedding every chunk and hoping similarity gets lucky.
- Its main advantage is fidelity on complex PDFs and Markdown, where hierarchy, page boundaries, and section starts matter as much as the words themselves.
- The repo’s real trick is verification, because the table of contents is treated as a hypothesis that must be checked against the page, not a truth to trust blindly.
- PageIndex is not a universal RAG replacement, but it is a sharper tool for high-stakes documents where structure is part of the answer.
Most RAG systems begin with text fragments. PageIndex begins with a map. That sounds like a small design choice, but it changes the whole retrieval game: instead of asking which chunk looks most similar, the system asks which branch of the document tree is actually worth reading.
Why vectors are the wrong first move
Chunk-and-embed works when the answer lives in a short paragraph and the document is forgiving. It breaks down when the source has structure, page numbering, section headers, tables, and long dependency chains between ideas. In those cases, similarity can find a related passage without finding the right passage.
| Approach | How it retrieves | Strength | Weak spot | Best fit |
|---|---|---|---|---|
| Chunk-and-embed RAG | Splits text into chunks, embeds them, and ranks by semantic similarity | Simple and fast to wire up | Ignores document structure and page logic | Short, mostly linear text |
| General document ETL | Extracts text and layout into a normalized pipeline | Broad file support | Often stops at parsing, not retrieval reasoning | Ingestion and cleanup |
| PageIndex | Builds a hierarchical document map, then navigates and verifies branches | Preserves structure during retrieval | More orchestration than a vector lookup | Complex PDFs, manuals, filings, and Markdown trees |
PageIndex looks awesome for indexing complex PDFs while preserving visual context
PageIndex builds a map before it searches
The core repo is a Python package with a clear division of labor. page_index.py handles PDF structure, page_index_md.py handles Markdown trees, retrieve.py exposes the tools an agent can call, and client.py orchestrates the lifecycle and persistence of an index.
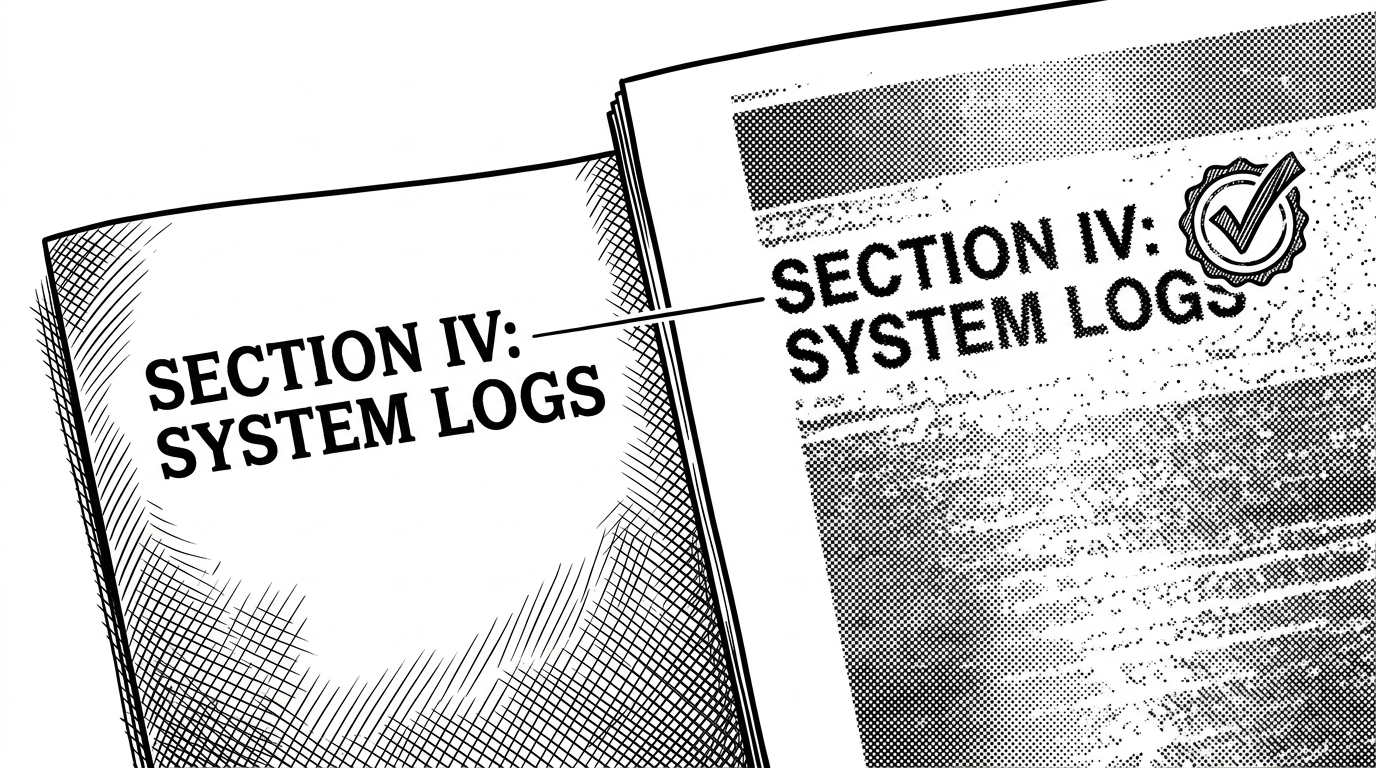
The trick is fuzzy validation, not blind trust
PageIndex’s PDF path is more interesting than a normal parser because it treats structural claims as something that can be checked. The outline says a section starts on a page, but the system still verifies that the title appears there, which helps when OCR noise, formatting glitches, or messy scans make the document slippery.
def verify_section_start(title, page_text):
    return check_title_appearance(title, page_text)

# If the title is present where expected, the branch is valid.
# If not, the tree is adjusted before retrieval continues.
Tree thinning turns Markdown into a usable hierarchy
The Markdown path follows the same philosophy, but with a different mechanism. Headers are parsed into a tree, small nodes are merged upward, and large nodes get summarized recursively. That means the model sees a compressed structure it can reason over, not a wall of raw text stuffed into context.
How the agent actually retrieves content
This is where PageIndex stops being a parser and starts acting like a toolset. The agent calls get_document_structure to inspect the map, then get_page_content only for the pages that matter. The loop is simple in concept, but powerful in practice: search, reason, verify.
| Step | What the agent gets | Why it matters |
|---|---|---|
| Inspect structure | A text-light tree of the document | The agent can plan without spending context on full pages |
| Choose a branch | Relevant section titles and page ranges | Retrieval becomes navigational instead of fuzzy |
| Fetch content | Only the pages the agent actually needs | Context is spent on evidence, not guesswork |
| Verify answer | The retrieved text is checked against the structure | The system reduces false confidence on noisy documents |
What PageIndex is really competing with
PageIndex is not trying to replace every RAG stack. It is competing with the places where generic loaders and vector search lose their footing: financial reports, legal filings, technical manuals, and any document where layout and hierarchy carry meaning. In that niche, preserving structure is not a nice-to-have. It is the retrieval strategy.
| Tool class | What it optimizes | Why PageIndex differs |
|---|---|---|
| Vector-first RAG | Similarity recall | PageIndex optimizes for structural relevance and verification |
| Document intelligence APIs | Extraction accuracy | PageIndex turns extracted structure into an agentic retrieval path |
| Layout-aware loaders | Chunk quality | PageIndex pushes past chunking into reasoning over hierarchy |
Why this matters for agents
The bigger idea is that retrieval can become deliberative. PageIndex is a compact example of that shift: the system does not just fetch text, it helps an agent think about where to look, what to trust, and when to ask for more evidence. That is a better fit for hard documents than one-shot similarity ever was.