resume-book: ACM@UIUC Resume Book: The Campus Recruiting System That Turns PDFs Into Searchable Talent
A dual-auth, AI-assisted platform for students and recruiters, built like a real product rather than a form stack.
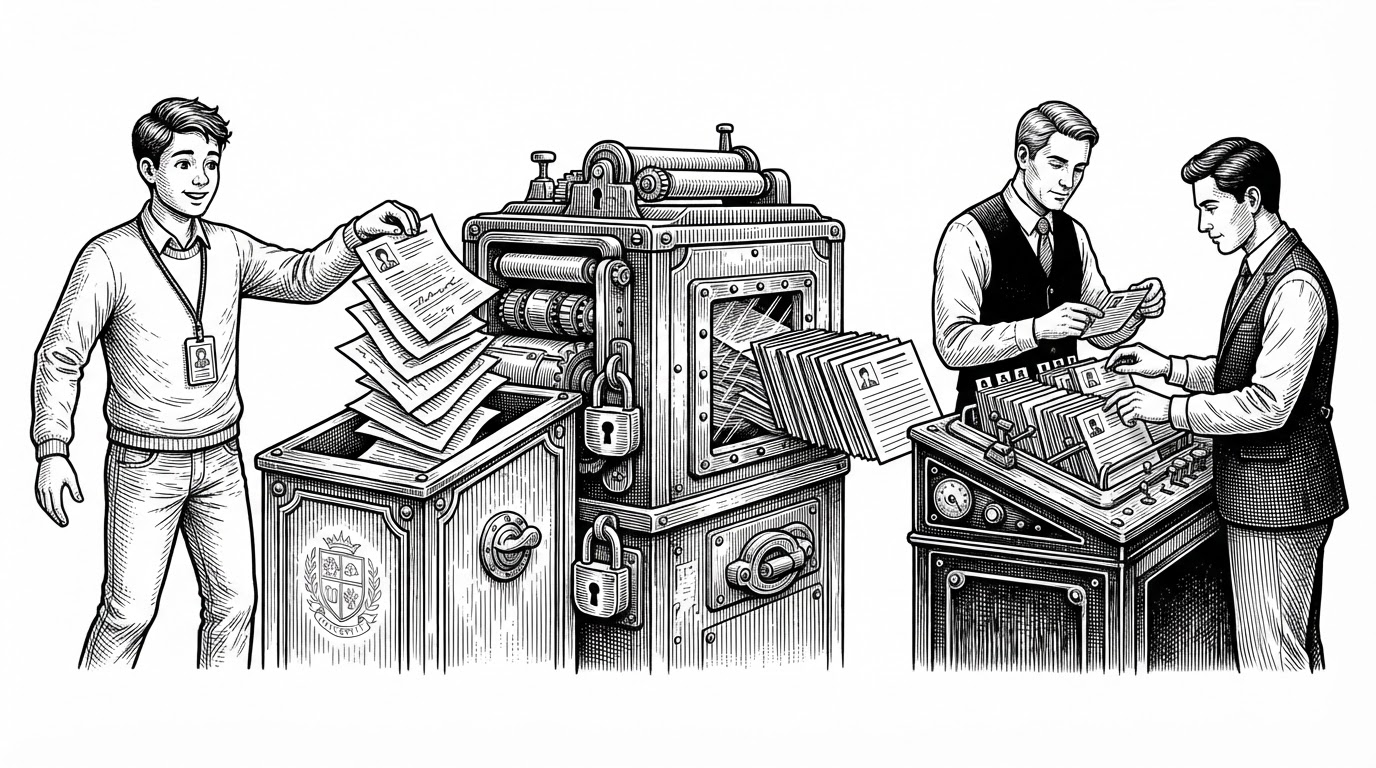
- ACM@UIUC Resume Book is built less like a resume website and more like a controlled recruiting exchange.
- Dual identity providers are not just an auth choice here, they are the product boundary between student access and recruiter access.
- The most important technical move is schema-locked resume parsing, which turns messy PDFs into searchable data.
- The repo feels mature because it treats search, access control, and deployment as one operational system.
Most resume tools help people present themselves. This one helps a campus org manage a closed recruiting pipeline. That difference changes everything, from authentication to data modeling to the way search has to work.
A Resume Site That Behaves Like a Marketplace
The surprise in acm-uiuc/resume-book is not that it stores resumes. It is that it behaves like a tiny recruiting platform with rules, roles, and downstream workflow. Students upload documents, recruiters search a curated pool, and the system keeps those two populations carefully separated.
Resume Book: Bridging the gap between UIUC CS/ECE students and corporate recruiters.
That framing matters because it explains the architecture. The project is not optimizing for personal branding or resume design. It is optimizing for trust, eligibility, and retrieval.
Why ACM @ UIUC Built It This Way
ACM @ UIUC serves a specific community: UIUC CS and ECE students on one side, corporate sponsors on the other. The platform needs to verify who belongs, keep access constrained, and make the sponsor experience fast enough to be useful. That is a very different problem from building a public resume builder.
Resume book access to market yourself to our corporate sponsors.
The product logic is simple once you see it. Students are not just users. Recruiters are not just viewers. Each group has different credentials, different routes, and different expectations.
Two Identity Providers, One App
The heart of the repo is the combined authorizer. It inspects the token issuer, routes Azure AD users to the student path, and routes Kinde users to the recruiter path. In other words, auth is not just protecting the app. It is defining the product surface.
| Layer | Students | Recruiters |
|---|---|---|
| Identity provider | Azure AD | Kinde |
| Primary task | Upload and manage a profile | Search and filter candidates |
| Trust model | Campus membership | Verified external access |
| Main UI | Profile and resume flow | Recruiter search interface |
| Authorization outcome | Student routes only | Recruiter routes only |
From Resume PDF to Structured Student Profile
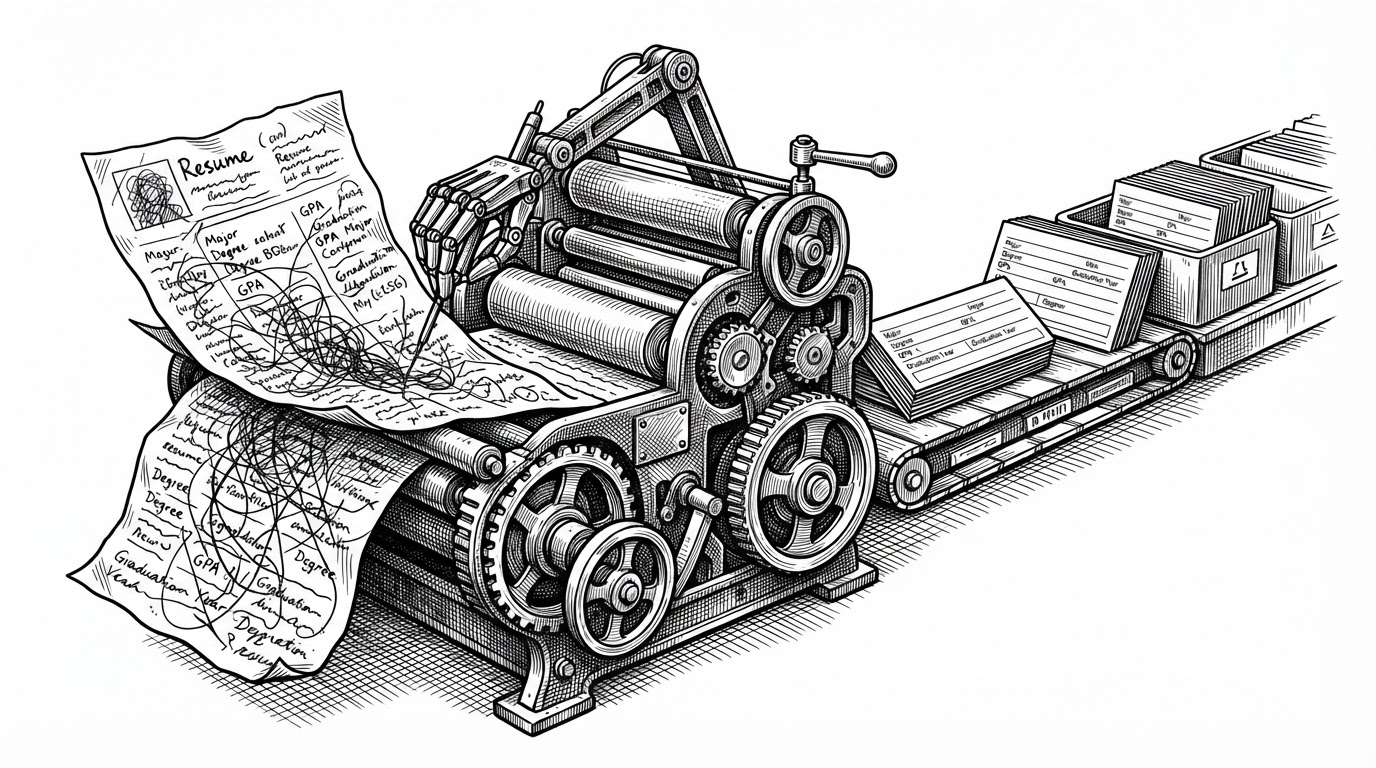
This is the smartest part of the stack. The backend does not try to interpret resume text on the fly for every search. It extracts, normalizes, and stores structured fields first, then lets recruiters query those fields later.
That makes the LLM behave like middleware. The model is not there to impress users. It is there to convert messy human documents into records the database can reason about.
# Simplified shape of the parsing idea
resume_text = extract_text(uploaded_pdf)
profile = llm_parse_to_schema(resume_text)

# profile is expected to match a strict student schema
save_student_profile(profile)
How Recruiter Search Stays Flexible Without Becoming Dangerous
Recruiter search has to feel open ended, but the backend still needs to protect itself from broken queries and injection risk. The repo handles that with dynamic SQL generation and safe parameterization, which gives recruiters filters without turning the app into a string-concatenation mess.
The search layer can combine fields like major, GPA, and graduation year with joins across normalized tables. That is a practical design choice. It keeps the recruiter experience quick while preserving enough structure for precise filtering.
# Conceptual shape of dynamic search generation
conditions = []
params = []

if major_filter:
    conditions.append("majors = ANY(%s)")
    params.append(major_filter)

if min_gpa:
    conditions.append("gpa >= %s")
    params.append(min_gpa)

query = build_safe_query(conditions)
results = db.execute(query, params)
The important detail is not that the query is dynamic. It is that the app lets recruiters search a curated dataset without giving up control over how the query is formed.
Why It Feels More Mature Than a Typical Student Project
The maturity signal is not visual polish. It is operational discipline. The repo includes backend tests, end to end tests, infrastructure code, and even a warmer to reduce Lambda cold starts. That is the footprint of a system expected to work under real usage, not just demo well.
| Maturity signal | What it suggests | Why it matters |
|---|---|---|
| CI and deployment workflows | Repeatable releases | A campus tool that ships like software |
| Playwright and backend tests | User flows and API paths are exercised | Search and auth regressions are harder to ship |
| Infrastructure as code | The environment is part of the product | The system can be rebuilt, not just run |
| Lambda warmer | Latency is a known concern | Recruiter search stays responsive |
That is why the repo reads like internal infrastructure. It is solving a narrow problem, but it is solving it with the habits of a larger engineering org.
What This Replaces, and What It Doesn’t
The nearest comparisons are useful precisely because they are incomplete. Reactive Resume and OpenResume focus on building or parsing resumes. Handshake and LinkedIn focus on broad recruiting marketplaces. ACM@UIUC Resume Book sits between those categories: narrower than a platform, more operational than a tool.
| Project | Primary job | What it is not |
|---|---|---|
| ACM@UIUC Resume Book | A controlled campus recruiting exchange | A public resume builder |
| Reactive Resume | Resume creation and formatting | A recruiter access system |
| OpenResume | Resume parsing and ATS-style formatting | A membership-gated distribution layer |
| Handshake / LinkedIn | Large-scale recruitment networks | A campus-specific curated pool |
That narrowness is the point. The repo is valuable because it solves the exact shape of ACM @ UIUC’s problem, not because it tries to serve everyone.
The Bigger Lesson
The most interesting open-source projects are not always the biggest. Sometimes they are the most specific. This one shows how a student organization can build software that looks and behaves like enterprise infrastructure when the workflow demands it.
Identity, parsing, and search are usually separate concerns. Here they are one system, and that is why the project feels coherent.