LinkedIn_Job_Stats: LinkedIn Job Stats Extension: Two Ways to Expose LinkedIn’s Hidden Job Metrics
A Chrome extension deep-dive into page injection, Chrome DevTools Protocol, and the small UI tricks that make hidden views and applicant counts feel native.
- This repo is really about browser boundaries, not just job search convenience, because it reveals data LinkedIn already serves but does not foreground.
- Its standout move is architectural duality: one path sneaks into the page, while the other asks Chrome’s debugger for the response body directly.
- The extension pairs a fragile browser trick with disciplined product design, so the overlay feels native instead of bolted on.
- Compared with headless scrapers, it favors immediacy and in-browser control over bulk extraction.
The job data LinkedIn keeps behind the curtain
LinkedIn job posts carry signals that matter to candidates: how many people have viewed a role, how many have applied, and how fast interest is building. The extension’s job is simple on paper. It takes those hidden signals and puts them where a job seeker can actually use them.
That is why this project feels bigger than a convenience feature. It is a small browser-native challenge to the default information hierarchy of a massive platform. Instead of asking users to dig for context, it surfaces context in place.
Why this repo has two brains
The repository is unusual because it solves the same problem twice. One implementation stays close to ordinary extension patterns. The other takes the heavier route and attaches Chrome’s debugger to the tab so it can pull network response bodies from the browser itself.
| Mechanism | What it sees | User cost | Robustness | Best fit |
|---|---|---|---|---|
| Standard injection path | Fetch and XHR traffic inside the page’s Main World | Low. No debugger banner, lighter permissions | Good, but more exposed to page and script changes | Polished consumer use |
| CDP debugger path | Network responses through Chrome DevTools Protocol | Higher. The browser shows it is being debugged | Very strong, because it reads browser internals | When reliability matters more than stealth |
That split is the real editorial hook. Most extensions pick one philosophy and live with it. This repo keeps both on the table, which makes the trade-off legible instead of hidden.
Path one: become the page
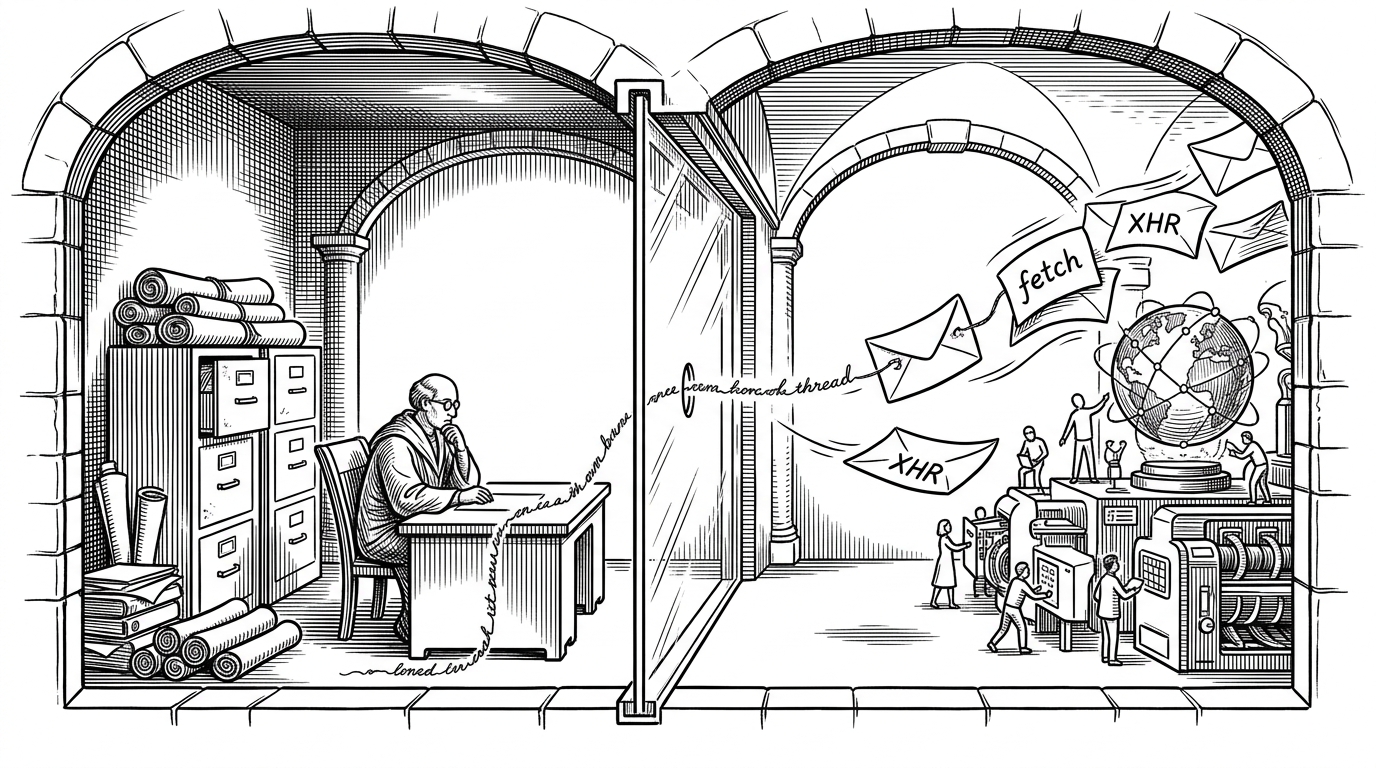
The standard path has to work around Chrome extension isolation. A content script cannot directly reach the page’s global `XMLHttpRequest` or `window.fetch`, so the extension injects a separate script tag into the Main World. Once that code is running where the page runs, it can watch the job endpoint and intercept the response before the UI ever sees it.
const originalFetch = window.fetch;
window.fetch = async (...args) => {
  const response = await originalFetch(...args);
  if (String(args[0]).includes('/voyager/api/jobs/jobPostings/')) {
    const data = await response.clone().json();
    window.postMessage({ type: 'LinkedInJobStatsData', data }, '*');
  }
  return response;
};
The point is not the patch itself. The point is the bridge back to the extension UI. The intercepted payload gets handed off through `postMessage` or a custom DOM event, which keeps the page-world trick and the popup logic cleanly separated.
Path two: become the debugger
The CDP version is the surprise. Instead of guessing when a page script saw a response, the extension listens for `Network.responseReceived` and then asks Chrome for the response body with `Network.getResponseBody`. That is a more direct line to the data, and it is also why the browser has to announce that debugging is happening.
That warning banner is not a footnote. It is the cost of choosing robustness over stealth. The repo makes that cost explicit, which is useful because it turns an implementation detail into a product decision.
The UI makes the hack feel native
The interface is not trying to look futuristic. It tries to disappear into LinkedIn’s visual noise while still being easy to move, read, and reuse. That is why the repository leans on vanilla JavaScript, a glass-like panel, and a cache layer instead of a heavier front-end stack.
class JobStatsCache {
  constructor(ttlMs = 300000) {
    this.ttlMs = ttlMs;
    this.store = new Map();
  }

  get(jobId) {
    const entry = this.store.get(jobId);
    if (!entry) return null;
    if (Date.now() - entry.savedAt > this.ttlMs) {
      this.store.delete(jobId);
      return null;
    }
    return entry.value;
  }

  set(jobId, value) {
    this.store.set(jobId, { value, savedAt: Date.now() });
  }
}
The cache matters because LinkedIn is a noisy surface. If you move between listings and back again, the extension does not need to redraw everything from scratch. It keeps the overlay responsive, which is exactly what you want when the underlying page is already heavy.
What this approach has that scrapers do not
This project sits in a different category from headless scrapers and job aggregators. Those tools are built to collect data at scale. This extension is built to reveal data at the point of decision, in the same browser window where the candidate is already evaluating the role.
Scrape public available jobs on Linkedin using headless browser.
The repository contains messages that I received on LinkedIn, and some Python scripts extracting interesting stats from it.
Those projects are useful, and in some cases broader. But they are working at a different altitude. This repository is more intimate. It stays inside the browser, watches the page’s own traffic, and turns hidden job metrics into a live overlay instead of a dataset.