End-to-end-Medical-Chatbot: End-to-end Medical Chatbot: The RAG Stack That Treats Deployment Like a Safety Feature
A Flask, LangChain, and Pinecone medical assistant that is more interesting for its cold-start handling and guardrails than for its chat UI.
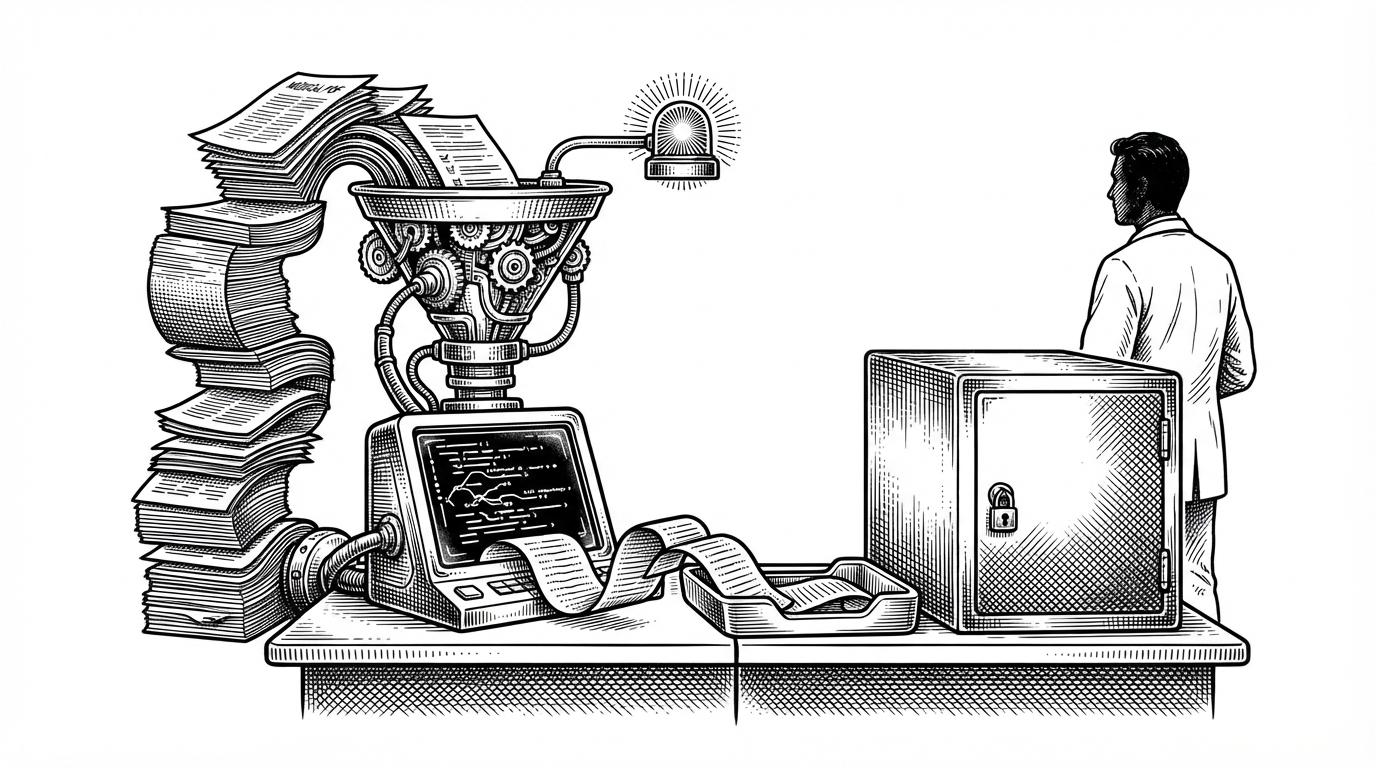
- This repo stands out because it treats readiness, timeouts, and initialization locks as product features, not backend trivia.
- Its medical safety posture is the real differentiator: answers are constrained to retrieved context and refusal is part of the design.
- The pipeline is conventional RAG, but the implementation is disciplined enough to look like a deployment template instead of a classroom demo.
- The move from local model support to Groq shows a practical trade-off: lower latency and easier hosting in exchange for less offline control.
The part most chatbot demos ignore: startup and readiness
Most medical chatbot demos spend their energy on the answer layer. This repo spends real attention on what happens before the first answer. That is the surprise: it treats boot time, readiness, and initialization failure as part of the product surface.
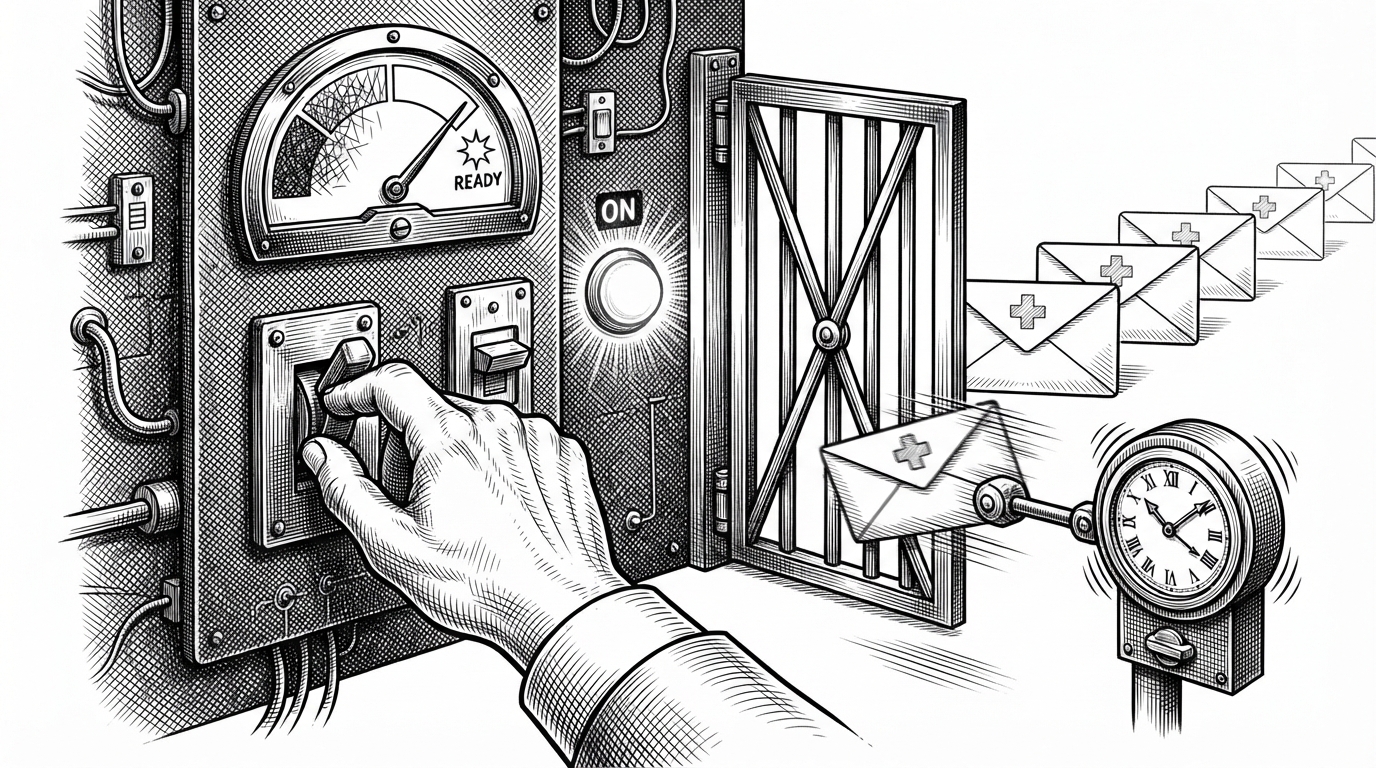
In `app.py`, the chain is initialized eagerly, not lazily on first user traffic. A `threading.Lock` prevents duplicate startup work, and a `/ready` endpoint keeps the app closed until its embeddings and QA chain are ready. On platforms with tight request timeouts, that is the difference between a live service and a dead-on-arrival demo.
Why a medical chatbot needs a harder boundary than a normal RAG app
The safety story lives in `src/prompt.py`. The prompt does not just say “be helpful.” It forces the model to answer only from provided context, say when the context is insufficient, and avoid diagnosis. In a medical setting, that is not a stylistic choice. It is the core boundary that keeps the system from pretending to be a clinician.
Finding → proposed fix → 2-person approval → task assigned → status tracked → audit logged. That's the @usekivora remediation loop. AI spots, queue approves, team executes. End-to-end, not "here's a chatbot, good luck." 5 design partner spots. DM.
| Mode | Grounding | Safety posture | Deployment behavior |
|---|---|---|---|
| Raw chatbot | None | High hallucination risk | Simple to run, hard to trust |
| Generic RAG | Context-based | Better, but uneven | Useful in demos, fragile under load |
| This repo | Context-only with refusal behavior | Explicit non-diagnostic guardrails | Readiness-aware startup and timeout protection |
How the pipeline turns PDFs into grounded answers
The mechanics are classic RAG, but they are assembled with enough care to matter. PDFs are loaded from `data/`, split into chunks with overlap, embedded with a sentence-transformer model, and stored in Pinecone. At query time, the retriever fetches the most relevant chunks and the LLM turns them into a contextual answer.
# Simplified flow from the repo
loader = DirectoryLoader('data/', glob='*.pdf', loader_cls=PyPDFLoader)
docs = loader.load()
chunks = RecursiveCharacterTextSplitter(chunk_size=500, chunk_overlap=20).split_documents(docs)
vectorstore = PineconeVectorStore.from_documents(chunks, embedding=embeddings, index_name=index_name)
qa = RetrievalQA.from_chain_type(llm=llm, retriever=vectorstore.as_retriever())
The interesting part is not any one library. It is the way the pieces are sequenced. `store_index.py` handles vector index setup, `src/helper.py` handles document loading and splitting, and `app.py` assembles the chain eagerly so the service is not improvising under traffic.
The cloud-native choice hidden in the code
The repo shows a practical shift from local model ambition to hosted inference. Its structure still acknowledges local support through `ctransformers`, but the active path uses Groq. That buys lower latency and easier operational fit. It also gives up some privacy and offline control.
| Choice | What it optimizes for | What it costs |
|---|---|---|
| Local model path | Privacy and offline control | Heavier startup and more host variability |
| Groq-backed path | Speed and hosting simplicity | Dependency on an external API |
| Hybrid template | Flexibility during development | More moving parts to maintain |
That trade-off is honest. For a medical assistant template, responsiveness and predictable hosting matter more than proving the code can run entirely on one machine. The repo looks like it was written by someone who has already met a timeout error in production and learned from it.
What this repo gets right for a prototype
A lot of starter repos feel temporary. This one has a more deliberate shape. Type hints, runtime config validation, security headers, a dedicated tests path, and a guarded boot sequence all point in the same direction: someone cared about failure modes, not just a screenshot.
That does not make it enterprise software. It does make it a strong template. If you wanted to show how a small AI app can behave like it expects real traffic, this repository gives you the right instincts: validate early, load eagerly, answer narrowly, and refuse when the context is missing.