PrepPath: The Placement Predictor That Learns From Seniors, Not Just Data
A Node and Python stack combines logistic regression, live peer stories, and a manual similarity search to turn placement prep into a feedback loop.
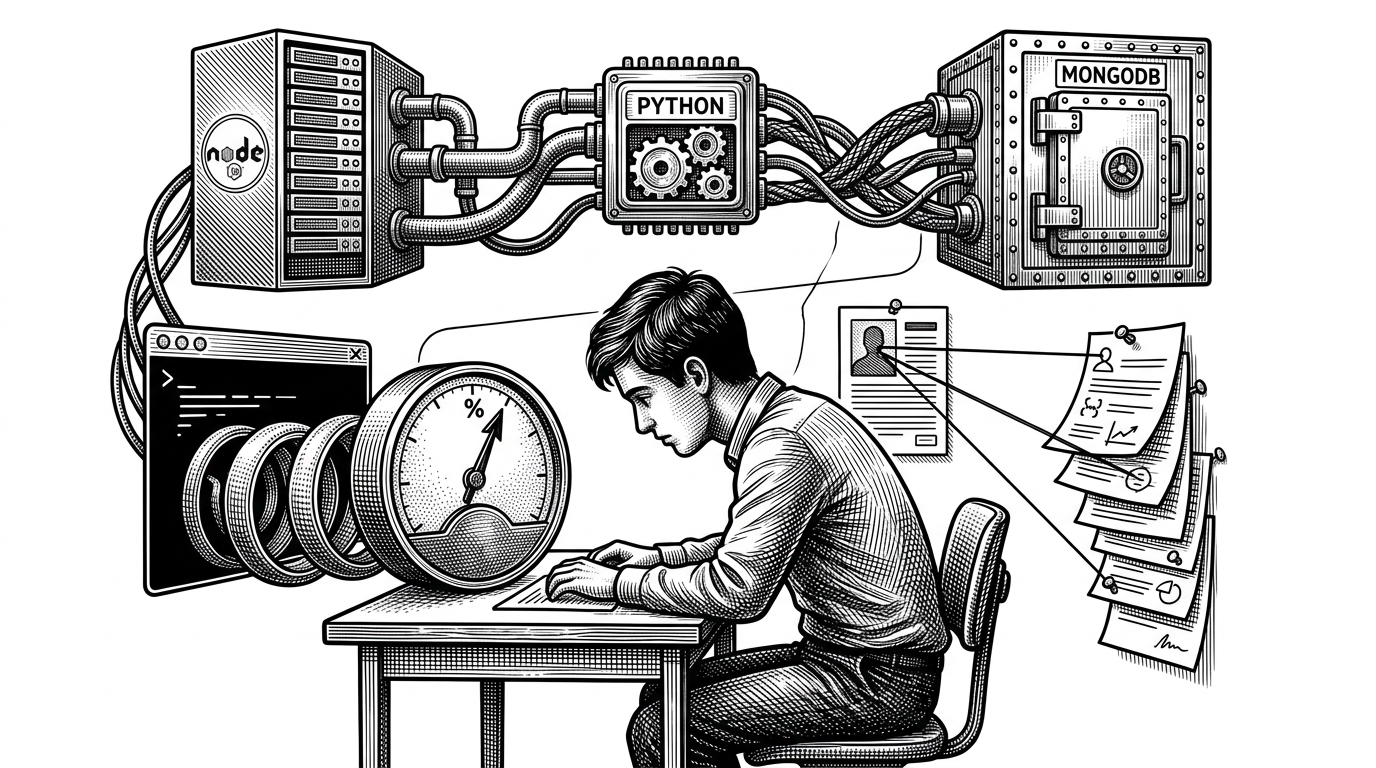
- PrepPath is strongest when it behaves like a two-channel feedback system, not a single placement classifier.
- Its real product move is to combine a probability score with matched senior experiences, which makes the advice easier to trust.
- The backend is where the app becomes opinionated, because it merges model output, database similarity, and trend analysis into one response.
- The manual senior-matching layer is clever and lightweight, but it also exposes the scaling limits of the current design.
Most placement tools pick a side. They either give you a score, or they give you stories. PrepPath does both, and that is why it stands out.
The repo is built like a small system, not a single app. React handles the UI, Node handles orchestration and auth, Python serves the model, and MongoDB stores both quantitative fresher data and qualitative senior experiences.
The best placement advice is both statistical and personal
PrepPath’s core idea is simple: a placement probability is useful, but it is incomplete. Students need a number that tells them where they stand, plus examples from people who had a similar starting point and still got across the line.
That combination changes the product category. It stops feeling like a generic prediction tool and starts feeling like a decision layer built around precedent.
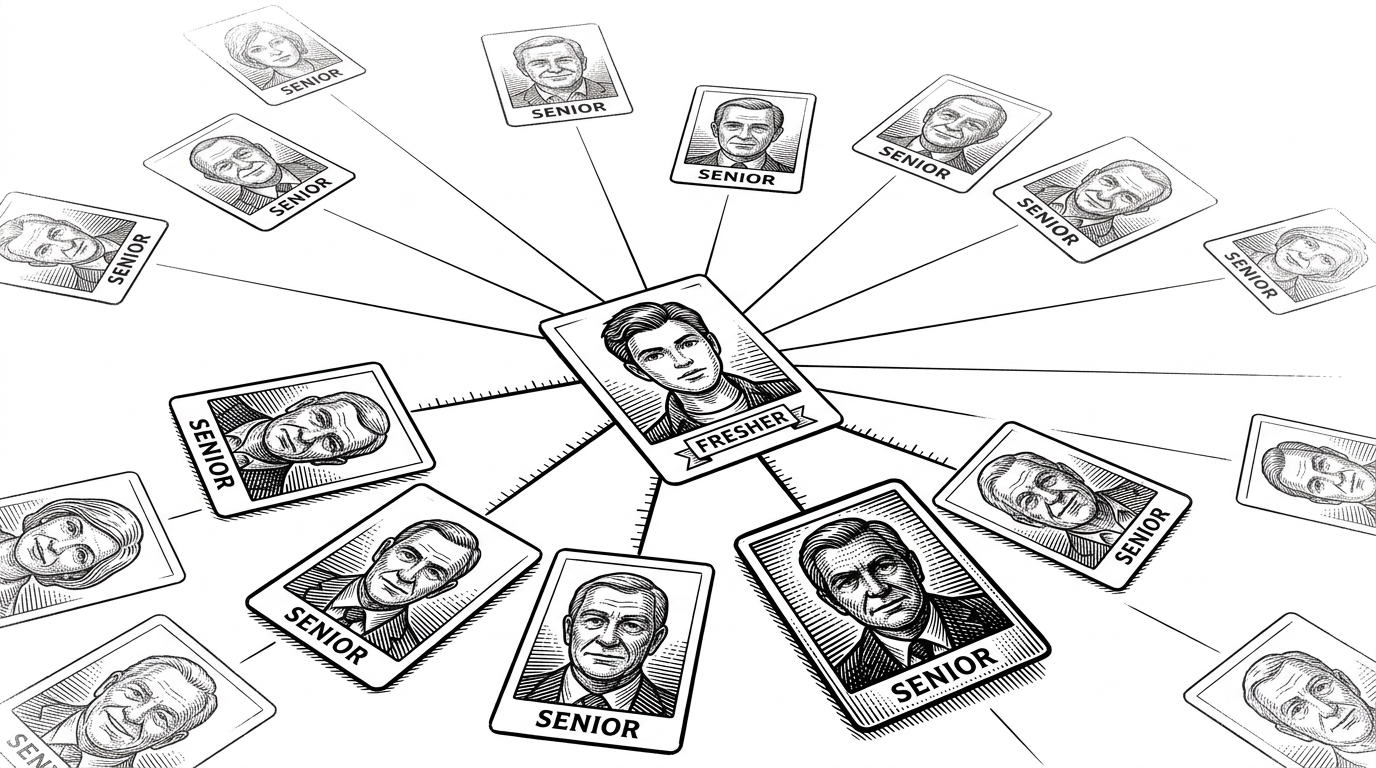
A two-part engine: prediction plus peer matching
The architecture is not subtle, but it is effective. The frontend sends a fresher profile to Node, Node forwards the feature set to the Flask prediction service, and the same backend also queries MongoDB for similar seniors before merging everything into one response.
const difference =
  Math.abs((s.dsa_problems || 0) - dsa) +
  Math.abs((s.projects || 0) - projects) +
  Math.abs((s.internships || 0) - internships) +
  Math.abs((s.study_hours || 0) - studyHours);
That little distance score does a lot of work. It turns the senior collection into a rough nearest-neighbor system without bringing in a vector database, embeddings, or any heavy retrieval stack.
Why the backend is the real product
Node is not just a pass-through here. It handles auth, gathers data from MongoDB, calls the ML service, and then adds trend context from dataset_stats.json. That makes the backend the place where raw signals become advice.
- Auth is enforced on the human-contributed senior routes with JWT.
- Prediction is delegated to a separate Python service through HTTP.
- Database matching is done in Node, not in the ML layer.
- Trend analysis is added after the model returns, which makes the output more opinionated than a raw score.
The manual similarity trick is simple, and that is the point
The senior matcher is probably the most revealing piece of code in the repo. It is not sophisticated, but it is legible, and legibility matters when the goal is to turn a student’s prep state into something actionable.
The trade-off is obvious. Fetching all senior plans into memory and scoring them one by one will work at small scale, but it will become a bottleneck as the collection grows.
const seniors = await SeniorPlan.find();
const matched = seniors
  .map((s) => ({
    senior: s,
    difference: Math.abs((s.dsa_problems || 0) - dsa) + Math.abs((s.projects || 0) - projects)
  }))
  .sort((a, b) => a.difference - b.difference);
That simplicity is also the point. The code says the product is still proving itself. It does not pretend to be a search platform or a recommendation engine with industrial-scale retrieval.
What the model really learns
The ML side is straightforward logistic regression. The training script maps placed and not placed into binary labels, then fits a model on features like coding skill score and mock interview score.
That matters because it keeps the article honest. PrepPath is not promising mystical prediction. It is using a familiar classifier to turn a few prep signals into a probability that can be compared, explained, and combined with peer examples.
| Approach | What it optimizes for | What it misses | Why PrepPath is different |
|---|---|---|---|
| Pure ML placement predictor | A single probability score | Context, examples, and social proof | Adds matched senior experiences beside the score |
| Pure mentorship community | Human advice and trust | Quantitative feedback and comparability | Pairs stories with a concrete estimate |
| PrepPath hybrid | Decision support | Maturity and scale | Uses prediction plus similarity search in one loop |
PrepPath is closer to a mentorship network than a prediction app
The real value is not the classifier on its own. It is the combination of a cold probability, a nearby precedent, and a next step that feels grounded in both data and lived experience.
That puts PrepPath in an interesting middle category. It is more useful than a score-only tool, more structured than a forum, and more fragile than a mature platform.
What breaks first
The implementation already shows where the stress points are. The ML endpoint lacks its own authentication, the senior matcher loads everything into memory, and the repo still reads like a prototype.
That does not weaken the idea. It clarifies it. PrepPath’s strongest insight is product-level, not infrastructural: students want odds, but they also want proof that the odds are navigable.