Banking_Support_RAG_Agent_Chatbot: Why a Banking Assistant Needs a Team, Not a Prompt
A tiny repository, a big ambition. The `.gitignore` hints at a multi-agent support system built for retrieval, compliance, and action, not just conversation.
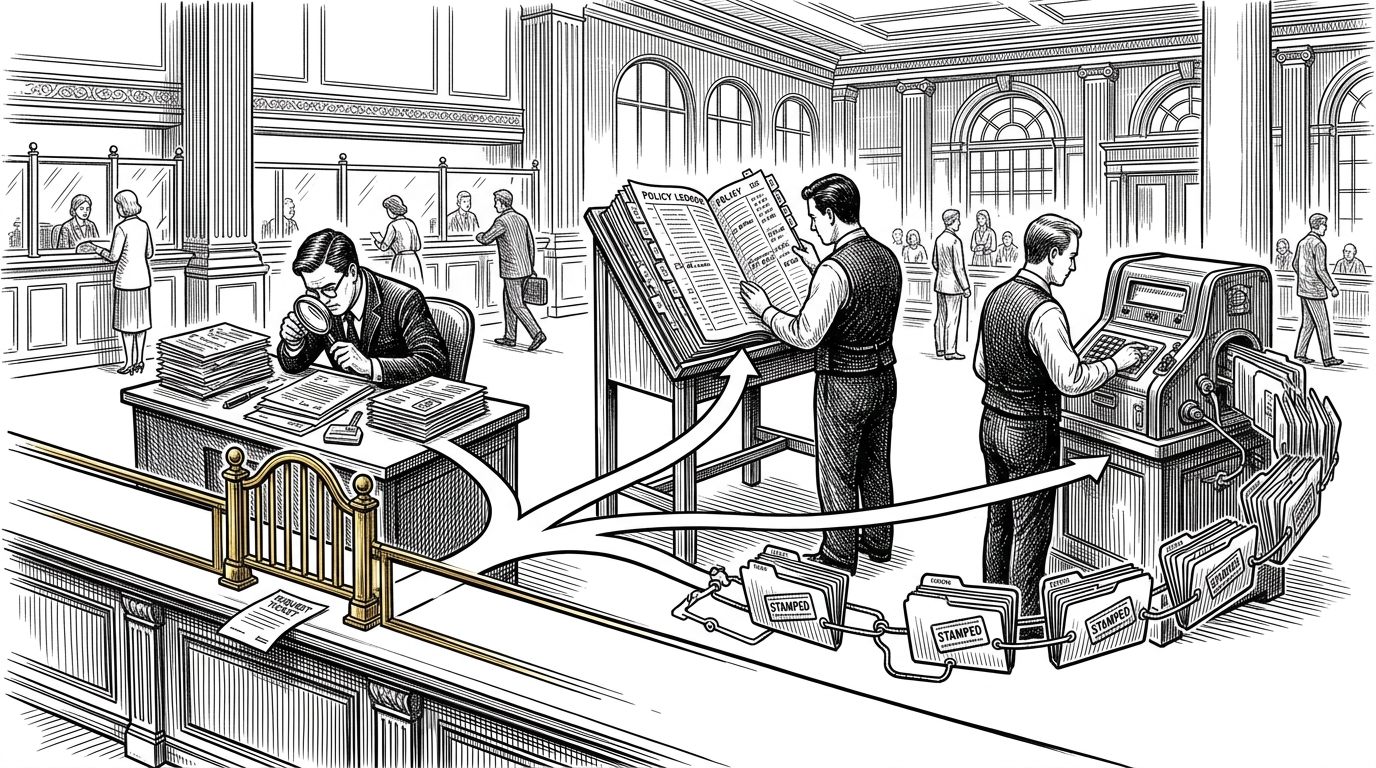
- This repository is interesting because its emptiness still reveals a real banking-support architecture.
- The `.gitignore` reads like a blueprint for Python, Streamlit, async orchestration, and secrets handling.
- Banking support is a coordination problem, so the useful system separates identity, retrieval, response, and action.
- The project’s main story is the gap between a serious regulated workflow and a codebase that has only begun to sketch it.
Most repos tell you what they are. This one tells you what it wants to become. The name promises a banking support assistant built on retrieval and agents, but the codebase is almost blank, which makes the surrounding scaffolding unusually revealing.
The repo tells on itself
The repository title says chatbot, but the structure says system. A minimal tree, plus a very opinionated `.gitignore`, suggests the author is thinking about Python packaging, UI delivery, background jobs, secrets, tests, and local development discipline before any real product logic exists.
That matters because banking support is not a toy domain. A useful assistant has to know when to answer from policy, when to ask for identity, when to stop, and when to hand off to a secure action layer. A single general prompt is the wrong unit of work.
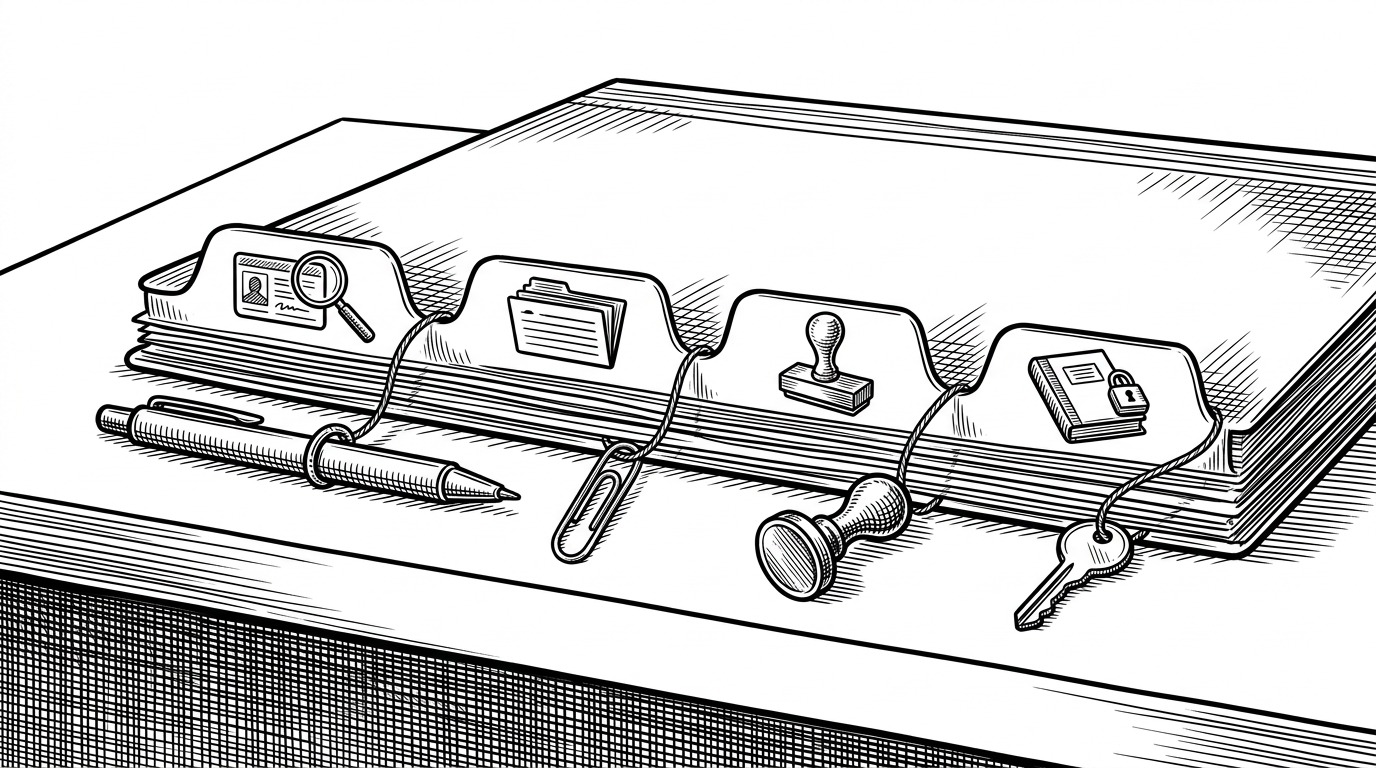
Banking support is not a normal chatbot problem
In most support tools, the job is to answer. In banking, the job is to answer, verify, constrain, and sometimes act. That changes the design brief completely.
| Dimension | Single chatbot | Multi-agent banking support |
|---|---|---|
| Identity handling | Mixed into the prompt | Separated into a gatekeeping step |
| Policy lookup | Ad hoc retrieval | Dedicated retrieval path with narrower scope |
| Action execution | Hard to isolate | Explicit action layer with logging |
| Auditability | Low by default | Built into the workflow |
| Failure isolation | A bad response can contaminate everything | A broken stage can fail closed |
| Regulated fit | Weak | Much stronger |
That table is the real argument. In a regulated support context, modularity is not a taste preference. It is how you keep a system understandable when the request involves private data, careful language, or a side effect that changes something in the account.
The hidden architecture in the `.gitignore`
With almost no application code to inspect, the ignored files become the most honest documentation in the repo. Streamlit implies a lightweight browser UI. Celery, Redis, and RabbitMQ imply asynchronous orchestration. SQLite and `instance/` hint at conventional Python backend habits. Secrets files tell you the project expects real credentials, not toy demos.
# Signals hiding in the ignore list
.streamlit/secrets.toml
.env
celerybeat-schedule
*.rdb
redis/
rabbitmq/
db.sqlite3
instance/
.pytest_cache
htmlcov/
Read together, those clues point to a production-shaped workflow, even if the implementation is not there yet. The repo is less a finished assistant than a set of decisions about how one should be built.
How the agents should divide the work
The cleanest design is a pipeline with specialized jobs. The first stage decides whether the request is informational, account-specific, or action-oriented. The next stage retrieves policy or account knowledge. A response stage writes the answer within guardrails. If the user wants something that changes state, an action layer handles it and records the event.
That flow is what the repository name is reaching for. It is not just RAG, and it is not just a chatbot. It is a control system for a sensitive domain where the right answer is only one part of the job.
What this approach trades away
Multi-agent systems buy structure, but they cost you latency, implementation complexity, and more moving parts to debug. That is a real tradeoff, not a free upgrade.
| Tradeoff | Monolithic chatbot | Multi-agent system |
|---|---|---|
| Latency | Usually lower | Usually higher |
| Control | Harder to constrain | Easier to isolate |
| Debugging | One large failure surface | Stage-by-stage visibility |
| Maintenance | Simpler at first | Cleaner as requirements grow |
| Compliance | Often bolted on later | Can be embedded from the start |
| Best fit | Low-risk support | Regulated, high-stakes support |
In banking, that cost can be justified. A slower system that fails closed, logs its steps, and keeps sensitive operations separate is often better than a faster one that blurs everything together.
The gap between promise and implementation
The current repository looks like a scaffold, not a shipping product. That is a limitation if you are looking for code, but it is the point of the article. The interesting thing here is the shape of the solution before the solution exists.
What you can see already is a disciplined instinct: environment isolation, secret management, async infrastructure, and a UI path that would let a banking assistant stay lightweight on the surface while staying controlled underneath. The repo is barely begun, but its intended architecture is legible.