Chetu248/Candidate_Ranking_System: How a Resume Screener Became a Heuristic Compiler
A LightGBM pipeline turns 100,000 candidates into a ranked shortlist by encoding recruiter taste, feature engineering, and explanation strings into one opinionated system.
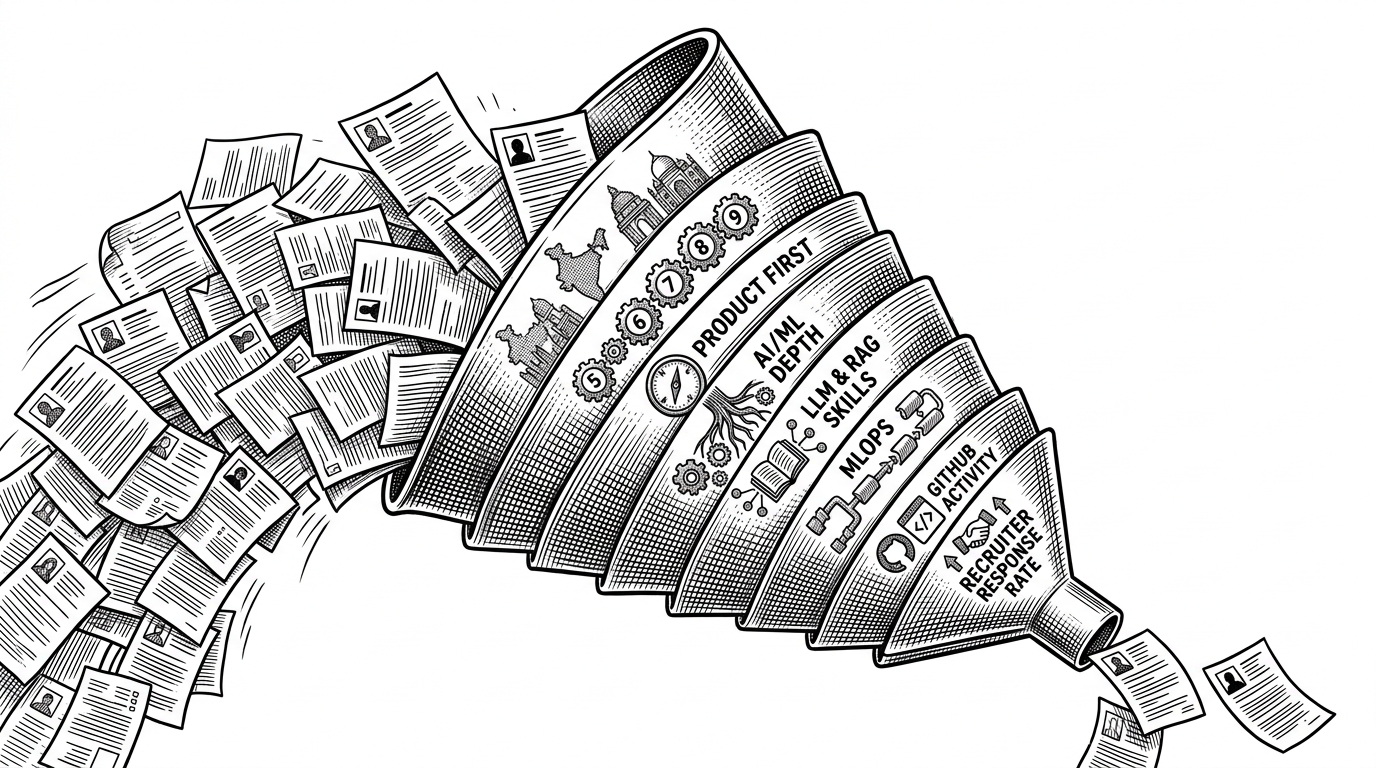
- This repo turns a recruiter’s narrow idea of fit into a fast ranking system, not a neutral matching engine.
- Its most distinctive move is not scoring candidates but generating a reason string that explains the score in human language.
- LightGBM is used less as a fancy model and more as a blunt, efficient compiler for a hand-built hiring rubric.
- The project is revealing because it makes its bias legible, which is more honest than hiding the same values inside embeddings or prompts.
The system does not search for talent. It searches for a profile.
The most important thing about this repo is not the model. It is the target. The pipeline is tuned for a sharply defined Senior AI Engineer profile: India-based, roughly 5 to 9 years of experience, product-first, and deep in AI/ML work. That makes it less like a universal recruiter and more like a machine for enforcing taste.
That choice changes how you should read everything else. The 71 engineered features are not trying to capture the totality of a person. They are trying to make a preferred hiring pattern machine-readable, then rank a large pool against it.
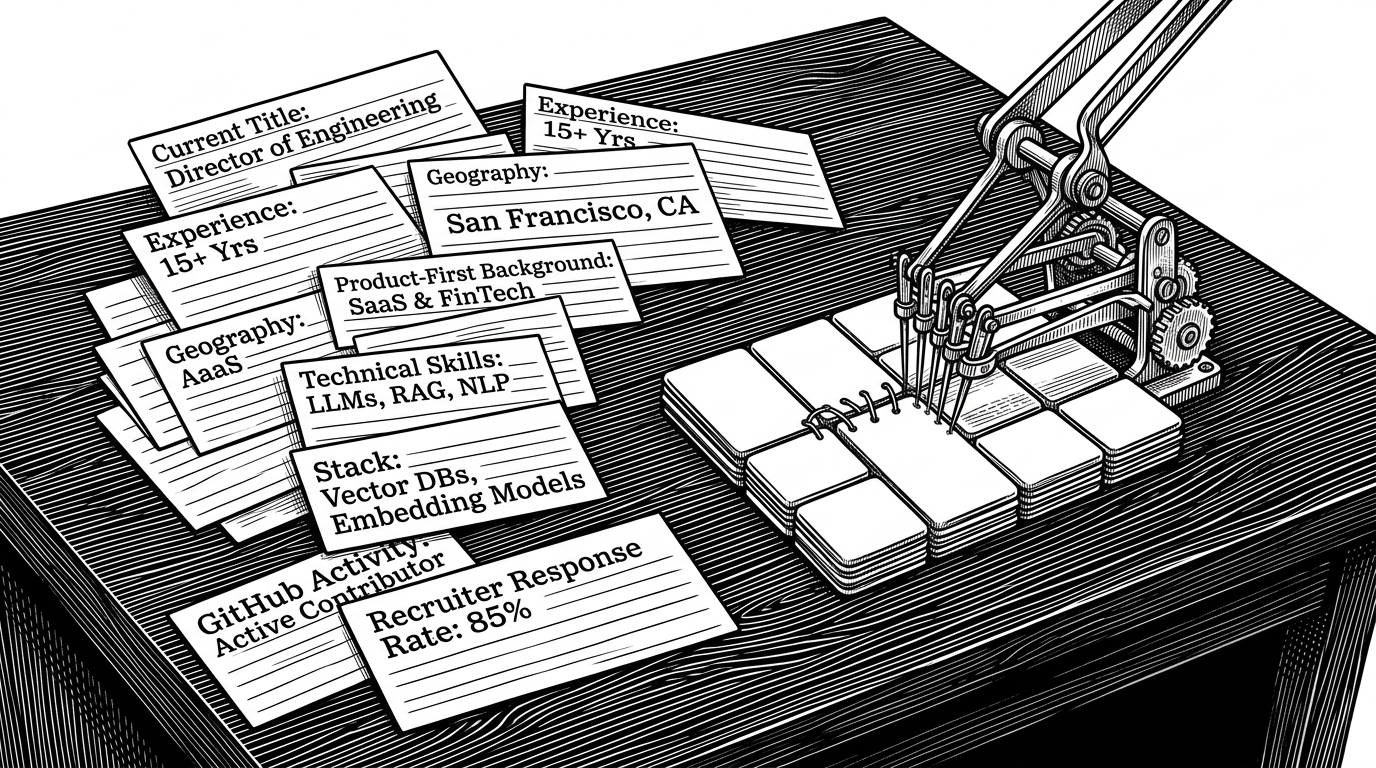
The ranking engine explains itself
The CSV output is where the project becomes unusual. Instead of leaving the reader with a raw score, the system emits a reasoning field that reads like a compact justification. In the research notes, a top candidate is described as having a strong embedding and retrieval stack, specific experience fit, and a core AI/ML title. That is not just reporting. It is narrating the ranking.
candidate_id,score,reasoning
CAND_0002025,0.9916,"Core AI/ML engineering title; 5.9 yrs exp; 70 months deep AI/ML career; strong embedding & retrieval stack (5 skills)"
CAND_0001844,0.9841,"Product-first background; experience fit; India-based; LLM/RAG/MLOps signals aligned with ideal profile"
That matters because it gives the recruiter something closer to a review trail than a black-box score. The explanation is still synthetic, and it still reflects the system’s values, but it makes those values visible.
Inside the notebook, the rubric becomes a model
The notebook reads like a compressed machine-learning competition submission. It loads JSONL records, engineers a large feature set, assigns synthetic tiers, trains a LightGBM multiclass classifier, and writes out the final shortlist. The project description says the system handles 100,000 candidates, uses 71 engineered features, and ranks them with sub-millisecond inference per candidate.
The important part is not that it learns from a mystical ground truth. It learns from a codified rubric. When labels are generated from a strict hiring philosophy, a tree model can reproduce that philosophy with striking consistency.
# Conceptual pipeline
records = load_jsonl("candidates.jsonl")
features = engineer_features(records)  # 71 signals
labels = assign_tiers(features)        # synthetic rubric tiers
model = LGBMClassifier(num_leaves=..., n_estimators=300)
model.fit(features, labels)
ranked = model.predict_proba(features)
explanations = build_reasoning_strings(features, ranked)
That is why the reported scores look almost too clean. A model cannot be more faithful to the rubric than the rubric itself. If the rubric is highly specific, the model can appear almost perfect.
Why LightGBM is the right kind of blunt instrument
This is a tabular problem with engineered signals, not a language problem. LightGBM fits that shape well. It handles mixed feature types, trains quickly, and makes inference cheap enough to score a large candidate pool in one pass.
A deep semantic system might sound more modern, but it would be less direct here. This repo wants to rank on explicit criteria such as experience fit, title relevance, and domain depth. A tree ensemble is a better fit for that kind of opinionated spreadsheet logic.
| Approach | Core signal | Strength | Weakness | What this repo does differently |
|---|---|---|---|---|
| TF-IDF or cosine similarity | Word overlap between resume and job description | Simple and transparent | Misses structured hiring preferences | Uses engineered signals instead of text resemblance |
| Embedding-based ranking | Semantic closeness in vector space | Captures broader meaning | Can blur precise rubric choices | Turns preference into explicit features and tiers |
| LLM hiring agent | Prompted natural-language judgment | Flexible and conversational | Hard to audit and reproduce | Produces deterministic rank plus reason strings |
| This repo | LightGBM over handcrafted signals | Fast, repeatable, explainable enough | Bakes in the designer’s bias | Makes the rubric the product |
The other practical win is speed. Once the feature table exists, scoring 100,000 rows with a tree model is cheap. That makes the system feel like a screening engine rather than a research demo.
The project is more revealing than neutral screeners
What makes the repo editorially interesting is that it does not pretend to be neutral. Many screening tools hide preference inside a similarity score or a prompt. This one declares its preferences in the structure of the pipeline.
That makes it more useful in one narrow sense and more controversial in a broader one. It is useful because the hiring team can see exactly what the machine is optimizing for. It is controversial because the machine is optimizing for a very specific kind of candidate, not for fairness, diversity of path, or general ability.
| Screening style | What it optimizes | How visible the bias is | Best use case |
|---|---|---|---|
| General resume matcher | Text similarity | Low | Broad initial triage |
| LLM reviewer | Narrative judgment | Medium | Small batch review with context |
| This repo | Codified recruiter taste | High | Narrow search for a specific senior profile |
What this system gets right, and what it leaves out
The strongest thing about the project is its clarity. It is fast, repeatable, and easy to reason about once you accept its assumptions. The explanation strings also give humans a usable bridge back from the model to the ranking.
The weakness is the same thing. A geographically and career-path specific rubric can be effective for a targeted search, but it also hard-codes exclusions. The repo is a clean example of a larger truth in hiring tech: software reflects the people who designed the rulebook.