IntervYou-MERN-Stack-project: IntervYou: The MERN Interview App That Grades Your Answers and Watches Your Face
A technical look at a prototype that splits evaluation across browser-side emotion tracking, cloud LLM scoring, and a hard three-strikes proctoring system.
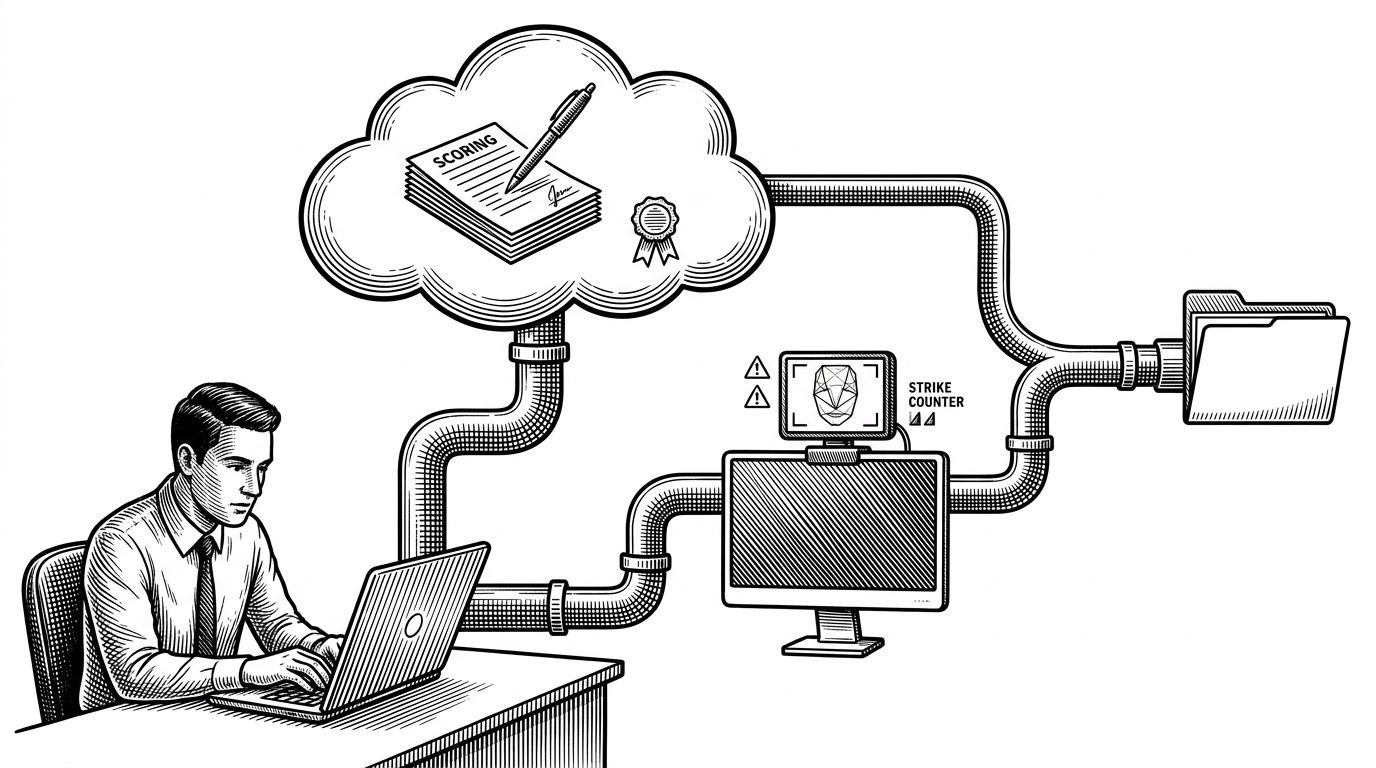
- IntervYou’s core idea is not interview simulation alone, but a two-channel judgment system that scores answers in the cloud while tracking candidate behavior in the browser.
- The project pushes proctoring past passive flagging by turning suspicious events into a booking-level strike count that can end the session automatically.
- Its data model is built to preserve the full evaluation context, including grading output, emotion reports, and raw answers, even if the question set changes later.
- The repo feels like an ambitious prototype because the architecture is thoughtful, but the polish, community footprint, and production maturity are still limited.
The Interviewer Is Watching in Two Directions
IntervYou is unusual because it treats an interview as two separate problems. One system judges what the candidate says. Another watches how the candidate behaves. That split is the whole story.
The result is more than a mock interview app. It is a prototype for a stricter kind of assessment system, one where answer quality and candidate conduct are scored in parallel and folded into the same outcome.
What Gayatri Chippawar Built, and Why It Matters
A real-time remote interview platform with a collaborative code editor and video conferencing.
The repository reads like a portfolio-grade MERN project that wanted to do something bigger than a standard coding playground. Gayatri Chippawar built a remote interview experience with AI features, proctoring, and session records. That puts it closer to an experimental assessment lab than a generic web app.
That matters because the code is not just trying to move text around or host a video call. It is trying to define trust. Who spoke well. Who looked suspicious. Who crossed the line. The design choices all serve that question.
The Split-Brain Architecture
The architecture is the best part of the repo. Browser-side computer vision handles facial expression analysis through face-api.js and TensorFlow.js. Cloud-side grading sends subjective answers to Gemini for scoring. The backend sits in the middle and orchestrates the session.
// Conceptual flow
const emotionSnapshot = await detectExpressionsFromWebcam();
const score = await gradeWithGemini({ question, answer, maxMarks });

await saveResult({
  score,
  emotionReport,
  rawAnswers,
  proctorEvents,
});
That split does three useful things. It reduces server load. It lowers latency for vision tasks. It also keeps the backend focused on coordination instead of pixel work.
How the Proctoring Logic Escalates
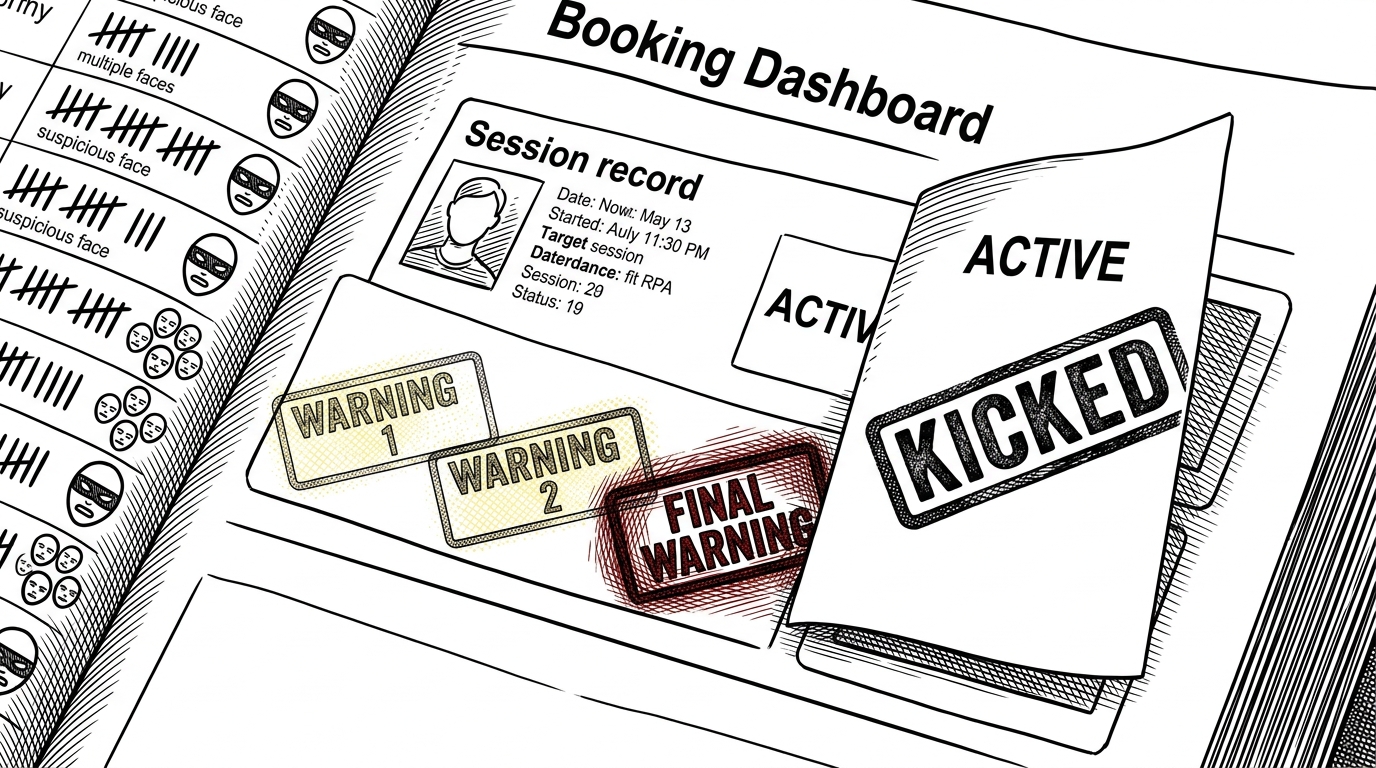
IntervYou does not just warn. It counts. The proctoring controller tracks suspicious events such as SUSPICIOUS_FACE and MULTIPLE_FACES, increments a booking-level warning count, and flips the session to KICKED after the third strike.
That is the project’s sharpest product decision. Most tools flag behavior. This one enforces an outcome. The model is simple, easy to explain, and aggressive enough to change the candidate experience the moment a threshold is crossed.
Why the Result Model Stores So Much
The database design tries to preserve the whole session rather than just the final score. The Result schema stores grading output, the emotion report string, and the raw answer JSON. That means the record can survive later changes to the question bank.
That is a strong archival choice for an assessment product. It gives the system a memory. You can inspect what happened, not just who passed or failed.
The Test model uses Mongoose virtuals to keep the document lighter, which is a sensible way to avoid stuffing the test record with data that can be derived later.
How It Compares to Real Interview Tools
| Tool | Live coding | Video or audio | Proctoring | Automated grading | Emotion analysis | Best fit |
|---|---|---|---|---|---|---|
| IntervYou | Yes | Yes | Yes | Yes | Yes | Experimental interview simulation |
| CoderPad | Yes | Yes | Limited | Some automation | No | Polished technical interviews |
| CodePair | Yes | Yes | Limited | Some automation | No | Enterprise interview workflows |
| VS Code Live Share | Yes | No | No | No | No | Collaborative development sessions |
The comparison makes the positioning clear. IntervYou is not trying to out-polish the market leaders. It is exploring a narrower and more invasive model of assessment. That is why the repo is interesting, even if it is not yet a product people would trust for hiring.
What IntervYou Gets Right, and Where It Still Feels Like a Prototype
The strongest parts are architectural. The browser and cloud split makes sense. The three-strikes rule is easy to reason about. The result model is richer than most student projects, which often throw away the very evidence they claim to analyze.
The rough edges are just as revealing. There are debug-style artifacts, odd automation around MongoDB replica setup, and little sign of community adoption. Those details do not weaken the idea. They show where the code ends and the product begins.