Voice & Multimodal AI
Real-time voice companions, multimodal agents, speech-to-speech, and audio-first interfaces
145 explainers
Voice & Multimodal AI
VoxCPM: The TTS Model That Skips Audio Tokens Entirely
OpenBMB’s tokenizer-free speech system turns text, voice descriptions, and short reference clips into continuous, high-fidelity speech.
Voice & Multimodal AI
AIRI: The Open-Source “Soul Container” Trying to Turn AI Into a Digital Being
A monorepo for embodied companions, where one TypeScript core can wear different bodies, speak with a cloned voice, and step into worlds like Minecraft.
Voice & Multimodal AI
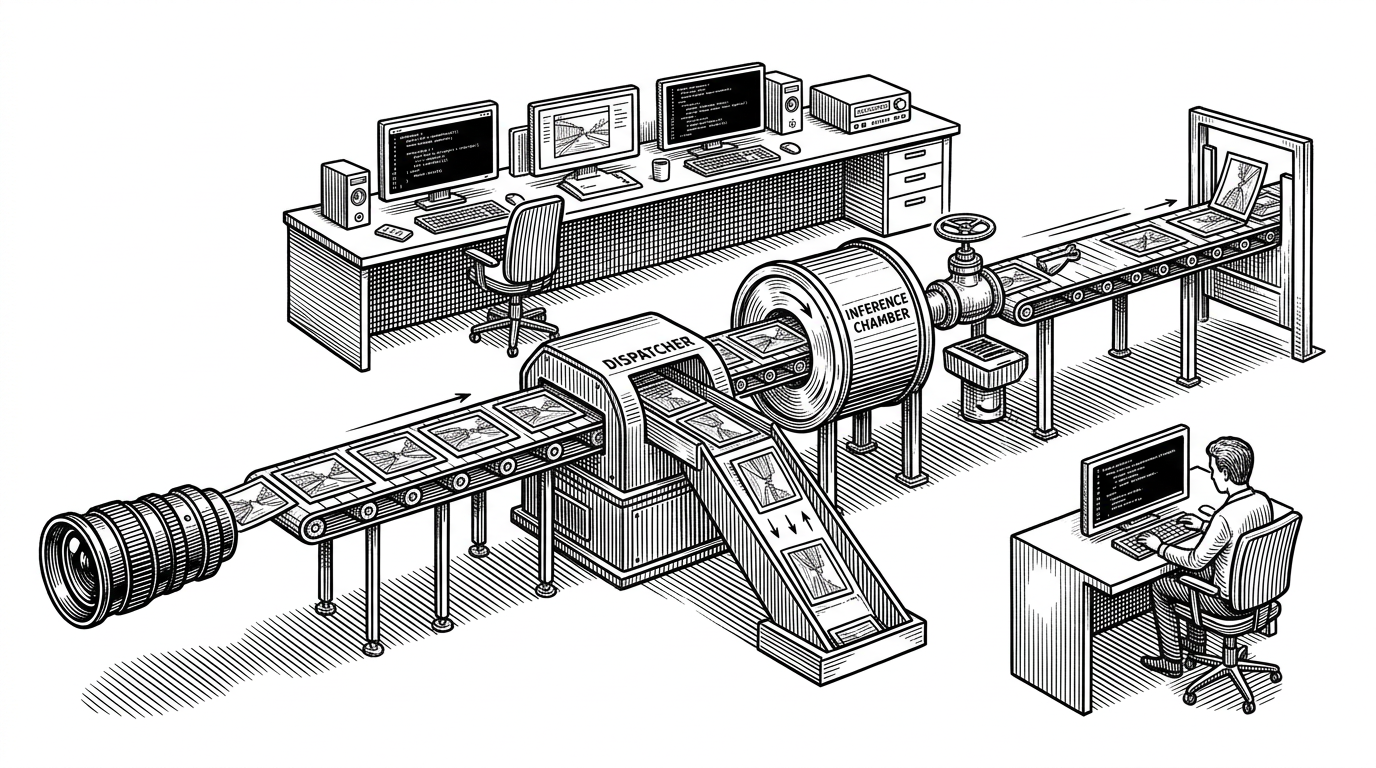
MediaPipe: The Graph Runtime That Keeps Real-Time AI From Falling Behind
How Google’s cross-platform pipeline turns video, audio, and sensor data into low-latency perception by deciding what to process, what to drop, and what to pass through.
Voice & Multimodal AI
microsoft/VibeVoice: The 7.5 Hz Hack That Broke the Audio Context Barrier
How a hybrid LLM-diffusion architecture squeezed 90 minutes of multi-speaker audio into a single pass, prompting a corporate redaction.
Voice & Multimodal AI
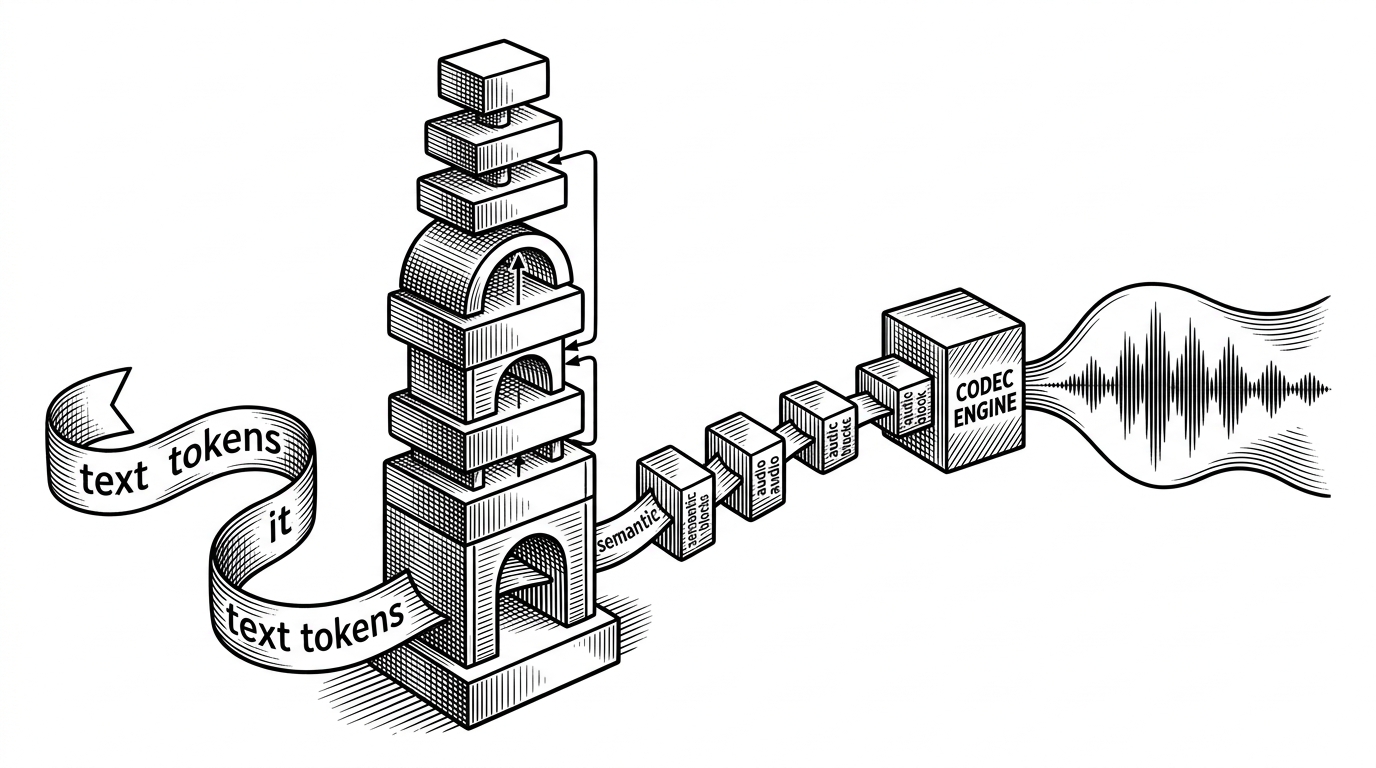
fish-speech: Fish Speech: The Audio Llama That Treats Voice Like Tokens
A deep dive into how Fish Speech combines dual-autoregressive transformers, repetition-aware sampling, and codec-level decoding to make open-source TTS sound controlled, expressive, and fast.
Voice & Multimodal AI
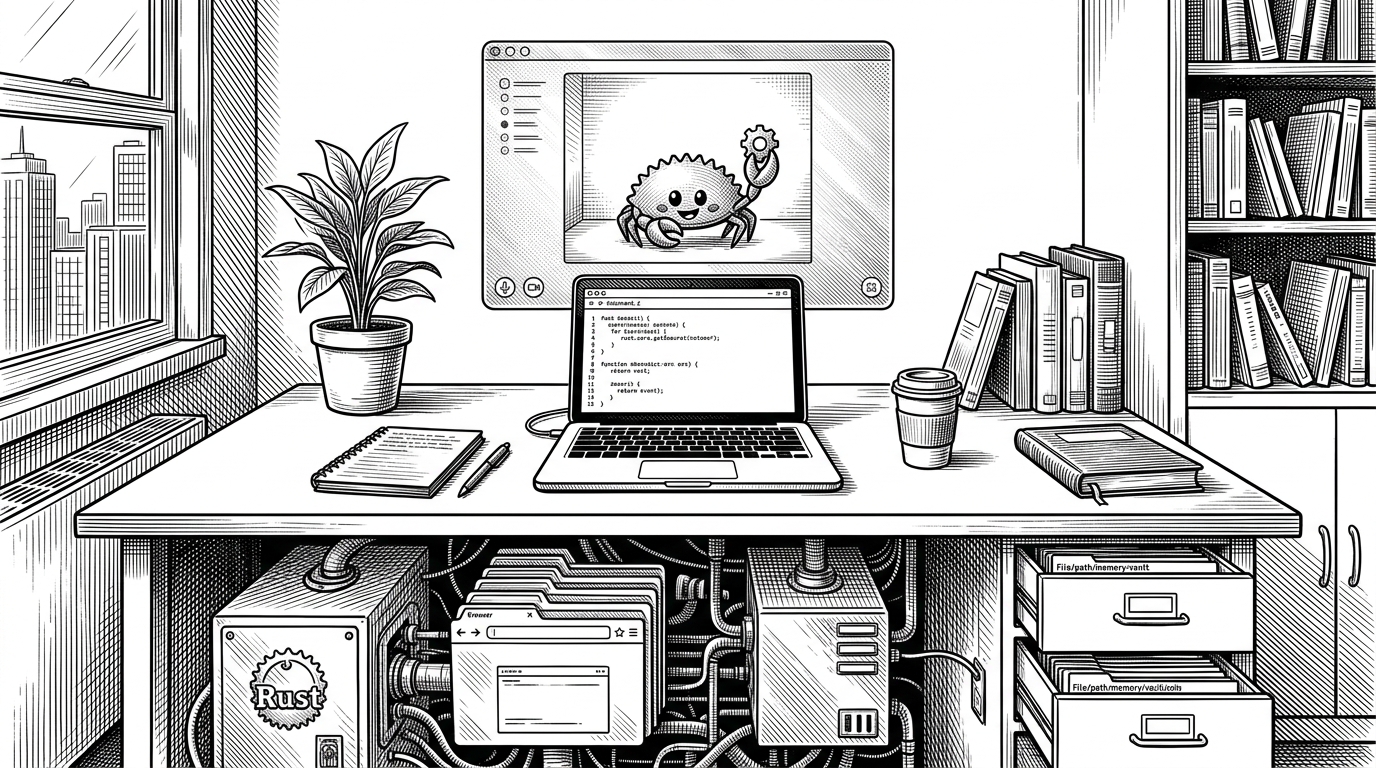
OpenHuman: The Personal AI That Treats the Browser, Desktop, and Camera as One Surface
A deep dive into the Rust core, CEF shell, local memory vault, and the fake-camera trick that lets an assistant show up inside your workflow instead of beside it.
Voice & Multimodal AI
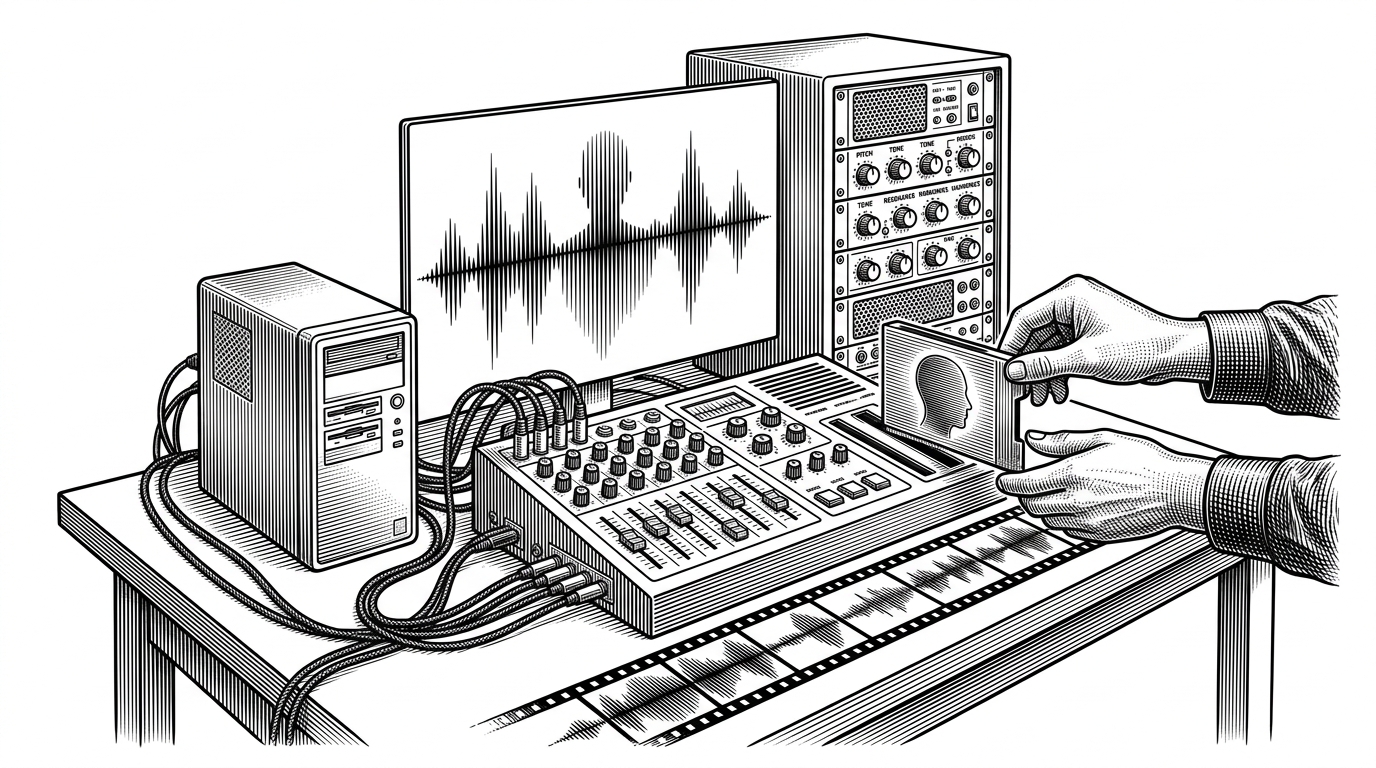
Voicebox: The Local Voice Studio That Makes TTS Feel Installed, Not Streamed
An open-source desktop app for voice cloning and speech generation that bundles the model, the backend, the editor, and the effects chain into one private workflow.
Voice & Multimodal AI
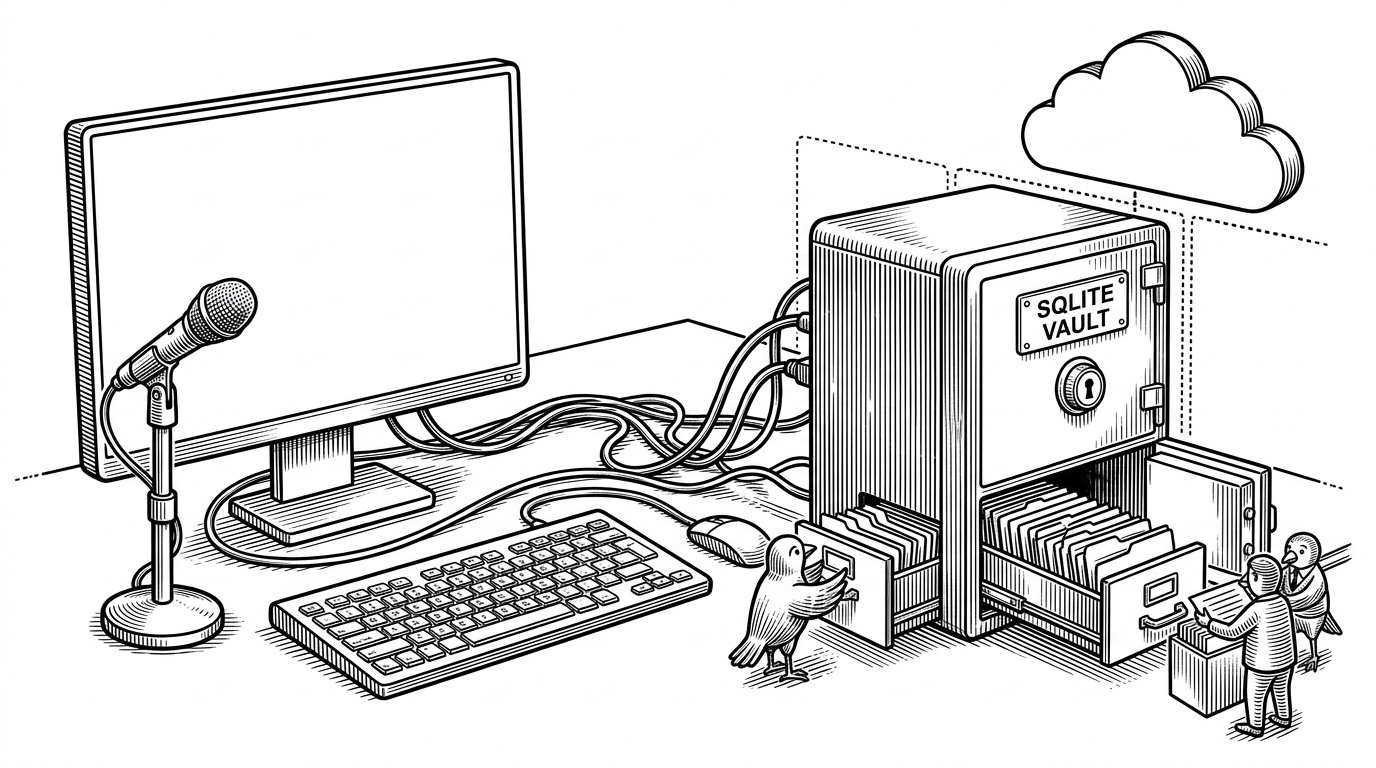
Screenpipe: The Open Source Memory Layer That Turns Your Desktop Into an API
A deep dive into the Rust-and-SQLite system that records everything you see and hear, then lets AI agents search, replay, and act on it without sending your life to the cloud.
Voice & Multimodal AI
VoxCPM: The TTS Model That Tries to Skip the Tokenizer Entirely
An open-source voice system that generates multilingual speech in continuous latent space, blends voice design with cloning, and aims for studio-quality output without the usual codebook bottleneck.
Voice & Multimodal AI
speech-to-speech: The Open-Source Voice Agent Built Around Interruption
A modular Python pipeline that swaps in local STT, LLM, and TTS backends, mimics the OpenAI Realtime API, and solves the hardest part of voice UX: stopping cleanly when the user starts talking.
Voice & Multimodal AI
ViMax: The Open-Source Film Studio That Teaches AI Video to Remember
A deep dive into the agentic pipeline, the camera tree, and the structured shot logic that try to solve the hardest problem in video generation: staying coherent from scene to scene.
Voice & Multimodal AI
Chandra and the End of the OCR Assembly Line
How full-page multimodal decoding is replacing twenty years of fragile document pipelines to finally solve the messy reality of handwriting and math.
Voice & Multimodal AI
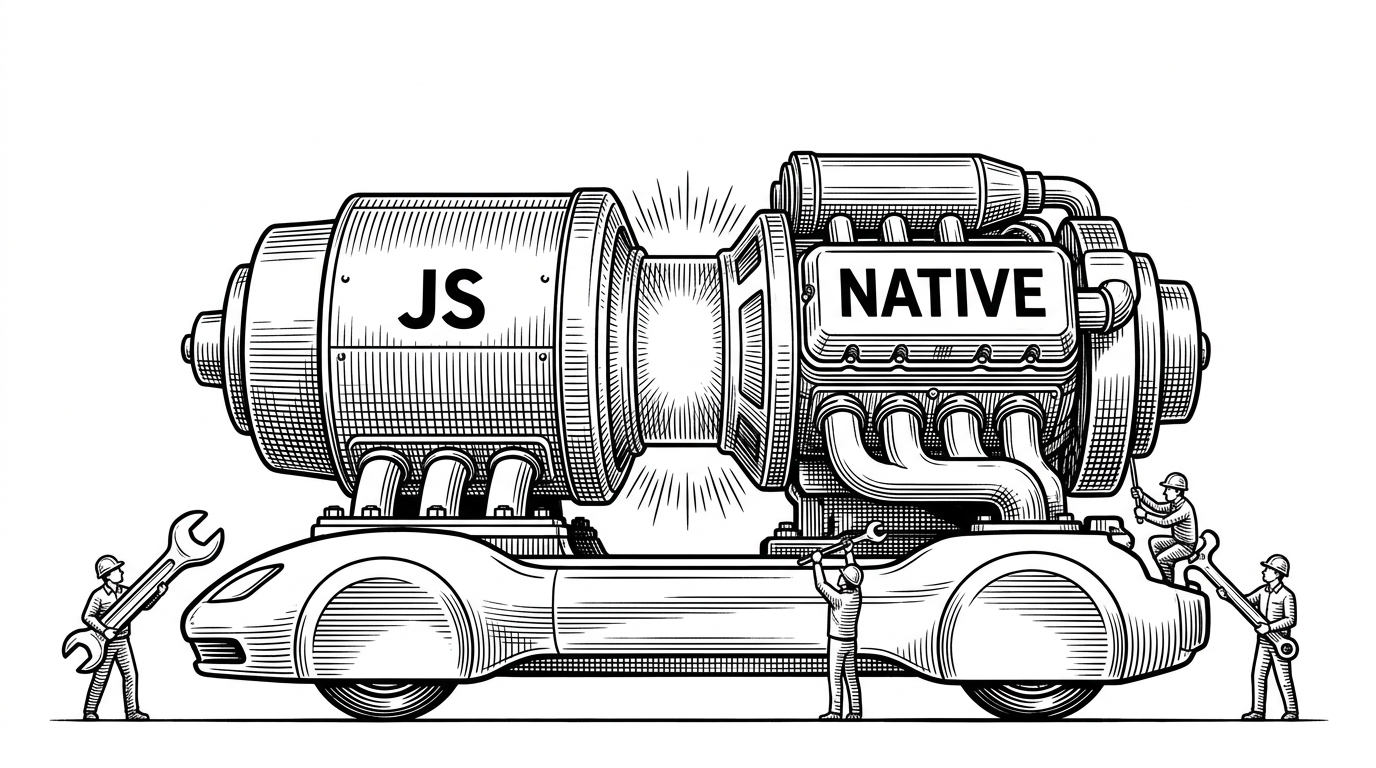
react-native-reanimated: Reanimated: The Engine That Stole the Render Loop
How Software Mansion turned React Native’s biggest weakness into a 120fps superpower through the magic of UI-thread Worklets.
Voice & Multimodal AI
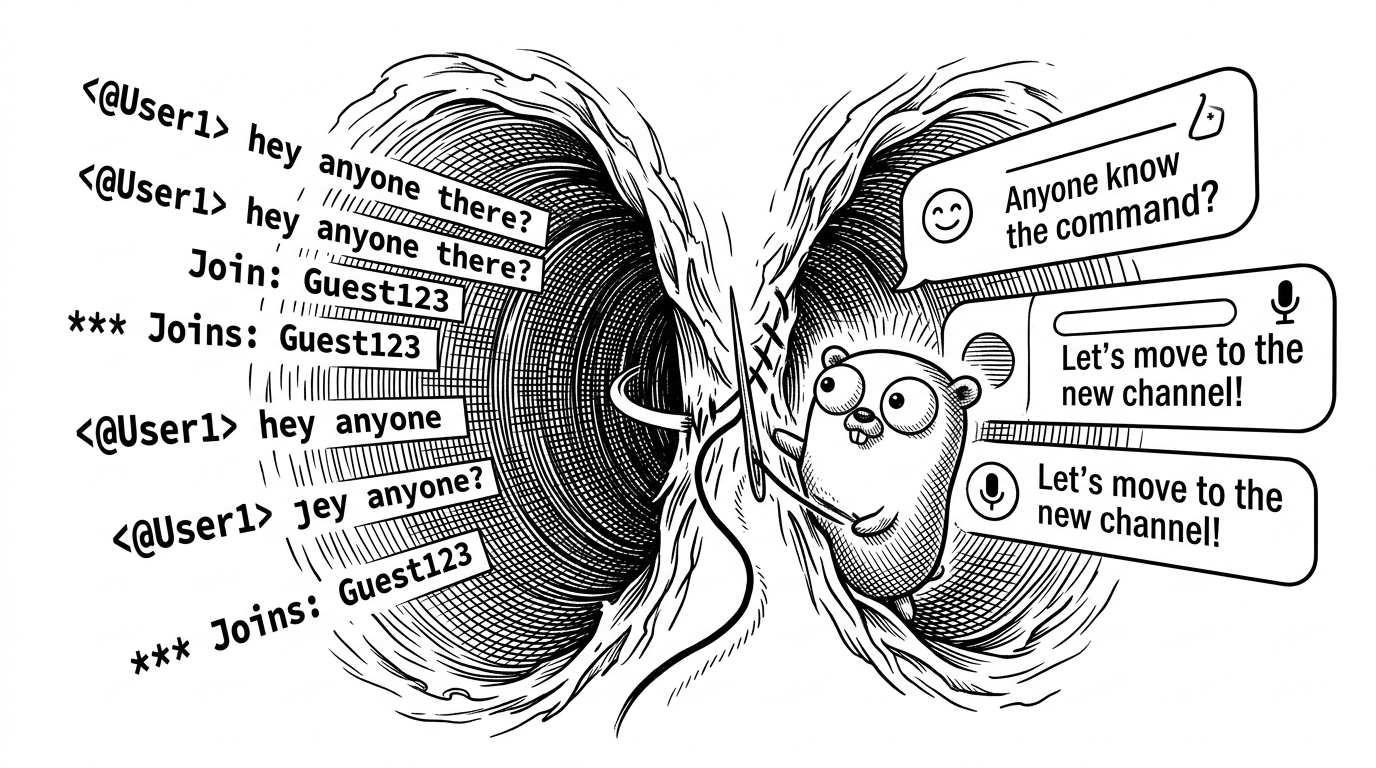
Matterbridge: The Stateless Wormhole Connecting the Fractured Chat Universe
How a single Go binary reconciles thirty years of incompatible protocols to create a "Unified Field Theory" for online conversation.
Voice & Multimodal AI
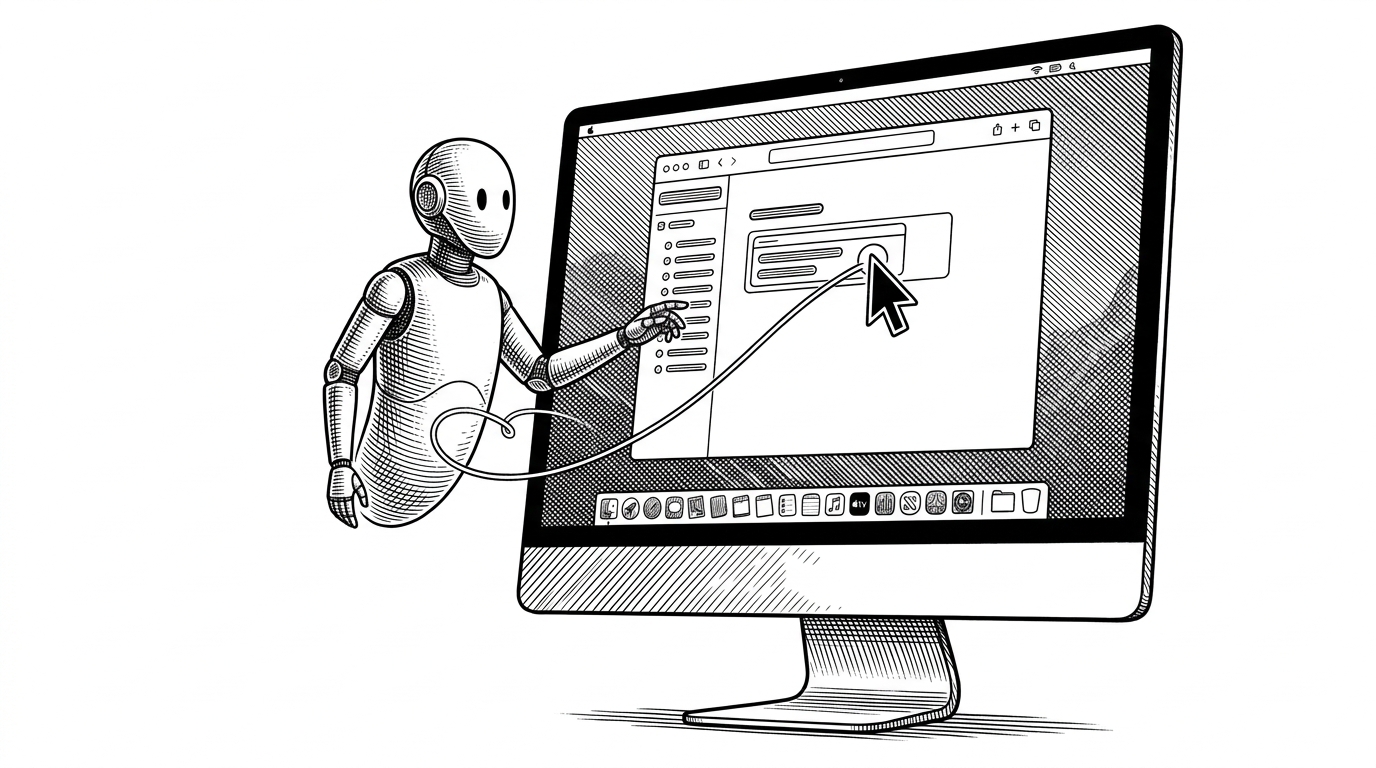
Clicky: The macOS AI Assistant That Points at Your Screen
A native Swift app, a thin Cloudflare proxy, and a tiny coordinate language turn Claude into a spatial tutor that follows your cursor instead of hiding in a sidebar.
Voice & Multimodal AI
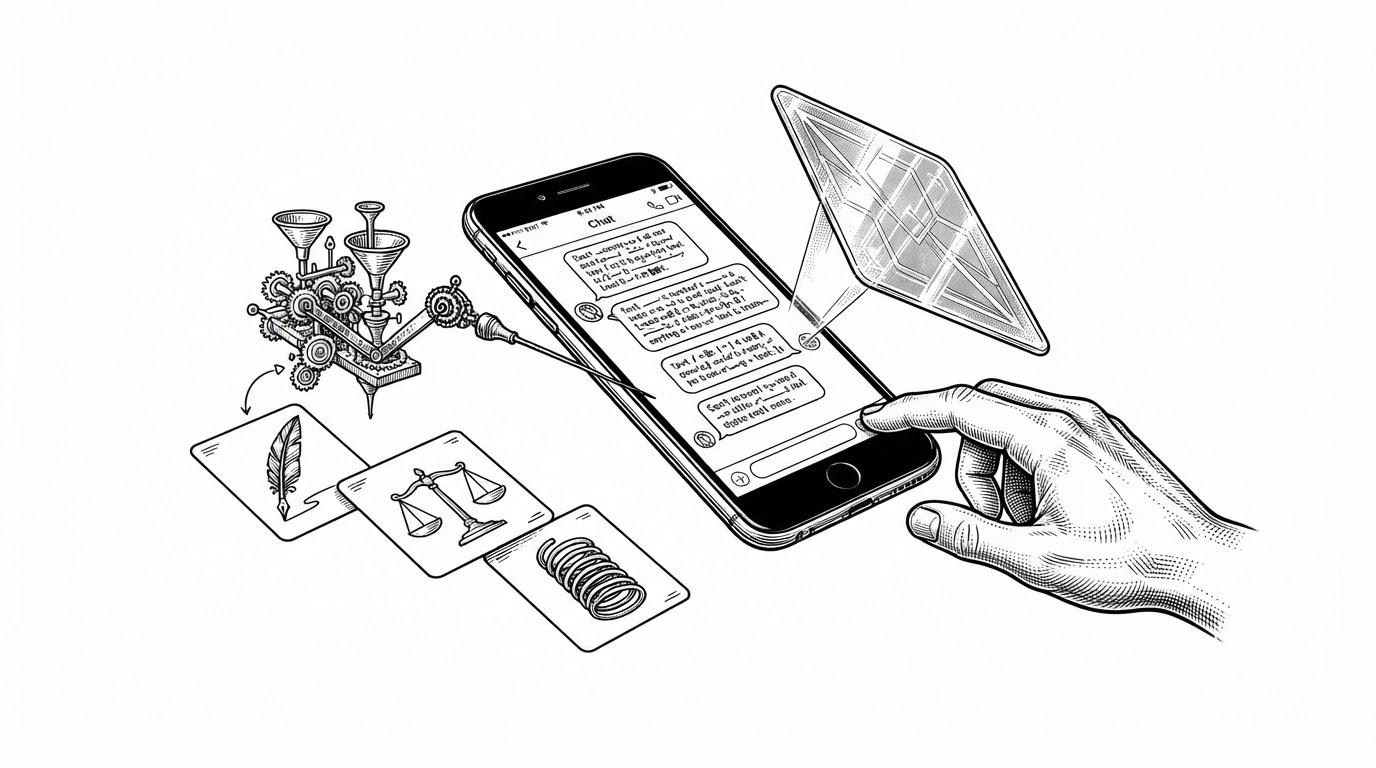
jev-chat-jarvis: The Android Copilot That Reads the Screen, Not the Process
A non-invasive chat assistant that combines Accessibility, OCR, and split-model reasoning to draft replies without rooting, hooking, or auto-sending.
Voice & Multimodal AI
helloianneo/ian-xiaohei-illustrations Turns Abstract Ideas Into a Visual System
A Codex Skill that uses a recurring black character, low-tech metaphors, and strict style rules to generate consistent hand-drawn editorial art for Chinese technical writing.
Voice & Multimodal AI
MOSS-TTS-Nano: The Small Voice Model That Refuses the GPU
How a 100M-parameter TTS stack uses audio tokenization, ONNX, and streaming decode to make high-fidelity voice generation feel local, fast, and practical.
Voice & Multimodal AI
Quill: The macOS recorder that treats diarization like a plumbing problem
A minimalist local-first tool that captures mic and system audio separately, writes crash-safe CAF files, and transcribes on-device without a cloud meeting bot.
Voice & Multimodal AI
qwen-audio-agent: Qwen Audio Agent Turns Voice Into a Live Operating Layer for AI Agents
An open-source runtime that keeps agents talking while they work, separates real-time presence from task execution, and wraps ACP-compatible backends in a persistent voice interface.
Voice & Multimodal AI
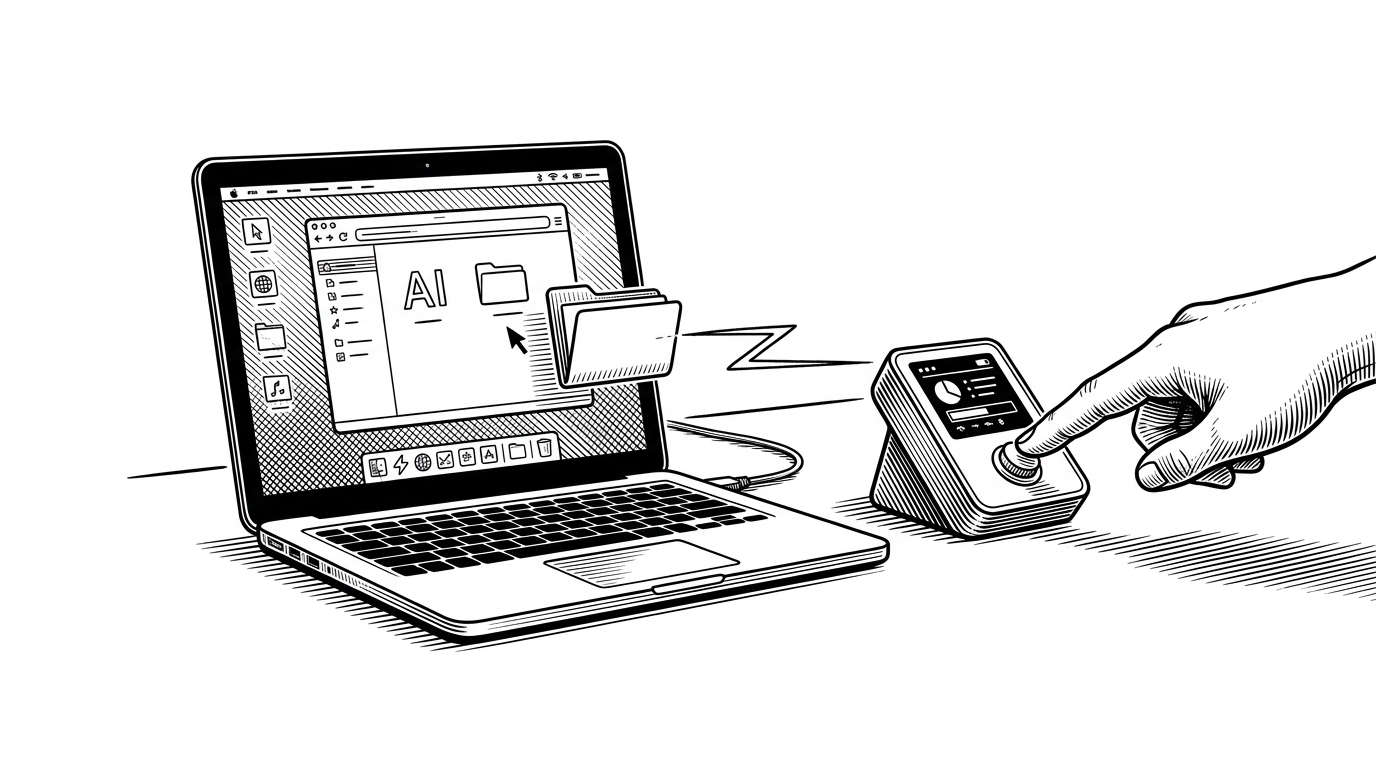
claude-desktop-buddy: Claude Desktop Buddy: The Desk Pet That Doubles as a Hardware Control Surface for Claude
A tiny ESP32 companion turns Claude Desktop state into motion, mood, and physical approvals, then ships custom assets to the device over BLE with a drag-and-drop workflow.
Voice & Multimodal AI
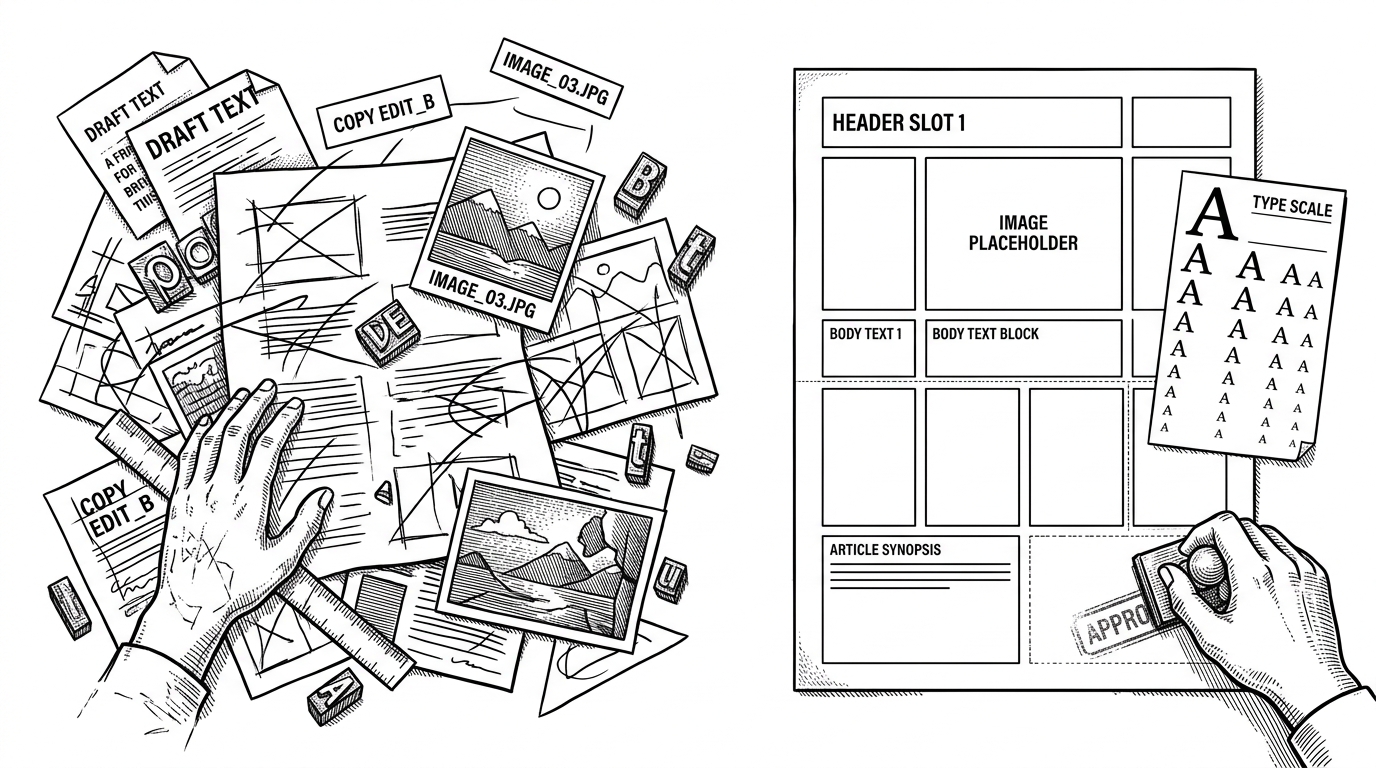
`guizang-social-card-skill`: The AI Design System That Refuses to Wing It
A deep look at how this skill uses seed templates, layout recipes, and rendered-image validation to turn raw content into polished Xiaohongshu and WeChat graphics without letting the model freestyle.
Voice & Multimodal AI
Fogsight: The End of the Black Box Video
How an open-source agent uses Gemini Pro and GSAP to replace diffusion models with perfectly editable, code-generated animations.
Voice & Multimodal AI
Querying Reality: Unpacking SentrySearch
How an open-source Python CLI uses multimodal AI and overlapping video chunking to replace timeline scrubbing with natural language search.
Voice & Multimodal AI
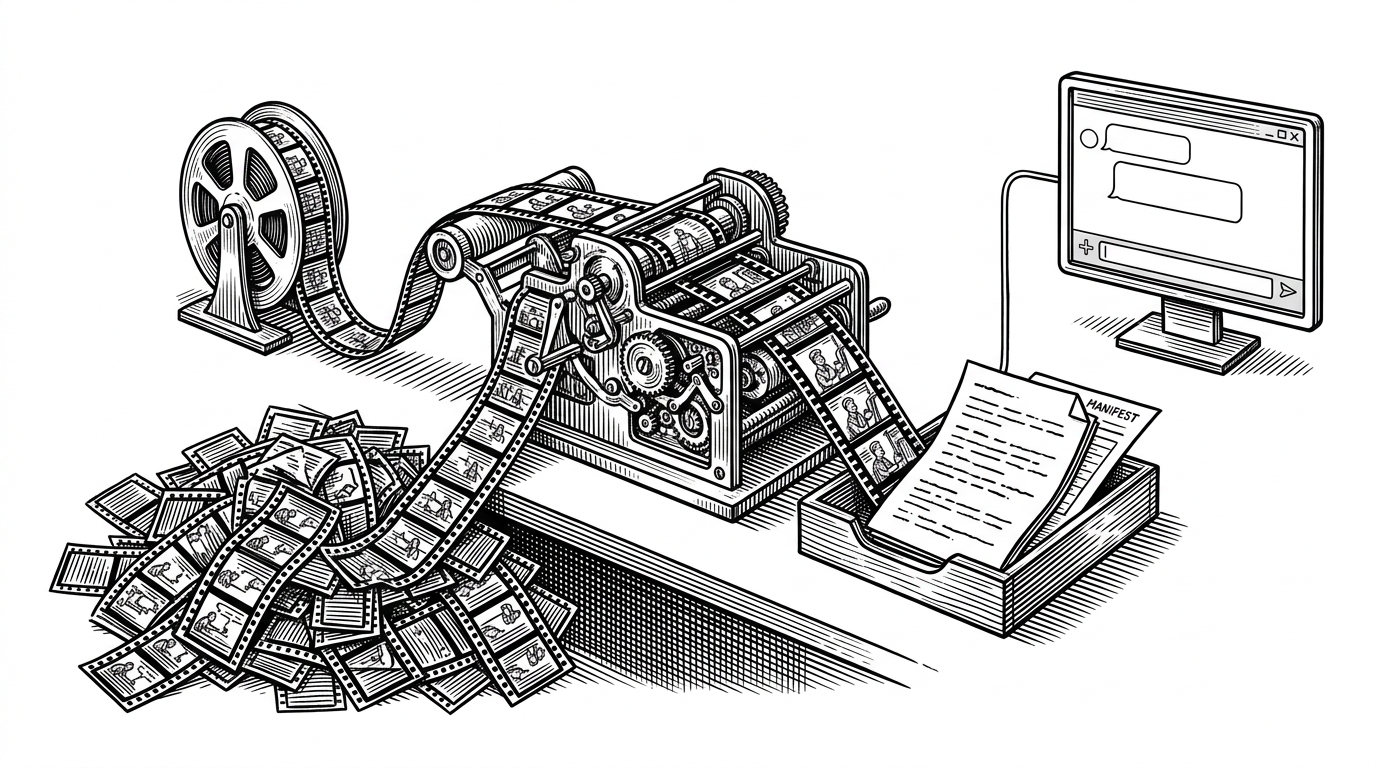
claude-real-video: The Video Pipeline That Teaches LLMs What to Ignore
A local-first tool that turns raw video into scene-aware keyframes, deduplicated grids, and a manifest an LLM can actually use.
Voice & Multimodal AI
The Local-First AI Control Plane: Inside nexu-io/nexu
How a TypeScript desktop client tames the OpenClaw runtime to bring private, autonomous agents to everyday messaging apps.
Voice & Multimodal AI
modelcontextprotocol/ext-apps: Escaping the Chatbox Prison
How the Model Context Protocol standardized interactive, sandboxed UIs to turn AI clients into fully-fledged operating systems.
Voice & Multimodal AI
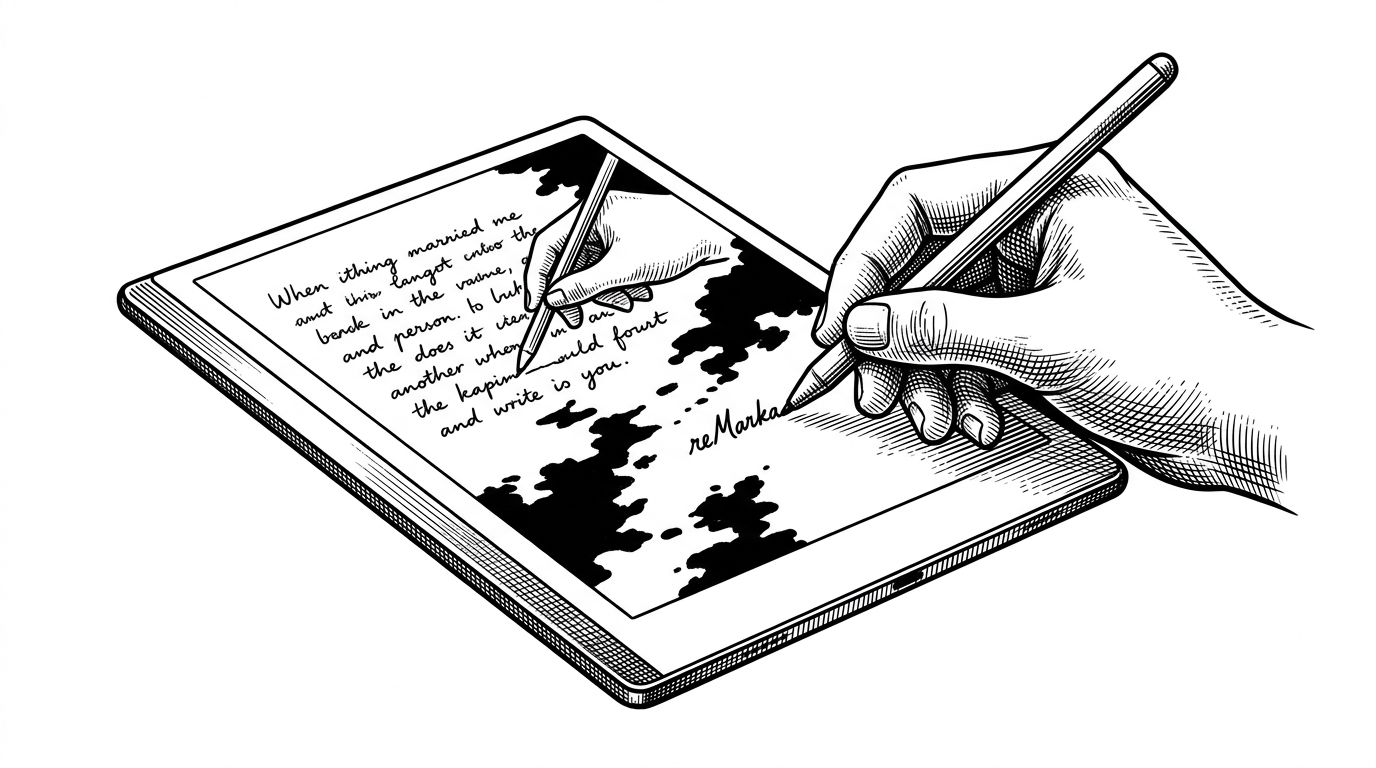
riddle: The Open-Source Diary That Makes a reMarkable Tablet Feel Haunted
A Rust-powered takeover of the Paper Pro that erases the interface, turns handwriting into a ritual, and uses an LLM as the voice behind the page.
Voice & Multimodal AI
Jarvis: The Local Voice Assistant That Remembers the Room
A deep dive into how `isair/jarvis` turns ambient speech, rolling transcript windows, and layered memory into a privacy-first assistant that can join a conversation without being reintroduced.
Voice & Multimodal AI
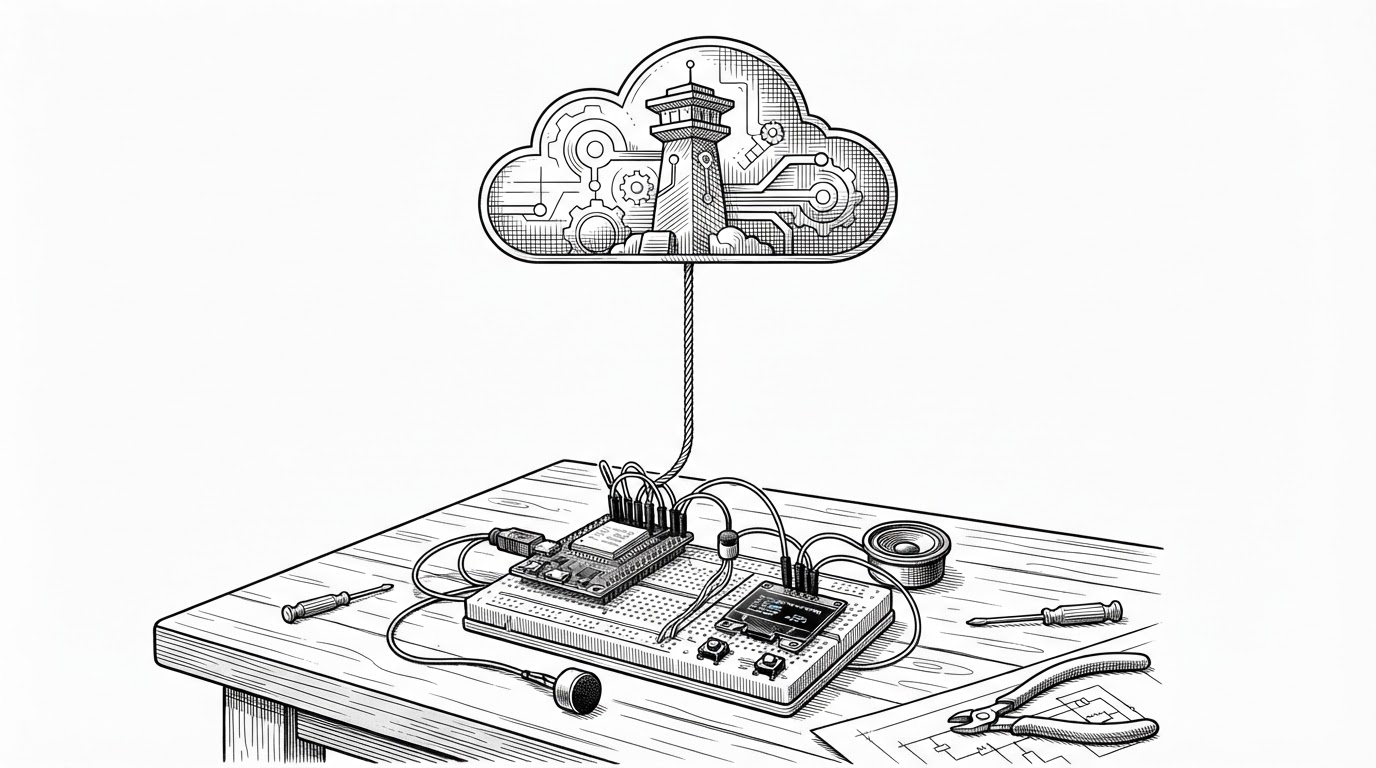
muse-gadget-sdk: Muse Gadget SDK: The Open Hardware Skin for Meta’s AI Agent
A look at how Meta turns ESP32 boards and Raspberry Pis into voice-first gadgets, with one firmware stack, one pairing flow, and one cloud brain behind the scenes.
Voice & Multimodal AI
natively-cluely-ai-assistant: Natively: Engineering the Invisible Copilot
How a Rust-powered Electron core bypasses screen-sharing detection to provide real-time, local-first interview intelligence.
Voice & Multimodal AI
Mural: The Language App That Trains You to Leave It
A deep dive into the local-first AI tutor that turns real-time conversation, spaced repetition, and your own API key into a private path to fluency.
Voice & Multimodal AI
oil-motion: Oil Motion: The AI Motion Pipeline That Makes Video Behave Like an Interface
It generates continuous motion, cleans the frames, chooses the right delivery format, and maps scroll, mouse, drag, touch, or device orientation onto the same sequence.
Voice & Multimodal AI
Inside vercel/chat: A JSX Runtime for the Chat Interface
How Vercel built a unified SDK that translates React-like components and streaming AI into native Slack, Teams, and Discord apps.
Voice & Multimodal AI
Wardrobe: The Local-First AI Closet That Turns Photos Into a Living Asset Pipeline
Behind the scenes, one upload becomes a staged job, a reviewed cutout, a modeled preview, and a searchable library that never leaves your machine.
Voice & Multimodal AI
vercel-labs/gemini-chatbot: When the chatbot becomes the interface
A Vercel Labs template that uses Gemini, tools, and typed React components to turn chat into a task flow instead of a transcript.
Voice & Multimodal AI
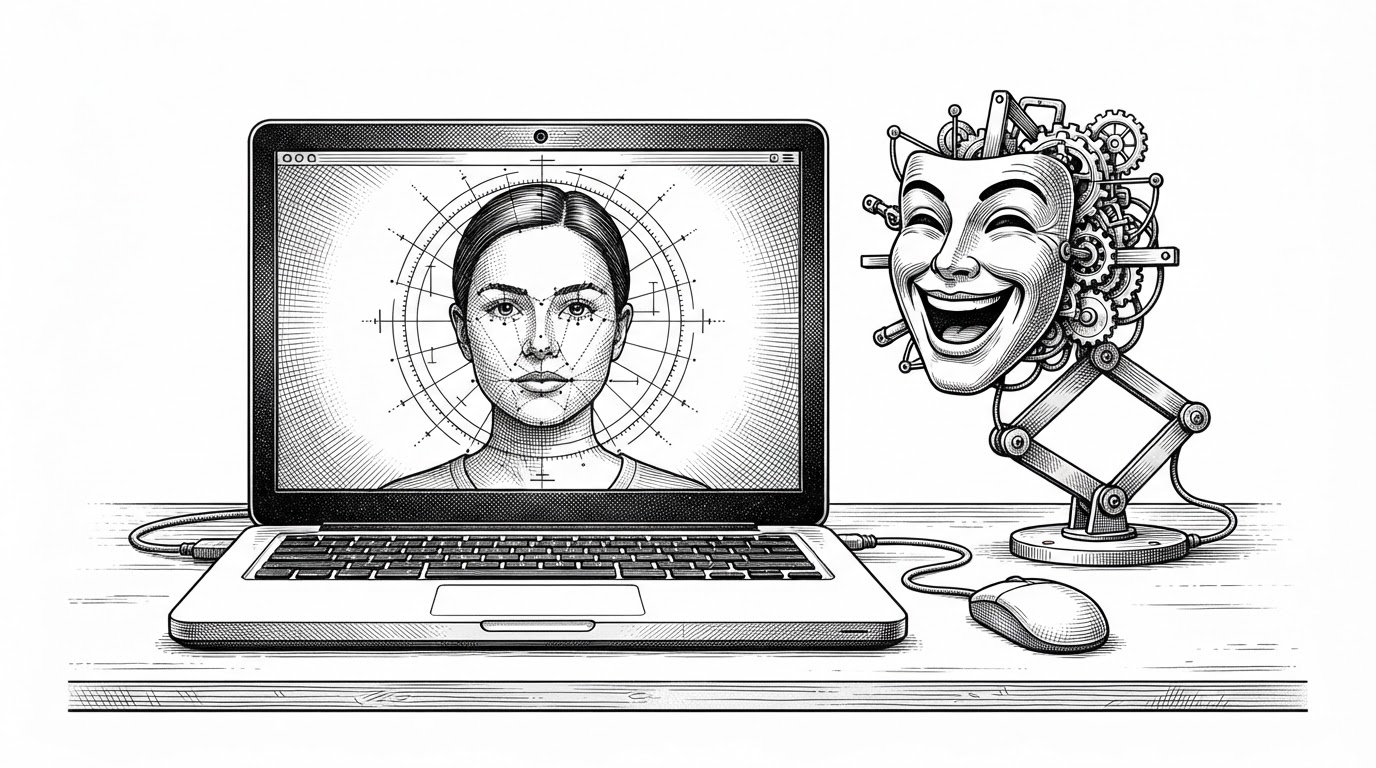
itsgiving: The Webcam Meme Engine That Learns Your Face
A lightweight Python app that calibrates to your neutral face, scores expressions relative to that baseline, and pushes live meme overlays into Zoom, Meet, and Discord as a virtual camera.
Voice & Multimodal AI
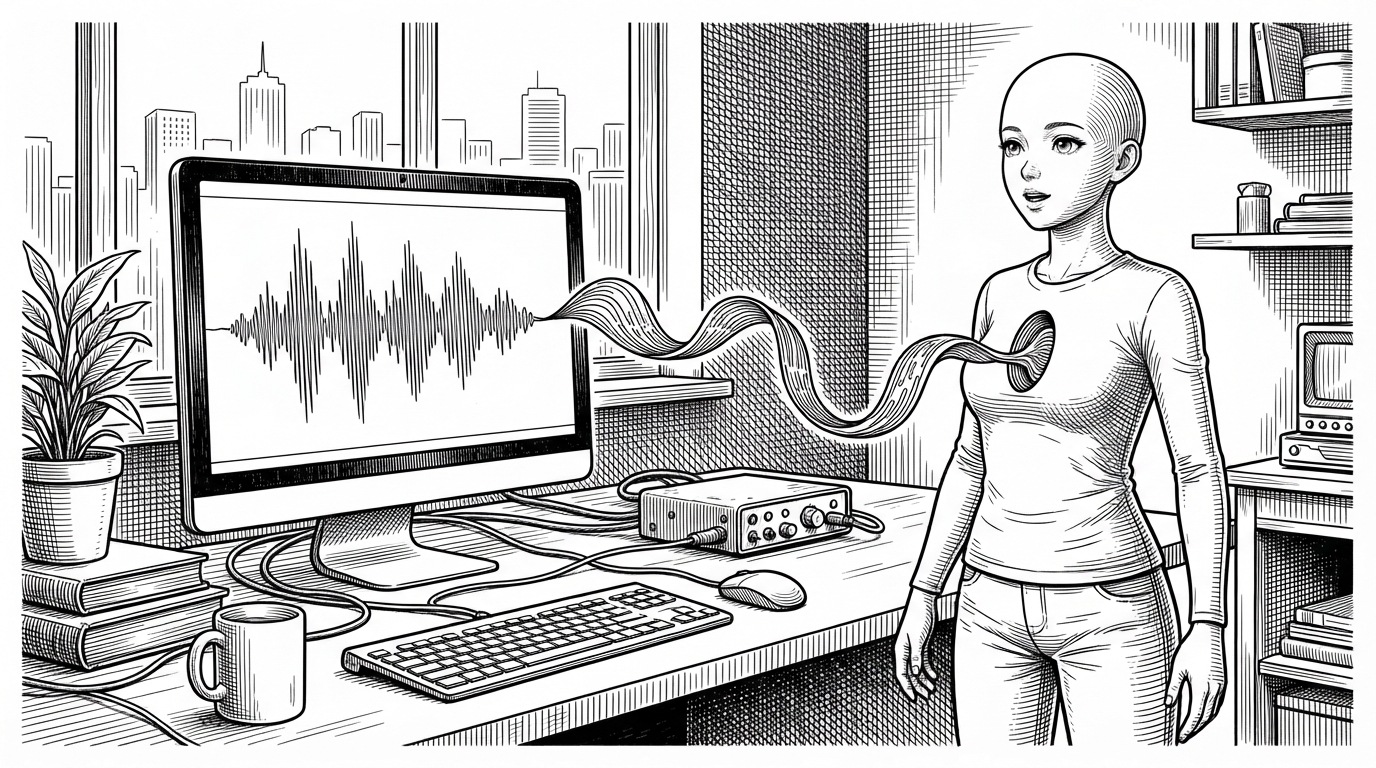
Persona Turns Voice AI Into a Desktop Character
A cross-platform Electron app that captures system output, lip-syncs a 3D avatar, and gives agents a body they can actually use.
Voice & Multimodal AI
openai/openai-chatkit-advanced-samples: ChatKit’s Headless GUI Blueprint
A FastAPI and React reference repo where state, widgets, hidden context, and client effects do the work that plain prompting cannot.
Voice & Multimodal AI
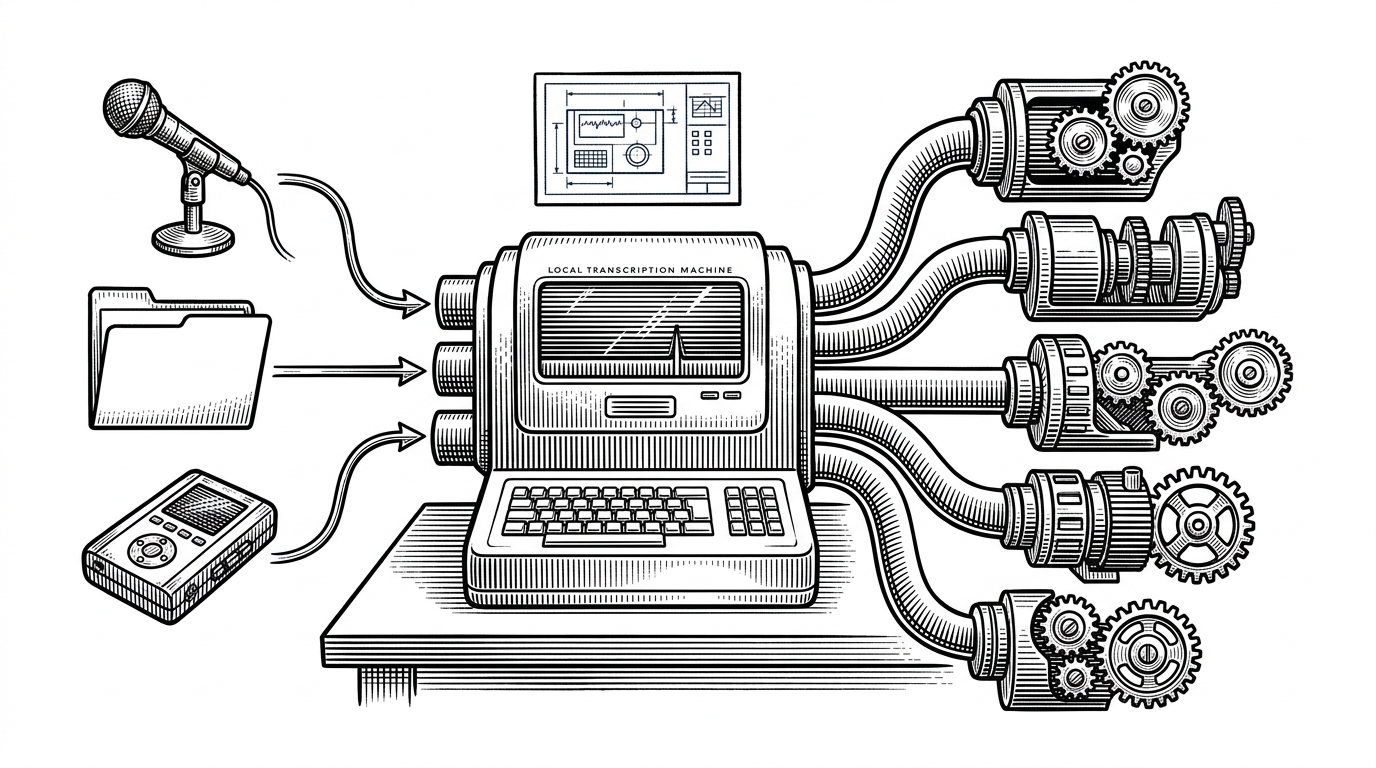
TranscriptionSuite: The Local-First Transcription App That Looks Like a Software Factory
A privacy-first audio workspace that swaps cloud APIs for local models, then adds diarization, notebook workflows, and an unusually structured AI-agent build system.
Voice & Multimodal AI
mulmocast-cli: MulmoCast: The Repo That Compiles One Script Into Video, Slides, Podcast, and Manga
An AI-native media engine where MulmoScript becomes the source of truth, the browser becomes the renderer, and the same narrative can ship in multiple formats without rewriting the story.
Voice & Multimodal AI
TIGER Makes Speech Separation Small Enough to Matter
A look at how this Tsinghua-built repo uses time-frequency interleaving and gain extraction to chase strong separation without the usual model bloat.
Voice & Multimodal AI
openai/chatkit-python: The SDK That Streams UI, Not Just Tokens
Inside the widget diff engine, typed protocol, and persistence layer that turn a Python backend into a living chat interface.
Voice & Multimodal AI
OpenAI-Wrapper-SwiftUI: The iPhone AI app that never ships your API key
A SwiftUI vision wrapper built around a proxy-first trust boundary, automatic camera prompting, and a deliberately boring backend that makes mobile AI safer to ship.
Voice & Multimodal AI
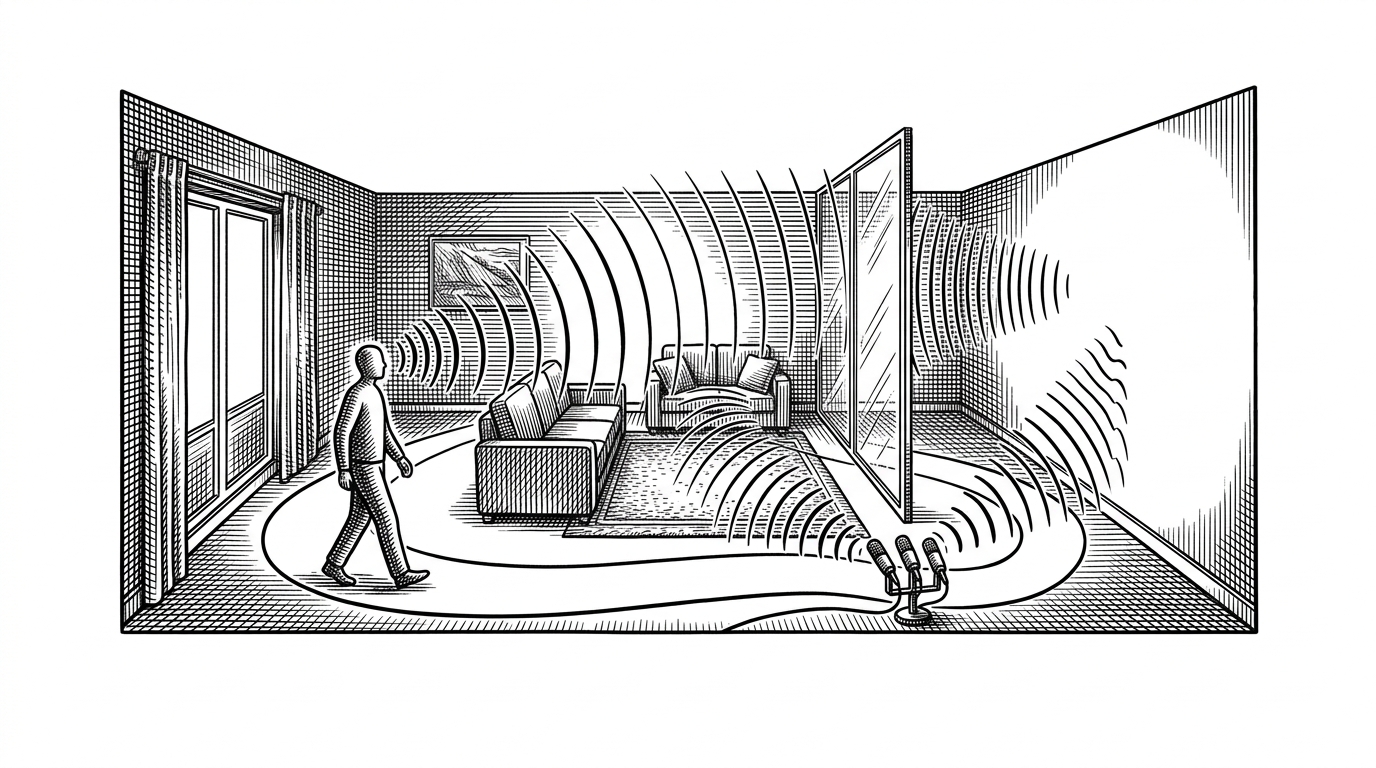
SonicSim: The Open-Source Simulator That Teaches AI How Moving Sound Actually Behaves
A synthetic audio stack that treats motion as the signal, not metadata, then turns that motion into a dataset and benchmark for speech enhancement and separation.
Voice & Multimodal AI
The Model That Points: Inside MaverickRen/PixelLM
How a lightweight codebook and a clever loss function gave Large Multimodal Models spatial agency without the heavy overhead of Segment Anything.
Voice & Multimodal AI
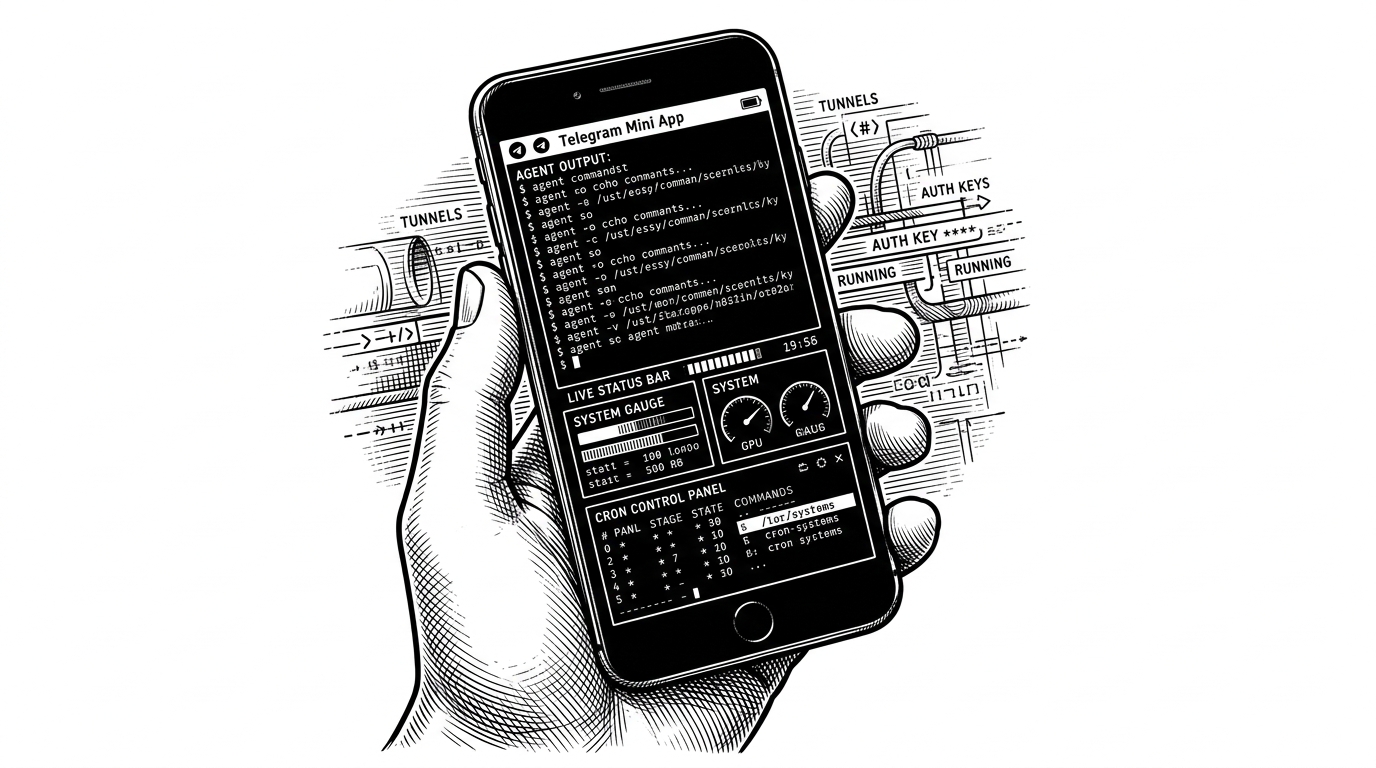
hermes-telegram-miniapp: Hermes Telegram Mini App: The Pocket Terminal That Turns a Self-Hosted Agent into an Operations Console
A fast, hardened Telegram Mini App for the Hermes agent. It does more than chat: it manages sessions, system status, cron jobs, and fork maintenance without losing the terminal feel.
Voice & Multimodal AI
SimpleStream: The Video AI Baseline That Wins by Forgetting More
A sliding-window VLM pipeline shows that, for streaming video, the smartest move may be to stop chasing memory and let the model focus on the last few frames.