Voice & Multimodal AI
Real-time voice companions, multimodal agents, speech-to-speech, and audio-first interfaces
145 explainers
Voice & Multimodal AI
Flow Teleprompter: The Windows Overlay That Reads Your Script Without Getting Caught
A Rust and Tauri desktop app that combines capture-proof window tricks, offline voice tracking, and remote script collaboration into one lightweight teleprompter.
Voice & Multimodal AI
gazectl: Your Head is the New Home Row
How a minimalist Swift utility uses computer vision to kill the "Cmd+Tab" bottleneck in multi-monitor workflows.
Voice & Multimodal AI
ankurdotio/interview-ai-yt: How to Turn an LLM Into a Structured Interview Engine
A look at the schema-first design that powers tailored questions, prep roadmaps, and ATS-friendly resume PDFs without letting the model run wild.
Voice & Multimodal AI
franken_whisper: The Bayesian Hypervisor for the Agentic Ear
How a zero-unsafe Rust orchestrator unified the fragmented Whisper ecosystem into a high-reliability streaming engine for AI agents.
Voice & Multimodal AI
Writher: The Windows Voice Tool That Solves the Last Mile
A local-first dictation and assistant app for Windows, built around Whisper, Ollama, and a clipboard-safe way to paste speech into any focused app.
Voice & Multimodal AI
push-to-do: Push To-Do: The iPhone App That Turns Speech Into Notion Tasks
A tiny SwiftUI utility that starts recording on launch, runs the audio through Whisper, and posts the result into Notion with almost no interface in between.
Voice & Multimodal AI
obs-mcp: Turning Claude into an OBS Technical Director
A protocol-first MCP server that maps OBS WebSocket v5 into safe, structured tools, so an AI assistant can switch scenes, mute sources, and drive a live production without falling apart when OBS does.
Voice & Multimodal AI
MiniMax-AI.github.io: MiniMax-Speech: The End of the Reference Script
How an intrinsic speaker encoder and Flow-VAE synthesis jumped to the top of the TTS Arena leaderboard.
Voice & Multimodal AI
Thuki: The macOS AI secretary that lives on top of everything else
A deep look at the local-first overlay that uses NSPanel, global event taps, and live screen context to make AI feel like a system reflex instead of a separate app.
Voice & Multimodal AI
ArtTuneDB: The Windows Audio Stack That Treats Footsteps Like a Signal Problem
A guided installer, custom DSP scripts, and game-specific tuning files turn messy Windows audio into a tactical system for competitive play.
Voice & Multimodal AI
InboundAIVoice: The Open-Source Voice Stack Built for Indian Calls
A production-minded AI phone framework that mixes LiveKit, Sarvam AI, SIP telephony, and a browser control panel to automate booking, support, and lead qualification in Hinglish and regional languages.
Voice & Multimodal AI
langgenius/chatbot-chrome-extension: The Smallest Possible Way to Put a Dify Bot on Every Page
A tiny Manifest V3 wrapper, a configurable iframe, and a maxed-out z-index turn one Dify app into a browser-wide assistant. The interesting work here is not intelligence. It is delivery.
Voice & Multimodal AI
Threadly Is the Browser Layer That Teaches Your Prompts to Think
A universal AI sidebar is the visible feature. The real invention is a privacy-first prompt triage and learning loop that lives entirely inside the browser.
Voice & Multimodal AI
Swift-Net: The Speech Separator That Refuses to Cheat
A real-time audio-visual model that uses mouth motion, causal convolutions, and SRUs to pull one voice out of a crowd without peeking into the future.
Voice & Multimodal AI
troyvis: Troy-VIS: Turning Any Text Prompt Into a Real-Time Video Track
Google Research’s open-vocabulary video segmentation stack pairs language grounding, memory, and deployment-minded engineering so the hard part is not just accuracy, but speed.
Voice & Multimodal AI
TFACM: The Cache That Lets Speech Separation Hear in Real Time
A causal separator from Tsinghua that swaps full hindsight for a rolling memory, and tries to erase the usual quality penalty of live audio.
Voice & Multimodal AI
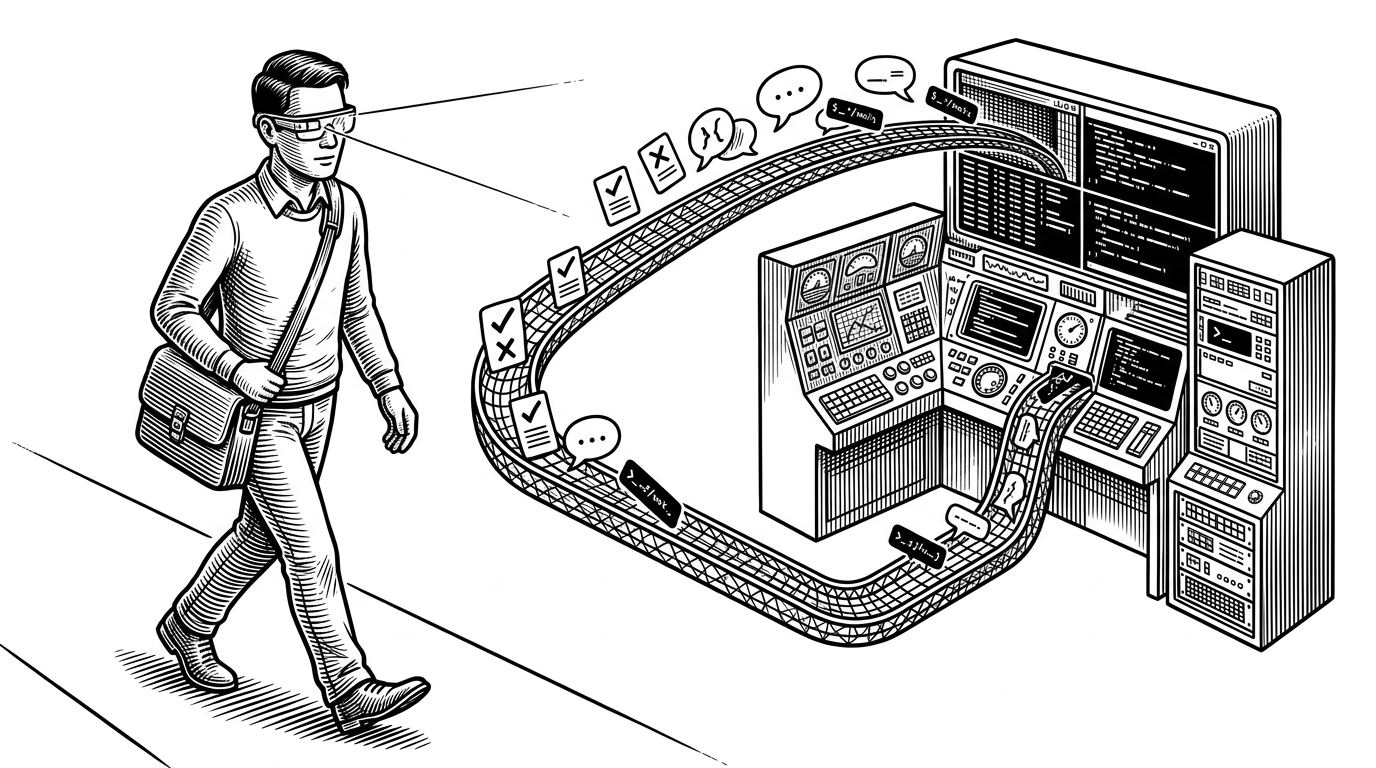
cc-g2 Turns `tmux` Into a Remote Control Surface for Claude Code
A bridge between Even G2 smart glasses and a terminal agent, with voice input, approval routing, and privacy-aware state handling built from surprisingly simple pieces.
Voice & Multimodal AI
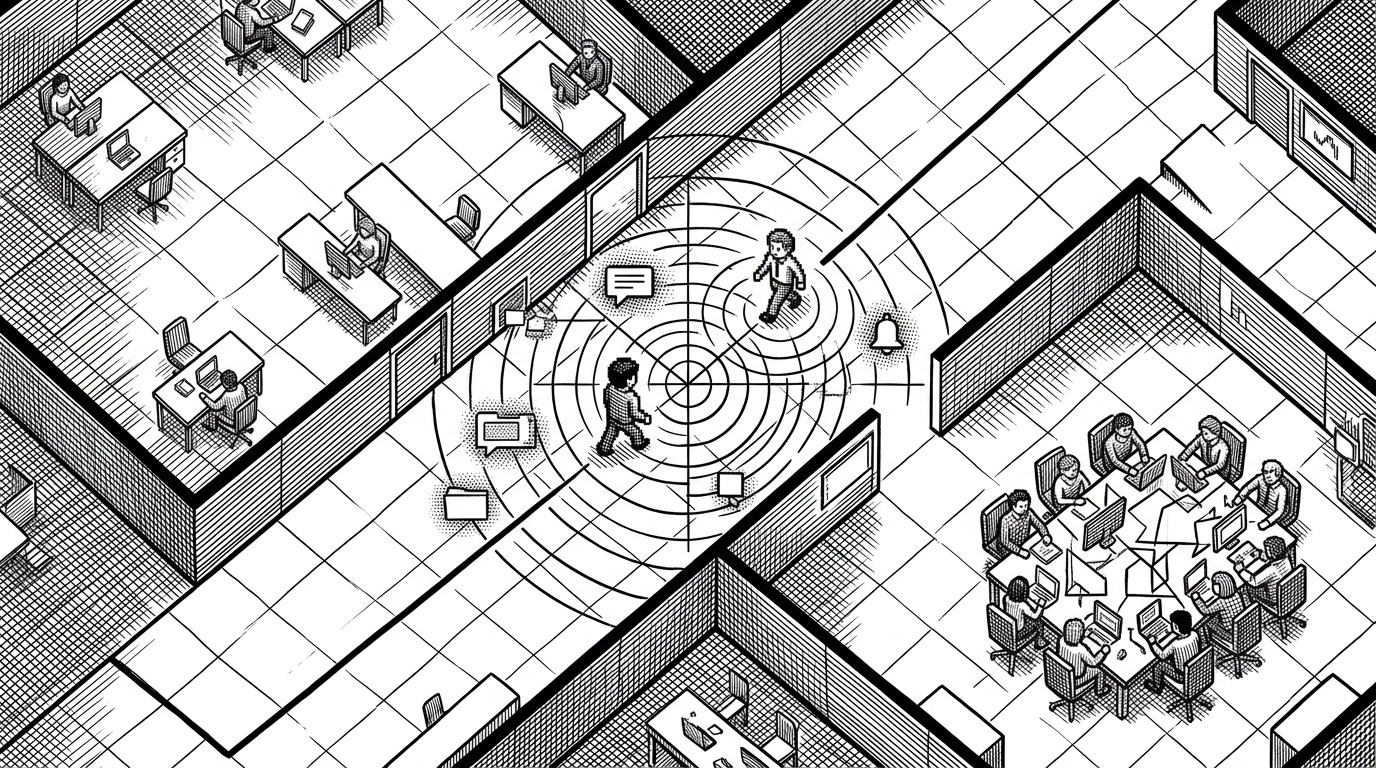
rshdhere/metaverse: When a 2D Game Loop Becomes a Virtual Office
A self-hosted collaboration stack that uses proximity, WebRTC, and a browser game engine to make remote work feel spatial, persistent, and strangely tangible.
Voice & Multimodal AI
CharacterView: The SwiftUI GIF Bridge That Turns Mascots Into State Machines
A tiny `UIViewRepresentable`, a cache, and one clever request guard make animated characters behave like app state, not flaky media assets.
Voice & Multimodal AI
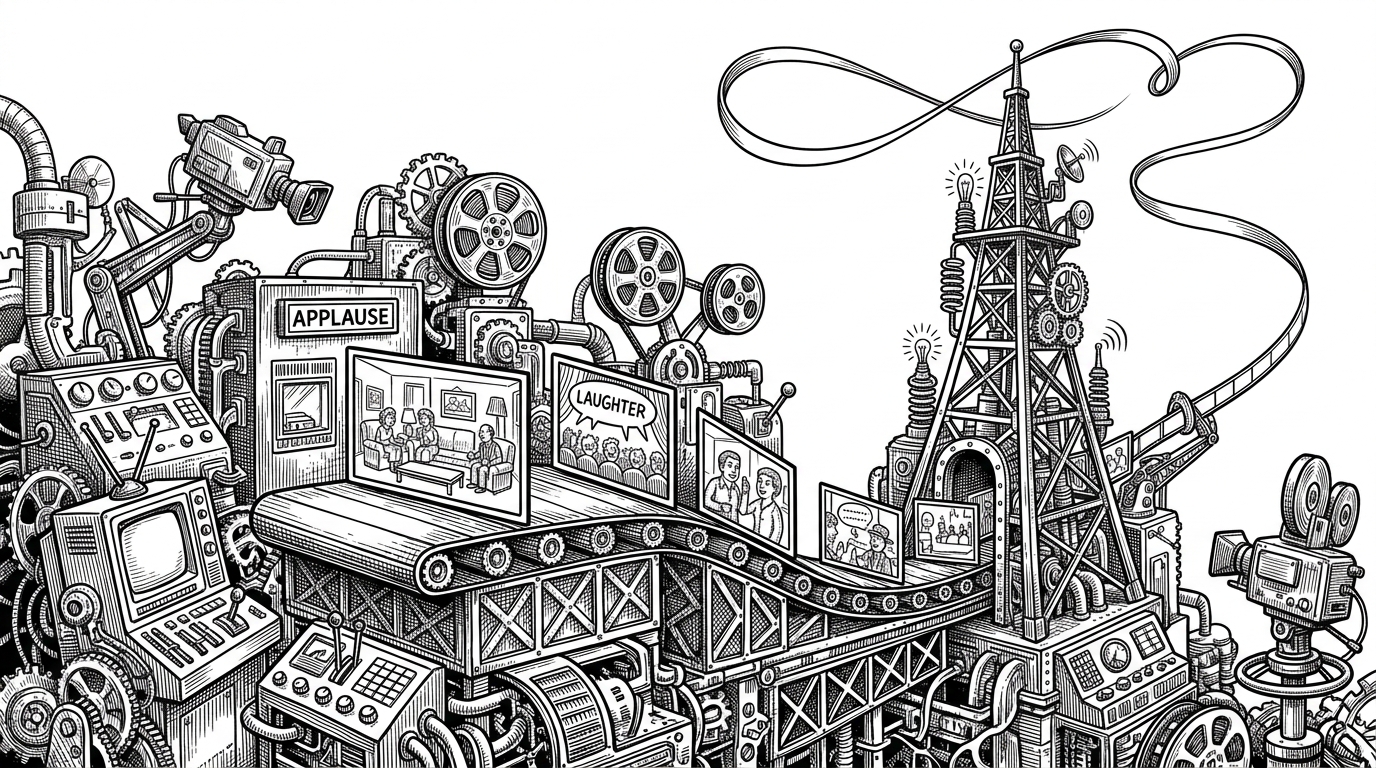
`replicate/cursedsit.com`: The AI sitcom that learned to act like TV
How a synthetic show becomes a seamless channel by trimming dead air, looping clips, and broadcasting through Replicate, Fly.io, and Cloudflare.
Voice & Multimodal AI
Apollo-data-preprocess: The tiny preprocessing repo that teaches Apollo what music is worth keeping
Apollo-data-preprocess is not a model repo. It is the filter that strips silence, slices tracks into learnable windows, and turns raw stems into HDF5 training fuel for high-fidelity music restoration.
Voice & Multimodal AI
The Mac as an AI Appliance: Unpacking localtalk
How an offline-first voice assistant uses Apple's MLX framework and aggressive audio engineering to sever the cloud API umbilical cord.
Voice & Multimodal AI
EndlessDreams: When Stable Diffusion Becomes a Live Instrument
A performance-obsessed take on generative video that favors instant steering, multimodal input, and rough-edged feedback over polished cinematic output.
Voice & Multimodal AI
getting-started-openai-realtime: The Browser Becomes the Robot Arm
A thin Cloudflare Worker keeps the keys safe, WebRTC keeps the voice loop fast, and client-side tool calls turn speech into immediate action.
Voice & Multimodal AI
HapticsManager-Swift: the one-method wrapper that makes iPhone taps feel instant
A tiny Swift utility that hides UIKit boilerplate, pre-warms the Taptic Engine, and turns haptics into a readable intent call.
Voice & Multimodal AI
Gull-Codec-Training: a codec that listens in frequency first
This repo is the training scaffolding behind Gull, a generative audio codec that compresses and reconstructs sound from subbands instead of raw waveforms.
Voice & Multimodal AI
opencode-voice: When the Tool Description Becomes the Voice
A small OpenCode plugin uses ElevenLabs v3, expressive audio tags, and macOS playback to make an AI agent sound directed, not robotic.
Voice & Multimodal AI
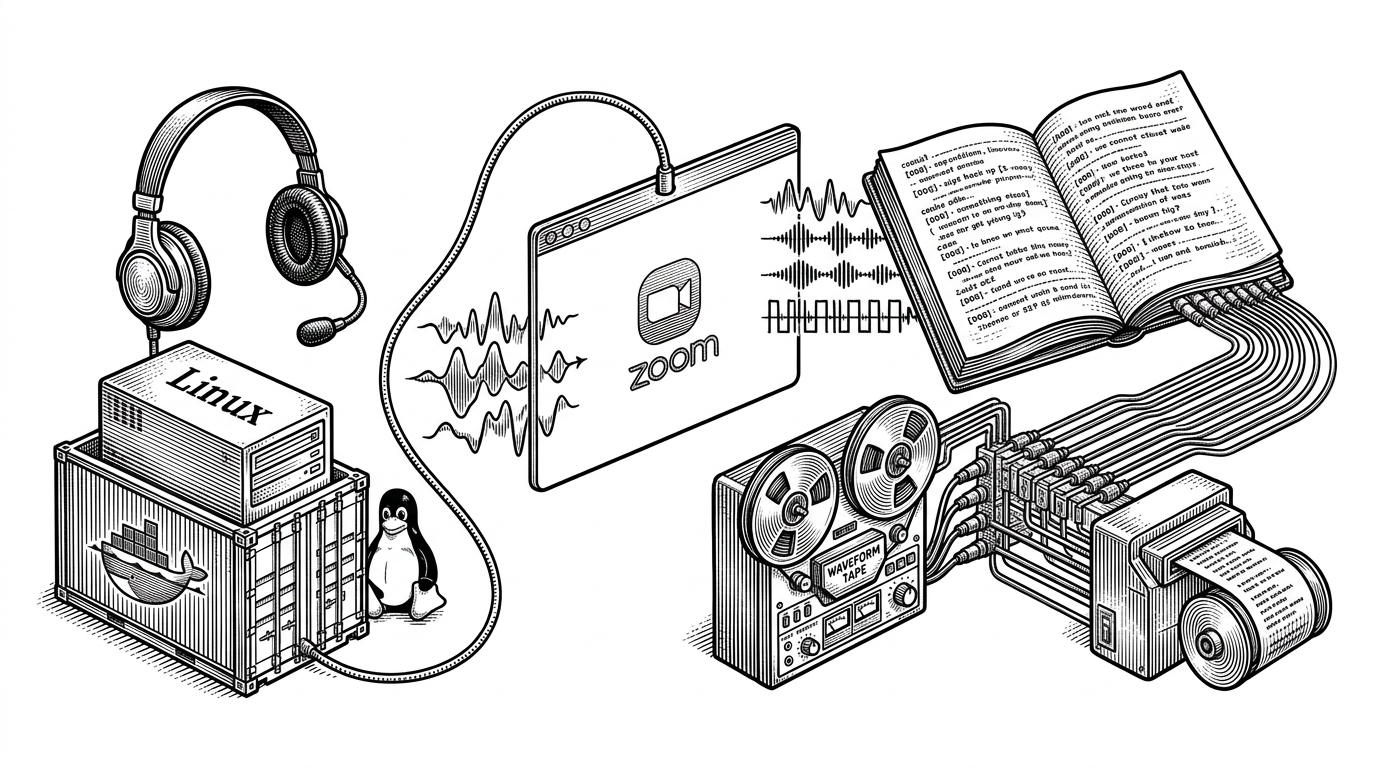
Inside `zoom/meetingsdk-headless-linux-sample`: How Zoom Becomes a Headless Meeting Bot
A C++ Docker sample that keeps the SDK alive, authenticates on the fly, and routes raw meeting audio into recording or transcription pipelines.
Voice & Multimodal AI
The Context-Aware Walkie-Talkie for Code: Unpacking ericclemmons/aside
How a lightweight macOS utility hijacks the Right Option key and uses AppleScript to give AI agents eyes on your active window.
Voice & Multimodal AI
Best-Audio-Paper-2025: The Year Audio AI Became an Omni-Model Race
A curated leaderboard that ranks the audio field three ways at once, and reveals why the strongest projects now win on research, demo quality, and open-source execution together.
Voice & Multimodal AI
clicky-win: ClickyWin: The Windows AI Tutor That Can Point at the Screen
A spatial voice assistant that fuses live transcription, multi-monitor vision, and cursor control into one unusually teachable desktop workflow.
Voice & Multimodal AI
`brown-noise`: The Tiny Go Engine That Makes Endless Brown Noise Feel Instant
A real-time audio generator that trades loops and media players for a minimal, low-GC pipeline, a first-order filter, and a shell-script switch you can actually live with.
Voice & Multimodal AI
MeetCaptioner Turns Google Meet Captions Into an Attention-Aware Translation Engine
A local-first Chrome extension that watches live captions, prioritizes what you can see, falls back across LLMs when a model fails, and keeps the whole meeting history on your device.
Voice & Multimodal AI
Forcing Gemini to Keep Time: Inside midnight-memory
How a local-first workflow uses multimodal LLMs to solve the tedious math of lyric alignment and AI lip-syncing.
Voice & Multimodal AI
UPI_Transaction_Alert: ShoutPay: The UPI Alert Engine That Turns Android Noise Into Spoken Money
A deep look at the parser pipeline, signal detection, and voice layer behind an open-source soundbox alternative for Android merchants.
Voice & Multimodal AI
Ridgevision-ai: RidgeVision AI: The Fingerprint Model That Refuses to Be a Black Box
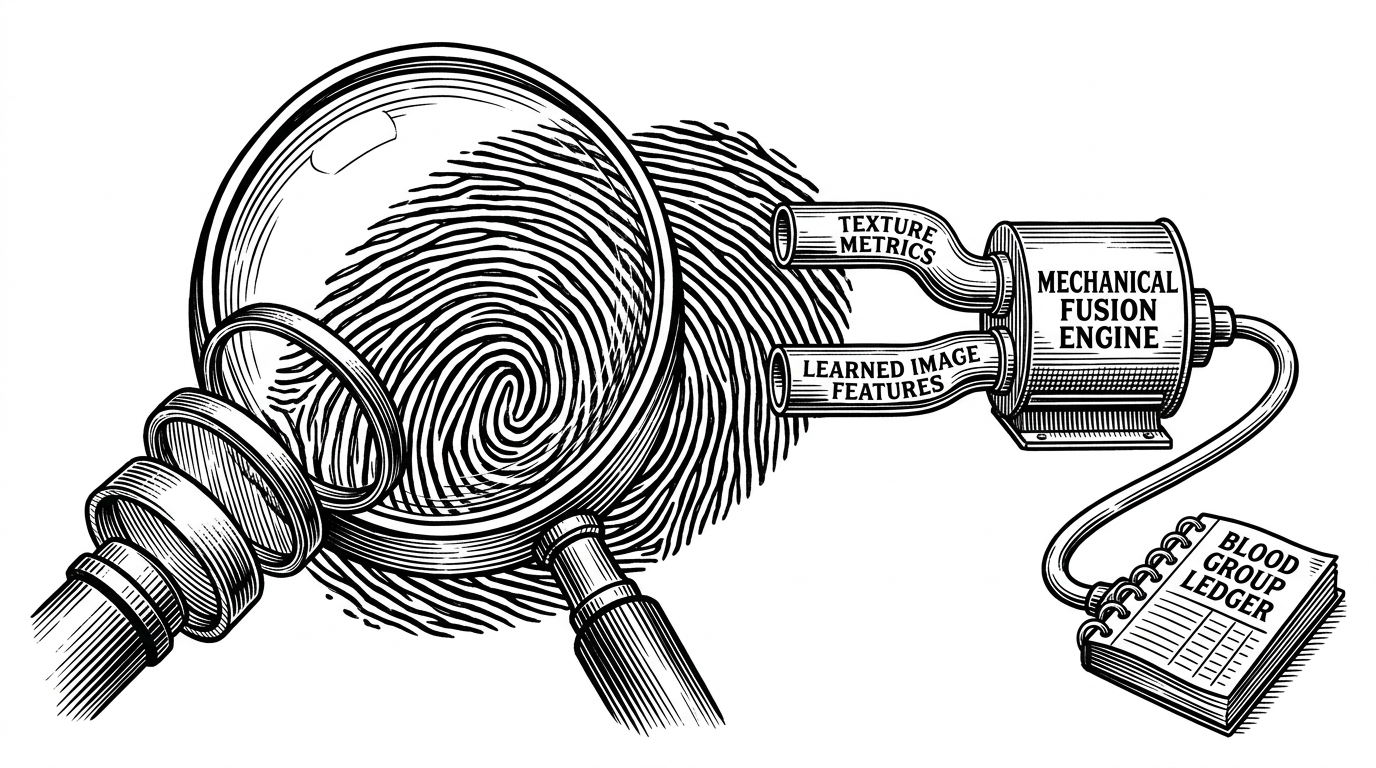
A hybrid biometrics prototype combines Gabor filtering, handcrafted texture features, EfficientNet, and heuristic heatmaps to estimate ABO/Rh blood groups from fingerprints.
Voice & Multimodal AI
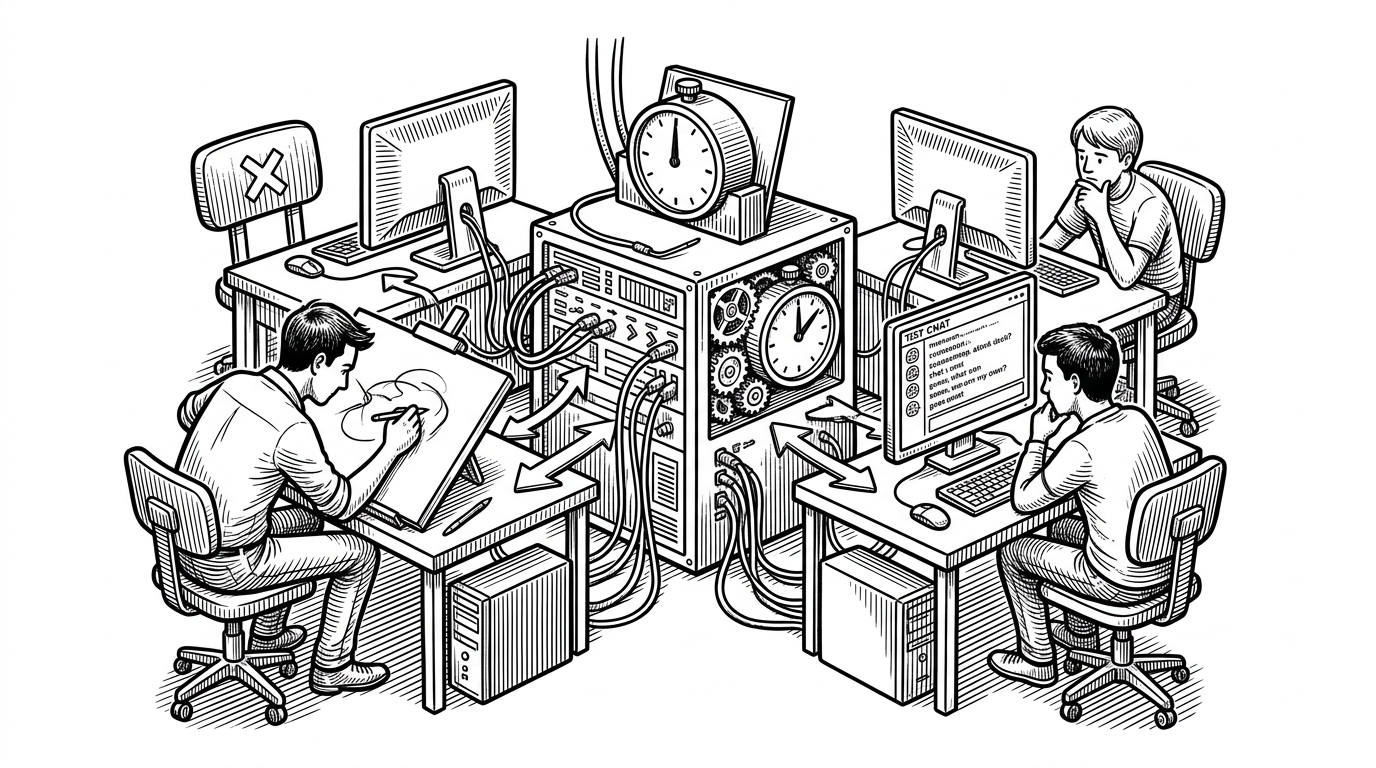
drawrush.io: DrawRush: The multiplayer drawing game that refuses to freeze
A real-time Pictionary-style stack where the server owns the room, the canvas stays aligned across devices, and offline players get skipped instead of breaking the match.
Voice & Multimodal AI
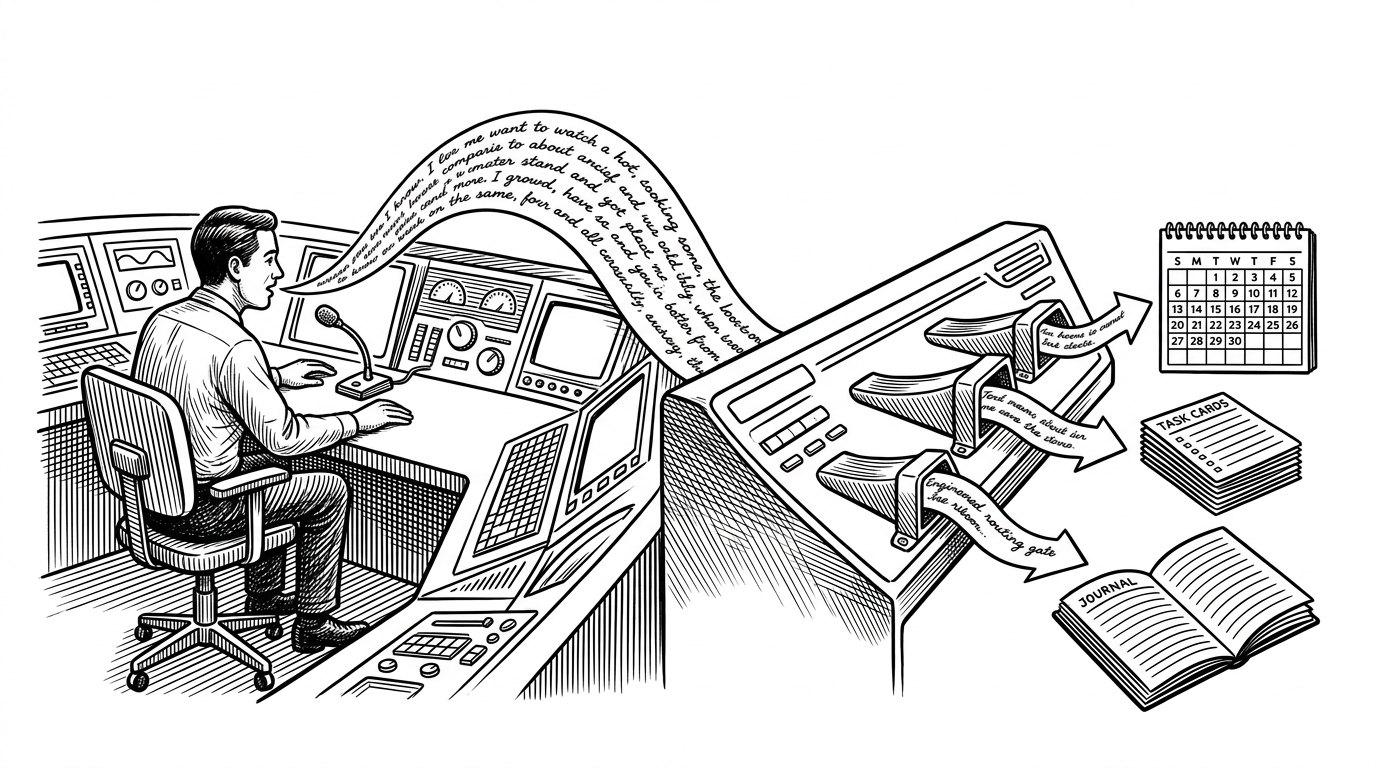
silent_gallery: Silent Gallery: The Productivity OS That Treats Voice Like an API
A Next.js dashboard that listens, classifies, and executes. The real trick is not the interface, but the translation layer between human speech and structured action.
Voice & Multimodal AI
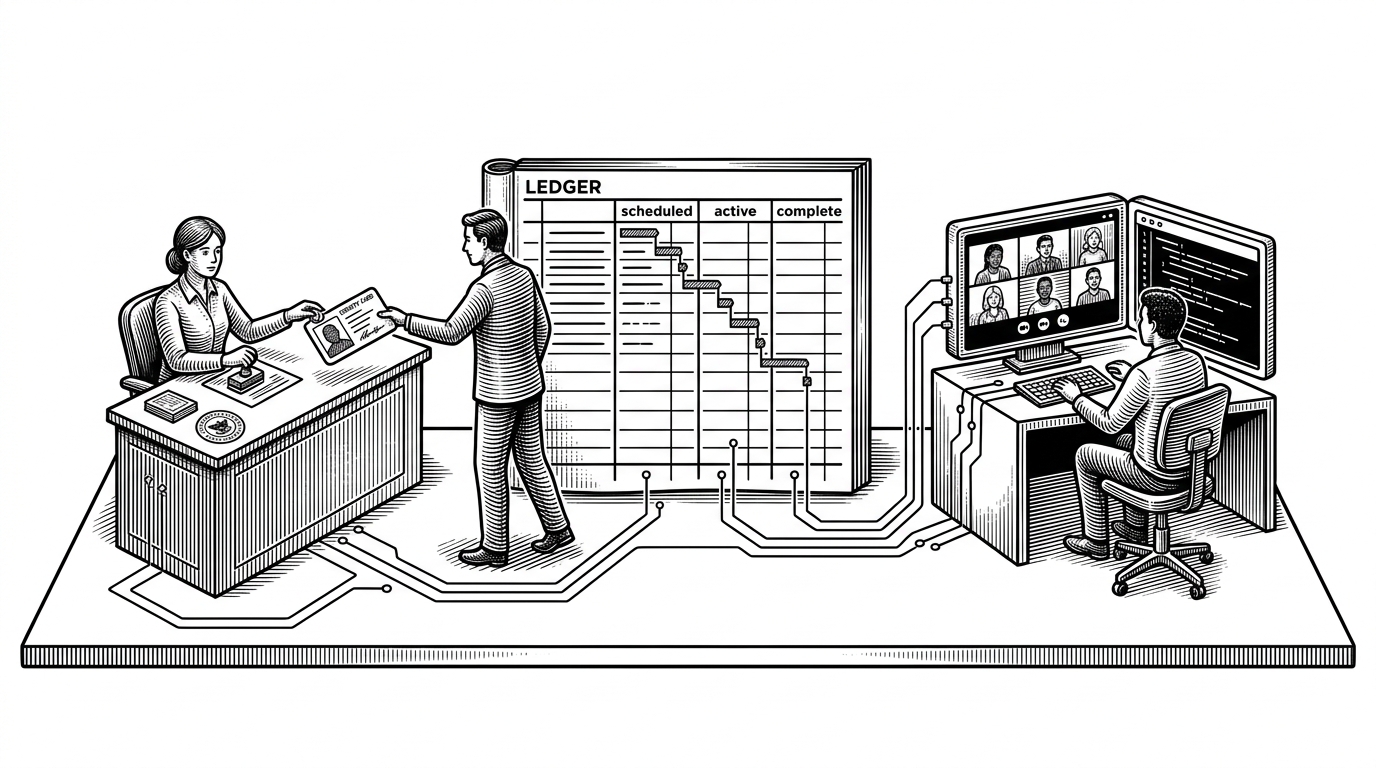
TalentScope: The Interview Platform Built from Three Backends
Clerk handles identity, Convex keeps the room in sync, and Stream carries the call. The interesting part is how cleanly the handoffs work.
Voice & Multimodal AI
gensay: The CLI That Keeps `/usr/bin/say` and Swaps in Modern Voice Engines
A drop-in macOS speech command that routes text to cloud TTS, local models, warm daemons, and fallback voices without changing your scripts.
Voice & Multimodal AI
call-me-skill: The CLI Agent That Calls You Back
Breaking the terminal tether with asynchronous voice handoffs and persistent memory loops.
Voice & Multimodal AI
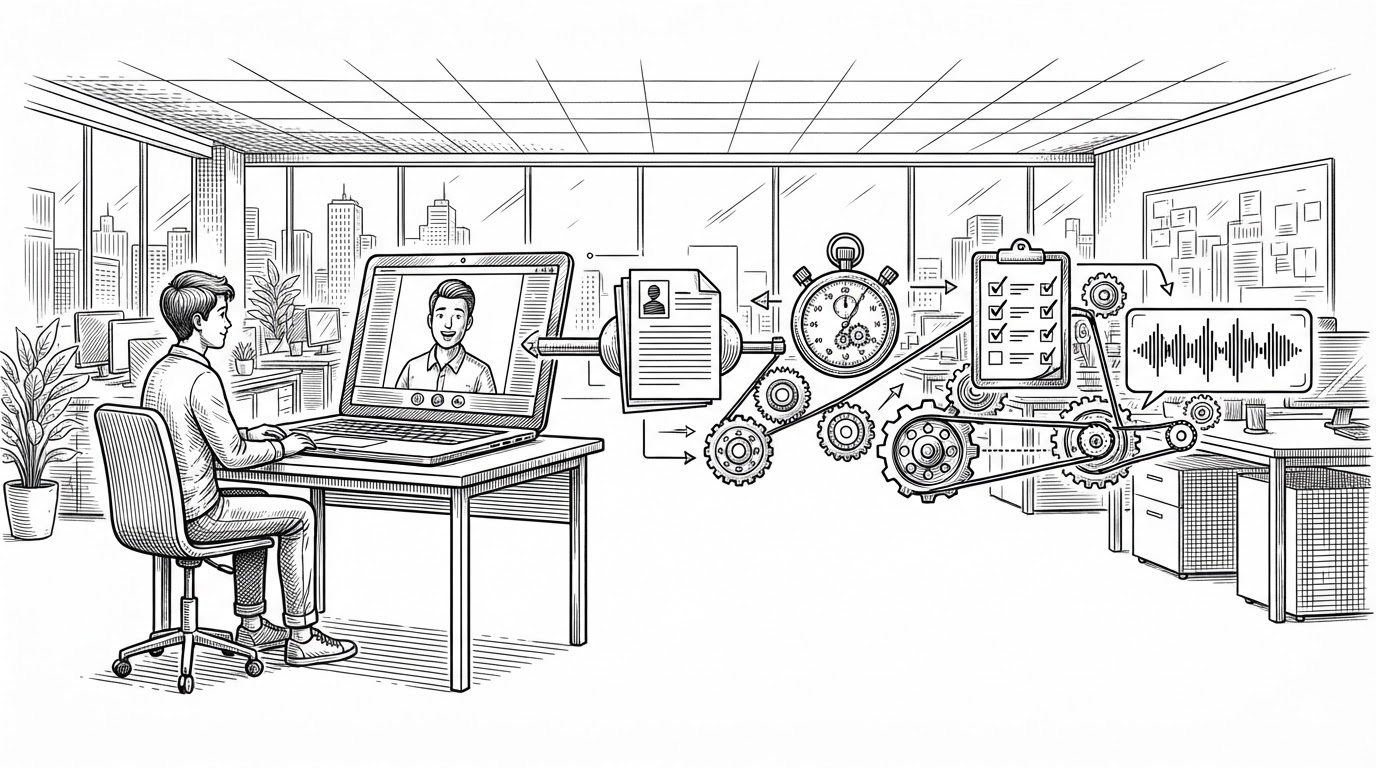
InterviewIQ_AI_Interview_Agent: InterviewIQ: The AI Interviewer That Turns a Resume Into a Controlled Conversation
A deep look at how this repo combines structured prompt engineering, browser speech APIs, and credit-backed SaaS logic to simulate a realistic mock interview.
Voice & Multimodal AI
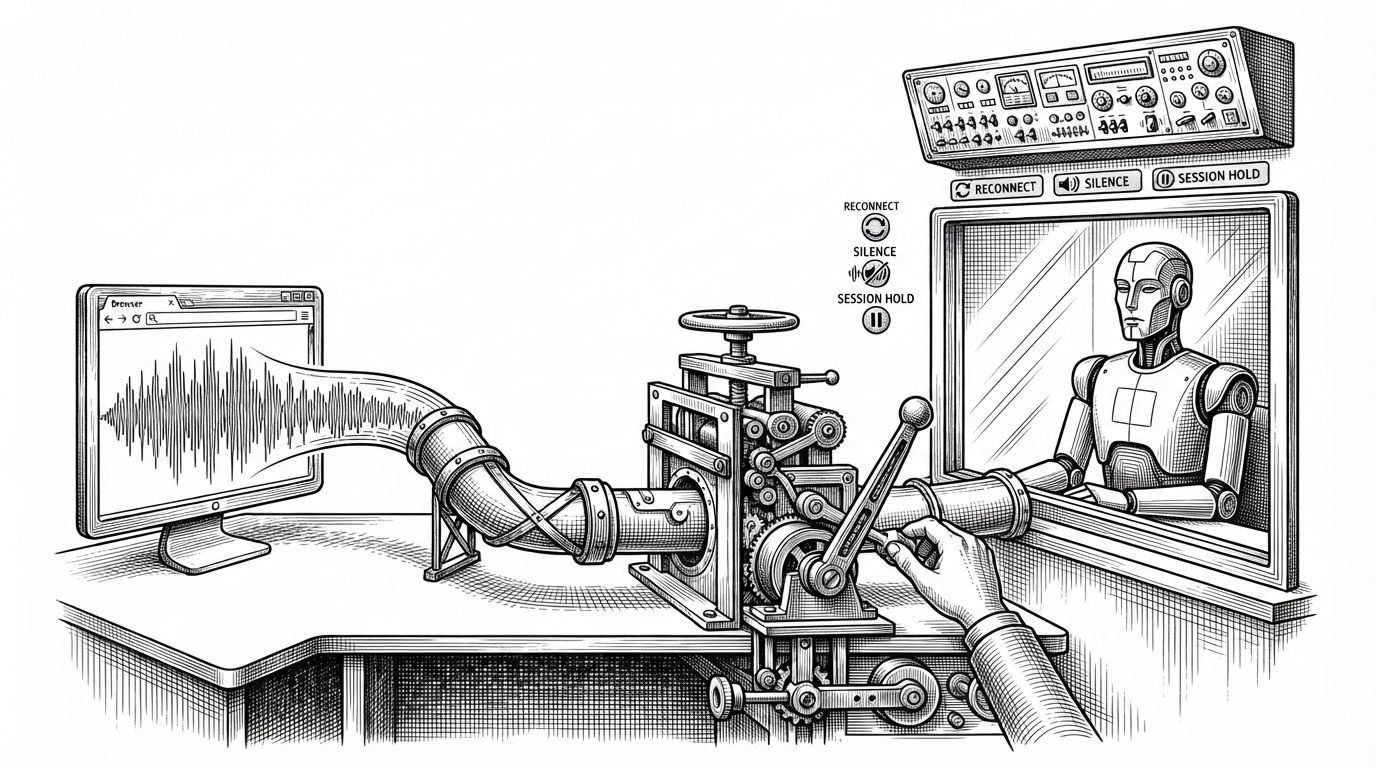
ai-interview-platform: The cage around the AI interviewer
A real-time voice interview stack that treats Gemini like a component, not a decision-maker.
Voice & Multimodal AI
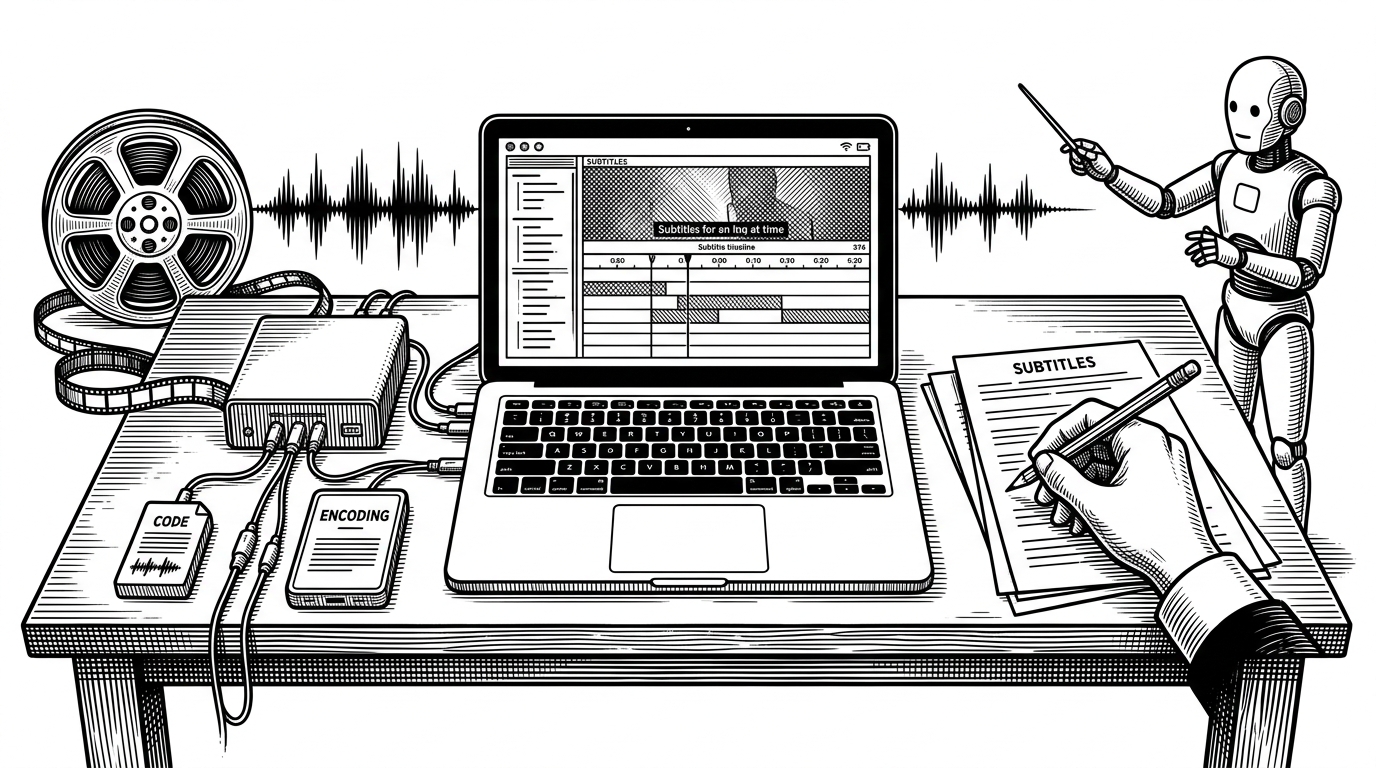
`add-ja-subs`: The Claude Code Skill That Turns a Video Into a Japanese Subtitle Factory
A local-first pipeline for transcription, translation, and burn-in subtitles, with the agent doing the editorial work where it matters most.
Voice & Multimodal AI
jarvis-interview-platform: Jarvis Interview Platform: How a Browser Pretends to Be a High-Stakes Interview Room
A voice-first mock interview app uses Gemini, Web Speech, and Firebase to turn a simple frontend into a tense, cinematic coaching loop that survives failed mic input, slow models, and empty transcripts.
Voice & Multimodal AI
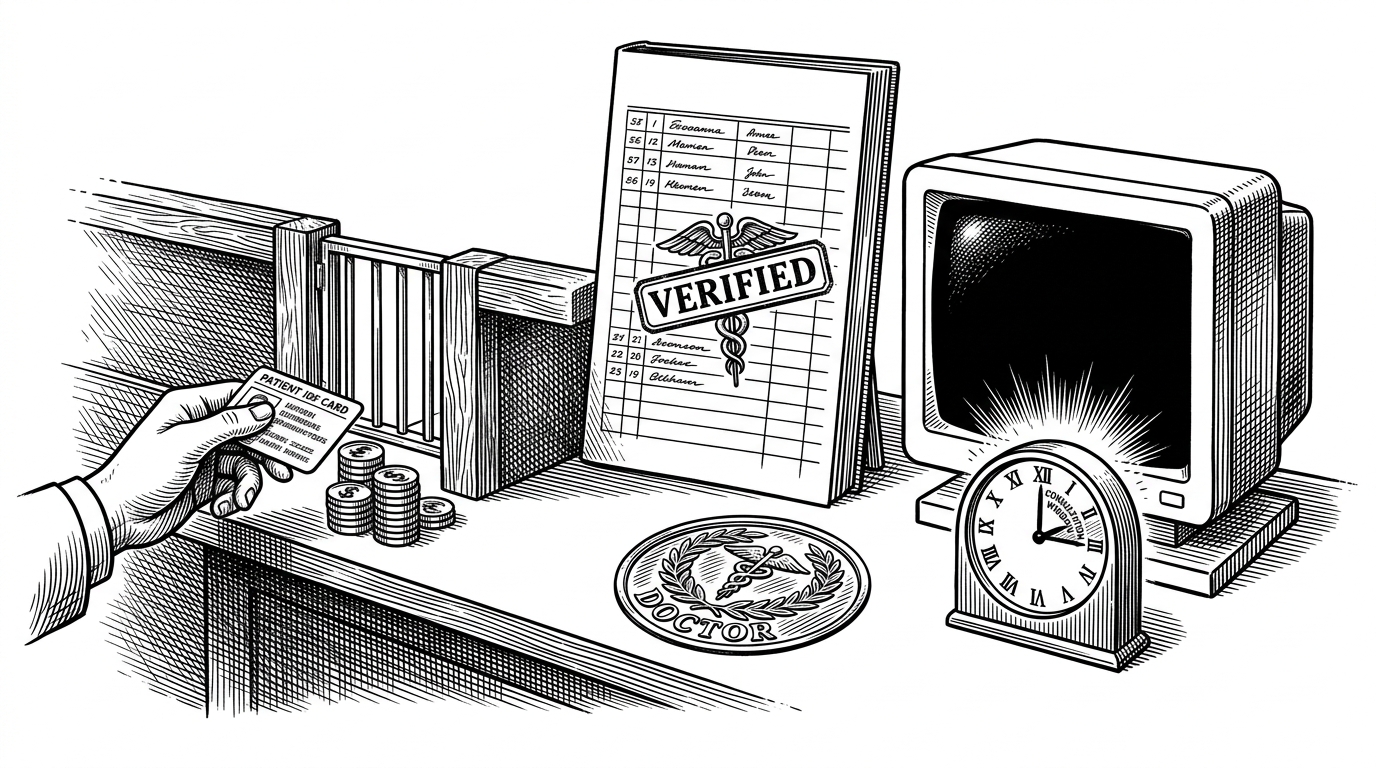
Medi_Meet: The Telemedicine App That Treats Appointments Like Financial Transactions
A deep dive into the verified-provider gate, credit ledger, and just-in-time video provisioning that make this Next.js platform feel more like a controlled marketplace than a simple booking tool.
Voice & Multimodal AI
Clinical-Insights: A Small Clinical Data Tool That Thinks Like a Dashboard, Not a Platform
A lightweight Flask project for visualizing clinical trial data, built with a compact front end, a small contributor surface, and just enough structure to keep the workflow legible.
Voice & Multimodal AI
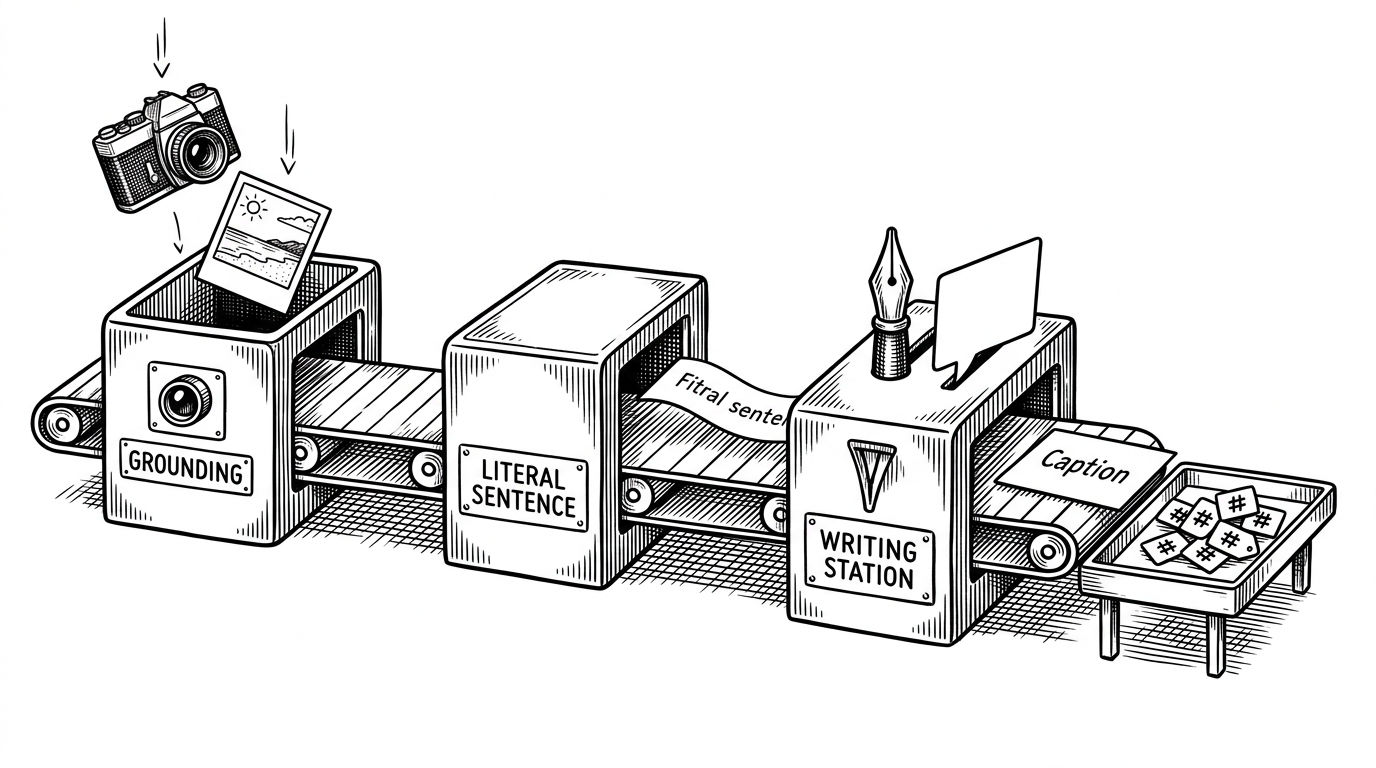
Ai-based-image-to-caption-generator: The Two-Step AI Trick Behind a Creator Tool
A Streamlit app that first describes an image literally, then hands that description to an LLM for captions and hashtags. The interesting part is not the UI. It is the chain.