Apollo-data-preprocess: The tiny preprocessing repo that teaches Apollo what music is worth keeping
Apollo-data-preprocess is not a model repo. It is the filter that strips silence, slices tracks into learnable windows, and turns raw stems into HDF5 training fuel for high-fidelity music restoration.
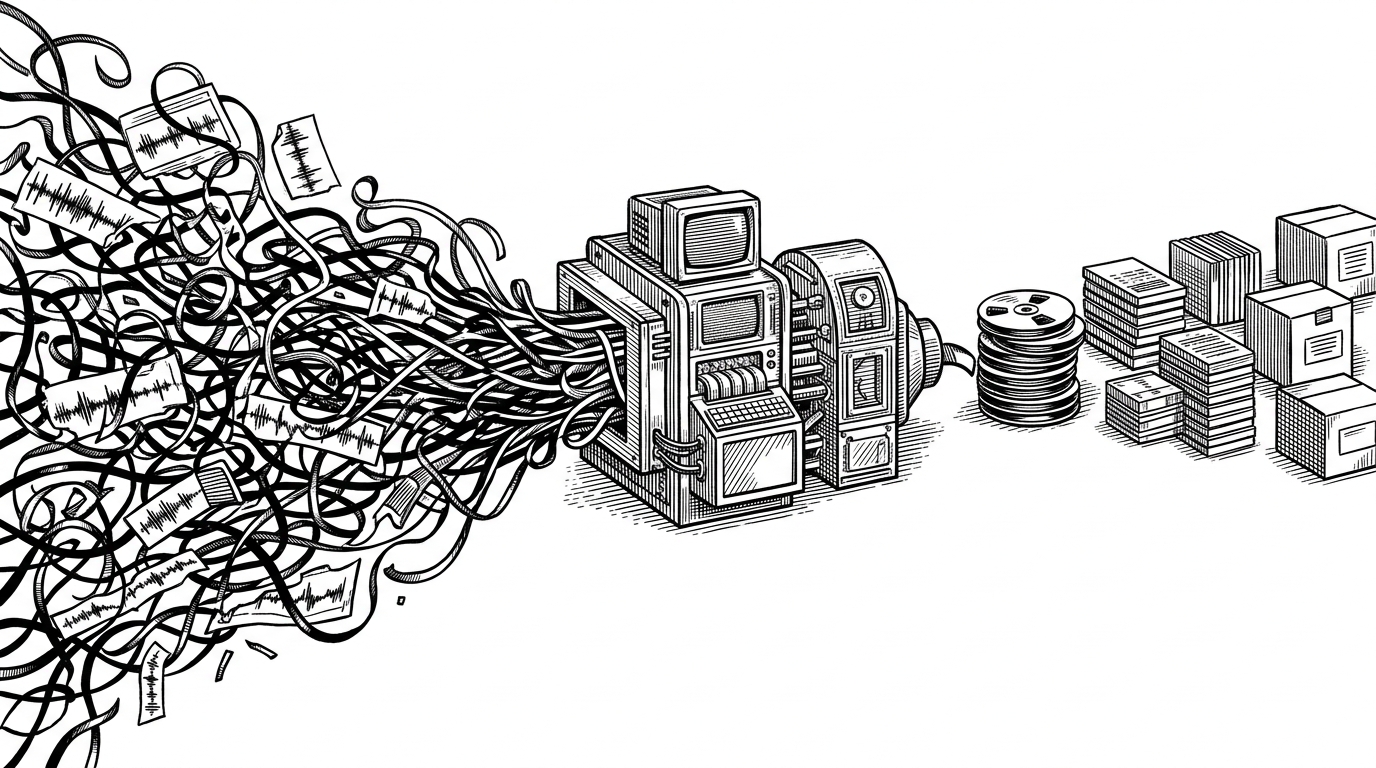
- Apollo-data-preprocess matters because the model's quality starts with which audio survives the filter, not with the network itself.
- Its percentile-based VAD adapts to each track's own energy distribution, which is a smarter fit for music than a fixed silence threshold.
- The repo favors research utility over software elegance, repeating logic across two scripts so each dataset path stays explicit and reproducible.
- HDF5 is the real delivery format here, because fast random access matters once training starts chewing through large music corpora.
Most preprocessing scripts are invisible by design. This one deserves a closer look because it decides what Apollo hears, what it ignores, and how expensive each training step becomes.
The repository sits behind Apollo, the music restoration project, and its job is simple to describe but hard to do well: take raw music datasets like MUSDB18-HQ and MoisesDB, remove unhelpful silence, cut the rest into consistent windows, and serialize everything into HDF5 files that train efficiently.
During data preprocessing, we drew inspiration from music separation techniques and implemented the following steps: Source Activity Detection (SAD)... Data Augmentation... Simulating Dynamic Bitrate Compression... Rescaling... Saving as HDF5
What the repo actually does
The codebase is tiny on purpose. Two scripts, musdb_preprocess.py and moisesdb_preprocess.py, handle two dataset layouts and share nearly the same core logic. That is not a polished product pattern. It is a research pattern: keep the path from dataset to training file obvious.
At the center is a music-aware activity detector. It does not try to recognize words or speakers. It measures audio power in windows, estimates a track-specific floor from the non-silent regions, then keeps only 6 second segments where more than half the frames clear that threshold. In plain terms, it refuses to waste training budget on dead air.
The differentiator is not cleaning. It is selective hearing.
Most data pipelines optimize for uniformity. Apollo optimizes for density. Its VAD logic uses a percentile of each track's own energy distribution, which means a quiet classical passage and a compressed rock chorus are both judged relative to their internal dynamics, not an arbitrary global decibel line.
That matters because restoration models learn from examples, and examples with no musical content are expensive noise. If you are training a model to restore compressed music, you want the model to spend its capacity on transients, harmonics, and layered stems, not empty bars.
Why the format choice matters
The output is HDF5, and that choice is doing more work than it first appears. Instead of leaving training to crawl through loose audio files, the scripts package segments into indexed arrays that can be loaded efficiently and repeatedly.
Each track becomes its own file, which is a research-friendly compromise. It is easy to parallelize, easy to inspect, and easy to rerun when a preprocessing tweak changes the sample population.
def VAD(x, win=441, step=22050, sr=44100):
    # Split into 6 second windows with 50% overlap
    # Estimate a track-specific noise floor from non-silent frames
    # Keep a window only if enough frames exceed the threshold
    pass

# Raw audio -> VAD filtering -> numpy array -> HDF5 dataset
That pattern fits the rest of the repository. The code is readable, direct, and not especially abstracted. It makes fewer promises than a production framework, but it also leaves fewer mysteries behind.
How it compares
| Dimension | Apollo-data-preprocess | Typical general-purpose prep |
|---|---|---|
| Primary goal | Keep only musically dense segments for restoration training | Normalize or transform data for broad reuse |
| Thresholding | Relative, track-aware percentile based VAD | Often fixed thresholds or generic heuristics |
| Input shape | Multi-track music datasets with stems | Single streams, text, images, or mixed modalities |
| Output | Per-track HDF5 files for fast training access | Variable formats, often less optimized for audio loops |
| Trade-off | Less DRY, more explicit | More generalized, less domain-specific |
The comparison is not really between good and bad engineering. It is between a generic data tool and a domain-shaped tool. Apollo's scripts are narrow because music restoration is narrow: the training data has to preserve timing, energy, and spectral detail at 44.1 kHz, or the model learns from an inferior world.
What this says about the project
This repo is a marker of research maturity. The authors did not stop at model architecture. They also published the part that makes the benchmark reproducible, which is often where the real advantage hides.
It also tells you what Apollo values. The project is willing to spend preprocessing complexity to preserve audio quality later. That is a strong signal that the goal is restoration, not convenience.
The license reinforces that framing. This is an academic artifact, built for research use and sharing, not a commercial pipeline product. The repo is small, but its role is large: it shapes the data lens through which the model learns what compressed music should become.