jevgrep: The CLI That Teaches Coding Agents Where to Look
A deep dive into the agent-first search layer that prunes repositories into high-signal context, using semantic judgment, AST-aware reading leads, and token-aware output.
Introducing jevgrep - a research agent CLI powered by jev from @typesafeai that reduces your coding agent cost by 40% (verified on SWE-bench) Make sure to use the built in skill so your coding agent knows to use jg for context collection.
- jevgrep is built to spend an agent’s context budget on the right repository surfaces, not to win a keyword-search race.
- Its retrieval pipeline turns traversal into judgment, then turns judgment into reading leads, source units, and pruned output.
- Tree-sitter and AST-aware parsing matter because they let the tool return code neighborhoods instead of flat line matches.
- The real comparison is not against grep alone, but against expensive agent wandering that starts before the model knows where to look.
When a coding agent enters a repo it does not know, the expensive part is often not the answer. It is the wandering. jevgrep is built around that problem: it treats context retrieval as a software system of its own, with judgment, budgets, and output pruning baked in from the start.
What If the Search Tool Was Really a Context Budgeter?
The usual search story is simple. You type a string, you get matches. jevgrep is doing something stranger and more useful for agents: it decides which parts of a repository deserve attention before the primary model burns tokens reading the wrong files. That makes it closer to a context compiler than a grep replacement.
Jev is not a chat model. It takes unstructured state plus a typed question and returns a typed decision — a choice, a score, or a boolean, each with a confidence.
That framing matters because it changes the product’s unit of value. The output is not “all possible matches.” It is “the few pieces of repository evidence most likely to move the agent forward.” In other words, selection beats dumping.
Built for Agents, Not Just for Humans
The clearest sign of the design shift is the jg skill command. The tool does not only serve a human at the terminal. It also teaches Claude Code, Codex, and similar systems when to call back into jevgrep for discovery. The user is now partly the model itself.
That is a subtle but important product move. Instead of expecting an agent to discover a tool by chance, jevgrep ships instructions that make the tool part of the workflow contract. It is search infrastructure plus onboarding for the model.
How the Retrieval Pipeline Chooses What Deserves Attention
The core engine lives in the retrieval flow. It walks the repository, asks what is worth following, and keeps tightening the scope until the result is compact enough to hand to the agent. The important detail is not that it searches. It is that it ranks, gates, and trims.
This is where the internal vocabulary matters. The pipeline does not just produce files. It produces reading leads and source units. That gives the agent a path into the codebase, not just a pile of file names.
Why Tree-Sitter Matters More Than Keyword Matching
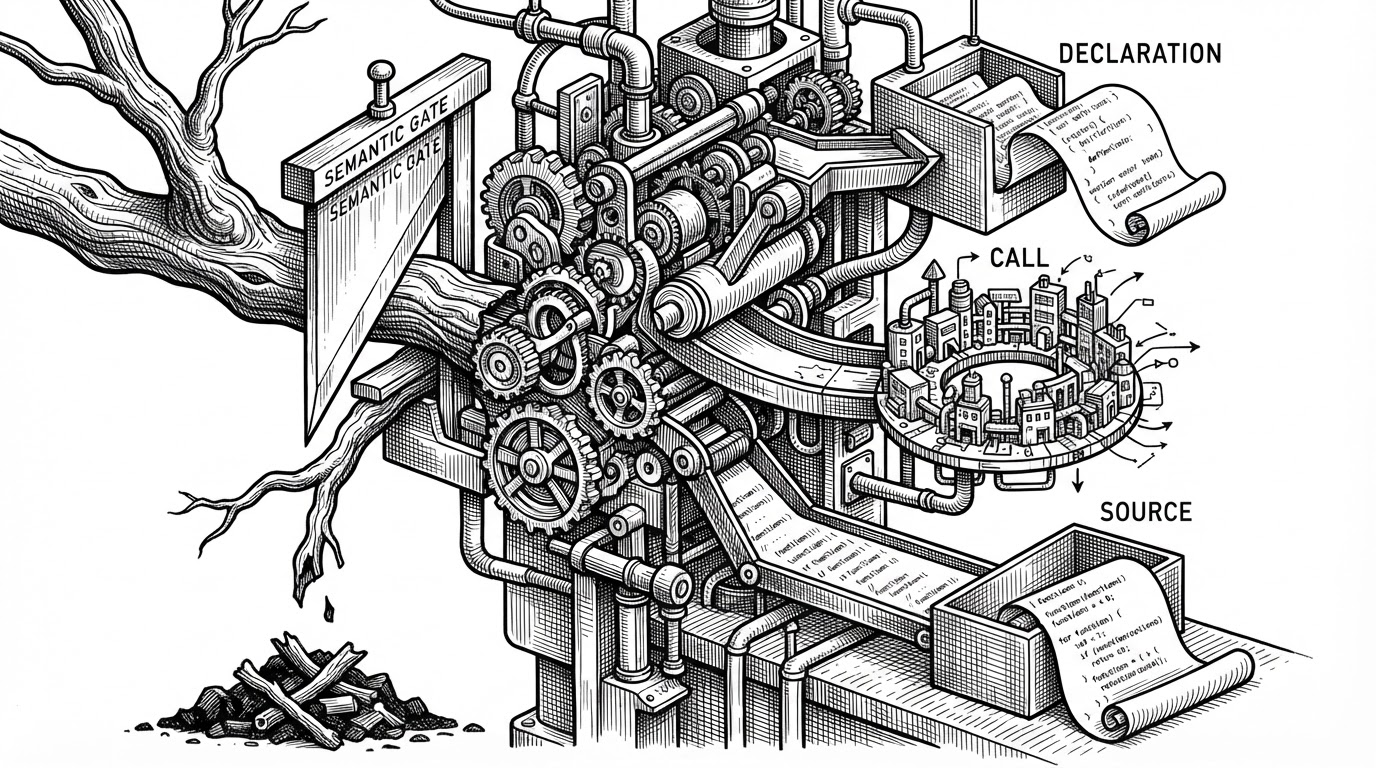
Plain text search can tell you where a string appears. It cannot tell you whether the hit is a declaration, a call site, or the most useful neighborhood around a function. That is why the parser layer matters. jevgrep uses tree-sitter to shape retrieval around code structure, not just characters.
// Conceptual shape of the parser layer
// Not exact source, but the behavior is clear:

const lead = {
  file: "src/auth/session.ts",
  kind: "declaration",
  range: { start: 42, end: 118 },
  evidenceRange: { start: 55, end: 94 },
  neighbors: ["refreshSession", "expireSession"],
  score: 0.91
}

// The agent gets a lead, not a haystack.
That structure gives the model better footing. A function declaration plus its call neighborhood is far more useful than a page of line matches, especially when the question is behavioral: where does session expiry happen, or what code handles retries?
| Tool | Best for | What it returns | Strength | Weakness | When to use it |
|---|---|---|---|---|---|
| rg | Known text or identifiers | Exact matches | Fast and deterministic | Needs the right string | When you already know what to search for |
| jevgrep | Likely relevant code | Ranked leads, file locations, excerpts | Finds useful structure for agents | Depends on semantic judgment | When you know the behavior, not the exact symbol |
| Agent-only exploration | Deep reasoning across a codebase | Narrated investigation | Flexible and adaptive | Expensive and context-hungry | When the problem needs broader reasoning after the first pass |
That comparison is the real middle layer. rg is still the right answer for exact lookup. Full agent exploration is still the right answer for broad reasoning. jevgrep sits between them, helping the model arrive at the right neighborhood before it starts thinking out loud.
The Hidden Product Is Output Pruning
The final trick is not discovery, but presentation. The renderer sorts by priority, respects a maximum output budget, and truncates intelligently so the agent stays oriented even when the entire result set would be too large. That is why the experience feels curated rather than verbose.
// Conceptual output behavior
// The goal is to preserve orientation under a byte budget.

renderResult({
  maxOutputBytes,
  sortBy: ["priority", "score"],
  keep: ["declaration locations", "reading leads"],
  prune: ["redundant source blocks", "low-value excerpts"]
})
This is a quiet but important shift in UX. The tool is not trying to be exhaustive. It is trying to be sufficient. That makes it feel less like a search result page and more like a briefing.
Where rg Stops and jevgrep Starts
The competitive frame is straightforward. ripgrep excels when the question already has a known string. jevgrep excels when the question is about behavior, ownership, or likely relevance. They are different tools for different parts of the discovery loop.
| Tool | Best for | What it returns | Strength | Weakness | When to use it |
|---|---|---|---|---|---|
| rg | Known strings | Literal matches | Speed | No semantic judgment | When the query is exact |
| jevgrep | Behavioral discovery | Semantic leads and excerpts | Context-aware selection | Requires a judge model | When the code surface is unknown |
| Agent-only exploration | Broad reasoning | Narrated investigation | Flexible | Context expensive | When search is no longer enough |
That is why the project should not be read as a replacement for grep. It is a different layer in the stack. Search finds. jevgrep selects.
The Economics of Asking the Right Model the Right Question
The cost story is the real thesis underneath the architecture. If a primary coding model spends less time reading irrelevant repository material, the whole workflow gets cheaper and faster. That is why the project’s benchmarks matter, even when they are not the whole accounting story.
dzhng/jevgrep checks the card catalog for your coding agent and pulls the right card, while Jev's coin meter charges for every drawer it opens. Tested commit baf2d1c4c719e339f10e7dfb20cf90f9fe402e01. Verdict. Adopt dzhng/jevgrep with care for finding code in repositories your coding agent does not know.
That tradeoff is clean. Spend a smaller model or decision layer to reduce waste in the larger model’s context window. The upside is better focus. The downside is that semantic judgment is never free, so the economics only work if the saved tokens and reduced wandering justify the extra step.