experimental-ext-grouping: MCP’s Folder System for Tools, Prompts, Resources, and Tasks
A protocol-level experiment in turning flat primitive lists into navigable groups, so clients can surface less noise, spend fewer tokens, and help models find the right capability faster.
- experimental-ext-grouping argues that the real scaling problem is not tool quality but tool organization, because flat discovery surfaces become noisy as MCP servers grow.
- The repo treats grouping as a protocol concern, which gives every client and server a shared way to narrow search before a model sees the full capability set.
- The project is experimental by design, and that matters because MCP is using governance to test ideas without freezing them into the core too early.
- Its core insight is simple: better namespace design can reduce cognitive load, token cost, and selection error at the same time.
MCP does not need more primitives. It needs a way to stop throwing them all at the model at once. That is the wager behind experimental-ext-grouping, a repository that tries to give MCP a folder system before the protocol drowns in its own flat lists.
The problem: flat lists stop working fast
The repository’s starting point is blunt: flat lists of MCP primitives can be long and cumbersome to work with. That sounds like a UI complaint until you zoom out. For an LLM, a long list is not just ugly. It is a larger search space, more distractors, more prompt tokens, and more chances to choose the wrong tool.
That makes the failure mode architectural. Once a server exposes dozens of tools, resources, prompts, or tasks, the client has to make discovery feel selective without making it feel hidden. If it cannot, every extra capability becomes part of the noise.
Flat lists of MCP primitives can be long and cumbersome to work with.
The fix: treat primitives like folders, not a pile of names
The extension’s central idea is simple to say and hard to do well: group primitives into a navigable hierarchy. A client sees group names first, then drills into the relevant branch instead of scanning everything at once. The result is less sprawl at the top and more specificity where it matters.
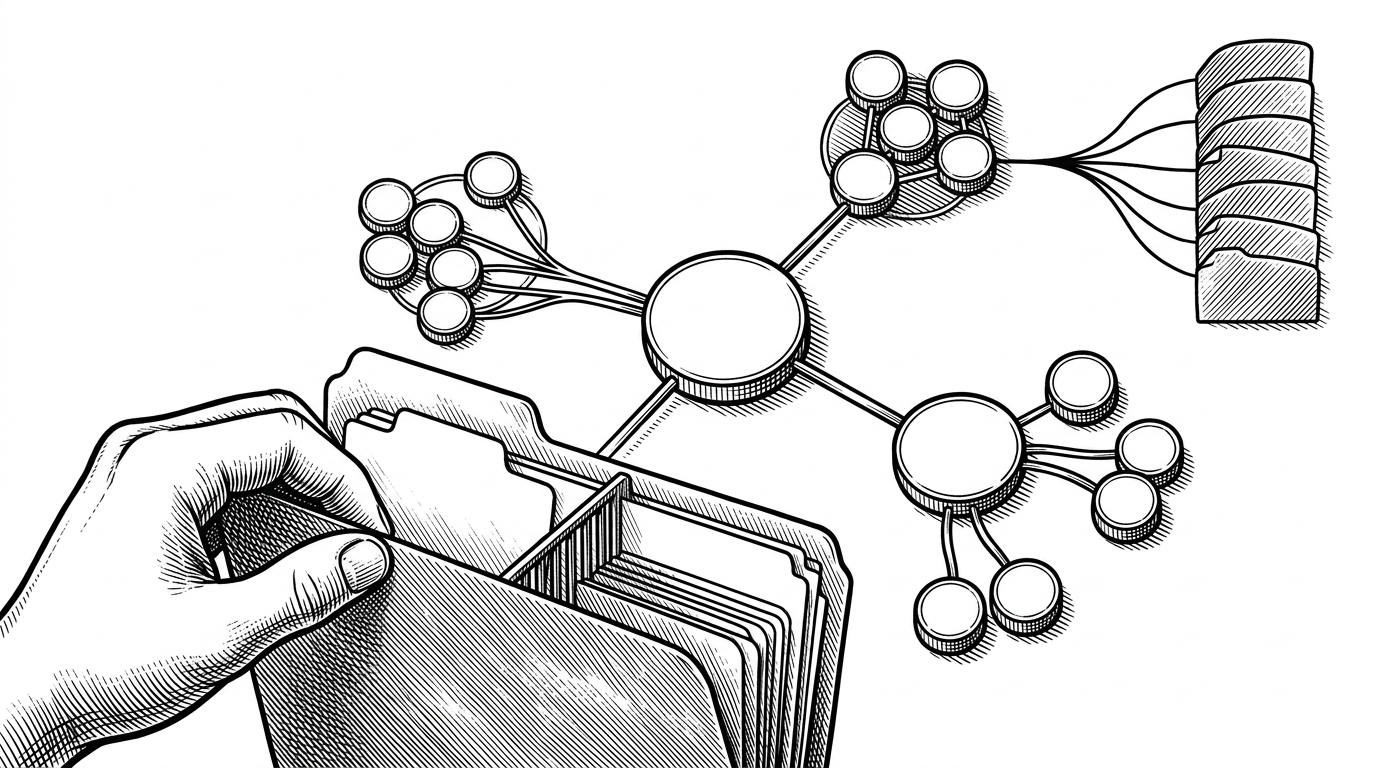
That matters because grouping is not just a nicer way to browse. It is a way to decide what the model should even be allowed to notice first. The repo is trying to shift MCP from scan everything to open one branch at a time.
Why the protocol layer matters more than the app layer
App-level grouping is easy to invent and hard to standardize. Every server can invent its own naming scheme, nesting depth, and disclosure logic. That works until users move between clients or combine multiple servers, and then every bespoke taxonomy becomes one more thing the model has to relearn.
Protocol-level grouping changes that. It gives clients and servers a shared language for discovery, so grouping is no longer a private UI trick. It becomes part of how capability negotiation works across the ecosystem.
| Approach | Where grouping lives | Who controls it | Discovery experience | Scaling behavior | Interoperability |
|---|---|---|---|---|---|
| Flat primitive lists | Nowhere | The server exposes everything at once | Scan the whole surface | Degrades quickly as lists grow | High surface compatibility, low usability |
| Application-level grouping | Inside one client or one server | Each app invents its own taxonomy | Better locally, inconsistent elsewhere | Scales only inside that app’s assumptions | Fragmented across clients and servers |
| Protocol-level grouping | In the MCP extension layer | A shared protocol convention | Open one branch, then descend | Scales by narrowing what must be loaded | Portable across implementations |
That is why this repo feels more important than a feature patch. It is a proposal for shared discovery semantics. Once the namespace is standardized, clients can get smarter without every server becoming a special case.
What the repo actually contains
This is not a polished spec masquerading as a package. The repository splits its weight between docs/, which frames the problem and possible approaches, and sdk/typescript/, which shows the extension taking shape in code. The docs are the argument. The SDK is the proof that the argument can survive contact with TypeScript.
The implementation signals are serious. The project uses strict TypeScript, schema validation with zod, and CI that builds, tests, and lints on every push. Experimental here means exploratory, not sloppy.
{
  "name": "@modelcontextprotocol/ext-grouping",
  "type": "module",
  "dependencies": {
    "@modelcontextprotocol/sdk": "^1.27.0",
    "zod": "^3.x"
  },
  "scripts": {
    "build": "tsc",
    "test": "vitest",
    "lint": "eslint ."
  }
}
The Interest Group is part of the product
The governance model is the other half of the story. This repository lives in a Primitive Grouping Interest Group, which is a place to explore patterns, gather requirements, and build proofs of concept without pretending the result is already official MCP policy.
That matters because standards do not stay healthy by accepting every idea immediately. They stay healthy by creating a place where ideas can be tested before they harden into mandates. The repository makes that boundary explicit.
⚠️ **Experimental** — This repository is an incubation space for the Primitive Grouping Interest Group. Contents are exploratory and do not represent official MCP specifications or recommendations.
That restraint is a feature, not a delay. It keeps the project useful as a laboratory while leaving room for the SEP process to decide whether anything graduates.
How it compares to the alternatives
The competition here is not another MCP repo. It is the default habit of exposing everything in one list, plus the local workarounds developers build on top of that habit. The comparison is less about feature counts than about where order lives.
| Model | What it optimizes | Main weakness | Best use case |
|---|---|---|---|
| Flat lists | Simplicity of exposure | Noise grows with capability count | Tiny servers with few primitives |
| App-specific grouping | Local convenience | Inconsistent across clients and servers | One-off products with controlled UX |
| Protocol-level grouping | Shared discovery semantics | Requires ecosystem agreement | Open ecosystems with many capabilities |
The verdict is straightforward. Flat lists are fine until they are not. App-specific grouping helps one surface at a time. Protocol-level grouping is the only version that can scale across the ecosystem without fragmenting the mental model.
Why this matters for MCP’s future
If MCP keeps growing, the next constraint will not just be transport or schema shape. It will be discovery. A protocol with a large capability surface needs a way to narrow the field before the model spends tokens inspecting everything in sight.
That is the real significance of experimental-ext-grouping. It is not trying to reinvent MCP. It is trying to teach MCP how to organize itself.